さらに、Tech4Exam Mule-Arch-201ダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1hDn2l-vFTwZqLhGONhn-Vygi1WjAYR16
もし君はSalesforceのMule-Arch-201認定試験に合格するのを通じて、競争が激しいIT業種での地位を高めて、IT技能を増強するなら、Tech4Examの SalesforceのMule-Arch-201試験トレーニング資料を選んだほうがいいです。長年の努力を通じて、Tech4ExamのSalesforceのMule-Arch-201認定試験の合格率が100パーセントになっていました。Tech4Examを選ぶのは成功を選ぶのに等しいです。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Architecting and Deploying API Implementations | 11% | - CI/CD and DevOps integration - Networking and security configuration - Runtime architecture and deployment options - High availability and fault tolerance |
| Topic 2: Deploying API Implementations to CloudHub | 11% | - VPC and private space configuration - Deployment optimization and scaling - CloudHub architecture and capabilities - Worker sizing and resource planning |
| Topic 3: Designing and Sharing APIs | 11% | - API design standards and best practices - API layering: Experience, Process, System APIs - API specification and documentation - Asset sharing and reuse via Anypoint Exchange |
| Topic 4: Applying Integration Patterns | 11% | - Error handling and reliability patterns - Event-driven and synchronous integration - Scalability and performance patterns - Common integration patterns and use cases |
| Topic 5: Establishing Organizational and Platform Foundations | 17% | - Anypoint Platform architecture and components - Center for Enablement (C4E) operating model - Governance and organizational structure - Platform strategy and roadmap definition |
| Topic 6: Explaining Application Network Basics | 11% | - Core concepts of application networks - API-led connectivity principles - Benefits of modern API design |
| Topic 7: Monitoring and Analyzing Application Networks | 8% | - Monitoring strategies and tools - Logging and alerting configuration - Operational visibility and optimization - Analytics and insight generation |
| Topic 8: Meeting API Quality Goals | 8% | - Security and compliance standards - Reliability and availability targets - Performance and latency requirements - Maintainability and testability |
| Topic 9: Managing APIs | 12% | - API policies and security enforcement - Versioning and deprecation strategies - Rate limiting and throttling - API lifecycle management |
当社の学習システムは、すべてのお客様に最高の学習教材を提供します。当社のMule-Arch-201最新の質問を購入すると、当社のすべてのMule-Arch-201認定トレーニング資料を楽しむ権利があります。さらに重要なことに、当社には多くの専門家がいます。これらの専門家の最初の義務は、すべてのお客様のために昼夜を問わず当社の学習システムを更新することです。 Mule-Arch-201トレーニング資料の学習システムを更新することにより、当社がMule-Arch-201試験に関する最新情報をすべての人に提供できることを保証できます。
質問 # 106
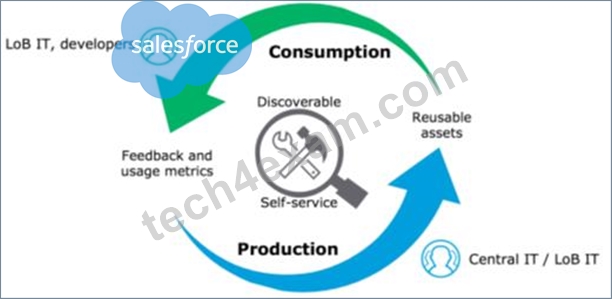
Which of the below, when used together, makes the IT Operational Model effective?
正解:A
解説:
Correct Answe r: Create reusable assets, Make them discoverable so that LOB teams can self-serve and browse the APIs, Get active feedback and usage metrics.
*****************************************
質問 # 107
Version 3.0.1 of a REST API implementation represents time values in PST time using ISO 8601 hh:mm:ss format. The API implementation needs to be changed to instead represent time values in CEST time using ISO 8601 hh:mm:ss format. When following the semver.org semantic versioning specification, what version should be assigned to the updated API implementation?
正解:C
解説:
Correct Answe r: 4.0.0
*****************************************
As per semver.org semantic versioning specification:
Given a version number MAJOR.MINOR.PATCH, increment the:
- MAJOR version when you make incompatible API changes.
- MINOR version when you add functionality in a backwards compatible manner.
- PATCH version when you make backwards compatible bug fixes.
As per the scenario given in the question, the API implementation is completely changing its behavior. Although the format of the time is still being maintained as hh:mm:ss and there is no change in schema w.r.t format, the API will start functioning different after this change as the times are going to come completely different.
Example: Before the change, say, time is going as 09:00:00 representing the PST. Now on, after the change, the same time will go as 18:00:00 as Central European Summer Time is 9 hours ahead of Pacific Time.
>> This may lead to some uncertain behavior on API clients depending on how they are handling the times in the API response. All the API clients need to be informed that the API functionality is going to change and will return in CEST format. So, this considered as a MAJOR change and the version of API for this new change would be 4.0.0
質問 # 108
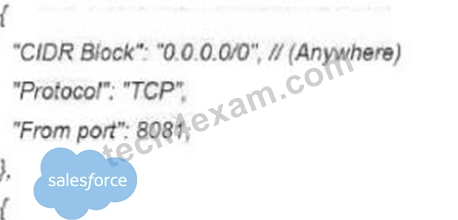
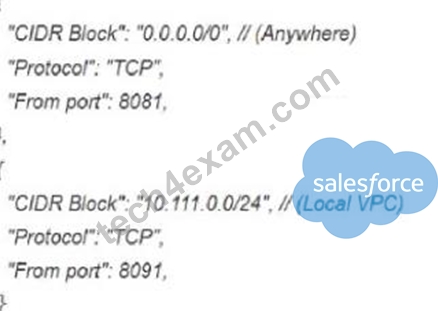
4 Production environment is running on a dedicated Virtual Private Cloud (VPC) on CloudHub 1,0, and the security team guidelines clearly state no traffic on HTTP.
Which two options support these security guidelines?
Choose 2 answers
正解:C、D
解説:
Security Guidelines Overview:
The production environment is hosted on a dedicated Virtual Private Cloud (VPC) on CloudHub 1.0, with a specific requirement from the security team that no traffic should occur over HTTP. This implies that only secure HTTPS traffic should be permitted, and HTTP access (port 8081, the default HTTP port in Mule applications) should be disabled.
Evaluating the Options:
Option A (Correct Answer): Configuring the HTTPS protocol in the HTTP listener in the Mule application ensures that all traffic is encrypted and occurs over HTTPS (port 8092 by default for HTTPS on Mule applications). This directly aligns with the security guideline to prevent unencrypted HTTP traffic.
Option B: Creating a custom policy for incoming and outgoing HTTP requests could provide some control over access, but it does not enforce the use of HTTPS exclusively. This option does not disable HTTP traffic and, therefore, does not meet the guideline effectively.
Option C (Correct Answer): Removing the entry for HTTP (port 8081) in the VPC firewall rule ensures that HTTP traffic is completely blocked at the firewall level. This prevents any HTTP requests from reaching the application, adding a layer of security that complies with the guidelines.
Option D: The IP Blocklist policy controls access based on IP addresses but does not enforce the use of HTTPS. This policy does not address the specific requirement of preventing HTTP traffic.
Option E: Adding a firewall rule entry for HTTP (port 8081) would enable HTTP traffic, which directly contradicts the security guidelines. Therefore, this option should be avoided.
Conclusion:
Option A and Option C are the correct choices. Configuring the HTTPS protocol in the Mule application's HTTP listener ensures that only HTTPS traffic is allowed, and removing the firewall rule for HTTP (port 8081) blocks any HTTP traffic from reaching the application. Together, these options enforce secure traffic as required by the security guidelines.
Refer to MuleSoft documentation on configuring HTTP listeners and managing VPC firewall rules for further details on implementing these security controls.
質問 # 109
A Platform Architect inherits a legacy monolithic SOAP-based web service that performs a number of tasks, including showing all policies belonging to a client. The service connects to two back-end systems - a life-insurance administration system and a general-insurance administration system - and then queries for insurance policy information within each system, aggregates the results, and presents a SOAP-based response to a user interface (UI).
The architect wants to break up the monolithic web service to follow API-led conventions.
Which part of the service should be put into the process layer?
正解:A
解説:
In the API-led connectivity approach, each layer (System, Process, and Experience) has a distinct purpose:
System APIs: These APIs connect directly to backend systems to expose and unlock data in a standardized way.
Process APIs: These are responsible for orchestrating and processing data across different systems, combining information where needed.
Experience APIs: These are designed for specific user interfaces or applications, often transforming data formats to fit the needs of each consumer application.
Why Option A is Correct:
Process APIs are designed to combine data from multiple systems, which aligns with the function of aggregating policy information from both the life and general insurance systems. This aggregation logic would ideally reside in the Process layer, separating data retrieval from data orchestration.
Moving this functionality to the Process layer enables reusability and modularity, as other Experience APIs or services could also leverage the combined policy data if needed.
of Incorrect Options:
Option B (Presenting the SOAP-based response) would be managed by the Experience layer, as this layer adapts data formats for specific interfaces.
Option C (Authenticating and maintaining backend connections) would typically be handled within the System layer, where backend integration and security handling occurs.
Option D (Querying data) is the function of System APIs, which access the backend systems directly and expose the raw data without additional processing.
Reference
For further details on API-led architecture and the roles of each layer, refer to MuleSoft's documentation on API-led connectivity and API layers.
質問 # 110
When could the API data model of a System API reasonably mimic the data model exposed by the corresponding backend system, with minimal improvements over the backend system's data model?
正解:B
解説:
Correct Answe r: When a pragmatic approach with only limited isolation from the backend system is deemed appropriate.
*****************************************
General guidance w.r.t choosing Data Models:
>> If an Enterprise Data Model is in use then the API data model of System APIs should make use of data types from that Enterprise Data Model and the corresponding API implementation should translate between these data types from the Enterprise Data Model and the native data model of the backend system.
>> If no Enterprise Data Model is in use then each System API should be assigned to a Bounded Context, the API data model of System APIs should make use of data types from the corresponding Bounded Context Data Model and the corresponding API implementation should translate between these data types from the Bounded Context Data Model and the native data model of the backend system. In this scenario, the data types in the Bounded Context Data Model are defined purely in terms of their business characteristics and are typically not related to the native data model of the backend system. In other words, the translation effort may be significant.
>> If no Enterprise Data Model is in use, and the definition of a clean Bounded Context Data Model is considered too much effort, then the API data model of System APIs should make use of data types that approximately mirror those from the backend system, same semantics and naming as backend system, lightly sanitized, expose all fields needed for the given System API's functionality, but not significantly more and making good use of REST conventions.
The latter approach, i.e., exposing in System APIs an API data model that basically mirrors that of the backend system, does not provide satisfactory isolation from backend systems through the System API tier on its own. In particular, it will typically not be possible to "swap out" a backend system without significantly changing all System APIs in front of that backend system and therefore the API implementations of all Process APIs that depend on those System APIs! This is so because it is not desirable to prolong the life of a previous backend system's data model in the form of the API data model of System APIs that now front a new backend system. The API data models of System APIs following this approach must therefore change when the backend system is replaced.
On the other hand:
>> It is a very pragmatic approach that adds comparatively little overhead over accessing the backend system directly
>> Isolates API clients from intricacies of the backend system outside the data model (protocol, authentication, connection pooling, network address, ...)
>> Allows the usual API policies to be applied to System APIs
>> Makes the API data model for interacting with the backend system explicit and visible, by exposing it in the RAML definitions of the System APIs
>> Further isolation from the backend system data model does occur in the API implementations of the Process API tier
質問 # 111
......
Tech4ExamのSalesforceのMule-Arch-201試験トレーニング資料は受験生が模擬試験場で勉強させます。受験生は問題を選べ、テストの時間もコントロールできます。Tech4Examというサイトで、あなたはストレスと不安なく試験の準備をすることができますから、一般的な間違いを避けられます。そうしたら、あなたは自信を得ることができて、実際の試験で経験を活かして気楽に合格します。
Mule-Arch-201日本語認定: https://www.tech4exam.com/Mule-Arch-201-pass-shiken.html
P.S.Tech4ExamがGoogle Driveで共有している無料の2026 Salesforce Mule-Arch-201ダンプ:https://drive.google.com/open?id=1hDn2l-vFTwZqLhGONhn-Vygi1WjAYR16