P.S. JpexamがGoogle Driveで共有している無料かつ新しいMule-Arch-201ダンプ:https://drive.google.com/open?id=15wSlXtDjy6XN1IBIiH__jAUfpZ0w01N_
Mule-Arch-201試験の急流を学び、Mule-Arch-201試験を準備するのに20〜30時間しかかかりません。多くの人々、特に現職のスタッフは仕事、学習、家族生活、その他の重要な事柄で忙しく、Mule-Arch-201試験を学習して準備する時間とエネルギーがほとんどありません。しかし、Mule-Arch-201テストトレントを購入すれば、最も重要なことにメインエネルギーを投資し、試験を学習して準備するために毎日1〜2時間を割くことができます。 Mule-Arch-201試験の質問と回答は実際の試験に基づいており、Salesforce Certified MuleSoft Platform Architect受験者の一般的な傾向に準拠しています。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Understanding the MuleSoft Platform & Application Networks | 11% | - Application Network Fundamentals - MuleSoft Anypoint Platform Core Concepts - C4E (Center for Enablement) Definition |
| Topic 2: Deploying API Implementations to CloudHub | 11% | - Deployment Strategies - CloudHub Architecture - CloudHub 2.0 & Runtime Fabric |
| Topic 3: Meeting API Quality Goals | 8% | - API Performance Optimization - Resilience & Reliability Patterns - Unit & Integration Testing |
| Topic 4: Applying Integration Patterns | 11% | - Integration Scenarios & Patterns - Event-Driven Architecture (EDA) - Batch Processing |
| Topic 5: Designing and Sharing APIs | 11% | - Anypoint Exchange for Sharing Assets - API Design Best Practices - API-Led Connectivity Approach |
| Topic 6: Monitoring and Analyzing Application Networks | 8% | - Alerting & Auditing - Anypoint Monitoring Tools - Analytics & Business Insights |
| Topic 7: Managing APIs | 12% | - API Security (Policies, SLAs) - API Lifecycle Management - API Versioning |
| Topic 8: Establishing Organizational and Platform Foundations | 17% | - Governance and Compliance Framework - Platform Foundation Setup - IT Delivery & C4E Operating Model |
| Topic 9: Architecting and Deploying API Implementations | 11% | - Mule Runtime Architecture - High Availability (HA) Design - Disaster Recovery (DR) Strategies |
Jpexam製品を購入する前に、Mule-Arch-201学習ツールを無料でダウンロードして試用できます。 Webサイト上の製品のページでデモを提供しているため、タイトルの一部とMule-Arch-201テストトレントの形式を理解できます。 Webサイトで製品のページにアクセスすると、更新時間、3つのバージョンを選択できます。 Mule-Arch-201ガイド急流の答えとタイトルと内容のフォームを確認してください。弊社のMule-Arch-201テストトレントを購入する価値があると思われる場合は、お好みのバージョンを選択できます。
質問 # 69
An organization is deploying their new implementation of the OrderStatus System API to multiple workers in CloudHub. This API fronts the organization's on-premises Order Management System, which is accessed by the API implementation over an IPsec tunnel.
What type of error typically does NOT result in a service outage of the OrderStatus System API?
正解:C
解説:
Correct Answe r: A CloudHub worker fails with an out-of-memory exception.
*****************************************
>> An AWS Region itself going down will definitely result in an outage as it does not matter how many workers are assigned to the Mule App as all of those in that region will go down. This is a complete downtime and outage.
>> Extended outage of API manager during initial deployment of API implementation will of course cause issues in proper application startup itself as the API Autodiscovery might fail or API policy templates and polices may not be downloaded to embed at the time of applicaiton startup etc... there are many reasons that could cause issues.
>> A network outage onpremises would of course cause the Order Management System not accessible and it does not matter how many workers are assigned to the app they all will fail and cause outage for sure.
The only option that does NOT result in a service outage is if a cloudhub worker fails with an out-of-memory exception. Even if a worker fails and goes down, there are still other workers to handle the requests and keep the API UP and Running. So, this is the right answer.
質問 # 70
A company deployed an API to a single worker/replica in the shared cloud in the U.S. West Region.
What happens when the Availability Zone experiences an outage?
正解:D
解説:
In a CloudHub deployment with a single worker/replica located in a specific Availability Zone (AZ), if an AZ experiences an outage, here's what happens:
Worker Availability: Since the application is deployed in a single AZ, CloudHub does not automatically redeploy the application in a different zone or region during an outage. Thus, if the current AZ is unavailable, the application will be offline.
Auto-Restart upon AZ Recovery: Once the affected AZ is back online, CloudHub will auto-restart the worker in the same AZ without manual intervention. This ensures that as soon as the AZ is functional, the application resumes automatically.
of Correct Answer (B):
Option B accurately describes the situation, as the API will remain unavailable until the original AZ is restored.
CloudHub does not currently support automatic failover across regions or other availability zones within the same region for single-worker deployments on the shared cloud.
of Incorrect Options:
Option A (auto-redeployment in the U.S. East region) is incorrect, as CloudHub does not migrate across regions automatically.
Option C (redeployment in another AZ within the U.S. West) is not a feature for single-worker deployments.
Option D (manual redeployment triggered by an admin) is unnecessary as CloudHub handles restarts automatically when the AZ is back online.
Reference
Refer to MuleSoft CloudHub's availability and disaster recovery documentation for more information on how CloudHub manages availability in shared environments.
質問 # 71
A system API has a guaranteed SLA of 100 ms per request. The system API is deployed to a primary environment as well as to a disaster recovery (DR) environment, with different DNS names in each environment. An upstream process API invokes the system API and the main goal of this process API is to respond to client requests in the least possible time. In what order should the system APIs be invoked, and what changes should be made in order to speed up the response time for requests from the process API?
正解:A
解説:
Correct Answe r: In parallel, invoke the system API deployed to the primary environment and the system API deployed to the DR environment, and ONLY use the first response.
*****************************************
>> The API requirement in the given scenario is to respond in least possible time.
>> The option that is suggesting to first try the API in primary environment and then fallback to API in DR environment would result in successful response but NOT in least possible time. So, this is NOT a right choice of implementation for given requirement.
>> Another option that is suggesting to ONLY invoke API in primary environment and to add timeout and retries may also result in successful response upon retries but NOT in least possible time. So, this is also NOT a right choice of implementation for given requirement.
>> One more option that is suggesting to invoke API in primary environment and API in DR environment in parallel using Scatter-Gather would result in wrong API response as it would return merged results and moreover, Scatter-Gather does things in parallel which is true but still completes its scope only on finishing all routes inside it. So again, NOT a right choice of implementation for given requirement The Correct choice is to invoke the API in primary environment and the API in DR environment parallelly, and using ONLY the first response received from one of them.
質問 # 72
An organization uses various cloud-based SaaS systems and multiple on-premises systems. The on-premises systems are an important part of the organization's application network and can only be accessed from within the organization's intranet.
What is the best way to configure and use Anypoint Platform to support integrations with both the cloud-based SaaS systems and on-premises systems?
A) Use CloudHub-deployed Mule runtimes in an Anypoint VPC managed by Anypoint Platform Private Cloud Edition control plane B) Use CloudHub-deployed Mule runtimes in the shared worker cloud managed by the MuleSoft-hosted Anypoint Platform control plane C) Use an on-premises installation of Mule runtimes that are completely isolated with NO external network access, managed by the Anypoint Platform Private Cloud Edition control plane D) Use a combination of Cloud Hub-deployed and manually provisioned on-premises Mule runtimes managed by the MuleSoft-hosted Anypoint Platform control plane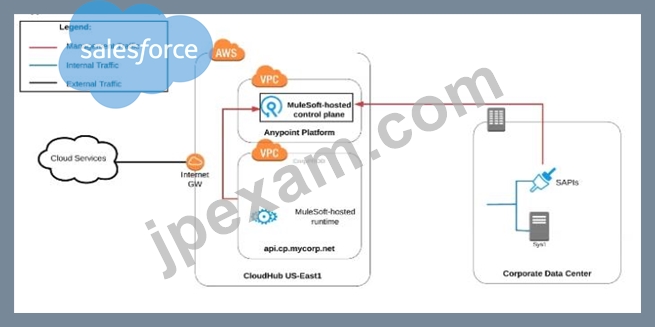
正解:C
解説:
Correct Answe r: Use a combination of CloudHub-deployed and manually provisioned on-premises Mule runtimes managed by the MuleSoft-hosted Platform control plane.
*****************************************
Key details to be taken from the given scenario:
>> Organization uses BOTH cloud-based and on-premises systems
>> On-premises systems can only be accessed from within the organization's intranet Let us evaluate the given choices based on above key details:
>> CloudHub-deployed Mule runtimes can ONLY be controlled using MuleSoft-hosted control plane. We CANNOT use Private Cloud Edition's control plane to control CloudHub Mule Runtimes. So, option suggesting this is INVALID
>> Using CloudHub-deployed Mule runtimes in the shared worker cloud managed by the MuleSoft-hosted Anypoint Platform is completely IRRELEVANT to given scenario and silly choice. So, option suggesting this is INVALID
>> Using an on-premises installation of Mule runtimes that are completely isolated with NO external network access, managed by the Anypoint Platform Private Cloud Edition control plane would work for On-premises integrations. However, with NO external access, integrations cannot be done to SaaS-based apps. Moreover CloudHub-hosted apps are best-fit for integrating with SaaS-based applications. So, option suggesting this is BEST WAY.
The best way to configure and use Anypoint Platform to support these mixed/hybrid integrations is to use a combination of CloudHub-deployed and manually provisioned on-premises Mule runtimes managed by the MuleSoft-hosted Platform control plane.
質問 # 73
An organization has created an API-led architecture that uses various API layers to integrate mobile clients with a backend system. The backend system consists of a number of specialized components and can be accessed via a REST API. The process and experience APIs share the same bounded-context model that is different from the backend data model. What additional canonical models, bounded-context models, or anti-corruption layers are best added to this architecture to help process data consumed from the backend system?
正解:A
解説:
Correct Answe r: Create a bounded-context model for the system layer to closely match the backend data model, and add an anti-corruption layer to let the different bounded contexts cooperate across the system and process layers
*****************************************
>> Canonical models are not an option here as the organization has already put in efforts and created bounded-context models for Experience and Process APIs.
>> Anti-corruption layers for ALL APIs is unnecessary and invalid because it is mentioned that experience and process APIs share same bounded-context model. It is just the System layer APIs that need to choose their approach now.
>> So, having an anti-corruption layer just between the process and system layers will work well. Also to speed up the approach, system APIs can mimic the backend system data model.
質問 # 74
......
あなたがSalesforce Mule-Arch-201試験に順調に合格できるのは我々の目標です。そして、あなたがMule-Arch-201試験に合格できるのは弊社が存在する意義です。だから、弊社は全力を尽くしてSalesforce Mule-Arch-201試験資料を改善し、試験制度の変更に応じて更新します。あなたはMule-Arch-201試験資料の最新版の問題集を使用できるために、ご購入の一年間で無料の更新を提供します。
Mule-Arch-201合格体験記: https://www.jpexam.com/Mule-Arch-201_exam.html
2026年Jpexamの最新Mule-Arch-201 PDFダンプおよびMule-Arch-201試験エンジンの無料共有:https://drive.google.com/open?id=15wSlXtDjy6XN1IBIiH__jAUfpZ0w01N_