What's more, part of that GuideTorrent Databricks-Generative-AI-Engineer-Associate dumps now are free: https://drive.google.com/open?id=1AGJBayp2wtJ7DuPtXmVWYV2SqQ8NBTMV
Are you still feeling uncomfortable about giving up a lot of time to entertain, work or accompany your family and friends in preparation for the exam? Using Databricks-Generative-AI-Engineer-Associate Quiz torrent, you can spend less time and effort reviewing and preparing, which will help you save a lot of time and energy. When some candidates trying to overcome an exam, they will all first think of choosing a good study material to prepare for their exam. The Databricks Certified Generative AI Engineer Associate prep torrent has a variety of self-learning and self-assessment functions to test learning outcome, which will help you increase confidence to pass exam.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
>> Test Databricks Databricks-Generative-AI-Engineer-Associate Engine <<
Our APP online version of Databricks-Generative-AI-Engineer-Associate exam questions has the advantage of supporting all electronic equipment. You just need to download the online version of our Databricks-Generative-AI-Engineer-Associate preparation dumps, and you can use our Databricks-Generative-AI-Engineer-Associate study quiz by any electronic equipment. We can promise that the online version will not let you down. We believe that you will benefit a lot from it if you buy our Databricks-Generative-AI-Engineer-Associate training materials.
NEW QUESTION # 77
A Generative AI Engineer is tasked with deploying an application that takes advantage of a custom MLflow Pyfunc model to return some interim results.
How should they configure the endpoint to pass the secrets and credentials?
Answer: A
Explanation:
Context: Deploying an application that uses an MLflow Pyfunc model involves managing sensitive information such as secrets and credentials securely.
Explanation of Options:
* Option A: Use spark.conf.set(): While this method can pass configurations within Spark jobs, using it for secrets is not recommended because it may expose them in logs or Spark UI.
* Option B: Pass variables using the Databricks Feature Store API: The Feature Store API is designed for managing features for machine learning, not for handling secrets or credentials.
* Option C: Add credentials using environment variables: This is a common practice for managing credentials in a secure manner, as environment variables can be accessed securely by applications without exposing them in the codebase.
* Option D: Pass the secrets in plain text: This is highly insecure and not recommended, as it exposes sensitive information directly in the code.
Therefore,Option Cis the best method for securely passing secrets and credentials to an application, protecting them from exposure.
NEW QUESTION # 78
A generative AI engineer is deploying an AI agent authored with MLflow's ChatAgent interface for a retail company ' s customer support system on Databricks. The agent must handle thousands of inquiries daily, and the engineer needs to track its performance and quality in real-time to ensure it meets service-level agreements. Which metrics are automatically captured by default and made available for monitoring when the agent is deployed using the Mosaic AI Agent Framework?
Answer: D
Explanation:
When deploying an agent via the Mosaic AI Agent Framework (which leverages Databricks Model Serving), operational metrics are captured automatically by default. These include system-level telemetry such as the number of requests per second (volume), the time taken for the model to respond (latency), and the rate of 4xx
/5xx HTTP errors. These are essential for monitoring Service Level Agreements (SLAs). However, Quality metrics (B), such as correctness, groundedness, or adherence to custom guidelines, cannot be determined " automatically " by the serving infrastructure because they require either human feedback or an LLM-as-a- judge evaluation (using Databricks Agent Evaluation). While Databricks makes it easy to generate quality metrics using the mlflow.evaluate API or the inference table, they are not " default operational metrics " that appear without additional evaluation configuration.
NEW QUESTION # 79
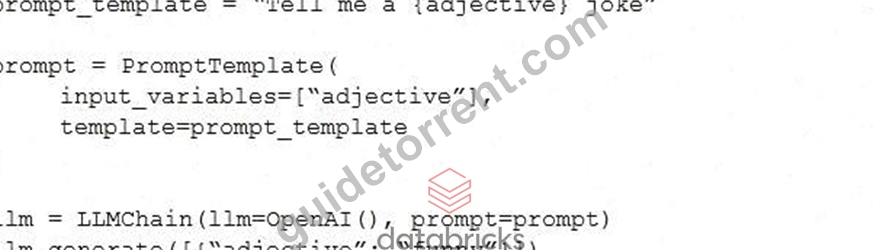
A Generative AI Engineer is testing a simple prompt template in LangChain using the code below, but is getting an error.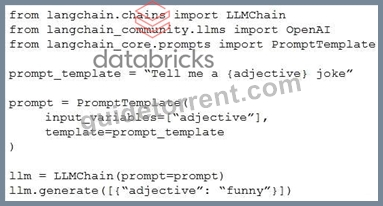
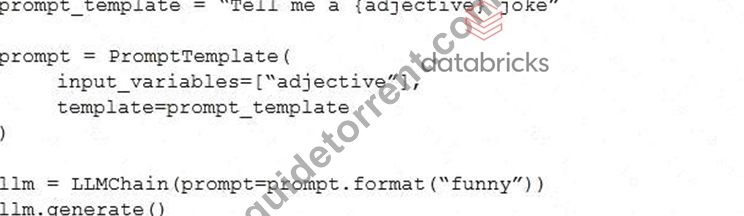
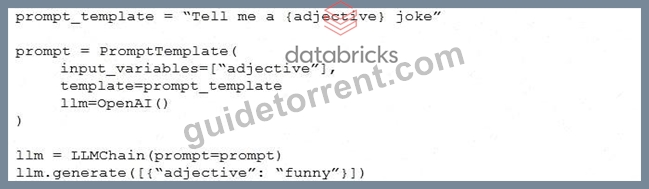
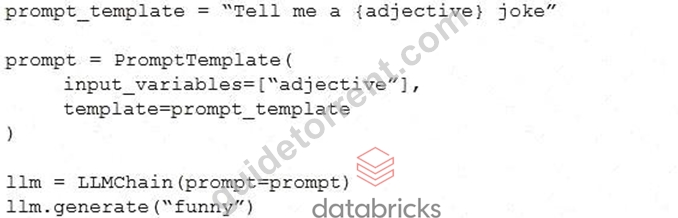
Assuming the API key was properly defined, what change does the Generative AI Engineer need to make to fix their chain?
Answer: B
Explanation:
To fix the error in the LangChain code provided for using a simple prompt template, the correct approach is Option C. Here ' s a detailed breakdown of why Option C is the right choice and how it addresses the issue:
* Proper Initialization : In Option C, the LLMChain is correctly initialized with the LLM instance specified as OpenAI(), which likely represents a language model (like GPT) from OpenAI. This is crucial as it specifies which model to use for generating responses.
* Correct Use of Classes and Methods :
* The PromptTemplate is defined with the correct format, specifying that adjective is a variable within the template. This allows dynamic insertion of values into the template when generating text.
* The prompt variable is properly linked with the PromptTemplate, and the final template string is passed correctly.
* The LLMChain correctly references the prompt and the initialized OpenAI() instance, ensuring that the template and the model are properly linked for generating output.
Why Other Options Are Incorrect:
* Option A : Misuses the parameter passing in generate method by incorrectly structuring the dictionary.
* Option B : Incorrectly uses prompt.format method which does not exist in the context of LLMChain and PromptTemplate configuration, resulting in potential errors.
* Option D : Incorrect order and setup in the initialization parameters for LLMChain, which would likely lead to a failure in recognizing the correct configuration for prompt and LLM usage.
Thus, Option C is correct because it ensures that the LangChain components are correctly set up and integrated, adhering to proper syntax and logical flow required by LangChain ' s architecture. This setup avoids common pitfalls such as type errors or method misuses, which are evident in other options.
NEW QUESTION # 80
A Generative Al Engineer is tasked with developing a RAG application that will help a small internal group of experts at their company answer specific questions, augmented by an internal knowledge base. They want the best possible quality in the answers, and neither latency nor throughput is a huge concern given that the user group is small and they're willing to wait for the best answer. The topics are sensitive in nature and the data is highly confidential and so, due to regulatory requirements, none of the information is allowed to be transmitted to third parties.
Which model meets all the Generative Al Engineer's needs in this situation?
Answer: B
Explanation:
Problem Context : The Generative AI Engineer needs a model for a Retrieval-Augmented Generation (RAG) application that provides high-quality answers, where latency and throughput are not major concerns.
The key factors are confidentiality and sensitivity of the data, as well as the requirement for all processing to be confined to internal resources without external data transmission.
Explanation of Options :
* Option A: Dolly 1.5B : This model does not typically support RAG applications as it ' s more focused on image generation tasks.
* Option B: OpenAI GPT-4 : While GPT-4 is powerful for generating responses, its standard deployment involves cloud-based processing, which could violate the confidentiality requirements due to external data transmission.
* Option C: BGE-large : The BGE (Big Green Engine) large model is a suitable choice if it is configured to operate on-premises or within a secure internal environment that meets regulatory requirements. Assuming this setup, BGE-large can provide high-quality answers while ensuring that data is not transmitted to third parties, thus aligning with the project ' s sensitivity and confidentiality needs.
* Option D: Llama2-70B : Similar to GPT-4, unless specifically set up for on-premises use, it generally relies on cloud-based services, which might risk confidential data exposure.
Given the sensitivity and confidentiality concerns, BGE-large is assumed to be configurable for secure internal use, making it the optimal choice for this scenario.
NEW QUESTION # 81
A company has a typical RAG-enabled, customer-facing chatbot on its website.
Select the correct sequence of components a user's questions will go through before the final output is returned. Use the diagram above for reference.
Answer: D
Explanation:
To understand how a typical RAG-enabled customer-facing chatbot processes a user's question, let's go through the correct sequence as depicted in the diagram and explained in option A:
* Embedding Model (1):The first step involves the user's question being processed through an embedding model. This model converts the text into a vector format that numerically represents the text. This step is essential for allowing the subsequent vector search to operate effectively.
* Vector Search (2):The vectors generated by the embedding model are then used in a vector search mechanism. This search identifies the most relevant documents or previously answered questions that are stored in a vector format in a database.
* Context-Augmented Prompt (3):The information retrieved from the vector search is used to create a context-augmented prompt. This step involves enhancing the basic user query with additional relevant information gathered to ensure the generated response is as accurate and informative as possible.
* Response-Generating LLM (4):Finally, the context-augmented prompt is fed into a response- generating large language model (LLM). This LLM uses the prompt to generate a coherent and contextually appropriate answer, which is then delivered as the final output to the user.
Why Other Options Are Less Suitable:
* B, C, D: These options suggest incorrect sequences that do not align with how a RAG system typically processes queries. They misplace the role of embedding models, vector search, and response generation in an order that would not facilitate effective information retrieval and response generation.
Thus, the correct sequence isembedding model, vector search, context-augmented prompt, response- generating LLM, which is option A.
NEW QUESTION # 82
......
With Databricks-Generative-AI-Engineer-Associate test answers, you are not like the students who use other materials. As long as the syllabus has changed, they need to repurchase new learning materials. This not only wastes a lot of money, but also wastes a lot of time. Our industry experts are constantly adding new content to Databricks-Generative-AI-Engineer-Associate test dumps based on constantly changing syllabus and industry development breakthroughs. All the language used in Databricks-Generative-AI-Engineer-Associate Study Materials is very simple and easy to understand. With Databricks-Generative-AI-Engineer-Associate test answers, you don't have to worry about that you don't understand the content of professional books. You also don't need to spend expensive tuition to go to tutoring class. Databricks-Generative-AI-Engineer-Associate test dumps can help you solve all the problems in your study.
Free Databricks-Generative-AI-Engineer-Associate Pdf Guide: https://www.guidetorrent.com/Databricks-Generative-AI-Engineer-Associate-pdf-free-download.html
P.S. Free 2026 Databricks Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by GuideTorrent: https://drive.google.com/open?id=1AGJBayp2wtJ7DuPtXmVWYV2SqQ8NBTMV