2026 DP-750 Test Pdf 100% Pass | Trustable Implementing Data Engineering Solutions Using Azure Databricks Latest Learning Materials Pass for sure

Our company have the higher class operation system than other companies, so we can assure you that you can start to prepare for the DP-750 exam with our study materials in the shortest time. In addition, if you decide to buy the DP-750 study materials from our company, we can make sure that your benefits will far exceed the costs of you. The rate of return will be very obvious for you. We sincerely reassure all people on the DP-750 Study Materials from our company and enjoy the benefits that our study materials bring.
| Section | Weight | Objectives |
|---|
| Deploy and maintain data pipelines and workloads | 30–35% | - Build and orchestrate pipelines
- 1. Implement CI/CD with Git, Databricks Asset Bundles, CLI, and APIs
- 2. Configure Lakeflow Jobs: schedules, triggers, alerts, retries
- 3. Design and implement Lakeflow Spark Declarative Pipelines
- Monitor, troubleshoot, and maintain workloads
- 1. Apply SDLC practices and version control
- 2. Troubleshoot failures, repair and restart jobs
- 3. Monitor performance, logs, and execution metrics
|
| Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
- 1. Manage workspace settings, permissions, and networking
- 2. Choose compute types: serverless, job compute, SQL warehouse, classic compute
- 3. Configure cluster policies, instance pools, and libraries
- Integrate with Azure services
- 1. Connect to Azure Data Lake Storage, Azure Data Factory, Microsoft Entra ID
- 2. Configure monitoring with Azure Monitor and diagnostic settings
|
| Prepare and process data | 30–35% | - Optimize and manage data storage
- 1. Optimize Delta tables: partitioning, Z-ordering, vacuum, optimize
- 2. Handle structured, semi-structured, and unstructured data
- 3. Implement lakehouse architecture and manage table versions
- Ingest and transform data
- 1. Ingest batch and streaming data from multiple sources
- 2. Implement schema enforcement, schema drift, and slowly changing dimensions
- 3. Transform using Spark SQL, PySpark, Scala, and Delta Lake
|
| Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
- 1. Configure access control: row-level, column-level, attribute-based security
- 2. Enforce data quality, lineage, and auditing
- 3. Manage catalogs, schemas, tables, views, and volumes
- Manage data sharing and permissions
- 1. Grant and revoke permissions, manage groups and service principals
- 2. Set up external locations and storage credentials
|
>> DP-750 Test Pdf <<
Pass-Sure DP-750 Test Pdf & Perfect DP-750 Latest Learning Materials Ensure You a High Passing Rate
We did not gain our high appraisal by our DP-750 exam practice for nothing and there is no question that our DP-750 practice materials will be your perfect choice. First, you can see the high hit rate on the website that can straightly proved our DP-750 study braindumps are famous all over the world. Secondly, you can free download the demos to check the quality, and you will be surprised to find we have a high pass rate as 98% to 100%.
Microsoft Implementing Data Engineering Solutions Using Azure Databricks Sample Questions (Q88-Q93):
NEW QUESTION # 88
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to implement a daily batch data process that requires complex and highly customized Python transformations. The solution must minimize additional complexity.
What should you include in the solution?
- A. a continuous job in Lakeflow Jobs
- B. a Databricks notebook triggered by a job
- C. an Azure Data Factory pipeline that has data flows
- D. a Lakeflow Spark Declarative Pipelines (SDP) pipeline
Answer: B
Explanation:
A Databricks notebook provides the flexibility required to implement complex, highly customized Python and PySpark transformations. Scheduling that notebook as a Lakeflow Jobs task supplies native daily orchestration, monitoring, retries, and compute management without introducing another service. Azure Data Factory data flows are oriented toward visually designed transformations and would add external orchestration complexity for logic already implemented most naturally in Python. A continuous job is inappropriate because the workload runs once per day rather than continuously. Spark Declarative Pipelines is effective for declarative batch and streaming ETL, but it is less direct when the core requirement emphasizes highly customized procedural Python transformations. A notebook task therefore provides the necessary programming freedom while keeping scheduling and operation inside Azure Databricks.
NEW QUESTION # 89
You have an Azure Databricks workspace that uses serverless compute.
You need to ingest data by using Lakeflow Jobs. New records must be processed as soon as they become available.
Which type of job trigger should you use for the ingestion?
- A. scheduled
- B. file arrival
- C. continuous
- D. manual
Answer: C
Explanation:
The best trigger type for this scenario is the Continuous trigger.
Immediate Processing: The Continuous trigger mode processes new records as soon as they arrive at the configured data sources. This matches your requirement to ingest and process records without waiting for an artificial time interval.
Native Serverless Support: When paired with serverless compute, Lakeflow Jobs efficiently manage resources by automatically scaling up or down according to the real-time stream volume.
Built-in Fault Tolerance: Continuous pipelines on Databricks automatically handle failures by retrying with an exponential backoff policy, keeping your automated ingestion operational 24/7 without manual intervention.
Reference:
https://docs.databricks.com/aws/en/jobs/continuous
NEW QUESTION # 90
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.fillna(0, subset=['order_amount'])
Does this meet the goal?
Answer: B
Explanation:
Correct:
* You run the following expression.
df.dropna(subset=["order_amount"])
The expression df.dropna(subset=["order_amount"]) is an appropriate and effective way to exclude rows where order_amount is null.
* You run the following expression.
df.filter(df.order_amount.isNotNull())
To exclude rows where the order amount is null, you can use the isNotNull() method or a SQL expression within the filter() or where() functions.Here are the standard, appropriate expressions:
Option 1: Python/PySpark API (Recommended)
pythondf_clean = df.filter(df["order_amount"].isNotNull())
Incorrect:
* You run the following expression.
df.fillna(0, subset=['order_amount'])
* You run the following expression.
df.filter(df.order_amount != None)
Reference:
https://www.geeksforgeeks.org/python/filter-pyspark-dataframe-columns-with-none-or-null-values/
https://learn.microsoft.com/en-us/azure/databricks/pyspark/reference/classes/dataframe/dropna
NEW QUESTION # 91
Which feature helps reduce data scan during query execution in Delta Lake?
- A. VACUUM
- B. Data skipping using statistics
- C. VACUUM retention override
- D. Cluster restart
Answer: B
Explanation:
Delta Lake uses data skipping based on file-level statistics (min/max values). This reduces unnecessary file scans and improves query performance. VACUUM removes old files but does not improve query speed. Cluster restart has no impact on query optimization.
NEW QUESTION # 92
Which SCD type should you use to support the planned data modeling changes? To answer, drag the appropriate types to the correct issues. Each type may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
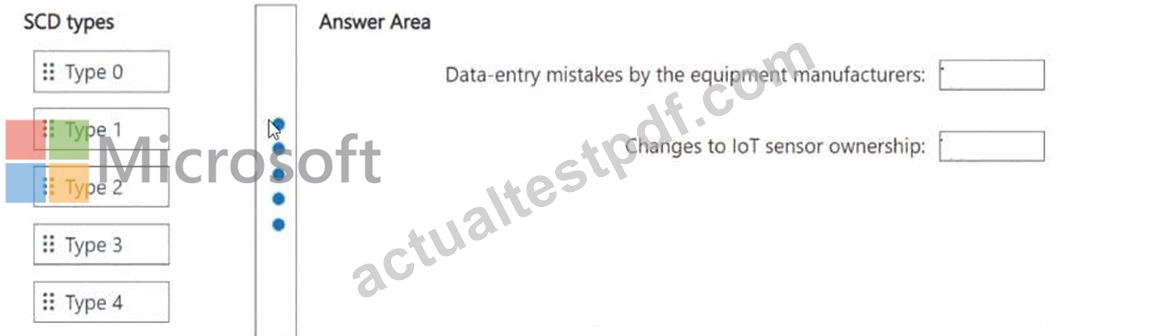
Answer:
Explanation:
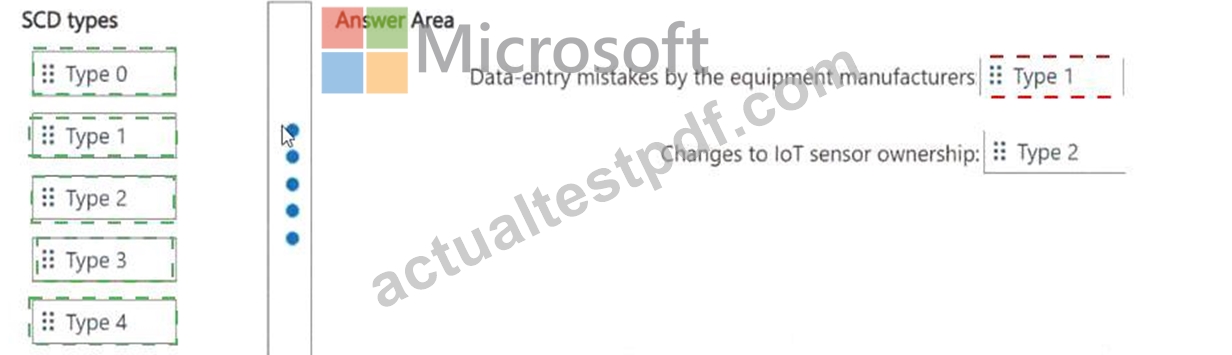
Explanation:
The correct mapping is SCD Type 1 for equipment metadata and SCD Type 2 for IoT sensor ownership history.
SCD Type 1 overwrites the existing record whenever an attribute changes - no history is kept. Contoso's requirement for equipment metadata (name, manufacturer, model, commissioning date) states 'historical values are NOT required,' which is the textbook definition of Type 1. A MERGE INTO with WHEN MATCHED THEN UPDATE handles this cleanly in Delta Lake.
SCD Type 2 creates a new row for each change, preserving the full history through effective-date or version columns. Contoso requires that 'analysts must track the full history of ownership' as sensors change hands over time - that full audit trail is only possible with Type 2. Type 3 (keeping just the previous value in an extra column) would lose earlier ownership records, so it doesn't satisfy the 'full history' requirement.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/merge
NEW QUESTION # 93
......
ActualtestPDF is a reputable platform that has been providing valid, real, updated, and free Implementing Data Engineering Solutions Using Azure Databricks DP-750 Exam Questions for many years. ActualtestPDF is now the customer's first choice and has the best reputation in the market. Microsoft DP-750 Actual Dumps are created by experienced and certified professionals to provide you with everything you need to learn, prepare for, and pass the difficult Microsoft DP-750 exam on your first try.
DP-750 Latest Learning Materials: https://www.actualtestpdf.com/Microsoft/DP-750-practice-exam-dumps.html
- Exam DP-750 Cram Questions 🏹 Well DP-750 Prep 🚍 Test DP-750 Simulator Online 🧫 Copy URL ➡ www.troytecdumps.com ️⬅️ open and search for ▶ DP-750 ◀ to download for free 🍒DP-750 Testdump
- DP-750 Test Pdf – Reliable Latest Learning Materials Providers for Microsoft DP-750: Implementing Data Engineering Solutions Using Azure Databricks 🧜 Copy URL ⇛ www.pdfvce.com ⇚ open and search for 「 DP-750 」 to download for free 🎆Exam DP-750 Outline
- 2026 Microsoft Unparalleled DP-750: Implementing Data Engineering Solutions Using Azure Databricks Test Pdf 🔹 Open ☀ www.practicevce.com ️☀️ enter ✔ DP-750 ️✔️ and obtain a free download 💝DP-750 Latest Exam Experience
- DP-750 Practice Braindumps 🔓 DP-750 Testdump 🔨 DP-750 Passleader Review 🦱 Download ⇛ DP-750 ⇚ for free by simply searching on ➥ www.pdfvce.com 🡄 🍎Exam DP-750 Outline
- 2026 Microsoft Unparalleled DP-750: Implementing Data Engineering Solutions Using Azure Databricks Test Pdf 💰 Search for ➥ DP-750 🡄 on 《 www.torrentvce.com 》 immediately to obtain a free download 🧲Latest DP-750 Guide Files
- Well DP-750 Prep ✨ Latest DP-750 Test Report 🕥 DP-750 Real Testing Environment ⤵ Simply search for ▷ DP-750 ◁ for free download on 《 www.pdfvce.com 》 🎢Exam DP-750 Outline
- DP-750 Latest Test Braindumps ⏲ DP-750 Latest Test Braindumps 💟 DP-750 Valid Test Pdf 🚔 《 www.easy4engine.com 》 is best website to obtain ▛ DP-750 ▟ for free download 👔Well DP-750 Prep
- DP-750 Latest Test Prep 🏮 Latest DP-750 Test Report 🎶 DP-750 Passleader Review 🌳 Search for “ DP-750 ” and easily obtain a free download on ➥ www.pdfvce.com 🡄 💏Latest DP-750 Test Report
- Crack Your Exam with www.examcollectionpass.com DP-750 Implementing Data Engineering Solutions Using Azure Databricks Practice Questions 💙 Simply search for ⮆ DP-750 ⮄ for free download on 《 www.examcollectionpass.com 》 🛺Latest DP-750 Guide Files
- New Release Microsoft DP-750 Dumps For Brilliant Exam Study 2026 😓 Open ✔ www.pdfvce.com ️✔️ enter “ DP-750 ” and obtain a free download 🚖Valid DP-750 Exam Pattern
- Free PDF 2026 Microsoft Unparalleled DP-750 Test Pdf 🧭 Easily obtain ☀ DP-750 ️☀️ for free download through ▶ www.exam4labs.com ◀ 🥎New DP-750 Exam Practice
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.impactio.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes