高収入をもたらす良い仕事を見つけたいですか?あなたは優秀な才能になりたいですか? CCAR-P認定は、あなたが望む夢を実現するのに役立ちます。なぜなら、AnthropicのCCAR-Pテスト準備は、仕事を探しているときに明らかな利点があることを証明でき、仕事を非常にうまく処理できるからです。そのため、CCAR-P試験の準備は、CCAR-P試験に合格して良い仕事を見つけるのに役立ちます。何を待っていますか? CCAR-P試験問題を購入してください。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Stakeholder Communication & Lifecycle Management | 14% | - Communicating architectural decisions - Solution lifecycle management - Architecture documentation - Discovery and requirements gathering - Stakeholder management - Service-level agreements |
| Topic 2: Developer Productivity & Operational Enablement | 7% | - Claude tooling configuration for teams - Developer enablement - Debugging and operational issue resolution - AI-assisted developer workflows |
| Topic 3: Solution Design & Architecture | 17% | - Decomposition techniques for complex problem solving - Translating business problems into Claude-based AI solutions - Alignment with business value, cost, performance, and SLAs - Multi-agent systems and orchestration - End-to-end architecture design - Architectural patterns
|
| Topic 4: Evaluation, Testing & Optimization | 16% | - Cost and performance optimization - Production monitoring and optimization - Evaluation framework design - Evaluation metrics and datasets - System issue diagnosis - A/B testing |
| Topic 5: Governance, Safety & Risk Management | 14% | - AI safety and guardrails - Human-in-the-loop validation - Regulatory and compliance requirements - Ethical AI considerations - Security and risk management |
| Topic 6: Claude Models, Prompting & Context Engineering | 13% | - Context window optimization - Guardrails - Prompt reuse and context engineering strategies - System prompts and prompt templates - Claude model selection and trade-offs |
| Topic 7: Integration | 19% | - Claude integration mechanisms
- Authentication and authorization analysis - RAG pipeline design
|
IT職員の一員として、今のCCAR-P試験資料を知っていますか?もし了解しなかったら、CCAR-P試験に合格するかどうか心配する必要がありません。弊社はCCAR-P試験政策の変化に応じて、CCAR-P試験資料を定期的に更新しています。こうした、お客様に全面的かつ高品質のCCAR-P試験資料を提供できます。CCAR-P試験に合格するために、お客様は今からCCAR-P試験資料を手に入りましょう!
質問 # 21
You are evaluating prompting claims in a peer's design document.
For each claim, select yes if the claim reflects sound practice. Otherwise, select no.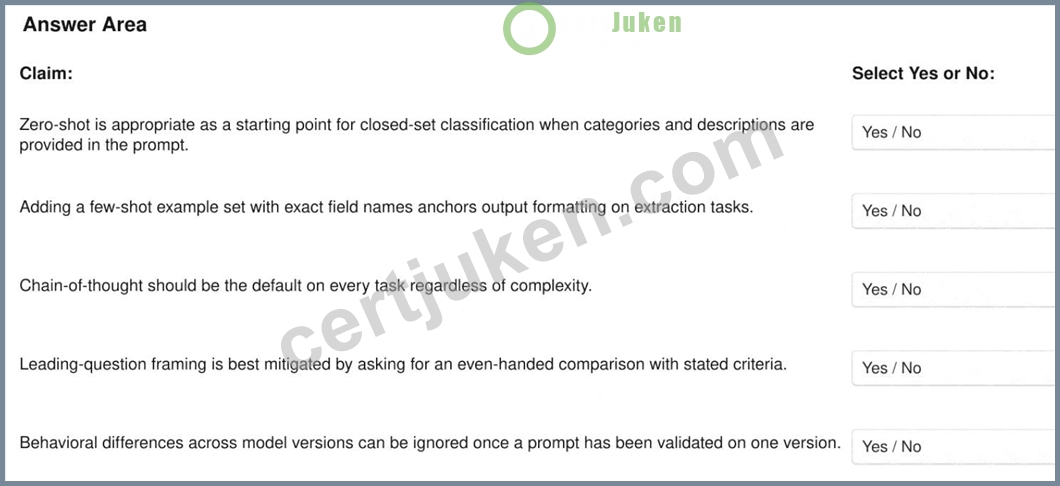
正解:
解説: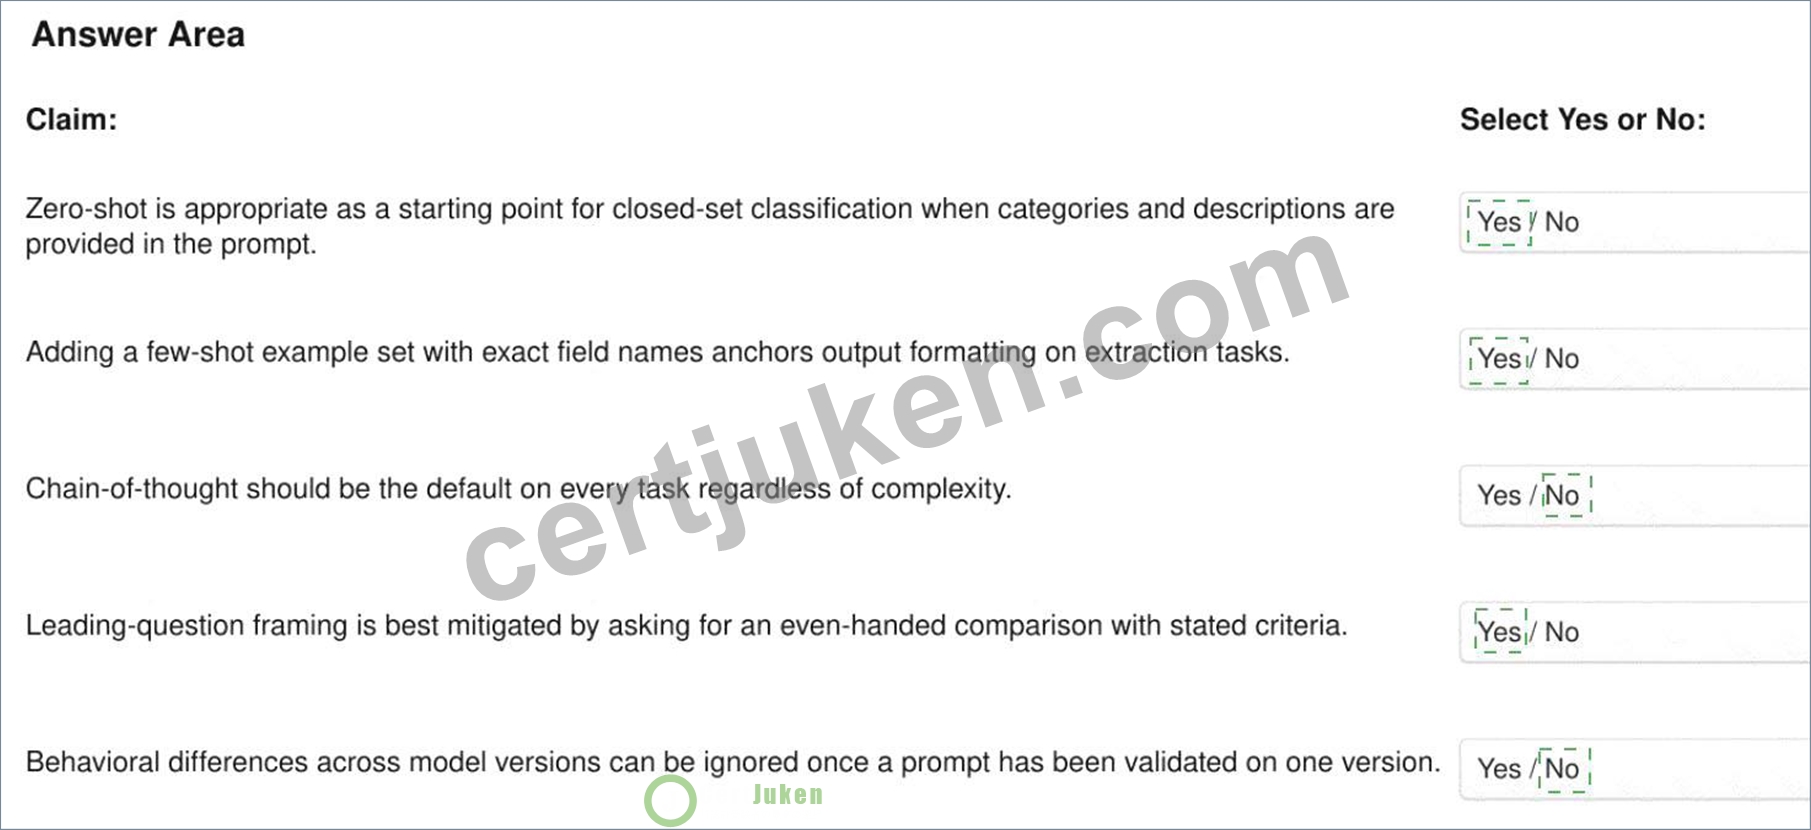
Explanation:
Yes, Yes, No, Yes, No
Zero-shot prompting is a reasonable baseline for a clearly defined closed-set classifier because the model receives both the permissible labels and their meanings. Performance should then be measured against an evaluation set before additional prompt complexity is introduced. Few-shot examples are also sound for extraction because examples containing the exact field names demonstrate the required schema and reduce formatting ambiguity. Anthropic identifies examples as one of the most reliable methods for steering output format, structure, and consistency. Prompting Best Practices Chain-of-thought is not an unconditional default. Additional reasoning is appropriate when the task requires substantive decomposition or complex judgment, but routine classification and extraction may gain little while consuming more tokens and increasing latency. The technique should be selected according to evaluated task requirements.
An even-handed comparison governed by explicit criteria mitigates leading-question bias by requiring symmetrical treatment of alternatives rather than presupposing a preferred conclusion. Finally, prompt validation is model-specific. New model versions may follow instructions differently, change formatting behavior, alter tool selection, or produce different latency and cost characteristics. Anthropic's migration guidance consequently recommends reevaluating prompts and workloads against the new baseline. Model Migration Guide Study Guide references/topics: Zero-shot prompting; few-shot examples; reasoning techniques; neutral framing; model migration and regression evaluation.
質問 # 22
A technical team is cataloguing risks specific to Claude's use in a document-grounded Q & A system.
Which two items represent failure modes intrinsic to LLM-based systems rather than generic software defects? (Select two.)
正解:A、C
解説:
Over-refusal and hallucination are characteristic model-behavior risks. An overly broad safety response can reject a legitimate request even when the surrounding application operates correctly. A plausible but unsupported answer is a groundedness failure arising from probabilistic generation and inadequate source adherence. These risks require model-specific evaluations, grounding instructions, citations, verification, and calibrated fallback behavior. Expired certificates, database timeouts, and load-balancer misconfiguration are conventional distributed-system failures that should be addressed through infrastructure monitoring, retries, health checks, and configuration management. Distinguishing these categories matters because ordinary software remediation will not resolve behavioral failures, while prompt changes will not repair infrastructure.
Anthropic's hallucination guidance recommends auditable citations and supporting evidence for generated claims. Reducing hallucinations
質問 # 23
You are classifying token-management tactics by where each tactic applies in the request lifecycle: "Input Preparation," "Prompt Construction," or "Output Handling."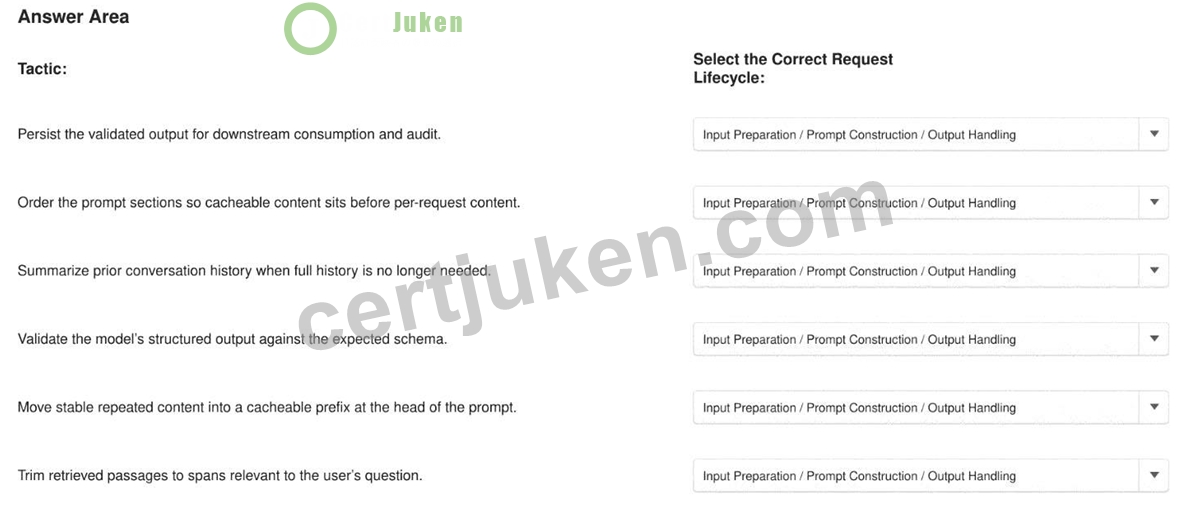
正解:
解説: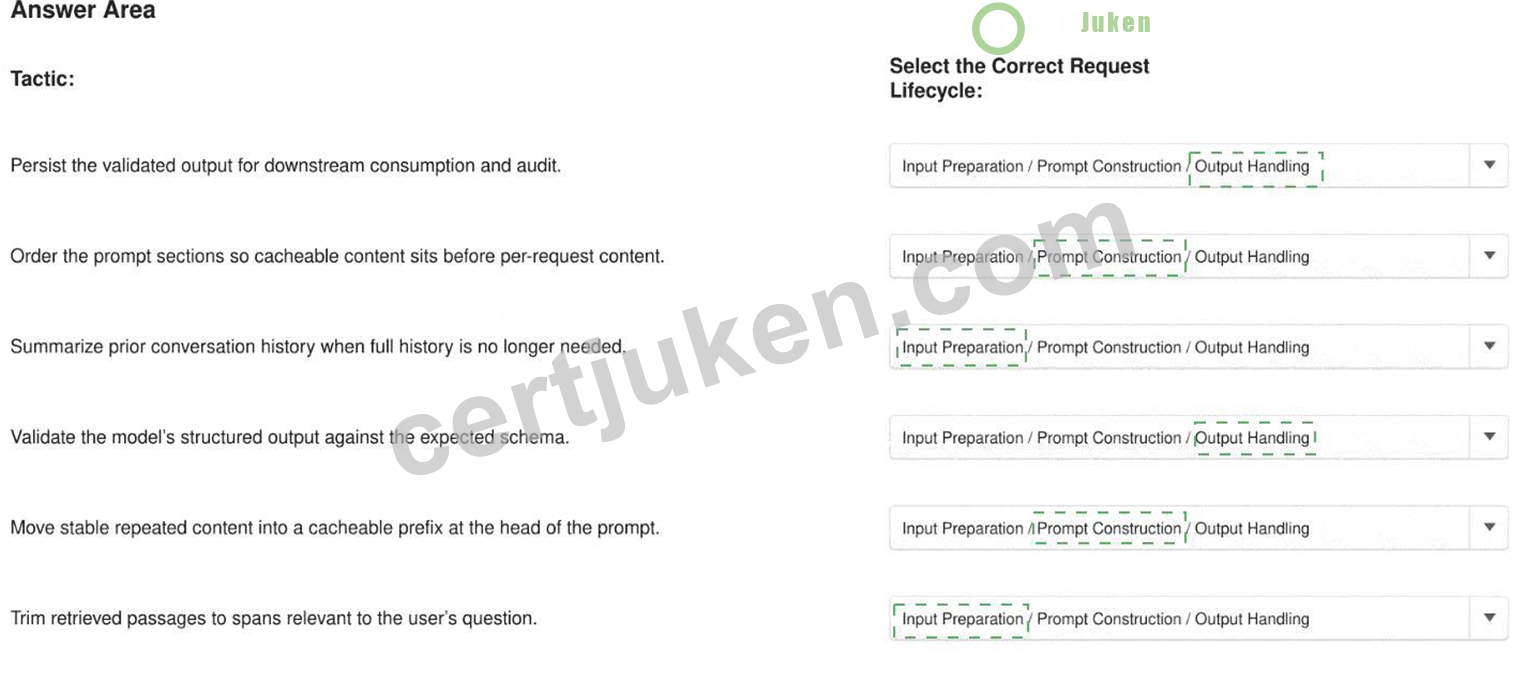
Explanation:
* Persist the validated output for downstream consumption and audit - Output Handling
* Order prompt sections so cacheable content appears before per-request content - Prompt Construction
* Summarize prior conversation history when full history is no longer needed - Input Preparation
* Validate the model's structured output against the expected schema - Output Handling
* Move stable repeated content into a cacheable prefix at the beginning of the prompt - Prompt Construction
* Trim retrieved passages to spans relevant to the user's question - Input Preparation Input preparation determines what evidence and history should enter the request, so summarization and retrieval trimming belong there. Prompt construction determines ordering and cache boundaries; stable repeated instructions must precede dynamic per-request content to maximize cache reuse. Output handling begins after generation and includes schema validation, persistence, auditing, and downstream delivery.
Mixing these responsibilities creates inefficient prompts and weak validation boundaries. Anthropic's context guidance emphasizes curating the smallest useful context because unnecessary tokens can reduce recall and accuracy. Prompt caching similarly depends on a stable reusable prefix, while structured outputs or schema validation protect downstream systems from malformed responses. Context windows; prompt caching
質問 # 24
You are configuring Claude Code for a team that needs every engineer to share the same MCP server set, permission rules, and project context across the engineering monorepo.
Which configuration scope best supports this requirement?
正解:C
解説:
Project scope is designed for configuration that must be shared by everyone working in a repository.
Committing the approved configuration provides versioning, review history, repeatable onboarding, and consistent MCP and permission behavior across the monorepo. User scope is intended primarily for individual preferences and personal rules, so independently maintained user files create configuration drift. Local scope affects only one person in one project and is therefore unsuitable for team-wide distribution. A lead architect's local configuration cannot establish a shared environment. Claude Code documentation specifically describes .
claude/settings.json as the shared project settings file that teams check into source control. Security-critical policies that must not be overridden should additionally be enforced through managed organizational settings rather than relying exclusively on repository configuration. Claude Code: Settings files and precedence
質問 # 25
A healthcare organization is evaluating two Claude-powered AI architectures for a clinical documentation assistant. Architecture X produces higher output quality scores but costs $0.18 per documentation session and averages 4.2 seconds per response. Architecture Y scores slightly lower on quality metrics but costs $0.09 per session and averages 2.1 seconds per response. The stated SLA requires responses under 3 seconds, and the annual volume is projected at 2 million documentation sessions.
Which evaluation approach correctly applies business value pillar analysis to this decision?
正解:D
解説:
Architecture X fails a stated production gate: its 4.2-second average exceeds the required three-second response SLA. It should therefore not remain a qualifying architecture unless it is redesigned and retested before selection. A promise to optimize after deployment is not evidence of compliance.
Architecture Y meets the latency requirement at 2.1 seconds. Its annual inference cost is $180,000 at two million sessions, compared with $360,000 for Architecture X-a difference of $180,000 annually. However, cost alone does not establish suitability. The organization must determine whether Y's lower quality score causes material omissions, correction effort, clinician dissatisfaction, documentation risk, or reduced workflow productivity.
Option C correctly treats the SLA as a threshold and then analyzes the remaining architecture across cost, efficiency, quality, and productivity. Option A ignores clinical quality. Option B disregards an explicit SLA failure. Option D may eventually be viable, but it introduces routing complexity and leaves unanswered how complex cases are detected, whether X's latency becomes acceptable for them, and how both paths are evaluated.
The final choice should be gated by clinical-quality evaluation, human review requirements, safety metrics, operational latency, and total annual cost.
Study Guide references/topics: Business-value pillars; performance gates; solution cost; workflow efficiency; quality trade-offs; healthcare architecture evaluation.
質問 # 26
......
21世紀には、{Examcode}認定は受験者の特定の能力を表すため、社会でますます認知されるようになりました。ただし、{Examcode}認定を取得するには、CCAR-P試験の準備に多くの時間を費やす必要があります。多くの人々は試験前のあらゆる種類の困難のためあきらめ、最終的に自己価値を高める機会を失いました。繁栄する多国籍企業として、私たちは常にこの問題の解決に取り組んでいます。たとえば、当社が開発したCCAR-P学習エンジンはCCAR-P試験を簡単かつ簡単にすることができ、自信を持ってこれを行ったと言えます。
CCAR-P出題内容: https://www.certjuken.com/CCAR-P-exam.html