What's more, part of that Prep4King AI-200 dumps now are free: https://drive.google.com/open?id=1_NxYZL9MNdIrIYPV1KNcvGn0aTg1vpox
Our company is considerably cautious in the selection of talent and always hires employees with store of specialized knowledge and skills on our AI-200 exam questions. All the members of our experts and working staff maintain a high sense of responsibility, which is why there are so many people choose our AI-200 Exam Materials and to be our long-term partner. For we carry forward the spirit of "firm & indomitable, developing & innovative, achieving the first class", serving customers with all our heart and soul with our wonderful AI-200 practice braindumps.
| Section | Objectives |
|---|---|
| Plan and manage Azure AI solutions | - Select appropriate Azure AI services - Monitor and optimize AI solutions - Plan security and compliance requirements |
| Implement Azure AI solutions | - Implement generative AI solutions using Azure OpenAI - Implement knowledge mining with Azure AI Search - Implement computer vision solutions - Implement natural language processing solutions |
| Implement and monitor AI workloads | - Monitor performance and troubleshoot issues - Deploy AI models and services |
>> AI-200 Guaranteed Passing <<
We have prepared our AI-200 training materials for you. They are professional practice material under warranty. Accompanied with acceptable prices for your reference, all our materials with three versions are compiled by professional experts in this area more than ten years long. Moreover, there are a series of benefits for you. So the importance of AI-200 Actual Test is needless to say. If you place your order right now, we will send you the free renewals lasting for one year. All those supplements are also valuable for your AI-200 practice exam.
NEW QUESTION # 126
You have an Azure web app that uses Azure Cosmos DB as a data store. You create a Cosmos DB container by running the following PowerShell script: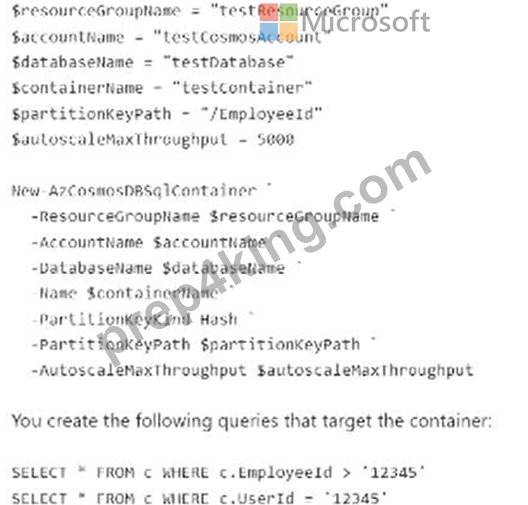
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.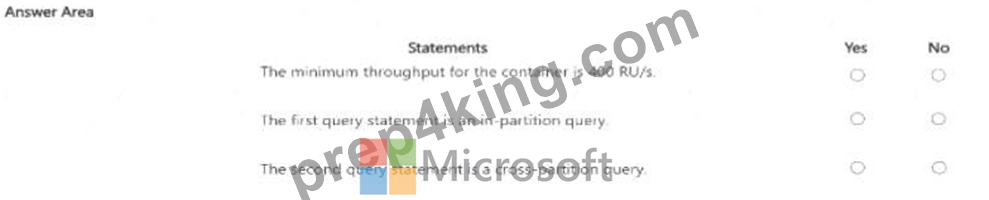
Answer:
Explanation: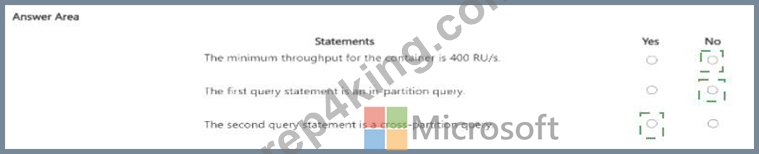
Explanation: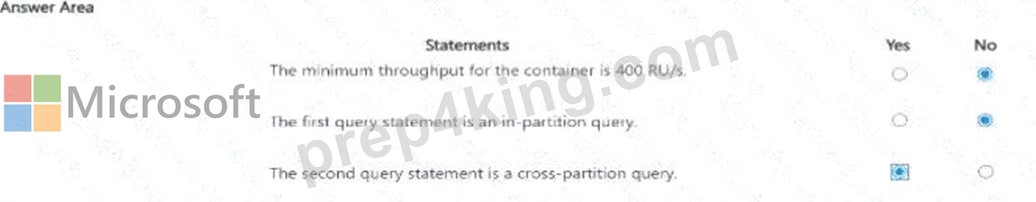
The question maps directly to the AI-200 objective "Develop AI solutions by using Azure Cosmos DB for NoSQL," which includes running queries and optimizing query performance and Request Unit (RU) consumption.
Statement 1: No - The minimum throughput is not 400 RU/s.
The PowerShell command provisions the container with:
-AutoscaleMaxThroughput 5000
Azure Cosmos DB autoscale operates between approximately 10% and 100% of the configured maximum throughput . Microsoft documentation specifically gives the example of an autoscale container provisioned with 5,000 RU/s scaling between 500 RU/s and 5,000 RU/s . Therefore, for this container, the minimum operating autoscale throughput is 500 RU/s , not 400 RU/s.
Therefore:
"The minimum throughput for the container is 400 RU/s." # No
Statement 2: No - The first query is not an in-partition query.
The container uses:
/EmployeeId
as its partition key.
The first query is:
SELECT * FROM c WHERE c.EmployeeId > ' 12345 '
Although the query references the partition key, it uses a range predicate ( > ) , not an equality predicate.
Microsoft explicitly states that a range filter on a partition key is not scoped to a single physical partition .
To qualify as an in-partition query, the filter must identify the applicable partition, typically through an equality predicate such as:
WHERE c.EmployeeId = ' 12345 '
Microsoft ' s documentation provides essentially the same example: a query using DeviceId > ... against a container partitioned by DeviceId is not an in-partition query .
Therefore:
"The first query statement is an in-partition query." # No
Statement 3: Yes - The second query is a cross-partition query.
The second query is:
SELECT * FROM c WHERE c.UserId = ' 12345 '
The container ' s partition key is /EmployeeId, not /UserId. Because the query contains no filter on the partition key , Azure Cosmos DB cannot route it to one logical partition. It must fan out the query across the applicable physical partitions and combine the results.
Microsoft describes this behavior directly: when a query does not contain a filter on the partition key, it must execute across the partitions.
Therefore:
"The second query statement is a cross-partition query." # Yes
NEW QUESTION # 127
An ACA app processes messages from an Azure Storage queue.
The app must scale automatically based on messages in a specific Azure Storage queue by using a Kubernetes Event-driven Autoscaler (KEDA) custom scale rule.
You need to configure the required scale rule values.
Which two values should you configure? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: B,C
Explanation:
[A]
QeueName: The exact name of the specific Azure Storage queue your app is polling is required.
[C]
Why Trigger Type is Required
When configuring a custom scale rule in Azure Container Apps (ACA), the platform utilizes KEDA underneath. Because a custom rule can connect to many different event sources (such as Kafka, Redis, or Azure Storage), you must explicitly define the Trigger type (e.g., azure-queue) so KEDA knows which specific scaler to initiate.
Reference:
https://techcommunity.microsoft.com/blog/fasttrackforazureblog/container-apps-a-practical-scaling-with-azure-queue-scale-rule/3722075
NEW QUESTION # 128
Drag and Drop Question
You are developing a Python application that reads data from Azure Cosmos DB for NoSQL by using the azure-cosmos SDK.
You need to connect to an existing account and run a SQL query against an existing container.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.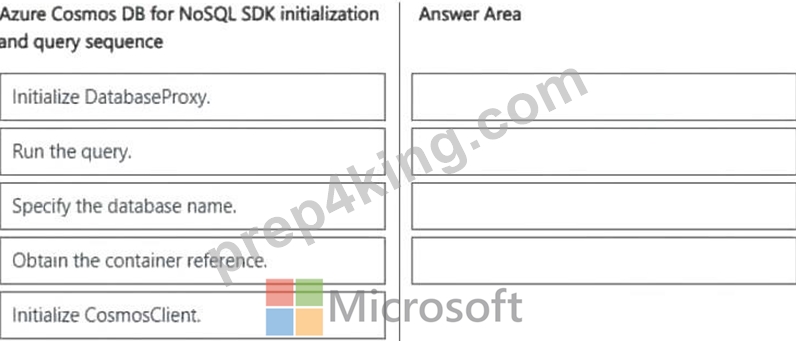
Answer:
Explanation: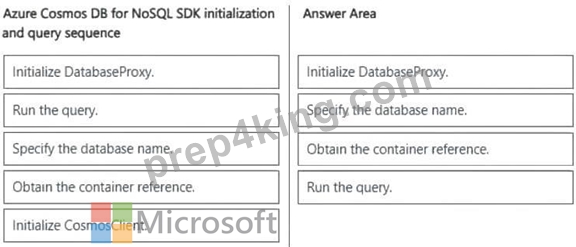
Explanation:
In the azure-cosmos Python SDK, you do not use an explicit "InitializeDatabaseProxy" method.
Instead, you use the client to get a database reference, and then use that database reference to get a container reference.
Step 1: Initialize CosmosClient
You must first establish the root connection using the client object with your account endpoint and credentials.
Step 2: Specify the database name
From the client, you call client.get_database_client(database_name) to target your specific database resource.
Step 3: Obtain the container reference
From the database proxy object, you call database.get_container_client(container_name) to reference the specific data container.
Step 4: Run the Query
Finally, you execute the SQL operation directly on that container using container.query_items().
Reference:
https://learn.microsoft.com/en-us/azure/cosmos-db/quickstart-python
NEW QUESTION # 129
You are developing a microservices-based application that uses Azure Container Apps The application consists of several containerized services that handle tasks, such as processing orders, managing inventory, and generating reports.
You must secure the container apps. All apps must reside in the same virtual network, share the same Dapr configuration, and share the same logging location.
Apps must support the configuration of the amount of memory and compute resources available to containers.
You need to configure the Azure Container App
How should you complete the CLI command? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.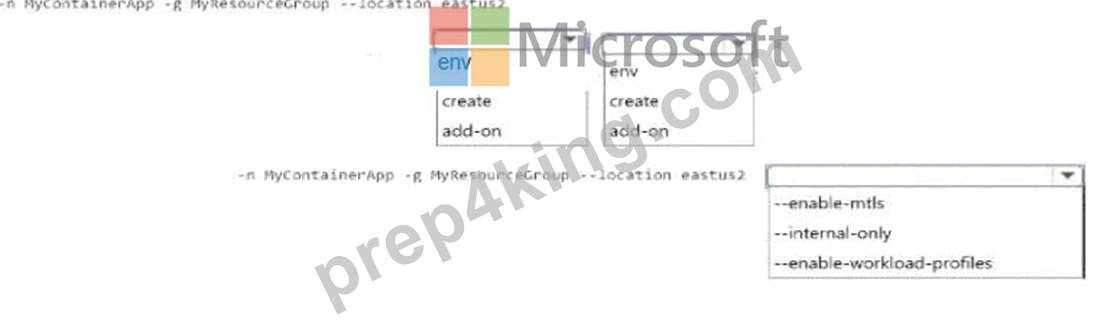
Answer:
Explanation: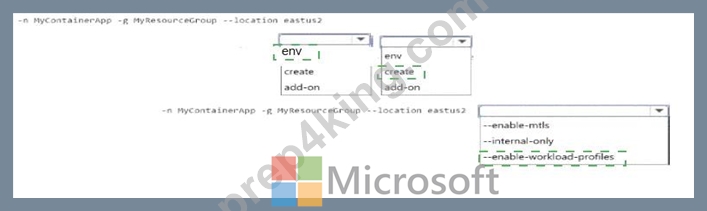
Explanation: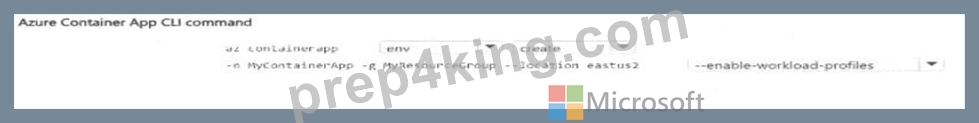
Verified answer: `az containerapp env create ... --enable-workload-profiles`.
Detailed Explanation: The shared boundary for Container Apps is the managed environment. Apps in one environment can share the environment's virtual network integration, observability destination, and Dapr- related environment configuration. Enabling workload profiles provides selectable compute profiles and resource sizing options for workloads in that environment. The CLI must therefore create a Container Apps environment and enable workload profiles. Creating an individual container app alone would not establish the common environment-level network, logging, and resource-profile boundary required by the scenario.
Study Guide Alignment: Containerized Azure workloads: registry builds, App Service containers, Container Apps revision/scaling behavior, and AKS deployment choices.
Official Microsoft Learn References: AI-200 Study Guide | Azure Container Apps environments
NEW QUESTION # 130
Drag and Drop Question
You are reviewing secret access patterns used by an AI application that retrieves credentials from Key Vault.
You need to evaluate the security impact of each implementation approach.
What is the outcome of each approach? To answer, move the appropriate outcomes to the correct implementations. You may use each outcome once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.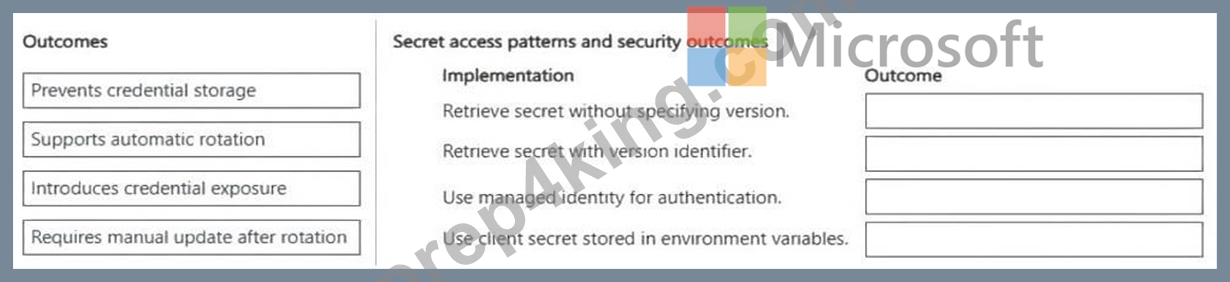
Answer:
Explanation: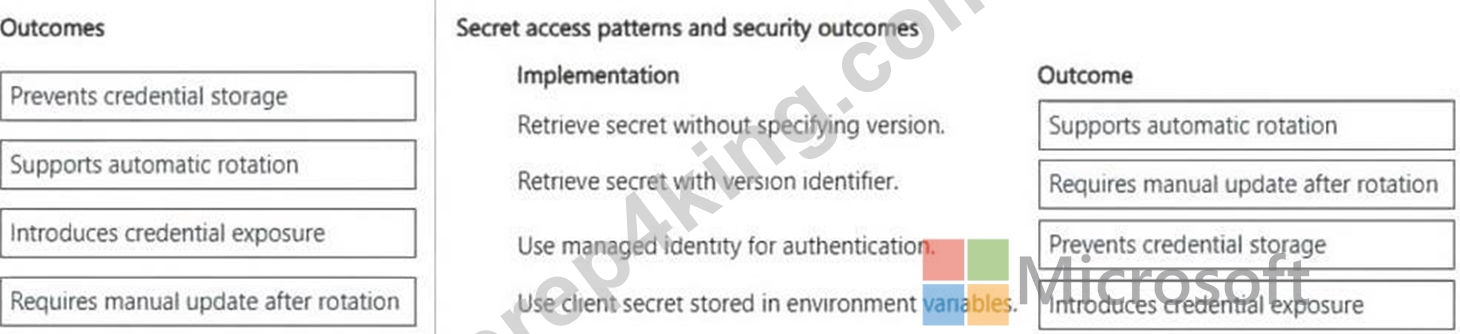
Explanation:
Box 1: Supports automatic rotation.
When an AI application retrieves a secret from Azure Key Vault without specifying a version, it always fetches the latest active version. This choice impacts your security and operations in the following ways:
Latest Version Fetch: The vault automatically serves the current active secret value.
No Code Changes: Your application reads the new credential immediately after rotation without a code redeployment.
Zero Downtime: Automated rotation pipelines can update the secret in Key Vault while the app seamlessly switches to the new token.
Box 2: Requires manual update after rotation
Using a specific version identifier when retrieving a secret from Key Vault means the application always requests one exact version of that secret. This choice requires manual update after rotation because the application code or configuration pins a specific version ID and will not fetch the new value when the secret rotates.
Box 3: Prevents credential storage
Prevents credential storage is the correct outcome of using managed identity for authentication.
No credentials to manage: Managed identities eliminate the need for developers to manage credentials entirely.
Automatic token handling: Azure automatically creates an identity for the application in Microsoft Entra ID and handles the service principal's lifecycle behind the scenes, ensuring that no secrets or connection strings are ever hardcoded or stored in configuration files.
Box 4: Introduces credential exposure
Introduces credential exposure and Requires manual update after rotation are the primary outcomes of storing a client secret in environment variables.
Storing clear-text secrets in environment variables poses a significant security risk. Any process, compromised dependency, or user with access to the execution environment (such as container details, application logs, or process dumps) can easily read them.
Reference:
https://medium.com/simform-engineering/building-automated-secret-rotation-using-azure-key-vault-and-net-01e0701f0a2e
https://www.varonis.com/blog/azure-managed-identities
NEW QUESTION # 131
......
We provide free PDF demo for each exam. This free demo is a small part of the official complete Microsoft AI-200 training dumps. The free demo can show you the quality of our exam materials. You can download any time before purchasing. You can tell if our products and service have advantage over others. I believe our Microsoft AI-200 training dumps will be the highest value with competitive price comparing other providers.
Latest AI-200 Test Notes: https://www.prep4king.com/AI-200-exam-prep-material.html
P.S. Free & New AI-200 dumps are available on Google Drive shared by Prep4King: https://drive.google.com/open?id=1_NxYZL9MNdIrIYPV1KNcvGn0aTg1vpox