It is a common sense that only high quality and accuracy AI-200 practice materials can relive you from those worries. It is our communal wish to reap successful fruits. So our company did a lot to make sure that happen. Our AI-200 practice materials compiled by the most professional experts can offer you with high quality and accuracy results for your success. If you are unfamiliar with our AI-200 practice materials, please download the free demos for your reference, and to some unlearned exam candidates, you can master necessities by our AI-200 practice materials quickly.
| Section | Objectives |
|---|---|
| Plan and manage Azure AI solutions | - Select appropriate Azure AI services - Monitor and optimize AI solutions - Plan security and compliance requirements |
| Implement Azure AI solutions | - Implement generative AI solutions using Azure OpenAI - Implement natural language processing solutions - Implement computer vision solutions - Implement knowledge mining with Azure AI Search |
| Implement and monitor AI workloads | - Monitor performance and troubleshoot issues - Deploy AI models and services |
>> Exam AI-200 Lab Questions <<
Our company is a professional certificate exam materials provider, and we have rich experiences in this field. AI-200 study guide are high quality, since we have a professional team to collect the information for the exam, and we can ensure you that AI-200 study guide you receive are the latest information we have. In order to strengthen your confidence for AI-200 Exam Dumps, we are pass guarantee and money back guarantee. If you fail to pass the exam, we will give you full refund. We offer you free update for one year for AI-200 exam dumps, and the update version will be sent to your email automatically.
NEW QUESTION # 141
You develop a message-processing service deployed to Azure Container Apps. The service reads messages from an Azure Service Bus queue.
The solution must minimize costs by ensuring NO compute resources are consumed when the queue is empty.
You need to configure scaling for the service.
Which two actions should you perform? Each correct answer presents part of the solution. Choose two NOTE: Each correct selection is worth one point.
Answer: B,D
Explanation:
Detailed Explanation: Azure Container Apps uses KEDA-based scale rules for event-driven workloads. A Service Bus scaler can monitor queue depth and create replicas only when messages are pending. To meet the explicit cost requirement, the scale configuration must permit a minimum replica count of zero so all active replicas can terminate when the queue is empty. Increasing the maximum replica count changes peak capacity, and HTTP ingress concurrency is not the correct scaling signal for a background Service Bus consumer.
Study Guide Alignment: Containerized Azure workloads: registry builds, App Service containers, Container Apps revision/scaling behavior, and AKS deployment choices.
Official Microsoft Learn References: AI-200 Study Guide | Set scaling rules in Azure Container Apps
NEW QUESTION # 142
Case Study 2 - Proseware Inc.
Background
Proseware Inc. develops AI-powered knowledge management solutions for enterprise customers.
The company is modernizing its platform to support semantic search, intelligent document retrieval, and real-time partner integrations.
The engineering team uses Python and Azure SDKs. The architecture is being redesigned to support containerized microservices, vector search workloads, and serverless backend processing.
Planned Application Architecture
Microservices are containerized by using Docker.
Code for containerized microservices and Azure Function apps is developed locally but stored in a GitHub repository.
Custom images for containerized microservices are stored in Azure Container Registry (ACR).
Base images are stored in Docker Hub. Custom images must be rebuilt automatically whenever their base images are updated.
Azure Cosmos DB for NoSQL stores documents, metadata, and vector embeddings.
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Azure Container Apps (ACA) apps host backend API services that provide semantic search across Azure Cosmos DB for NoSQL documents. API services process Service Bus messages and update search indexes.
Azure Kubernetes Service (AKS) processes batch vector embedding regeneration for existing Azure Cosmos DB for NoSQL documents (whenever the embedding model is changed).
An extranet-facing containerized webhook allows business partners to submit documents to be processed by internal AI workflows for semantic search and retrieval.
Monitoring
Telemetry generated by Azure resources is sent to Azure Monitor.
A Log Analytics workspace is used to collect ACA apps logs, AKS container logs, and Azure Functions apps logs.
Monitoring of Azure Functions is currently implemented by using Azure Application Insights SDK instrumentation.
Business Requirements
Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Backend API services must scale automatically during business hours.
Cold start delay of backend APIs must be minimized.
Secrets must be stored outside of container images.
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Azure Cosmos DB for NoSQL RU consumption must be minimized.
Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
The partner-facing containerized webhook service must run on Azure App Service.
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
Azure App Service must supply secrets at runtime without relying on external services.
Resources and workloads must be deployed by using Bicep templates through an automated, version-controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Known Issues
RU consumption spikes during vector similarity queries.
Hotspot Question
You need to configure image build automation based on the technical requirements.
Which settings should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Scenario, Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Box 1: Commit
Use a Commit trigger for this configuration
Immediate Validation: Builds continuous integration (CI) pipelines automatically when a developer submits a pull request or pushes code.
Gatekeeper Function: Prevents unvalidated code or broken container images from merging into your main branch.
Workflow Alignment: Supports microservices development by isolating tests to the specific code updates being introduced.
Box 2: GitHub workflow
To implement automatic image builds and validation before code updates are merged into the main branch, you should use a GitHub workflow.
Branch gating: GitHub Actions can trigger specifically on pull_request events targeting the main branch, allowing you to validate code and builds before merging.
Automation control: It orchestrates the entire continuous integration (CI) pipeline, including linting, running unit tests, building Docker images, and scanning them for vulnerabilities.
Integration capacity: It can seamlessly hand off the successfully validated image to Azure Container Registry (ACR) or utilize ACR Tasks under the hood as part of the pipeline steps.
Reference:
https://docs.github.com/en/actions/tutorials/publish-packages/publish-docker-images
NEW QUESTION # 143
You are developing an application that must extract structured field data (invoice number, total, vendor name) from scanned invoices in multiple layouts.
You need a solution that requires no custom model training.
What should you use?
Answer: A
Explanation:
Use the Azure AI Document Intelligence prebuilt invoice model . The prebuilt invoice model is specifically designed to analyze invoices and extract structured fields and line items without requiring an organization to train a custom model. Microsoft documents support for fields including InvoiceId , VendorName , InvoiceTotal , InvoiceDate, CustomerName, AmountDue, tax information, addresses, and invoice line items.
Because the model is pretrained to recognize common invoice structures, it can process invoices that use different layouts and formats while returning normalized structured output. This directly satisfies the requirement to extract invoice number, total, and vendor information from scanned documents while minimizing development and training effort.
The Azure AI Vision Read API performs OCR and can extract printed or handwritten text, but it does not provide invoice-specific semantic field extraction. Custom named entity recognition would require training and is designed for text entity extraction rather than document-layout understanding. A Document Intelligence custom neural model can handle organization-specific forms and layouts, but it requires custom model training, directly violating the requirement.
Therefore, the prebuilt invoice model provides the required combination of OCR, document understanding, structured extraction, and zero custom training.
Study Guide references: Azure AI Document Intelligence # prebuilt invoice model; structured field extraction; OCR; invoice fields and line items.
NEW QUESTION # 144
You are creating an Azure Functions app project in your local development environment by using Azure Functions Core Tools.
You must create the project in either Python or C# without using a template.
You need to specify the command and its parameter required to create the Azure Functions app project.
Which command and parameter should you specify? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
* Command: func init
* Parameter: --worker-runtime
Use func init to initialize a new Azure Functions project. Microsoft documents func init as the Azure Functions Core Tools command that creates the project structure in either the current directory or a specified project folder. The command is specifically intended for creating a new Functions application project, whereas func new creates an individual function from a template inside an already initialized project.
The --worker-runtime parameter specifies the language/runtime model for the Functions project. For example, Microsoft documents func init --worker-runtime python for Python projects and func init --worker- runtime dotnet-isolated for modern C#/.NET isolated-worker projects.
--language is not the primary parameter used to establish the Functions worker runtime in this scenario. It can be relevant to certain runtime combinations, such as Node.js, but the Core Tools project initialization examples for Python and C# rely on --worker-runtime. --target-framework is used to select a specific .NET target framework after the worker/runtime model is determined; it does not identify whether the project should be Python or C#.
Therefore, the correct combination is func init + --worker-runtime .
Study Guide references: Azure Functions Core Tools # func init; local Functions project creation; --worker- runtime; Python and .NET isolated worker projects.
NEW QUESTION # 145
You are investigating high latency in an AI search application that processes millions of requests daily.
Telemetry is stored in Azure Monitor Logs.
You must create a KQL query that correlates information from the AppRequests table and the AppDependencies table. The query must meet the following requirements:
* Include only data from the last 24 hours.
* Filter for failed requests only.
* Calculate the average duration of dependencies, grouped by operation.
The query must follow best practice to optimize the performance by minimizing the initial data scan.
You need to create the query.
In which order should perform the actions? To answer, move all actions from the list of actions to the answer area and arrange them in the correct order.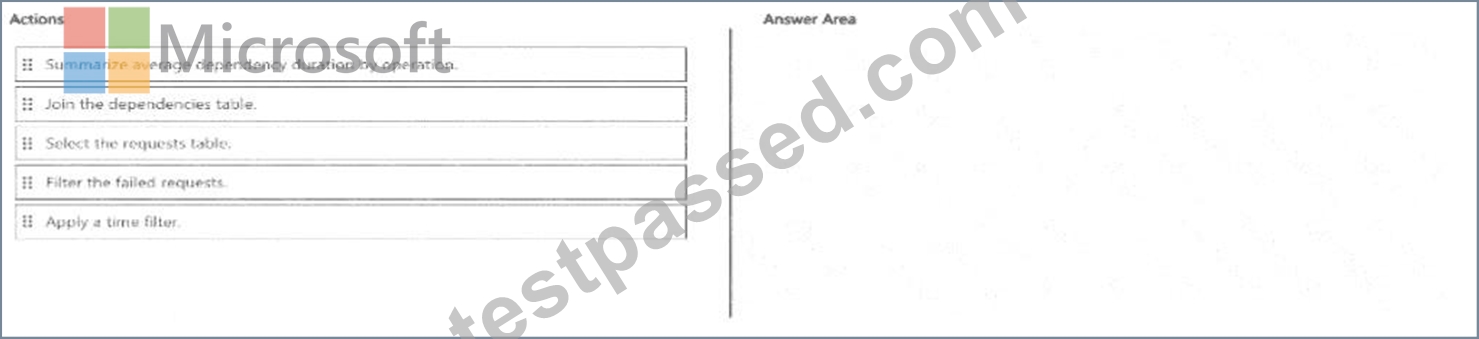
Answer:
Explanation:
Explanation:
Verified answer: 1) Select the requests table; 2) apply the 24-hour time filter; 3) filter failed requests; 4) join the dependencies table; 5) summarize average dependency duration by operation.
Detailed Explanation: KQL performs best when high-selectivity filters are applied as early as possible, especially the time predicate that limits the amount of data scanned. Starting from AppRequests, restricting to the last 24 hours, and then filtering failures reduces the left-side dataset before the join. The dependency table is then correlated with those requests, and aggregation is performed last to calculate average dependency duration by operation. Joining or summarizing before the time and failure filters would process more data than necessary.
Study Guide Alignment: Security and operations: Key Vault, App Configuration, managed identity, OpenTelemetry, Azure Monitor, and KQL-based troubleshooting.
Official Microsoft Learn References: AI-200 Study Guide | Optimize log queries in Azure Monitor
NEW QUESTION # 146
......
Before you can become a professional expert in Microsoft technology, you need to pass AI-200 exam test. It means you should get the AI-200 certification. The AI-200 actual exam is challenging and passing is definitely requires a lot of hard work and effort. TestPassed will provide the latest and valid AI-200 test study material to you. It just needs to be taken 20-30 hours for preparation, then you can attend the actual test with confident. Besides, in case of failure, we will give you full refund. While, 100% pass is the guarantee we promise to our customers.
Real AI-200 Exam: https://www.testpassed.com/AI-200-still-valid-exam.html