The moment you choose to go with our DP-800 study materials, your dream will be more clearly presented to you. Next, through my introduction, I hope you can have a deeper understanding of our DP-800 learning quiz. We really hope that our DP-800 Practice Engine will give you some help. In fact, our DP-800 exam questions have helped tens of thousands of our customers successfully achieve their certification.
| Section | Objectives |
|---|---|
| Integrate AI capabilities with database systems | - Use Azure AI services with database workloads - Implement AI-assisted data processing |
| Develop and manage database solutions | - Ensure security and compliance of data solutions - Optimize performance and scalability |
| Design and implement data solutions | - Implement data storage and data processing solutions - Design database solutions using Azure data services |
| Monitor, troubleshoot, and maintain solutions | - Troubleshooting data pipeline issues - Monitoring database health and performance |
>> Microsoft DP-800 Books PDF <<
Everything needs a right way. The good method can bring the result with half the effort, the same different exam also needs the good test method. Our DP-800 study questions in every year are summarized based on the test purpose, every answer is a template, there are subjective and objective exams of two parts, we have in the corresponding modules for different topic of deliberate practice. To this end, our DP-800 Training Materials in the qualification exam summarize some problem- solving skills, and induce some generic templates. The user can scout for answer and scout for score based on the answer templates we provide, so the universal template can save a lot of precious time for the user.
NEW QUESTION # 86
You have an Azure SQL database that contains a table named dbo.ManualChunks.
dbo.ManualChunks contains product manuals.
A retrieval query already returns the top five matching chunks as nvarchar (max)text.
You need to call an Azure OpenAI REST endpoint for chat completions. The request body must include both the user question and the retrieved chunks.
You write the following Transact-SQL code.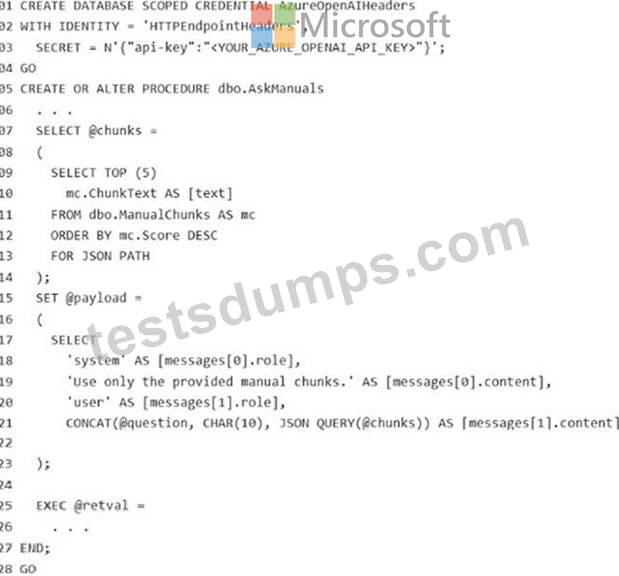
What should you insert at line 22?
Answer: C
Explanation:
To construct a payload for the Azure OpenAI REST API within Azure SQL, you can use a Common Table Expression (CTE) to structure the messages and then collapse them into a single JSON object.
T-SQL Payload Generation
Key Implementation Details
Message Hierarchy: Azure OpenAI requires a messages array. By nesting a subquery with FOR JSON PATH inside the main SELECT, SQL Server creates the required JSON array of objects.
JSON Formatting: Using FOR JSON PATH, WITHOUT_ARRAY_WRAPPER on the outer selection ensures the root of your @payload is a clean JSON object {...} rather than a single- element array [{...}].
Context Injection: It is standard practice to prepend the retrieved manual chunks to the system message or a dedicated user message to provide the model with the necessary grounding data.
Assuming you have your retrieved chunks concatenated into a single @Context variable and the user's input in @UserQuestion, use the following logic:
DECLARE @UserQuestion NVARCHAR(MAX) = 'How do I reset the device?';
DECLARE @Context NVARCHAR(MAX) = 'Manual Chunk 1... Manual Chunk 2...'; -- Your top 5 chunks DECLARE @payload NVARCHAR(MAX);
-- Define the message structure for Chat Completions
WITH ChatMessages AS (
SELECT 'system' AS [role],
'You are a helpful assistant. Use these manual excerpts: ' + @Context AS [content] UNION ALL SELECT 'user' AS [role],
@UserQuestion AS [content]
)
-- Generate the final JSON body
SELECT @payload = (
SELECT
(SELECT [role], [content] FROM ChatMessages FOR JSON PATH) AS [messages],
0.7 AS [temperature],
800 AS [max_tokens]
FOR JSON PATH, WITHOUT_ARRAY_WRAPPER
);
-- Resulting @payload is now ready for sp_invoke_external_rest_endpoint PRINT @payload; Reference:
https://devblogs.microsoft.com/azure-sql/using-openai-rest-endpoints-with-azure-sql-database
NEW QUESTION # 87
Your team is developing an Azure SQL database solution from a locally cloned GitHub repository by using Microsoft Visual Studio Code and GitHub Copilot Chat.
You need to ensure that GitHub Copilot Chat uses the team's coding standards when generating Transact-SQL code in Visual Studio Code.
What should you use?
Answer: D
Explanation:
o ensure GitHub Copilot Chat adheres to your team's specific Transact-SQL (T-SQL) standards while deploying an Azure SQL database from VS Code, you should focus on Custom Instructions and Workspace Context.
Required Setup
Create a .github/copilot-instructions.md File
This is the most effective way to enforce standards.
Create this file in the root of your repository.
Copilot automatically reads this file to understand project-specific rules.
Include sections for:
Naming conventions (e.g., PascalCase for tables, proc_ prefix for stored procedures).
Formatting rules (e.g., keywords in UPPERCASE, use of 4 spaces).
Security practices (e.g., always use schema prefixes, avoid SELECT *).
Reference:
https://nikolay-dev.medium.com/master-web-development-with-github-spark-ai-b0b874525418
NEW QUESTION # 88
You have a SQL database in Microsoft Fabric that contains a table named WebSite. Logs. WebSite.Logs stores application telemetry data. Website.Logs contains a nvarehar(iMx) column named log that stores JSON documents You have a daily report that filters by the $.severity JSON property and returns Logld. LogDateTime, and log.
The report frequently causes full table scans.
You need to modify Website. Logs to support efficient filtering by $. severity and avoid key lookups for the columns returned by the report.
How should you complete the Transact-SQL code to avoid full table scans? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.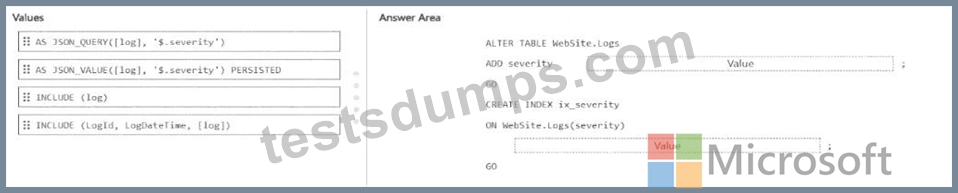
Answer:
Explanation: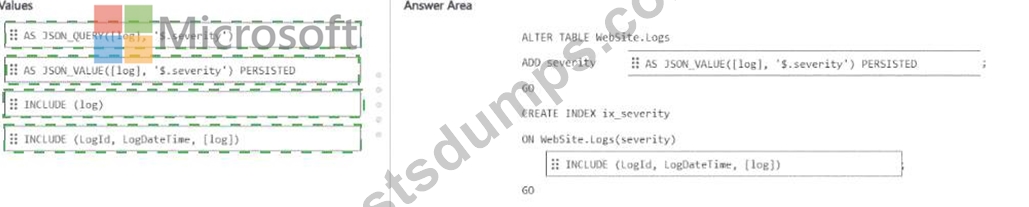
Explanation: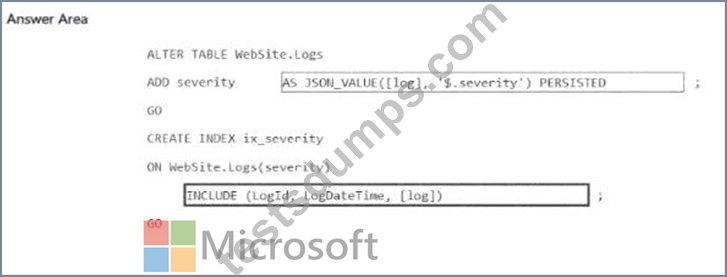
The correct way to avoid full table scans here is to add a computed column that extracts the JSON scalar property with JSON_VALUE , and then create a nonclustered index on that computed column with the report's returned columns in the INCLUDE list. Microsoft's JSON indexing guidance specifically recommends creating a computed column that exposes the JSON property you filter on, using the same expression as in the query, and then indexing that computed column.
So the computed column must be:
AS JSON_VALUE([log], ' $.severity ' ) PERSISTED
This is correct because $.severity is a scalar JSON value, so JSON_VALUE is the proper function.
JSON_QUERY would be for extracting an object or array, not a scalar property. Microsoft also notes that persisted computed columns can improve access speed for JSON-derived values.
The index should then include:
INCLUDE (LogId, LogDateTime, [log])
That is the right covering strategy because the report filters by severity but returns LogId, LogDateTime, and log. Microsoft's guidance on included columns explains that nonkey included columns let a nonclustered index cover more queries and reduce extra lookups to the base table.
So the completed code is:
ALTER TABLE WebSite.Logs
ADD severity AS JSON_VALUE([log], ' $.severity ' ) PERSISTED;
GO
CREATE INDEX ix_severity
ON WebSite.Logs(severity)
INCLUDE (LogId, LogDateTime, [log]);
GO
NEW QUESTION # 89
You have a database named DB1. The schema is stored in a Git repository as an SDK-style SQL database project.
You have a GitHub Actions workflow that already runs dotnet build and produces a database artifact.
You need to add a deployment step that publishes the dacpac file to an Azure SQL database by using the secrets stored in GitHub repository secrets What should you include in the workflow?
Answer: A
Explanation:
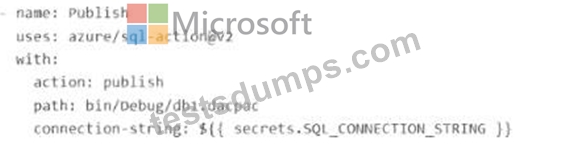
The correct workflow step is Option C because it uses the Azure SQL GitHub Action to publish a .dacpac file and reads the connection string from GitHub repository secrets , which is exactly what the requirement asks for. Microsoft's Azure SQL GitHub Actions guidance shows using azure/sql-action@v2 with a connection string stored in secrets and a DACPAC path for deployment.
The key parts that make C correct are:
* uses: azure/sql-action@v2
* action: publish
* path: bin/Debug/db1.dacpac
* connection-string: ${{ secrets.SQL_CONNECTION_STRING }}
That matches the documented publish pattern for deploying a DACPAC to Azure SQL Database from GitHub Actions. Microsoft and the Azure SQL action documentation both describe Publish as the deployment action for applying a DACPAC to a target database, while Extract is used to create a DACPAC from an existing database, not deploy one.
Why the other options are incorrect:
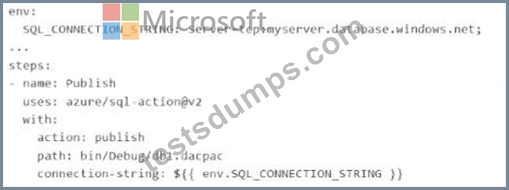
* A uses an environment variable defined inline with a visible connection string rather than using GitHub repository secrets , which does not meet the requirement.
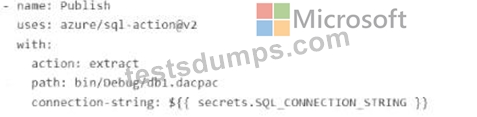
* B uses action: extract, which would create a DACPAC from a database instead of publishing the existing DACPAC artifact.
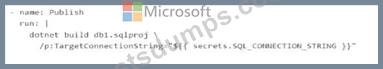
* D passes a target connection string to dotnet build, but the question says the workflow already runs dotnet build and produces a database artifact . The missing step is the deployment/publish step, not another build step. Microsoft's SQL project automation guidance separates build the DACPAC from publish the DACPAC .
NEW QUESTION # 90
You have an Azure SQL database named SalesDB that supports an AI-enabled product search application.
SalesDB has a table named SalesLT.Product that contains the following columns:
* ProductID (int)
* Name (nvarchar(100))
* ListPrice (decimal(18,2))
You need to create an object that returns products priced above a caller-provided threshold. The solution must meet the following requirements:
* Support being used in a join.
* Accept one input parameter.
* Return a table result.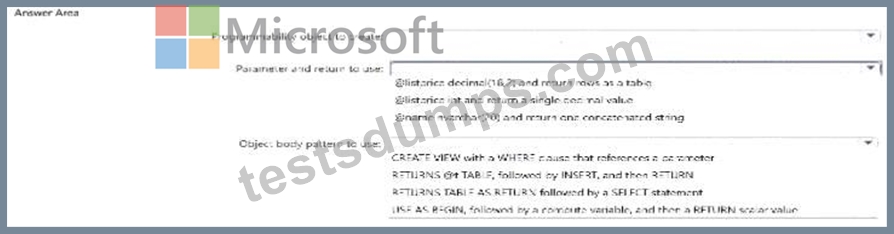
Answer:
Explanation: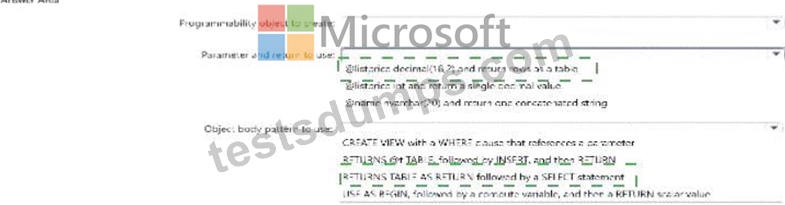
Explanation: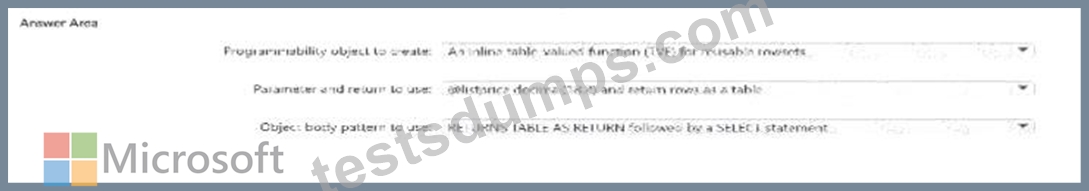
NEW QUESTION # 91
......
For candidates who are going to buy DP-800 test materials online, they may pay more attention to the money safety. We applied international recognition third party for the payment, all our online payment are accomplished by the third safe payment gateway. If you choose us, there is no necessary for you to worry about this, since the third party will protect interests of you. In addition, DP-800 Exam Braindumps are high quality, and you can use them at ease. You can try free demo before buying DP-800 exam dumps, so that you can know the mode of the complete version.
DP-800 Reliable Test Voucher: https://www.testsdumps.com/DP-800_real-exam-dumps.html