BONUS!!! Download part of Itcerttest AB-100 dumps for free: https://drive.google.com/open?id=1qWIb2PG6yedVi_dT02uv1TbqfcDR6pBc
Our AB-100 study materials are in short supply in the market. Our sales volumes are beyond your imagination. Every day thousands of people browser our websites to select study materials. As you can see, many people are inclined to enrich their knowledge reserve. So you must act from now. The quality of our AB-100 Study Materials is trustworthy. We ensure that you will satisfy our study materials. If you still cannot trust us, we have prepared the free trials of the AB-100 study materials for you to try.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> AB-100 Latest Exam Discount <<
Thousands of people will compete with you to get the AB-100 certificate. You must feel scared and disappointed. Do not lose hope. Our study materials come to your help. We will enhance your knowledge about the AB-100 exam. You just need to follow our AB-100 Study Materials to prepare the exam. No extra reference books are needed. And our pass rate is proved by our worthy customers to be high as 98% to 100%. You will pass the exam easily with our AB-100 practice braindumps.
NEW QUESTION # 13
You are evaluating a Microsoft Copilot Studio agent that supports Microsoft Dynamics 365 Customer Service representatives.
You need to recommend a testing solution that meets the following requirements:
- Evaluates agent effectiveness during active sessions
- Validates whether the agent delivers accurate and helpful responses
- Provides measurable, actionable insights for continuous improvement
What should you recommend?
Answer: C
Explanation:
To establish a testing and evaluation setup for your Microsoft Copilot Studio agent within Dynamics 365 Customer Service, you should leverage specialized AI-driven evaluation agents and integrated analytics dashboards.
1. Evaluate Effectiveness and Accuracy
Use the Quality Evaluation Agent in Dynamics 365 to automate the assessment of agent performance during and after active sessions.
2. Track Measurable Insights with Dashboards
Utilize the built-in and customizable dashboards to monitor key performance indicators (KPIs) like resolution and deflection.
3. Ensure Consistency with Agent Scripts
To maintain uniform and company-endorsed communication, implement Agent Scripts within the Customer Service Admin center.
Reference:
https://learn.microsoft.com/en-us/dynamics365/contact-center/administer/manage-quality- evaluation-agent
NEW QUESTION # 14
A company uses Microsoft Dynamics 365 Sales to manage leads that are stored in a Microsoft Dataverse table named Lead and use non-standard terminology and custom columns.
You need to configure business terms in the Lead table so that Microsoft Copilot controls can summarize the leads efficiently. The solution must minimize administrative effort.
How should you configure the business terms?
Answer: A
Explanation:
Comprehensive and Detailed Explanation From Agentic AI Business Solutions Topics:
The correct answer is B. Map the field display names as business terms .
In this scenario, the company is using Microsoft Dynamics 365 Sales with data stored in a Dataverse Lead table , but the table includes non-standard terminology and custom columns . The goal is to help Microsoft Copilot controls understand and summarize lead data efficiently, while also minimizing administrative effort .
This points directly to using the field display names as business terms .
Why this is the best choice:
Microsoft Copilot works best when the business meaning of data is clear and human-readable. In Dataverse, display names are already designed to represent the user-friendly business meaning of a field. They are what users see in the interface, and they typically align better with business language than technical names do.
By mapping field display names as business terms, you achieve two important outcomes:
* Copilot can interpret the fields more naturally Since display names reflect business-friendly terminology, Copilot can generate summaries that make sense in the context of sales operations.
* Administrative effort stays low The display names already exist. Reusing them avoids creating a large amount of extra metadata or manually defining separate business terms for every column.
From an AI-powered business solutions perspective, this is exactly the kind of configuration choice that improves semantic clarity while keeping the solution lightweight and maintainable . In enterprise AI adoption, the best design is often the one that improves model comprehension without adding unnecessary governance overhead.
Why the other options are incorrect:
A). Combine all the fields into one custom field
This is not a good design for Dataverse, Dynamics 365, or Copilot summarization. Combining everything into one field reduces structure, hurts maintainability, makes reporting harder, and weakens Copilot's ability to understand the meaning of specific attributes. Structured data is far more useful than a merged blob of text.
C). Add the schema names as business terms
Schema names are technical identifiers, not business-friendly labels. They are often formatted for developers and administrators rather than end users. Copilot summarization benefits from semantic clarity, and schema names usually do not provide that. They also do not minimize interpretation effort from a business AI perspective.
D). Create new business terms for each field
This might work technically, but it does not minimize administrative effort. The question explicitly asks for a solution that keeps administration low. If display names already represent the business meaning well enough, creating entirely new business terms for every field would be unnecessary overhead.
Expert reasoning:
In Microsoft AI business applications, especially with Dataverse + Dynamics 365 + Copilot , the system performs better when field metadata is aligned to business-readable language . The most efficient way to do that is usually to reuse display names , because they already express the intended meaning of the data and avoid extra manual configuration.
NEW QUESTION # 15
You are designing two Microsoft Copilot Studio agents named Agent1 and Agent2. Each agent must meet the following requirements:
Each agent must use a standard model.
Each agent must NOT use generative orchestration.
Agent1 must support simple and short phrases for a given topic.
Agent2 must integrate with Microsoft Dynamics 365 Contact Center voice channel.
You need to recommend language models for the agents.
What should you recommend for each agent?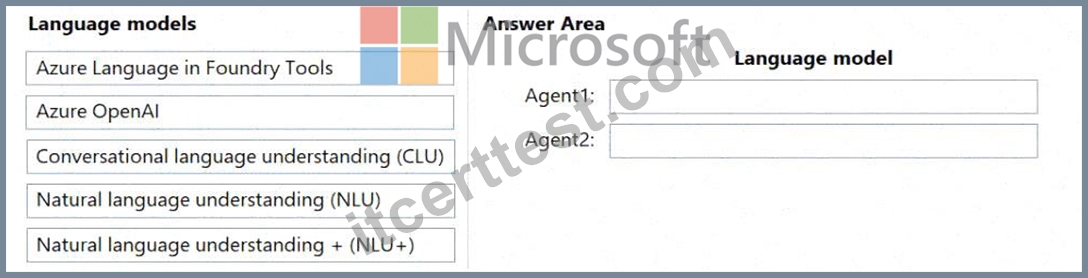
Answer:
Explanation: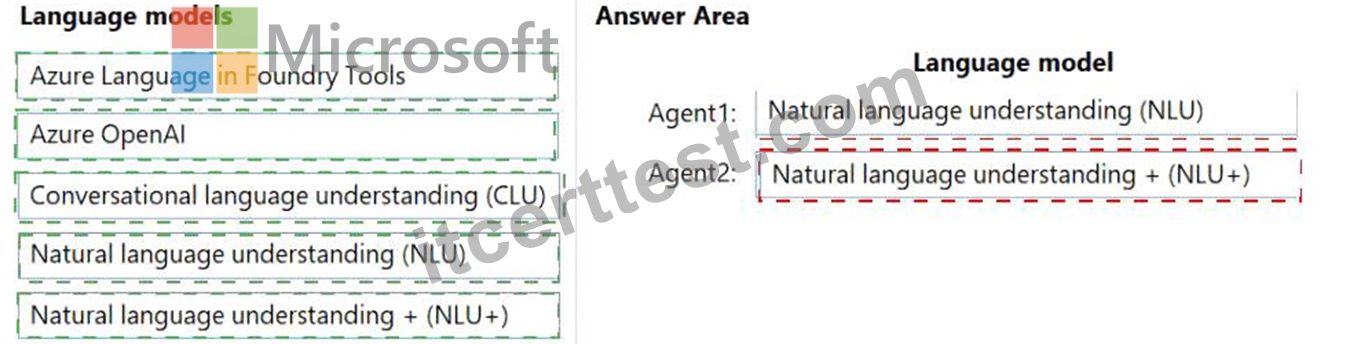
Explanation:
Agent 1 = NLU
Agent 2 = NLU and NLU+
https://learn.microsoft.com/en-us/microsoft-copilot-studio/nlu-overview Agent1 must support simple and short phrases for a given topic. That is the classic use case for NLU in Copilot Studio. NLU is designed for standard intent recognition where users enter brief, predictable utterances tied to a topic.
This makes NLU the best fit for:
narrow topic triggering
short phrase matching
standard, non-generative agent behavior
Why Agent2 = NLU+
Agent2 must integrate with Microsoft Dynamics 365 Contact Center voice channel. For that scenario, NLU+ is the correct recommendation among the listed standard models.
NLU+ extends the standard NLU approach and is the model aligned to scenarios that need stronger language understanding support in more advanced enterprise channel integrations such as voice experiences. Since the requirement explicitly says:
use a standard model
do not use generative orchestration
NLU+ fits better than Azure OpenAI or other generative options.
NEW QUESTION # 16
A company has a Microsoft Foundry project that uses a single agent and a single prompt to complete a series of tasks.
The agent encounters the following issues:
It frequently produces incomplete results.
It struggles with domain-specific reasoning.
Agent response times are remarkably slow.
You need to recommend a solution to improve the overall performance and accuracy of the agent.
What should you include in the recommendation? To answer, drag the appropriate actions to the correct requirements. Each action may be used once, more than once, or not at all.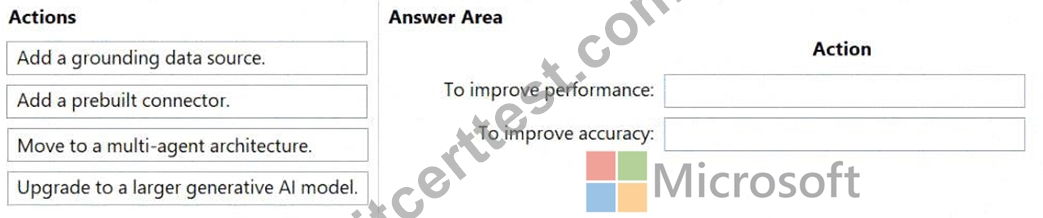
Answer:
Explanation: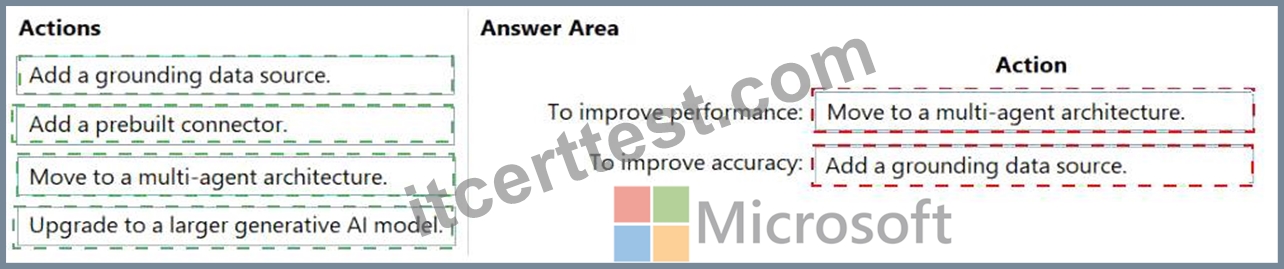
Explanation:
To improve performance # Move to a multi-agent architecture
To improve accuracy # Add a grounding data source
The current design uses a single agent and a single prompt to complete a series of tasks. That is often a bottleneck. When one agent is responsible for everything, it has to manage multiple steps, multiple reasoning modes, and multiple task transitions in one flow. This commonly leads to:
slower response times
task overload
incomplete outputs
reduced efficiency as complexity grows
Moving to a multi-agent architecture helps performance because tasks can be separated by function. For example:
one agent can handle task planning
another can retrieve domain knowledge
another can perform structured reasoning
another can prepare the final response
From an agentic AI systems perspective, decomposition improves throughput and execution quality. Instead of one overloaded agent trying to do everything, specialized agents handle narrower responsibilities. That often reduces latency in practical enterprise designs and improves the reliability of task completion.
This also addresses the symptom of incomplete results, because a multi-agent architecture can break a large workflow into smaller, controlled substeps.
Why "Add a grounding data source" improves accuracy
The agent struggles with domain-specific reasoning. That strongly suggests it lacks sufficient domain context during inference.
The best way to improve accuracy in this case is to add a grounding data source.
Grounding means giving the model access to trusted, relevant business knowledge at runtime, such as:
internal documentation
product specifications
policy manuals
knowledge bases
industry-specific reference data
This improves domain-specific reasoning because the model no longer relies only on general pretrained knowledge. Instead, it can anchor its responses in authoritative content.
From an AI business solutions standpoint, grounding is one of the most important mechanisms for improving:
factual relevance
domain accuracy
consistency
trustworthiness
explainability in enterprise contexts
When a model is inaccurate because it lacks business context, grounding is usually a better first fix than simply scaling model size.
Why the other actions are not the best fit
Add a prebuilt connector
A prebuilt connector helps with integration to systems and services, but it does not directly solve slow reasoning, incomplete output, or weak domain-specific reasoning unless the issue is specifically missing access to an external system. That is not the main problem described here.
Upgrade to a larger generative AI model
A larger model may sometimes improve reasoning quality, but it usually comes with higher cost and often slower response times, which works against the stated performance issue. It is not the best recommendation when the current agent is already slow.
Also, when domain-specific reasoning is the problem, grounding is usually more efficient and more controllable than simply choosing a larger model.
Expert reasoning shortcut
Use this exam logic:
Slow and overloaded single agent handling many tasks # move to multi-agent architecture Weak domain-specific reasoning # add grounding data source Need system integration # prebuilt connector Need raw generative capability increase, but can accept more cost/latency # larger model
NEW QUESTION # 17
You are creating validation criteria for a custom generative AI model that produces business reports based on internal enterprise data.
You need to assess whether the model's outputs are appropriate and meaningful for the business reports.
Which metric should you use?
Answer: A
Explanation:
To validate a custom generative AI model for business reports based on internal data, you should focus on alignment with domain-specific tasks through a mix of automated and human-centric metrics.
Validation Criteria for Business Reports
*-> Task-Specific Quality Evaluation (TSQE): This is your primary metric for assessing whether outputs are meaningful for specific business tasks.
* Groundedness and Factuality: Measure the model's ability to provide information strictly referenced from your internal enterprise data. This prevents "hallucinations" that could lead to poor business decisions.
* Domain-Specific Benchmarking: Compare AI outputs against "ground truth" data-verified, accurate reports previously created by human experts.
Reference:
https://www.prompts.ai/blog/how-to-evaluate-generative-ai-llm-outputs-with-structure-and- precision
NEW QUESTION # 18
......
Itcerttest's Microsoft AB-100 exam training materials not only can save your energy and money, but also can save a lot of time for you. Because the things what our materials have done, you might need a few months to achieve. So what you have to do is use the Itcerttest Microsoft AB-100 Exam Training materials. And obtain this certificate for yourself. Itcerttest will help you to get the knowledge and experience that you need and will provide you with a detailed Microsoft AB-100 exam objective. So with it, you will pass the exam.
New AB-100 Exam Experience: https://www.itcerttest.com/AB-100_braindumps.html
P.S. Free 2026 Microsoft AB-100 dumps are available on Google Drive shared by Itcerttest: https://drive.google.com/open?id=1qWIb2PG6yedVi_dT02uv1TbqfcDR6pBc