Databricks-Certified-Professional-Data-Engineer Free Sample - Successfully Pass The Databricks Certified Professional Data Engineer Exam

There are so many features to show that our Databricks-Certified-Professional-Data-Engineer study guide surpasses others. You can have a free try for downloading our Databricks-Certified-Professional-Data-Engineer exam demo before you buy our products. What’s more, you can acquire the latest version of Databricks-Certified-Professional-Data-Engineer training materials checked and revised by our exam professionals after your purchase constantly for a year. Besides, the pass rate of our Databricks-Certified-Professional-Data-Engineer Exam Questions are unparalled high as 98% to 100%, you will get success easily with our help.
| Section | Weight | Objectives |
|---|
| Topic 1: Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
- 1. Differences between data lake, data warehouse, and lakehouse
- 2. Data governance fundamentals
- 3. Bronze, silver, gold data layers
|
| Topic 2: Delta Lake | 20-25% | - Delta Lake operations
- 1. Delta Live Tables
- 2. Merge, update, delete operations
- 3. Schema evolution and enforcement
- Delta Lake fundamentals
- 1. Optimize and Z-order
- 2. Time travel and data versioning
- 3. ACID transactions
|
| Topic 3: Data Ingestion | 15-20% | - Streaming ingestion
- 1. Kafka integration
- 2. Structured streaming fundamentals
- Batch ingestion methods
- 1. Integration with external systems
- 2. Spark APIs for ingestion
- 3. DBR autoloader
|
| Topic 4: Data Processing with Spark | 25-30% | - Spark DataFrames and Spark SQL
- 1. Spark SQL queries and functions
- 2. DataFrame operations and transformations
- 3. Window functions
- Python and SQL for data engineering
- 1. Spark APIs in Python
- 2. Built-in and user-defined functions
- 3. Performance optimization techniques
|
| Topic 5: Pipeline Development and Orchestration | 10-15% | - Databricks workflows
- 1. Jobs and job scheduling
- 2. Monitoring and alerting
- 3. Task dependencies and orchestration
|
>> Databricks-Certified-Professional-Data-Engineer Free Sample <<
Databricks-Certified-Professional-Data-Engineer Study Practice Guide Give Customers Best Databricks Certified Professional Data Engineer Exam Exam Materials
Databricks-Certified-Professional-Data-Engineer guide torrent is authoritative. Over the years, our study materials have helped tens of thousands of candidates successfully pass the exam. Databricks-Certified-Professional-Data-Engineer certification training is prepared by industry experts based on years of research on the syllabus. These experts are certificate holders who have already passed the certification. They have a keen sense of smell for the test. Therefore, Databricks-Certified-Professional-Data-Engineer Certification Training is the closest material to the real exam questions. With our study materials, you don't have to worry about learning materials that don't match the exam content.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q177-Q182):
NEW QUESTION # 177
A data engineer, while designing a Pandas UDF to process financial time-series data with complex calculations that require maintaining state across rows within each stock symbol group, must ensure the function is efficient and scalable. Which approach will solve the problem with minimum overhead while preserving data integrity?
- A. Use applyInPandas on a Spark DataFrame so that each stock symbol group is received as a pandas DataFrame, allowing processing within each group while maintaining state variables local to each group's processing function.
- B. Use a scalar_iter Pandas UDF with iterator-based processing, implementing state management through persistent storage (Delta tables) that gets updated after each batch to maintain continuity across iterator chunks.
- C. Use a scalar Pandas UDF that processes the entire dataset at once, implementing custom partitioning logic within the UDF to group by stock symbol and maintain state using global variables shared across all executor processes.
- D. Use a grouped-aggregate Pandas UDF that processes each stock symbol group independently, maintaining state through intermediate aggregation results that get passed between successive UDF calls via broadcast variables.
Answer: A
Explanation:
applyInPandas is the documented grouped Pandas API for processing each group as a pandas DataFrame.
Spark passes all columns for each group together, which allows per-group state to be maintained naturally inside the function. By contrast, scalar Pandas UDFs are batch-oriented Series-to-Series operations, not group- state processing tools. ( Apache Spark ) This is why option C is the intended best answer among the listed choices. Option A adds unnecessary external persistence overhead, option B relies on unsupported global executor state, and option D misuses grouped aggregation semantics for row-by-row stateful logic. Spark also documents applyInPandas specifically as a grouped operation, while scalar Pandas UDFs process row batches and concatenate results rather than preserving grouped state semantics. ( Apache Spark )
======
NEW QUESTION # 178
A distributed team of data analysts share computing resources on an interactive cluster with autoscaling configured. In order to better manage costs and query throughput, the workspace administrator is hoping to evaluate whether cluster upscaling is caused by many concurrent users or resource-intensive queries.
In which location can one review the timeline for cluster resizing events?
- A. Cluster Event Log
- B. Executor's log file
- C. Ganglia
- D. Workspace audit logs
- E. Driver's log file
Answer: A
NEW QUESTION # 179
A data ingestion task requires a one-TB JSON dataset to be written out to Parquet with a target part-file size of
512 MB. Because Parquet is being used instead of Delta Lake, built-in file-sizing features such as Auto-Optimize & Auto-Compaction cannot be used.
Which strategy will yield the best performance without shuffling data?
- A. Ingest the data, execute the narrow transformations, repartition to 2,048 partitions (1TB*
1024*1024/512), and then write to parquet. - B. Set spark.sql.files.maxPartitionBytes to 512 MB, ingest the data, execute the narrow transformations, and then write to parquet.
- C. Set spark.sql.adaptive.advisoryPartitionSizeInBytes to 512 MB bytes, ingest the data, execute the narrow transformations, coalesce to 2,048 partitions (1TB*1024*1024/512), and then write to parquet.
- D. Set spark.sql.shuffle.partitions to 2,048 partitions (1TB*1024*1024/512), ingest the data, execute the narrow transformations, optimize the data by sorting it (which automatically repartitions the data), and then write to parquet.
- E. Set spark.sql.shuffle.partitions to 512, ingest the data, execute the narrow transformations, and then write to parquet.
Answer: D
Explanation:
The key to efficiently converting a large JSON dataset to Parquet files of a specific size without shuffling data lies in controlling the size of the output files directly.
* Setting spark.sql.files.maxPartitionBytes to 512 MB configures Spark to process data in chunks of
512 MB. This setting directly influences the size of the part-files in the output, aligning with the target file size.
* Narrow transformations (which do not involve shuffling data across partitions) can then be applied to this data.
* Writing the data out to Parquet will result in files that are approximately the size specified by spark.sql.files.maxPartitionBytes, in this case, 512 MB.
* The other options involve unnecessary shuffles or repartitions (B, C, D) or an incorrect setting for this specific requirement (E).
References:
* Apache Spark Documentation: Configuration - spark.sql.files.maxPartitionBytes
* Databricks Documentation on Data Sources: Databricks Data Sources Guide
NEW QUESTION # 180
You were asked to create or overwrite an existing delta table to store the below transaction data.
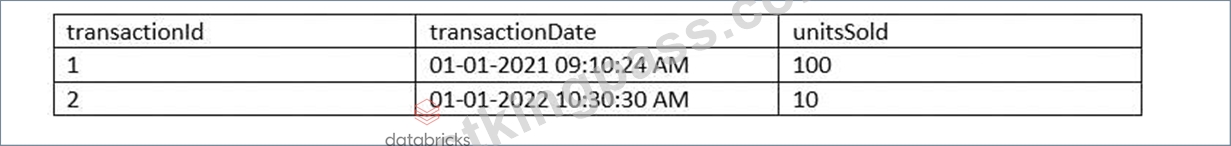
- A. 1.CREATE OR REPLACE TABLE transactions (
2.transactionId int,
3.transactionDate timestamp,
4.unitsSold int) - B. 1.CREATE IF EXSITS REPLACE TABLE transactions (
2.transactionId int,
3.transactionDate timestamp,
4.unitsSold int) - C. 1.CREATE OR REPLACE TABLE IF EXISTS transactions (
2.transactionId int,
3.transactionDate timestamp,
4.unitsSold int)
5.FORMAT DELTA - D. 1.CREATE OR REPLACE DELTA TABLE transactions (
2.transactionId int,
3.transactionDate timestamp,
4.unitsSold int)
Answer: A
Explanation:
Explanation
The answer is
1.CREATE OR REPLACE TABLE transactions (
2.transactionId int,
3.transactionDate timestamp,
4.unitsSold int)
When creating a table in Databricks by default the table is stored in DELTA format.
NEW QUESTION # 181
A data engineer has configured their Databricks Asset Bundle with multiple targets in databricks.yml and deployed it to the production workspace. Now, to validate the deployment, they need to invoke a job named my_project_job specifically within the prod target context. Assuming the job is already deployed, they need to trigger its execution while ensuring the target-specific configuration is respected.
Which command will trigger the job execution?
- A. databricks bundle run my_project_job -t prod
- B. databricks job run my_project_job --env prod
- C. databricks run my_project_job -t prod
- D. databricks execute my_project_job -e prod
Answer: A
Explanation:
Databricks Asset Bundles (DABs) enable declarative configuration and deployment of Databricks resources such as jobs, pipelines, and dashboards across multiple environments.
Once deployed, jobs can be executed in a specific target context using the databricks bundle run command, which ensures all environment-specific configurations from the bundle definition (such as parameters, cluster settings, and workspace URLs) are respected.
The -t flag specifies the target environment (e.g., dev, staging, or prod). This ensures that the execution runs with the correct configuration defined under that target in databricks.yml.
Other options (A, B, and C) are invalid because they reference deprecated or incorrect command syntax that doesn't integrate with bundle targets. Therefore, D is the correct and verified answer.
NEW QUESTION # 182
......
To further strengthen your preparation for the Databricks Databricks-Certified-Professional-Data-Engineer exam, TestkingPass provides an online Databricks Practice Test engine. With this interactive tool, you can practice the Databricks-Certified-Professional-Data-Engineer Exam questions in a simulated exam environment. The Databricks-Certified-Professional-Data-Engineer online practice test engine is designed based on the real Databricks Databricks-Certified-Professional-Data-Engineer Exam patterns, allowing you to familiarize yourself with the format and gain confidence for the actual Databricks Databricks-Certified-Professional-Data-Engineer exam. Practicing with the Databricks Databricks-Certified-Professional-Data-Engineer exam questions will not only increase your understanding but also boost your overall performance.
Databricks-Certified-Professional-Data-Engineer Exam Consultant: https://www.testkingpass.com/Databricks-Certified-Professional-Data-Engineer-testking-dumps.html
- Valid Databricks-Certified-Professional-Data-Engineer Test Syllabus 🏬 Databricks-Certified-Professional-Data-Engineer Valid Test Discount 🏝 Databricks-Certified-Professional-Data-Engineer Learning Engine 🪀 Open ▛ www.prepawayexam.com ▟ and search for 【 Databricks-Certified-Professional-Data-Engineer 】 to download exam materials for free 🚶Databricks-Certified-Professional-Data-Engineer Guide
- Databricks Databricks-Certified-Professional-Data-Engineer – Best Practices to Pass Databricks-Certified-Professional-Data-Engineer Exam [2026] 🔕 ➤ www.pdfvce.com ⮘ is best website to obtain ⇛ Databricks-Certified-Professional-Data-Engineer ⇚ for free download 🅾Databricks-Certified-Professional-Data-Engineer Exam Certification Cost
- Free PDF Databricks - Useful Databricks-Certified-Professional-Data-Engineer - Databricks Certified Professional Data Engineer Exam Free Sample 👧 Immediately open ▛ www.prep4sures.top ▟ and search for ✔ Databricks-Certified-Professional-Data-Engineer ️✔️ to obtain a free download 🎄Cert Databricks-Certified-Professional-Data-Engineer Exam
- Starting Your Databricks Databricks-Certified-Professional-Data-Engineer Exam Preparation? Get the Right Direction Here 👴 Copy URL “ www.pdfvce.com ” open and search for ✔ Databricks-Certified-Professional-Data-Engineer ️✔️ to download for free 🤣Instant Databricks-Certified-Professional-Data-Engineer Download
- Free PDF Databricks - Databricks-Certified-Professional-Data-Engineer - High Pass-Rate Databricks Certified Professional Data Engineer Exam Free Sample ◀ Search for ⇛ Databricks-Certified-Professional-Data-Engineer ⇚ and download exam materials for free through ➤ www.dumpsquestion.com ⮘ 👩Databricks-Certified-Professional-Data-Engineer Valid Exam Labs
- Reliable Databricks-Certified-Professional-Data-Engineer Test Prep 🔧 Databricks-Certified-Professional-Data-Engineer Dumps Collection 🍢 Databricks-Certified-Professional-Data-Engineer Valid Test Discount 😋 Download ➠ Databricks-Certified-Professional-Data-Engineer 🠰 for free by simply searching on ➽ www.pdfvce.com 🢪 ⓂNew Databricks-Certified-Professional-Data-Engineer Mock Exam
- Databricks-Certified-Professional-Data-Engineer Free Sample | Professional Databricks-Certified-Professional-Data-Engineer: Databricks Certified Professional Data Engineer Exam 🥙 Search for 「 Databricks-Certified-Professional-Data-Engineer 」 and download it for free on 【 www.exam4labs.com 】 website ✨Databricks-Certified-Professional-Data-Engineer Real Sheets
- ThreeFormats of Pdfvce Databricks Databricks-Certified-Professional-Data-Engineer Practice Test Questions 📢 Search for ▛ Databricks-Certified-Professional-Data-Engineer ▟ on ⮆ www.pdfvce.com ⮄ immediately to obtain a free download ✏Databricks-Certified-Professional-Data-Engineer Exam Format
- Databricks-Certified-Professional-Data-Engineer Valid Test Format 🗜 Training Databricks-Certified-Professional-Data-Engineer Kit 🎹 Reliable Databricks-Certified-Professional-Data-Engineer Test Prep 🥶 Download ✔ Databricks-Certified-Professional-Data-Engineer ️✔️ for free by simply entering ➡ www.prepawaypdf.com ️⬅️ website 🍀New Databricks-Certified-Professional-Data-Engineer Mock Exam
- Databricks-Certified-Professional-Data-Engineer Reliable Study Guide 😂 Databricks-Certified-Professional-Data-Engineer Real Sheets 🛬 Training Databricks-Certified-Professional-Data-Engineer Kit 🐨 Copy URL [ www.pdfvce.com ] open and search for ( Databricks-Certified-Professional-Data-Engineer ) to download for free 🏄Exam Databricks-Certified-Professional-Data-Engineer Lab Questions
- Databricks-Certified-Professional-Data-Engineer Valid Dumps Pdf 🤭 Databricks-Certified-Professional-Data-Engineer Exam Details 🏚 Databricks-Certified-Professional-Data-Engineer Valid Test Discount 🅾 Download ➤ Databricks-Certified-Professional-Data-Engineer ⮘ for free by simply searching on ➥ www.testkingpass.com 🡄 👲Databricks-Certified-Professional-Data-Engineer Latest Test Question
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, wanderlog.com, Disposable vapes