你是其中之一嗎,你是否還在擔心和困惑的各種材料和花哨的培訓課程考試嗎?KaoGuTi是你正確的選擇,因為我們可以為你提供全面的考試資料,包括問題及答案,也是最精確的解釋,所有這些將幫助你掌握更好的知識,我們有信心你將通過KaoGuTi的Microsoft的DP-750考試認證,這也是我們對所有客戶提供的保障。
| Section | Weight | Objectives |
|---|---|---|
| Deploy and manage data pipelines and workloads | 30-35% | - Operational reliability
|
| Configure and manage Azure Databricks environments | 15-20% | - Workspace and compute configuration
|
| Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
| Prepare and process data | 30-35% | - Data quality and validation
|
想通過學習Microsoft的DP-750認證考試的相關知識來提高自己的技能,讓別人更加認可你嗎?Microsoft的考試可以讓你更好地提升你自己。如果你取得了DP-750認證考試的資格,那麼你就可以更好地完成你的工作。雖然這個考試很難,但是你準備考試時不用那麼辛苦。使用KaoGuTi的DP-750考古題以後你不僅可以一次輕鬆通過考試,還可以掌握考試要求的技能。
問題 #24
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains two catalogs named Catalog1 and Catalog2.
An external application uses a service principal named SP1 to connect to a SQL warehouse.
You need to ensure that SP1 can query the data in Catalog1 and Catalog2. The solution must follow the principle of least privilege.
Which permissions should you grant to SP1 for the catalogs?
答案:A
問題 #25
Hotspot Question
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job1 contains three tasks named Task1, Task2, and Task3.
If Task1 fails, Task2 and Task3 must be prevented from running. Successfully completed tasks must NOT rerun during recovery.
You need to configure Job1 to support controlled failure handling and recovery.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.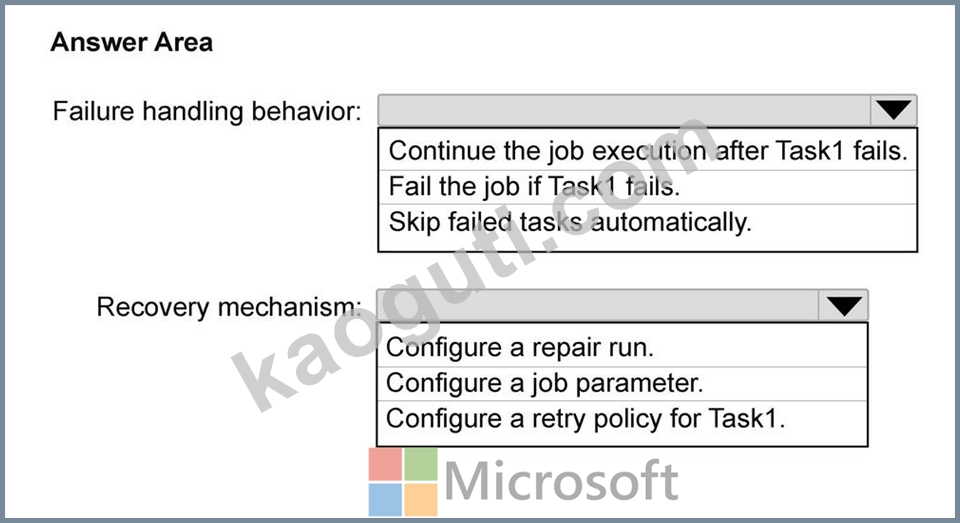
答案:
解題說明: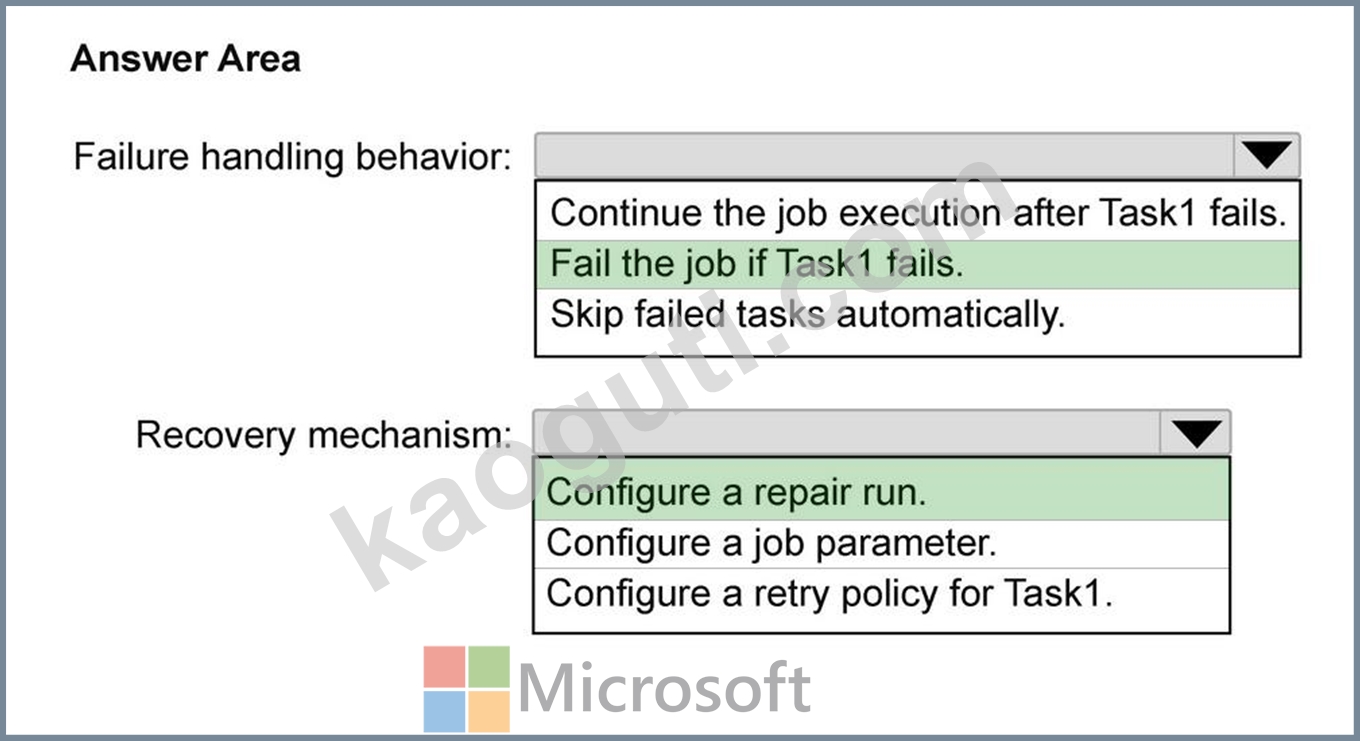
問題 #26
You have an Azure Databricks workspace that contains an all-purpose cluster named Cluster! You need to configure Cluster1 to meet the following requirements;
* The cluster must scale up automatically when workloads increase.
* The cluster must scale down automatically when workloads decrease.
The solution must minimize costs.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
答案:B,E
解題說明:
The correct answers are C and D. Together they deliver cost-efficient autoscaling:
D (Enable autoscaling) allows the cluster to grow when workloads increase and shrink when they ease off.
This satisfies both scale-up and scale-down requirements without manual intervention.
C (Auto-termination after 30 minutes of inactivity) ensures the cluster stops entirely when no work is running, eliminating the cost of an idle cluster. This is the cheapest possible state.
Option A (disable Photon) reduces compute acceleration - that's a performance regression with no meaningful cost benefit for autoscaling. Option B (compute policy that lets users manage settings) adds governance overhead and doesn't address scaling behaviour. Option E (fixed number of workers) is the opposite of autoscaling - a static worker count that either over-provisions during quiet periods or under- provisions during peaks.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/configure#autoscaling
問題 #27
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df-fillna(0, subset=['order_amount'])
Does this meet the goal?
答案:A
解題說明:
The correct answer is B - No.
df.fillna(0, subset=['order_amount']) does not remove null rows. It replaces null values in order_amount with the integer 0, leaving those rows in the DataFrame with 0 as their order_amount value. The row count is unchanged - nulls are imputed, not dropped.
The requirement is to exclude rows where order_amount is null, meaning those rows should not appear in the result at all. fillna is a data imputation function - it fills gaps with default values, which is a different operation entirely from filtering. After fillna, a downstream process would see order_amount = 0 and might treat it as a valid zero-value order rather than recognising it was originally null.
The correct approach is df.dropna(subset=['order_amount']) or df.filter(df.order_amount.isNotNull()), both of which physically remove null rows from the resulting DataFrame.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
問題 #28
You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
* The schemas and tables can be queried in Databricks.
* The schemas and tables appear alongside other Unity Catalog objects.
* The data is NOT copied into Databricks-managed storage.
Solution: You create a Lakeflow Connect pipeline and connect it to DB1. Does this meet the goal?
答案:A
解題說明:
The correct answer is B - No.
Lakeflow Connect is an ingestion service that physically copies data from external databases into Delta tables managed by Databricks. It's designed for scenarios where you want a replicated, writable Delta copy of external data - essentially a CDC-based ingestion pipeline.
That's the opposite of what's required here. The requirement states 'the data is NOT copied into Databricks- managed storage.' Lakeflow Connect would create Delta tables in Databricks and copy DB1's data into them
- a direct violation.
Additionally, Lakeflow Connect creates Databricks-native Delta tables rather than exposing DB1's original schemas and tables as virtual objects. Analysts querying through a Lakeflow Connect pipeline are querying a replicated copy, not the live source.
For zero-copy, live query federation of an external SQL Server into Unity Catalog, Lakehouse Federation (foreign catalog) is the correct tool.
Reference: https://learn.microsoft.com/en-us/azure/databricks/ingestion/lakeflow-connect/
問題 #29
......
KaoGuTi的資深專家團隊研究出了針對Microsoft DP-750考試的培訓教材。通過KaoGuTi提供的教材培訓和學習,通過Microsoft DP-750 認證考試將會很簡單。KaoGuTi能100%保證你首次參加Microsoft DP-750 認證考試就可以成功通過。我們給你提供的考試練習題和答案將在你考試的時候會出現。當你選擇了我們的幫助,KaoGuTi承諾給你一份準確而全面的考試資料,而且會給你提供一年的免費更新服務。
DP-750熱門考題: https://www.kaoguti.com/DP-750_exam-pdf.html