If you don't purchase any course, although you spend a lot of time and effort to review of knowledge to prepare for Anthropic Certification CCAR-P Exam, it is still risky for you to pass the exam. But selecting TorrentVCE's products allows you to spend a small amount of money and time and safely pass the exam. I believe that TorrentVCE is more suitable for your choice in the society where time is so valuable. Moreover, our TorrentVCE a distinct website which can give you a guarantee among many similar sites. Choosing TorrentVCE is equivalent to choose success.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Stakeholder Communication & Lifecycle Management | 14% | - Stakeholder management - Service-level agreements - Architecture documentation - Discovery and requirements gathering - Communicating architectural decisions - Solution lifecycle management |
| Topic 2: Claude Models, Prompting & Context Engineering | 13% | - Guardrails - System prompts and prompt templates - Claude model selection and trade-offs - Prompt reuse and context engineering strategies - Context window optimization |
| Topic 3: Governance, Safety & Risk Management | 14% | - AI safety and guardrails - Regulatory and compliance requirements - Human-in-the-loop validation - Security and risk management - Ethical AI considerations |
| Topic 4: Integration | 19% | - RAG pipeline design
- Authentication and authorization analysis |
| Topic 5: Developer Productivity & Operational Enablement | 7% | - Claude tooling configuration for teams - AI-assisted developer workflows - Developer enablement - Debugging and operational issue resolution |
| Topic 6: Solution Design & Architecture | 17% | - Architectural patterns
- End-to-end architecture design - Multi-agent systems and orchestration - Translating business problems into Claude-based AI solutions - Decomposition techniques for complex problem solving |
| Topic 7: Evaluation, Testing & Optimization | 16% | - System issue diagnosis - Evaluation framework design - Production monitoring and optimization - A/B testing - Evaluation metrics and datasets - Cost and performance optimization |
Our braindumps for CCAR-P real exam are written to highest standard of technical profession, tested by our senior IT experts and certified trainers. You can totally trust our CCAR-P exam prep materials because we guarantee the best quality of our products. With our latest CCAR-P Training Materials, you will pass the certification exam in your first try. We hope you clear exam successfully with our products.
NEW QUESTION # 21
You are comparing two configurations for an internal compliance Q & A assistant. Configuration X reduces top-k retrieval and uses a lighter model, lowering p95 latency by 38 percent while producing a measured 2 percent reduction in the accuracy benchmark. Configuration Y retains the existing top-k retrieval setting and heavier model, with unchanged p95 latency and no measurable change in accuracy. The deployment's stated priorities are accuracy first and latency second.
Which configuration is the better recommendation?
Answer: B
Explanation:
Configuration Y is the appropriate recommendation because architectural optimization must follow the deployment's explicitly defined priorities and acceptance criteria. Accuracy is the primary requirement for this compliance assistant, and Configuration X introduces a measured two-percent accuracy regression. That reduction cannot be dismissed as ordinary benchmark variation unless repeated evaluation establishes that it is statistically insignificant. In a compliance workload, even a small accuracy decline can increase incorrect guidance, missed policy requirements, human-review effort, and regulatory exposure. Configuration Y preserves the established accuracy level while maintaining the current latency profile. Although its latency does not improve, latency is explicitly the secondary objective. Configuration X could be reconsidered only if further testing eliminates the accuracy regression or stakeholders formally approve a revised trade-off.
Options C and D incorrectly impose a general preference for latency over the documented deployment priorities.
NEW QUESTION # 22
You are diagnosing a Claude Code session whose subagent uses 50,000 tokens of context before the engineer types a single message.
Which root cause is most likely?
Answer: A
Explanation:
Claude Code constructs the model context before the first user message. That initial context can include the system prompt, project instructions, subagent configuration, MCP server instructions, and tool definitions expressed as JSON schemas. When numerous MCP servers expose many tools and Tool Search is disabled, those schemas must be loaded upfront. A large collection of verbose tool descriptions and parameter schemas can therefore consume tens of thousands of tokens before the engineer enters any text.
Tool Search is specifically designed to prevent this form of context inflation. With Tool Search enabled, Claude initially receives only server instructions and compact tool-identification information; full tool schemas are deferred until a relevant tool is discovered and required. Anthropic consequently describes Tool Search as the mechanism for keeping MCP context consumption low as integrations scale.
Keyboard layouts, font rendering, and display scaling operate outside the language-model context and cannot generate API input tokens. Likewise, model behavior does not silently reserve 50,000 tokens for personal preferences. The diagnostic action is to inspect configured MCP servers and tool counts, determine whether Tool Search has been disabled, and remove or defer unnecessary definitions.
Study Guide references/topics: [MCP Tool Search and context scaling](https://docs.anthropic.com/en/docs
/claude-code/mcp); MCP server configuration; subagent context budgeting; tool-schema optimization.
NEW QUESTION # 23
The engineering lead at Trenova Systems, Inc. is evaluating two proposals for improving developer workflows using Claude-assisted tooling. Proposal A adds Claude Code to the IDE for inline code generation and review. Proposal B routes all code-generation requests through a shared Slack bot without IDE integration.
Which two observations most accurately evaluate these proposals against workflow-improvement objectives?
(Select two.)
Answer: C,D
Explanation:
Workflow improvement depends on where assistance is delivered, not solely on the underlying model. IDE integration makes code, selections, diagnostics, diffs, and repository context available at the point where developers work. This reduces context switching and avoids repeatedly transferring code between systems.
Routing every request through Slack introduces an additional interaction surface, separates assistance from development context, and increases friction. A Slack record may support auditability, but it does not outweigh the stated productivity objective, and equivalent audit data can be captured through approved telemetry and repository history. Notifications do not inherently improve engineering velocity. Anthropic's Claude Code integrations are designed to place agentic coding capabilities directly within terminal and IDE workflows.
NEW QUESTION # 24
You are evaluating retrieval-strategy claims used by a peer team.
For each claim, select yes if the statement is generally accurate. Otherwise, select no.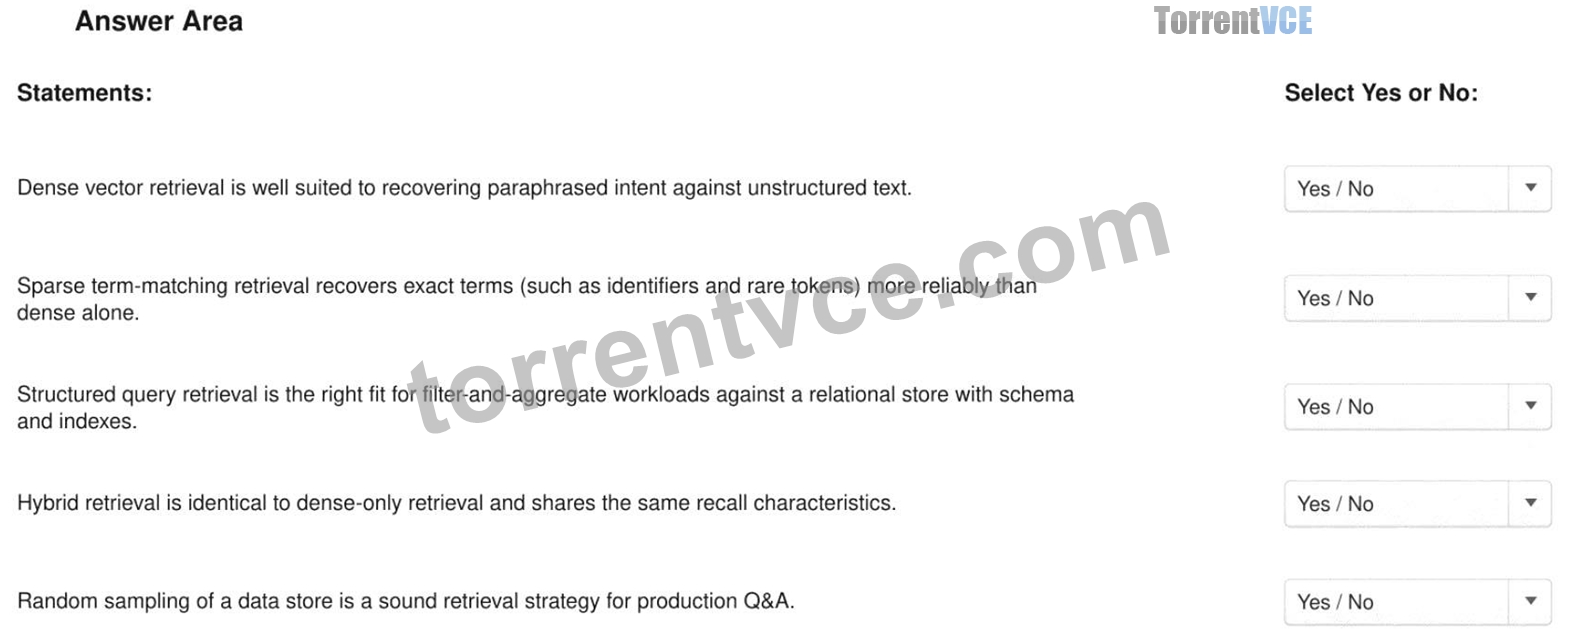
Answer:
Explanation: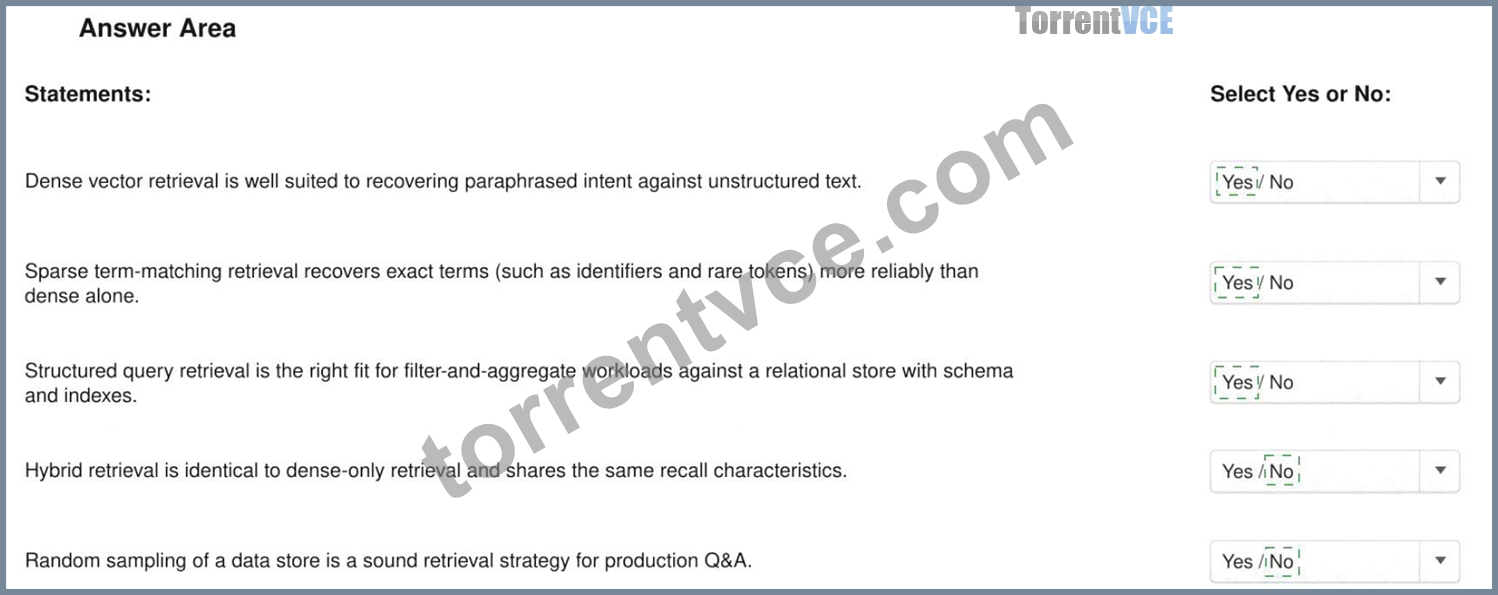
Explanation:
Yes, Yes, Yes, No, No
Dense vector retrieval represents semantic similarity, making it suitable for matching paraphrases and conceptually related language even when the query and source do not share identical words. Sparse lexical retrieval, including BM25-style matching, retains strong sensitivity to exact tokens and is therefore valuable for identifiers, product codes, technical names, and uncommon terminology.
Structured query retrieval is appropriate when the required operation depends on explicit fields, predicates, joins, counts, grouping, or aggregation over a relational schema. In that situation, generating or invoking a constrained database query is more precise than approximating the operation through semantic similarity.
Hybrid retrieval is not identical to dense retrieval. It combines semantic and lexical candidate sets, typically followed by rank fusion or reranking. Anthropic's contextual-retrieval guidance explains that semantic search captures meaning and paraphrases, while BM25 captures exact terminology; combining them improves coverage. Contextual Retrieval , Contextual Retrieval Cookbook Random sampling is not a relevance strategy. It provides no systematic relationship between the query and selected evidence, producing unstable coverage and preventable hallucination risk. Production Q & A requires deterministic or evaluated relevance mechanisms, access filters, suitable indexes, and measurable retrieval metrics such as recall at k .
Study Guide references/topics: Dense retrieval; sparse retrieval; structured queries; hybrid search; rank fusion; retrieval evaluation; production RAG design.
NEW QUESTION # 25
You are presenting an architectural decision to a mixed audience that includes an executive sponsor and the engineering leads who will implement the decision.
Which presentation strategy best serves both audiences?
Answer: A
NEW QUESTION # 26
......
You will make progress and obtain your desired certification with our topping CCAR-P exam dumps for we own the first-class quality as well as the first-class customer service online. We can promise that you will get the most joyful study experience. Our CCAR-P learning guide is useful to help you make progress. Besides, the three version of CCAR-P Test Quiz can be used in all kinds of study devices. Furthermore, the three version of CCAR-P pass-sure torrent can promise your success on your coming exam.
Study CCAR-P Group: https://www.torrentvce.com/CCAR-P-valid-vce-collection.html