P.S. Free & New DP-800 dumps are available on Google Drive shared by Prep4SureReview: https://drive.google.com/open?id=1NWM6I1K423avKQA-Q2bVLJP4JFng3yaW
If you face any hitch while using the Microsoft DP-800 practice exam software of Prep4SureReview, contact our customer support. Our team is available for the assistance of Microsoft DP-800 updated exam dumps users. Many candidates of the DP-800 examination pay extra money because Microsoft weaks the content of the test.
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Developing AI-Enabled Database Solutions |
| Exam Number: | DP-800 |
| Exam Price: | $165 USD |
| Available Languages: | Spanish, French, Chinese (Traditional), Korean, Arabic (Saudi Arabia), English, Japanese, Chinese (Simplified), Italian, Portuguese (Brazil), Indonesian (Indonesia), German |
| Passing Score: | 700 |
| Real Exam Qty: | 40-60 |
| Related Certifications: | Microsoft Certified: SQL AI Developer Associate |
| Exam Duration: | 100 minutes |
| Exam Format: | Case studies, Multiple choice, Multiple select, Build list, Drag and drop |
| Certificate Validity Period: | 1 year |
| Sample Questions: | Microsoft DP-800 Sample Questions |
| Exam Way: | Online proctored or in-person at a testing center |
| Pre Condition: | No specific prerequisites, but candidates should have experience with SQL and a basic understanding of Azure services. Familiarity with AI or machine learning concepts is recommended. |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/certifications/exams/dp-800/ |
>> Reliable DP-800 Exam Guide <<
Our DP-800 study practice guide boosts the function to stimulate the real exam. The clients can use our software to stimulate the real exam to be familiar with the speed, environment and pressure of the real DP-800 exam and get a well preparation for the real exam. Under the virtual exam environment the clients can adjust their speeds to answer the DP-800 Questions, train their actual combat abilities and be adjusted to the pressure of the real test. They can also have an understanding of their mastery degree of our DP-800 study practice guide.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
NEW QUESTION # 47
You have an Azure SQL database that contains the following SQL graph tables:
* A NODE table named dbo.Person
* An EDGE table named dbo.Knows
Each row in dbo.Person contains the following columns:
* Personid (int)
* DisplayName (nvarchar(100))
You need to use a HATCH operator and exactly two directed Knows relationships to return the Personid and DisplayName of people that are reachable from the person identified by an input parameter named
@startPersonid.
Which Transact-SQL query should you use?
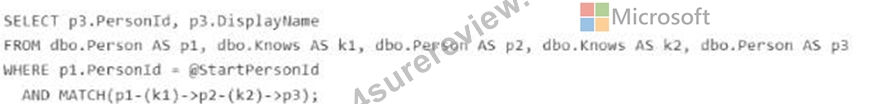
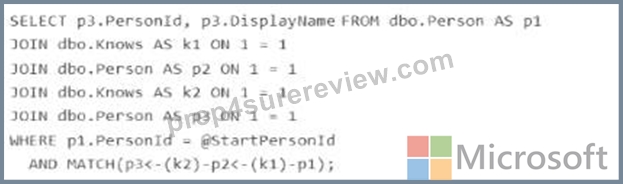
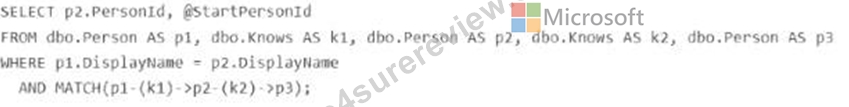
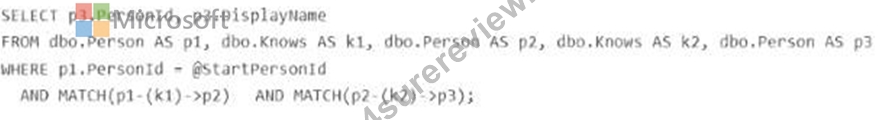
Answer: A
Explanation:
The correct query is Option D because it starts from the input person and uses exactly two directed Knows edges in a single MATCH pattern:
MATCH(p1-(k1)- > p2-(k2)- > p3)
Microsoft documents that SQL Graph uses the MATCH predicate in the WHERE clause to express graph traversal patterns over node and edge tables, and directed relationships are written with arrow syntax such as node1-(edge)- > node2.
Why D is correct:
* It anchors the starting node with p1.PersonId = @StartPersonId.
* It traverses two directed hops : p1 - > p2 - > p3.
* It returns p3.PersonId, p3.DisplayName, which are the people reachable in exactly two Knows relationships.
Why the others are wrong:
* A filters on DisplayName = DisplayName, which is unrelated to the required input parameter and does not correctly anchor the start node.
* B reverses the traversal direction in the pattern.
* C uses two separate MATCH predicates instead of the required single two-hop directed pattern. The proper graph pattern syntax supports chaining the hops directly in one MATCH expression.
NEW QUESTION # 48
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have an SDK-style SQL database project stored in a Git repository. The project targets an Azure SQL database.
The CI build fails with unresolved reference errors when the project references system objects.
You need to update the SQL database project to ensure that dotnet build validates successfully by including the correct system objects in the database model for Azure SQL Database.
Solution: Add the Microsoft.SqlServer.Dacpacs.Master NuGet package to the project.
Does this meet the goal?
Answer: B
Explanation:
Correct:
* Add the Microsoft.SqlServer.Dacpacs.Azure.Master NuGet package to the project.
To resolve system reference errors in an SDK-style SQL project targeting Azure SQL Database, you need to add a reference to the Microsoft.SqlServer.Dacpacs.Azure.Master NuGet package.
In your .sqlproj file, include the following item group:
<ItemGroup>
<PackageReference Include="Microsoft.SqlServer.Dacpacs.Azure.Master" Version="1.60.0" />
</ItemGroup>
Why this works:
System Objects: Standard SDK-style projects don't automatically include system views (like sys.database_principals or sys.dm_db_resource_stats). This package provides the necessary metadata for the compiler.
Azure Specifics: It includes Azure-only system objects that aren't present in the standard master database dacpac used for on-premises SQL Server.
CI/CD Friendly: Since it is a NuGet package, the dotnet build command will automatically restore it during the CI process without requiring manual file paths or local installations of Visual Studio.
Incorrect:
* Add an artifact reference to the Azure SQL Database master.dacpac file.
* Add the Microsoft.SqlServer.Dacpacs.Master NuGet package to the project.
Reference:
https://learn.microsoft.com/en-us/sql/tools/sql-database-projects/concepts/system-objects
NEW QUESTION # 49
Which component handles security in Azure SQL?
Answer: B
Explanation:
Azure Key Vault securely stores secrets and keys.
NEW QUESTION # 50
You have an Azure SQL database that contains a table named knowledgebase, knowledgebase stores human resources (HR) policy documents and contains columns named title, content, category, and embedding.
You have an application named App1. App1 queries two relational tables named employee_pnofiles and benefits_enrollnent that contain HR data. App1 hosts a chatbot that calls a large language model (LLM) directly.
Users report that the chatbot answers general HR questions correctly but provides outdated or incorrect answers when policies change. The chatbot also fails to answer questions that reference internal policy documents by title or category.
You need to recommend a Retrieval Augmented Generation (RAG) solution to resolve the chatbot issues.
What should you recommend? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.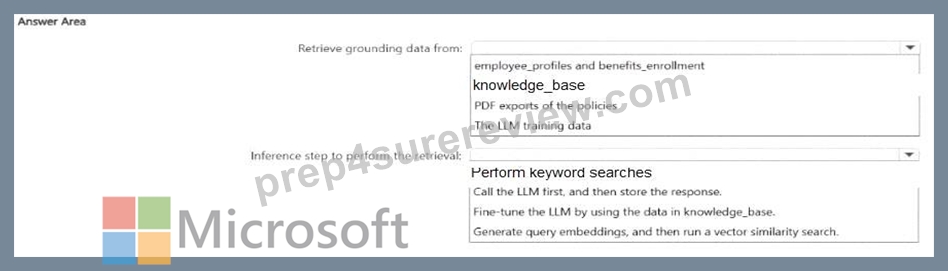
Answer:
Explanation: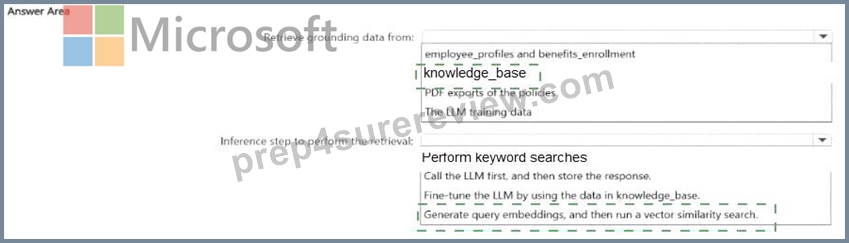
Explanation: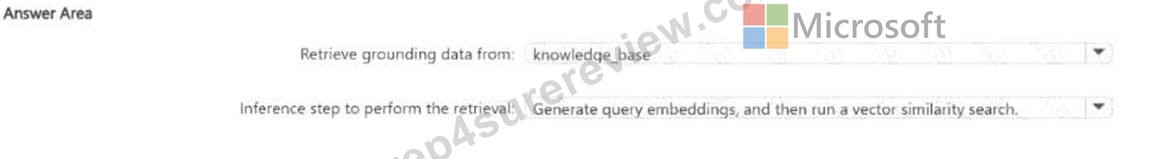
The correct recommendation is to retrieve grounding data from knowledge_base and, at inference time, generate query embeddings and run a vector similarity search .
The chatbot currently answers some general HR questions but fails when policies change and when users ask about internal policy documents by title or category . That is exactly the kind of problem RAG is meant to solve: ground the LLM in the organization's proprietary content instead of relying on the model's training data or unrelated transactional tables. Microsoft's RAG guidance states that RAG extends LLMs by grounding responses in your own content and that, for agentic retrieval, knowledge bases unify knowledge sources for retrieval.
So the grounding data should come from knowledge_base , because that table stores the HR policy documents and already includes fields like title, content, category, and embedding. Those are the fields directly tied to the missing and outdated policy answers. By contrast:
* employee_profiles and benefits_enrollment are operational HR tables, not the authoritative store for policy-document grounding.
* PDF exports of the policies would be inferior to querying the indexed/structured knowledge base already prepared for retrieval.
* The LLM training data is specifically the wrong source when the issue is outdated internal content.
For the retrieval step, Microsoft's guidance says to use embeddings for vector queries and notes that vector similarity search matches concepts, not exact terms . This is especially important because users ask about policy documents by title or category and also phrase questions in ways that might not exactly match document wording. Generating a query embedding and then running a vector similarity search is the appropriate retrieval step in a RAG pipeline.
NEW QUESTION # 51
Hotspot Question
You have an Azure SQL database that contains a table named knowledge_base.
knowledge_base stores human resources (HR) policy documents and contains columns named title, content, category, and embedding.
You have an application named App1. App1 queries two relational tables named employee_profiles and benefits_enrollment that contain HR data. App1 hosts a chatbot that calls a large language model (LLM) directly.
Users report that the chatbot answers general HR questions correctly but provides outdated or incorrect answers when policies change. The chatbot also fails to answer questions that reference internal policy documents by title or category.
You need to recommend a Retrieval Augmented Generation (RAG) solution to resolve the chatbot issues.
What should you recommend? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.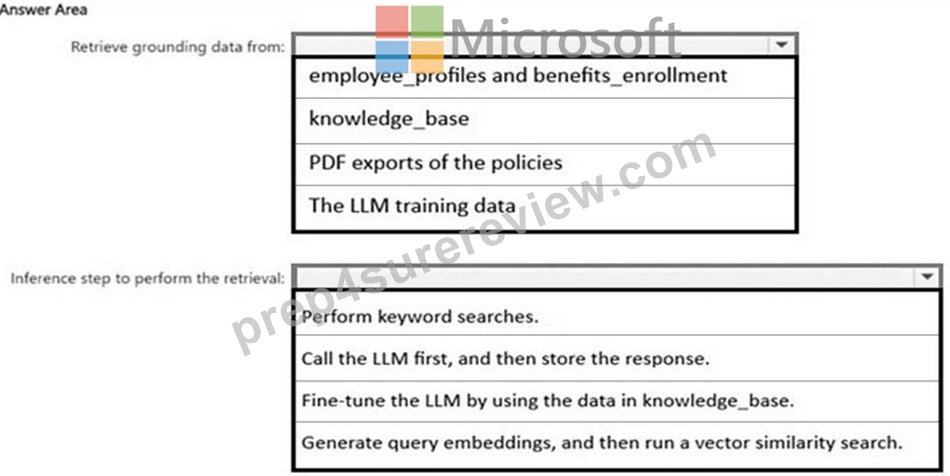
Answer:
Explanation: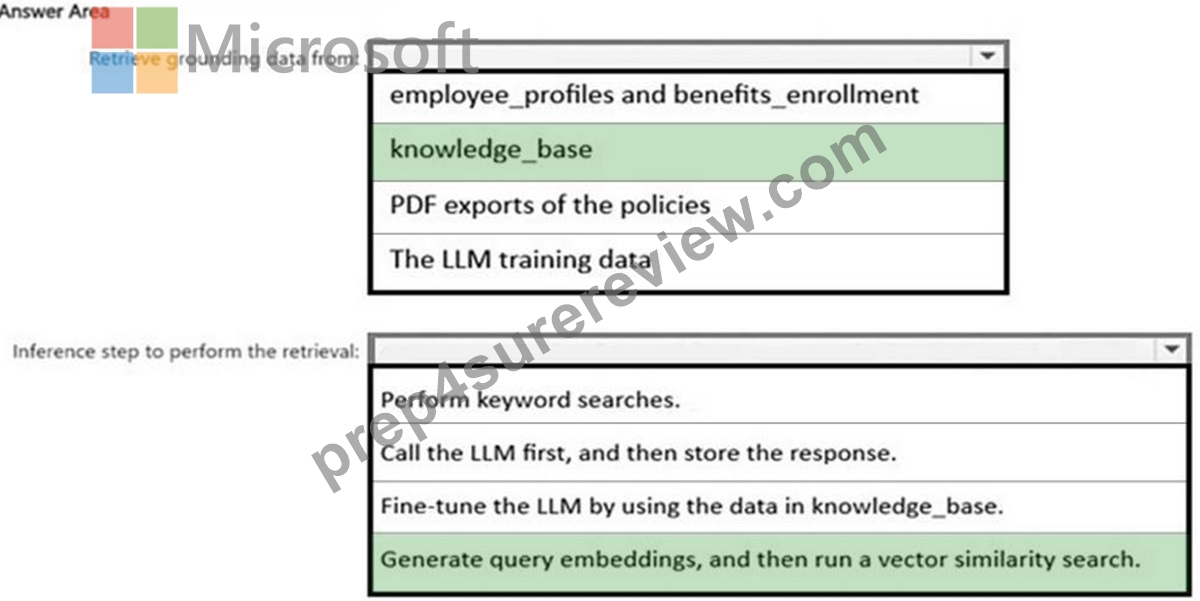
NEW QUESTION # 52
......
DP-800 New Question: https://www.prep4surereview.com/DP-800-latest-braindumps.html
P.S. Free 2026 Microsoft DP-800 dumps are available on Google Drive shared by Prep4SureReview: https://drive.google.com/open?id=1NWM6I1K423avKQA-Q2bVLJP4JFng3yaW