KoreaDumps의 Anthropic인증 CCAR-P덤프는 거의 모든 실제시험문제 범위를 커버하고 있습니다.Anthropic인증 CCAR-P시험덤프를 구매하여 덤프문제로 시험에서 불합격성적표를 받을시KoreaDumps에서는 덤프비용 전액 환불을 약속드립니다.
| Section | Weight | Objectives |
|---|---|---|
| Developer Productivity & Operational Enablement | 7% | - AI-assisted developer workflows - Debugging and operational issue resolution - Claude tooling configuration for teams - Developer enablement |
| Claude Models, Prompting & Context Engineering | 13% | - Claude model selection and trade-offs - Guardrails - System prompts and prompt templates - Prompt reuse and context engineering strategies - Context window optimization |
| Stakeholder Communication & Lifecycle Management | 14% | - Service-level agreements - Discovery and requirements gathering - Stakeholder management - Solution lifecycle management - Architecture documentation - Communicating architectural decisions |
| Solution Design & Architecture | 17% | - Architectural patterns
- Decomposition techniques for complex problem solving - End-to-end architecture design - Multi-agent systems and orchestration - Alignment with business value, cost, performance, and SLAs |
| Evaluation, Testing & Optimization | 16% | - Evaluation metrics and datasets - A/B testing - System issue diagnosis - Evaluation framework design - Cost and performance optimization - Production monitoring and optimization |
| Integration | 19% | - RAG pipeline design
- Claude integration mechanisms
|
| Governance, Safety & Risk Management | 14% | - Security and risk management - Ethical AI considerations - Regulatory and compliance requirements - Human-in-the-loop validation - AI safety and guardrails |
우리의 덤프는 기존의 시험문제와 답과 시험문제분석 등입니다. KoreaDumps에서 제공하는Anthropic CCAR-P시험자료의 문제와 답은 실제시험의 문제와 답과 아주 비슷합니다. KoreaDumps는 여러분이 한번에Anthropic CCAR-P인증시험을 패스함을 보장 드립니다.
질문 # 35
You are defining when to introduce a project subagent versus relying on Claude Code's general capabilities.
Which scenario most directly justifies a dedicated subagent?
정답:B
설명:
A dedicated subagent is justified when specialization is recurring and operationally valuable. Option A allows the team to encode a database-review role once, including its system prompt, triggering description, permitted tools, model, and review criteria. This improves consistency across sessions, isolates specialized context, and applies least privilege by withholding unrelated capabilities. Anthropic's custom subagent documentation supports task-specific prompts, model selection, tool allowlists, permission modes, hooks, skills, and persistent memory. A one-time question does not justify the maintenance overhead of a reusable agent definition, while Options C and D explicitly provide no specialization requirement. The subagent should also have clear invocation conditions, evaluation cases, ownership, and lifecycle review.
Study Guide references/topics: Claude Code subagents; task specialization; context isolation; model routing; scoped permissions; reusable automation.
질문 # 36
An operations engineer reports that a Claude-based pipeline began returning malformed JSON responses after a scheduled maintenance window, causing downstream processing failures.
Which two investigative steps most directly isolate the root cause? (Select two.)
정답:A,D
설명:
The strongest investigation combines configuration comparison with controlled replay. Comparing the current system prompt and output-schema settings against the last known good version identifies maintenance-related configuration drift. Relevant differences include removed formatting instructions, altered schema requirements, incompatible parser expectations, changed stop sequences, or a disabled structured-output mechanism.
Replaying known premaintenance requests against the current configuration creates a controlled test set.
Inspecting the raw response before parsing then establishes whether malformed JSON originates in model generation or is introduced by streaming assembly, transport handling, post-processing, or the downstream parser. If the raw response is valid but the pipeline rejects it, the fault lies after generation. If the raw response is malformed, the prompt, schema enforcement, stop reason, and request configuration become the primary investigation targets.
Clearing the prompt cache assumes cache corruption without evidence. Changing model tiers introduces another variable and weakens causal attribution. Raising `max_tokens` is appropriate only when raw responses show truncation and the returned stop reason indicates the token limit was reached; it is not the most direct initial test.
Study Guide references/topics: [Increasing output consistency](https://docs.anthropic.com/en/docs/test-and- evaluate/strengthen-guardrails/increase-consistency); [agent evaluation methodology] (https://www.anthropic.
com/engineering/demystifying-evals-for-ai-agents); regression replay; last-known-good comparison; raw- output inspection.
질문 # 37
You are classifying token-management tactics by where each tactic applies in the request lifecycle: "Input Preparation," "Prompt Construction," or "Output Handling."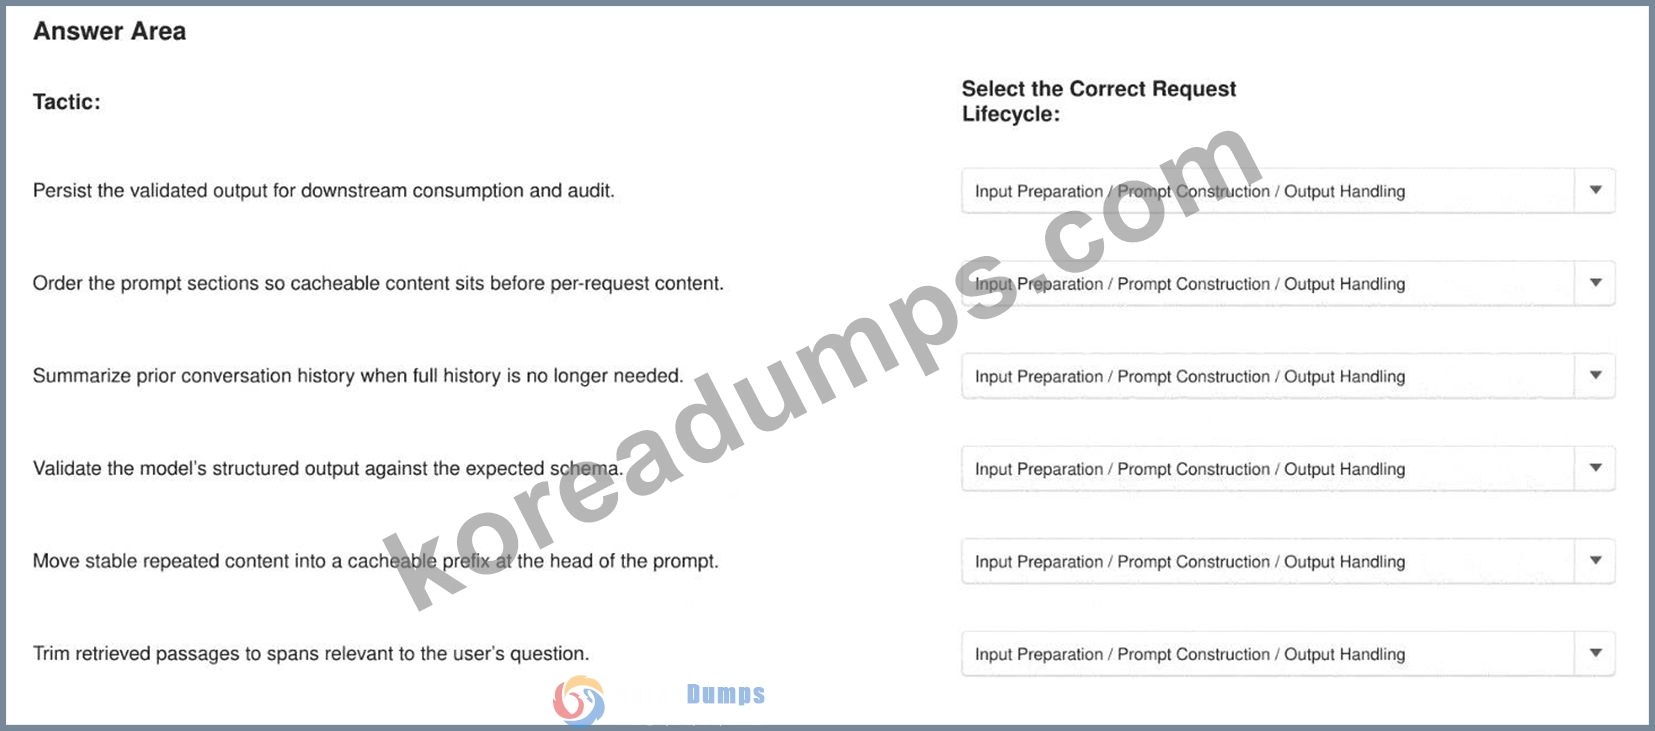
정답:
설명: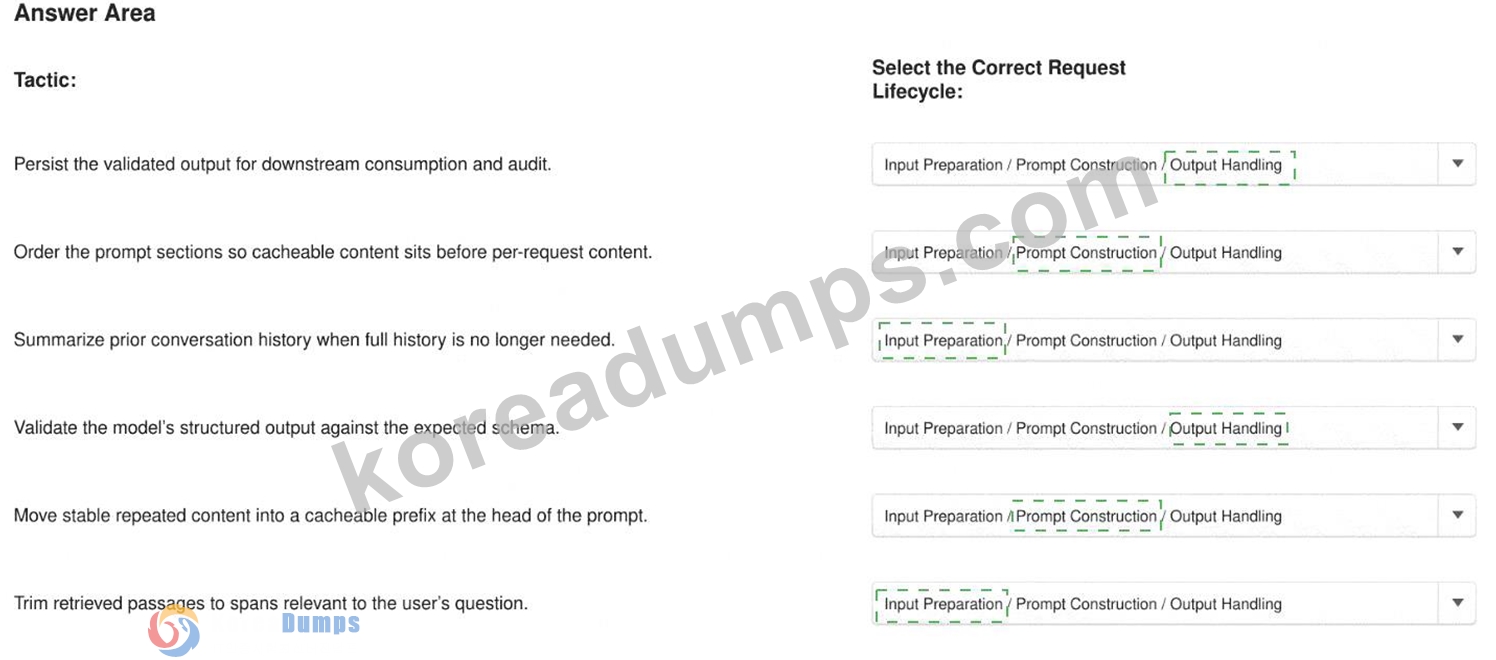
Explanation:
Persist the validated output for downstream consumption and audit - Output Handling Order prompt sections so cacheable content appears before per-request content - Prompt Construction Summarize prior conversation history when full history is no longer needed - Input Preparation Validate the model's structured output against the expected schema - Output Handling Move stable repeated content into a cacheable prefix at the beginning of the prompt - Prompt Construction Trim retrieved passages to spans relevant to the user's question - Input Preparation Input preparation determines what evidence and history should enter the request, so summarization and retrieval trimming belong there. Prompt construction determines ordering and cache boundaries; stable repeated instructions must precede dynamic per-request content to maximize cache reuse. Output handling begins after generation and includes schema validation, persistence, auditing, and downstream delivery.
Mixing these responsibilities creates inefficient prompts and weak validation boundaries. Anthropic's context guidance emphasizes curating the smallest useful context because unnecessary tokens can reduce recall and accuracy. Prompt caching similarly depends on a stable reusable prefix, while structured outputs or schema validation protect downstream systems from malformed responses. Context windows; prompt caching
질문 # 38
You are supporting an engineer whose newly added MCP server does not appear in their Claude Code session.
Which diagnostic step should be tried first?
정답:D
설명:
The first diagnostic action must establish whether Claude Code has loaded the MCP server configuration and whether it can connect to the registered endpoint. The official management command is claude mcp list; within Claude Code, /mcp can also be used to inspect server status. The listing distinguishes registered and connected servers from configurations that require authentication, approval, or connection troubleshooting.
Connect Claude Code to Tools via MCP
If the server was added or its configuration changed after the current session began, reconnecting or restarting the relevant Claude Code session is a proportionate next step. This ensures that configuration state and available tool definitions are refreshed before more intrusive troubleshooting begins. If the server is listed but unhealthy, the engineer can then inspect it with claude mcp get < name > and investigate transport, command path, credentials, workspace approval, or endpoint connectivity.
Options A, B, and D are operationally unsound because they discard working capabilities or environments before confirming the basic registration state. Disabling all MCP servers eliminates useful diagnostic comparisons; changing product families abandons the relevant configuration; reinstalling the operating system is grossly disproportionate and risks destroying evidence needed for diagnosis.
Study Guide references/topics: Claude Code environment configuration; MCP registration; server-status inspection; session refresh; targeted operational troubleshooting.
질문 # 39
You are explaining the precedence of Claude Code configuration scopes to the team.
Which precedence ordering, from highest to lowest, is correct?
정답:B
설명:
The correct general precedence is managed configuration, command-line arguments, local configuration, project configuration, and then user configuration.
Managed configuration has the highest authority because it contains centrally administered organizational and compliance controls that ordinary engineers must not be able to override. Command-line arguments provide temporary session-level overrides where the relevant setting permits them. Local settings apply to one user within a specific repository and take precedence over the shared project configuration. Project settings apply to every contributor using that repository and override general user preferences. User settings form the lowest tier because they provide personal defaults across projects and apply only when no higher-precedence source supplies a value.
Anthropic documents this order explicitly: managed, command line, local, project, and user. It also notes that permission rules may merge rather than behave as simple scalar overrides, and certain security-sensitive keys have specialized precedence behavior. Claude Code Configuration Scopes The ordering allows personal customization without permitting it to defeat repository conventions or centrally mandated security requirements. Architects must still examine the merge behavior of the individual configuration property rather than assuming every array or permission rule is replaced wholesale.
Study Guide references/topics: Claude Code configuration; scope precedence; managed policies; local overrides; project settings; user defaults.
질문 # 40
......
KoreaDumps를 선택함으로, KoreaDumps는 여러분Anthropic인증CCAR-P시험을 패스할 수 있도록 보장하고,만약 시험실패시 KoreaDumps에서는 덤프비용전액환불을 약속합니다.
CCAR-P시험덤프문제: https://www.koreadumps.com/CCAR-P_exam-braindumps.html