P.S. Free & New AI-300 dumps are available on Google Drive shared by Itexamguide: https://drive.google.com/open?id=1X7fUWzHOqgVtu--GsPF7mluzaT0xy9HV
Before you take the exam, you only need to spend 20 to 30 hours to practice, so you can schedule time to balance learning and other things. Of course, you care more about your passing rate. We will provide you with three different versions. The PDF version allows you to download our AI-300 quiz prep. After you download the PDF version of our learning material, you can print it out. In this way, even if you do not have a computer, you can learn our AI-300 Quiz prep. We believe that it will be more convenient for you to take notes. Our website is a very safe and regular platform. You can download our AI-300 exam guide with assurance. You can take full advantage of the fragmented time to learn, and eventually pass the authorization of AI-300 exam.
| Section | Weight | Objectives |
|---|---|---|
| Design and implement a GenAIOps infrastructure | 20–25% | - Implement infrastructure for generative AI workloads
|
| Implement generative AI quality assurance and observability | 10–15% | - Monitor generative AI systems
|
| Design and implement an MLOps infrastructure | 15–20% | - Create and manage Machine Learning workspace resources and assets
|
| Optimize generative AI systems and model performance | 15–20% | - Optimize model selection and configuration
|
| Implement machine learning model lifecycle and operations | 25–30% | - Monitor and maintain models in production
|
>> Valid AI-300 Test Registration <<
Itexamguide provides with actual Microsoft AI-300 exam dumps in PDF format. You can easily download and use AI-300 PDF dumps on laptops, tablets, and smartphones. Our real AI-300 dumps PDF is useful for applicants who don't have enough time to prepare for the examination. If you are a busy individual, you can use AI-300 Pdf Dumps on the go and save time.
NEW QUESTION # 173
-
You review the following Azure CLI command and the relevant Bicep excerpt.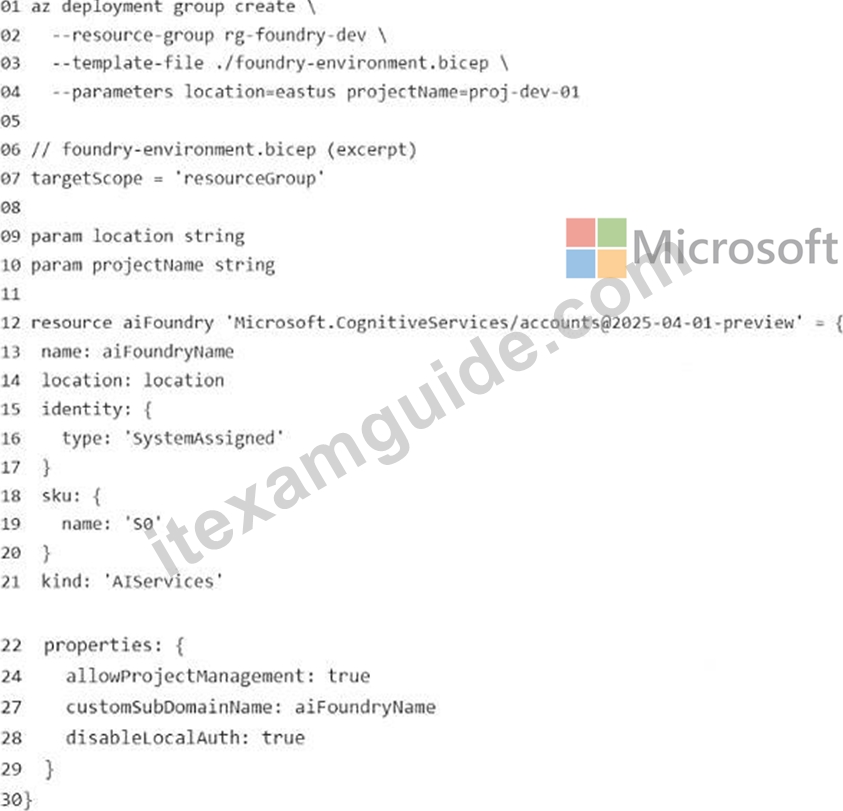
(Non-relevant sections are omitted.)
You need to validate what the snippet will do before it is merged. For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.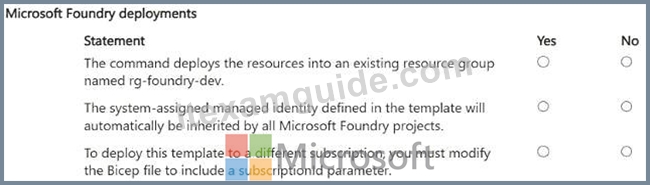
Answer:
Explanation: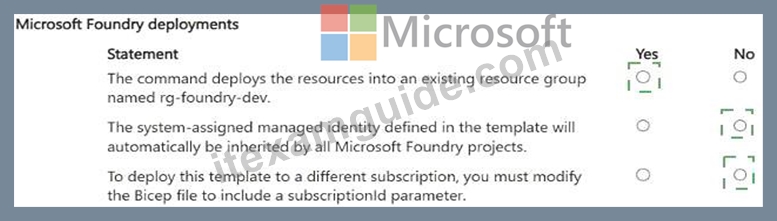
Explanation:
The command deploys the resources into an existing resource group named rg-foundry-dev: Yes The system-assigned managed identity defined in the template will automatically be inherited by all Microsoft Foundry projects: No To deploy this template to a different subscription, you must modify the Bicep file to include a subscriptionId parameter: No The first statement is Yes . The command uses az deployment group create --resource-group rg-foundry-dev, which performs an Azure Resource Manager deployment at resource-group scope . Microsoft documents that the target resource group must already exist; if it does not, it must be created before running the resource- group deployment.
The second statement is No . The Bicep declaration assigns a system-assigned managed identity to the Foundry resource itself . A Microsoft Foundry project is a child resource and can have its own managed identity . Microsoft explicitly shows project creation with " identity " : { " type " : " SystemAssigned " } and separately discusses assigning permissions to a project ' s managed identity. Therefore, the parent ' s system- assigned identity is not automatically inherited as the identity of every project.
The third statement is No . Because targetScope = ' resourceGroup ' , the same Bicep template can be deployed to a resource group in another subscription without adding a subscriptionId parameter. Azure CLI supports the global --subscription argument, or the active subscription can be changed with az account set.
NEW QUESTION # 174
-
A team is developing a Retrieval-Augmented Generation (RAG) system.
The team requires improvements to the system ' s retrieval quality to ensure accurate, grounded responses.
You need to assess RAG performance before you can suggest an improvement strategy.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.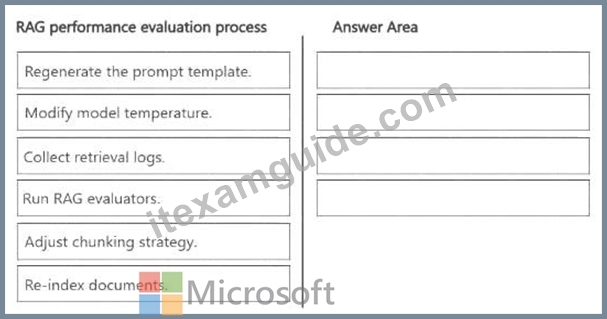
Answer:
Explanation: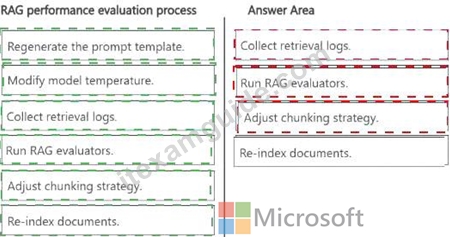
Explanation:
Correct sequence:
* Collect retrieval logs.
* Run RAG evaluators.
* Adjust chunking strategy.
* Re-index documents.
The process should begin by collecting retrieval logs . Retrieval diagnostics provide the evidence needed to understand which queries were issued, which document chunks were returned, and whether relevant content is being surfaced. Without retrieval telemetry, optimization becomes speculative rather than measurable.
Next, run RAG evaluators . Microsoft Foundry provides retrieval-oriented evaluators that assess how relevant retrieved context is to a query. The Retrieval evaluator measures contextual relevance without requiring ground truth, while the Document Retrieval evaluator can calculate metrics such as Fidelity and NDCG when labeled retrieval ground truth exists. These measurements help establish the retrieval-quality baseline before modifications are made.
After identifying retrieval deficiencies, adjust the chunking strategy . Microsoft specifically recommends reviewing chunk size and chunking methodology when retrieval returns irrelevant or incomplete passages.
Chunks that are too small can lose context, while oversized chunks can introduce irrelevant material and reduce retrieval precision.
Finally, re-index the documents so the revised chunking configuration is reflected in the searchable corpus.
Changing temperature or regenerating the prompt template primarily affects generation behavior rather than correcting the underlying retrieval pipeline.
Study Guide Reference: Implement generative AI quality assurance and observability - RAG evaluation, retrieval telemetry, retrieval-quality metrics, chunk optimization, indexing, and grounded-response assessment.
NEW QUESTION # 175
A team is validating a generative AI assistant for a company. The assistant generates responses by using internal knowledge sources.
The company requires assurance that responses are accurate, supported by sources, and related to the user prompts before enabling production access.
You need to implement quality metrics that confirm the assistant produces reliable and meaningful responses.
Which two evaluation metrics should you use? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: B,C
Explanation:
To ensure your Azure Machine Learning generative AI assistant (which utilizes a Retrieval- Augmented Generation or RAG architecture) produces reliable and meaningful responses before going live, you should use the RAG Triad of built-in quality evaluation metrics.
These primary automated metrics-Groundedness, Relevance, and Response Completeness- directly measure accuracy, connection to internal knowledge sources, and alignment with user prompts.
The Primary Metrics (The RAG Triad)
These metrics are evaluated on a 1-to-5 scale using Azure Machine Learning's built-in, AI- assisted "LLM-as-a-judge" evaluators:
Groundedness: Measures how well the assistant's generated answer aligns only with the information retrieved from your internal knowledge sources. Even if a response is factually correct in the real world, it is penalized if the information cannot be verified inside the retrieved context document. This is your primary defense against hallucinations.
Relevance: Assesses how pertinently the model's generated response directly addresses the user's specific prompt. This checks whether the system understood the user's intent or if it provided an off-topic or distracted response.
Response Completeness: Focuses on the "recall" aspect of the assistant. It measures whether the generated text effectively answers all parts of the user prompt using the ground truth data, ensuring no critical insights or data points are omitted.
Reference:
https://medium.com/thedeephub/a-deep-dive-into-evaluation-in-azure-prompt-flow-dd898ebb158c
NEW QUESTION # 176
A team is working in Microsoft Foundry to test and compare large language model (LLM) prompt variants in a development environment.
The team requires consistent inputs to evaluate prompt variants without relying on live user traffic.
You need to create a controlled evaluation of input data.
Which action should you perform first?
Answer: B
Explanation:
The team cannot rely on live user traffic for evaluation because it would make results non-reproducible and could expose users to untested prompts. Synthetic data generation within Microsoft Foundry allows the team to produce diverse, representative input examples that simulate real user queries without any live traffic risk, giving a stable, consistent test set evaluated under identical conditions. Option B (content filters) and Option C (blocklists) are safety controls applied at inference time, not evaluation inputs. Option D (observability metrics) is a monitoring capability for production systems. With synthetic data, the team can construct edge cases, varied phrasings, and domain-specific scenarios that would take months to accumulate organically from real users, directly enabling the controlled evaluation the question requires without any dependency on live traffic.
Microsoft Learn Reference Topic: Evaluate generative AI apps with synthetic data - Microsoft Foundry prompt evaluation
NEW QUESTION # 177
You have a deployment of an Azure OpenAI Service base model.
You plan to fine-tune the model.
You need to prepare a file that contains training data for multi-turn chat.
Which file encoding method should you use?
Answer: B
Explanation:
For preparing a multi-turn training data file for the Azure OpenAI Service, you should use UTF-8 with a Byte Order Mark (BOM) encoding.
File Format Requirements
Format: The file must be in JSON Lines (JSONL) format, where each individual line is a valid JSON object representing one training example.
Encoding: Specifically, Azure OpenAI requires the JSONL file to be encoded in UTF-8 with BOM.
Structure: For multi-turn conversations, each line must contain a messages array with multiple role ("system", "user", "assistant") and content pairs to represent the dialogue history.
Reference:
https://dev.to/icebeam7/fine-tuning-a-model-with-azure-open-ai-studio-39p7
NEW QUESTION # 178
......
Our AI-300 exam questions are totally revised and updated according to the changes in the syllabus and the latest developments in theory and practice. We carefully prepare the AI-300 test guide for the purpose of providing high-quality products. All the revision and updating of products can graduate the accurate information about the AI-300 Guide Torrent you will get, let the large majority of student be easy to master and simplify the content of important information. Our product AI-300 test guide delivers more important information with fewer questions and answers.
Reliable AI-300 Dumps Ebook: https://www.itexamguide.com/AI-300_braindumps.html
BTW, DOWNLOAD part of Itexamguide AI-300 dumps from Cloud Storage: https://drive.google.com/open?id=1X7fUWzHOqgVtu--GsPF7mluzaT0xy9HV