我々の商品の質量を保証するために、専門家たちは商品の開発を研修しています。過去の試験のデータを基づいて、AI-200問題集を開発しています。現在でも、問題集の更新に働いています。複数の更新を通して、今の的中率高いAI-200問題集になりました。我々のAI-200問題集で試験に合格することができると信じています。
| Section | Objectives |
|---|---|
| Topic 1: Implement and monitor AI workloads | - Deploy AI models and services - Monitor performance and troubleshoot issues |
| Topic 2: Implement Azure AI solutions | - Implement generative AI solutions using Azure OpenAI - Implement natural language processing solutions - Implement knowledge mining with Azure AI Search - Implement computer vision solutions |
| Topic 3: Plan and manage Azure AI solutions | - Monitor and optimize AI solutions - Select appropriate Azure AI services - Plan security and compliance requirements |
あなたは進歩を遂げたいですか。あなたはどのようにして勉強するのかわかりますか。この時、おそらく私たちのAI-200試験準備資料の助けが必要でしょう。私たちのAI-200試験準備資料を使用している人の99%がすでに望む証明書を持っていました。私たちのAI-200試験準備資料を買う限り、あなたも成功できます!
質問 # 30
An AI application uses a database. The database credential rotates every 30 days.
The application currently requires a manual update each time the credential rotates.
You need to ensure that the application always uses the latest secret version without manual updates.
Which two actions should you perform? Each correct answer presents part of the solution. Choose two.
NOTE: Each correct selection is worth one point.
正解:A、D
質問 # 31
Drag and Drop Question
You have an existing AKS cluster and a container image stored in Azure Container Registry.
You must deploy a new version without interrupting traffic.
You need to perform a rolling update by using a manifest file.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.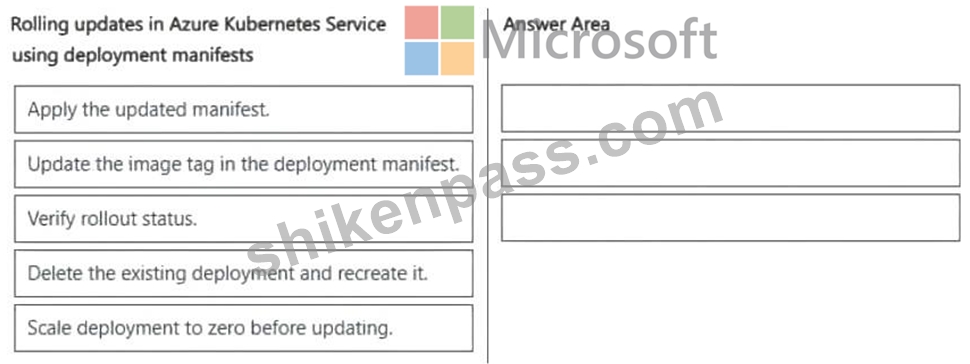
正解:
解説: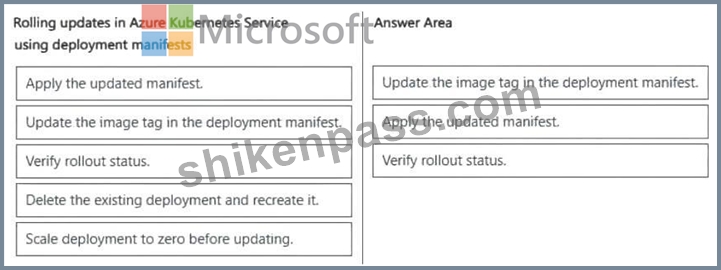
Explanation:
Step 1: Update the image tag in the deployment manifest
This changes the definition file to point to your new version image stored in the Azure Container Registry.
Step 2: Apply the updated manifest
Running kubectl apply -f <manifest.yaml> triggers Kubernetes to natively initiate a zero-downtime rolling update strategy, incrementally replacing old pods with new ones.
Step 3: Verify rollout status
Running kubectl rollout status deployment/<deployment-name> allows you to track and ensure the new version deploys successfully without failure.
Reference:
https://learn.microsoft.com/en-us/azure/aks/tutorial-kubernetes-deploy-application
質問 # 32
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure.
The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security.
The solution must meet strict performance, scalability, and security requirements.
Current environment
Application architecture
The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
Semantic retrieval uses metadata filtering combined with vector similarity search.
Azure Managed Redis is used as a caching layer.
Front-end and API workloads are deployed to Azure Container Apps (ACA).
Batch model retraining workloads run in Azure Kubernetes Service (AKS).
Container and CI/CD
Container images are stored in Azure Container Registry (ACR).
CI/CD uses ACR Tasks to build images on commit.
ACA environments support revision management.
AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring
Logs are collected in Azure Monitor.
Teams inspect container logs and Kubernetes events when troubleshooting.
Developers write KQL queries to analyze latency spikes.
Business requirements
Customer experience: Maintain a seamless, low-latency recommendation experience for end- users, even during unpredictable seasonal traffic spikes.
Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs.
Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction.
Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets.
Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers.
Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization.
Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates.
Identity: Use managed identities for all service-to-service and service-to-database authentication.
Plain-text credentials in configuration files are strictly prohibited.
Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy.
Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero.
CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
Hotspot Question
You need to deploy a batch retraining workload.
How should you complete the scaling configuration? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.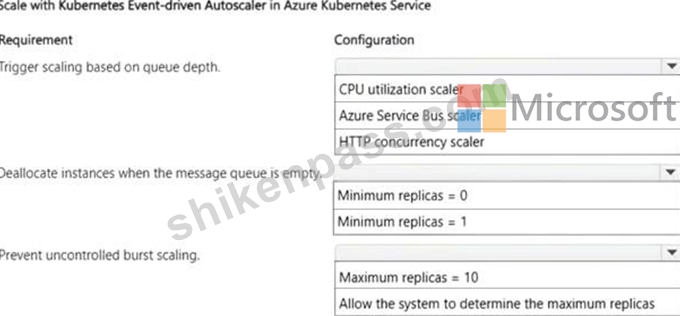
正解:
解説: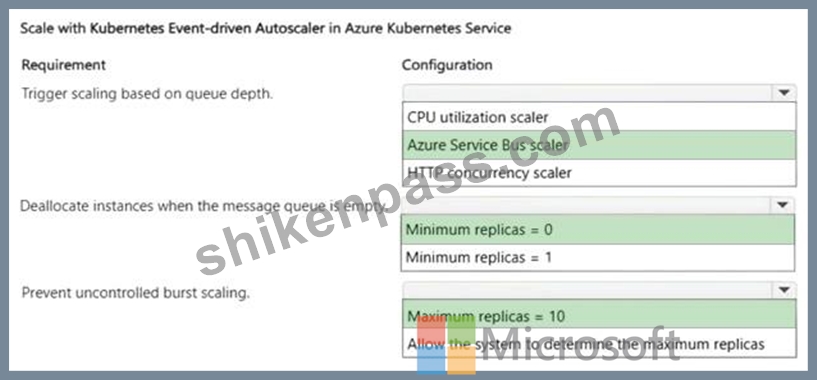
Explanation:
Box 1: Azure Service Bus scaler
An Azure Service Bus scaler needs to be set up to meet this requirement.
Queue-Depth Metrics: To trigger scaling based strictly on queue depth, the orchestration layer (such as Azure Container Apps or AKS using KEDA) requires a scaler that can natively communicate with the message broker and monitor metrics like active message count.
Scale-to-Zero Support: Unlike standard resource scalers, an Azure Service Bus scaler enables event-driven batch workloads to spin up consumers when messages arrive and scale all the way down to zero instances when the queue is completely empty.
Box 2: Minimum replicas = 0.
You need to set Minimum replicas = 0.
Setting the minimum replicas to 0 enables the system to scale down to zero instances when there are no messages left in the queue, completely deallocating resources and eliminating idle compute costs.
Box 3: Maximum replicas = 10
To prevent uncontrolled burst scaling during your batch retraining workloads, you need to set maximum replicas = 10.
Enforcing Upper Bounds: Allowing the system to determine the maximum replica gives the underlying autoscaler (such as KEDA or the Horizontal Pod Autoscaler in Azure Kubernetes Service) the freedom to scale out infinitely or up to large default platform limits. This directly risks uncontrolled burst scaling when a massive batch queue is processed.
Resource and Cost Protection: Hard-coding a ceiling (like maximum replicas = 10) ensures that the batch workload cannot consume more cluster resources than allocated, preventing resource starvation for customer-facing recommendation APIs and keeping operational costs predictable.
Reference:
https://azure.github.io/aca-dotnet-workshop/aca/09-aca-autoscale-keda/
https://kserve.github.io/website/docs/reference/crd-api
質問 # 33
Hotspot Question
You plan to develop an Azure Functions app with an HTTP trigger.
The app must support the following functionality:
- Event-driven scaling
- Ability to use custom Linux images for function execution
You need to identify the app's hosting plan and the maximum amount of time that the app function can take to respond to incoming requests.
Which configuration setting values should you use? To answer, select the appropriate values in the answer area.
NOTE: Each correct selection is worth one point.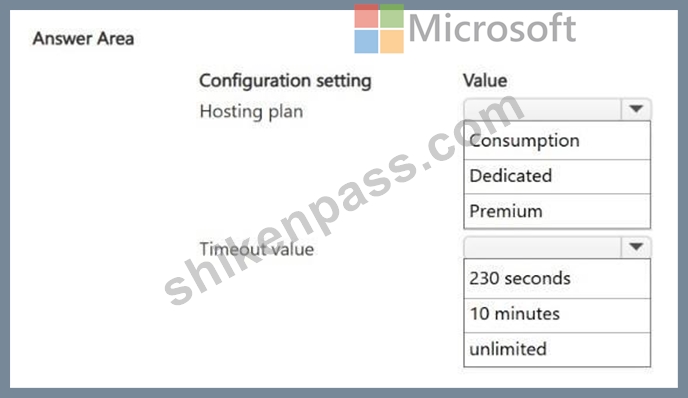
正解:
解説: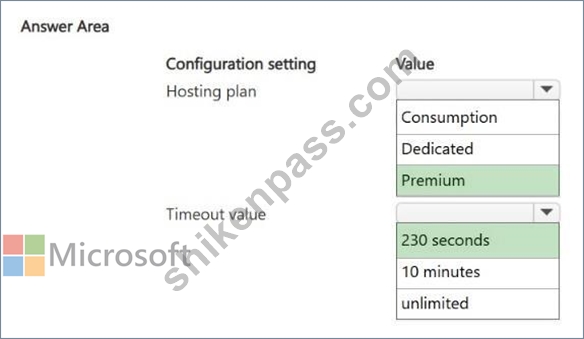
Explanation:
Box 1: Premium
To fulfill your requirements, you should use the Azure Functions Premium plan (also known as the Elastic Premium plan).
Event-Driven Scaling: It features dynamic, automatic scale-out driven by the Azure scale controller. It can scale down to zero instances when idle, ensuring you only pay for active compute time.
Custom Linux Images: Unlike the base Consumption plan, the Premium plan allows you to deploy and run your functions inside a custom Linux container image. This lets you bring your own custom OS dependencies, specialized tools, or specific runtime environments.
Box 2: 230 seconds
The correct maximum timeout value to use for an HTTP-triggered function is 230 seconds.
Azure Load Balancer Limit: Regardless of the specific Azure Functions hosting plan or timeout configurations you set in host.json, the Azure Functions Scale and Hosting documentation states that an HTTP-triggered function has a hard limit of 230 seconds to respond to a request.
Idle Timeout: This constraint is strictly enforced due to the default idle timeout of the underlying Azure Load Balancer. If your function runs longer than 230 seconds without returning a response, the connection will be dropped, resulting in a timeout error.
Reference:
https://learn.microsoft.com/en-us/azure/azure-functions/functions-deployment-technologies
https://learn.microsoft.com/en-us/azure/azure-functions/functions-scale
質問 # 34
Drag and Drop Question
You are investigating high latency in an AI search application that processes millions of requests daily. Telemetry is stored in Azure Monitor Logs.
You must create a KQL query that correlates information from the AppRequests table and the AppDependencies table. The query must meet the following requirements:
- Include only data from the last 24 hours.
- Filter for failed requests only.
- Calculate the average duration of dependencies, grouped by operation.
The query must be optimized for performance by minimizing the initial data scan.
You need to create the query.
Which five actions should you perform in sequence? To answer, move all actions from the list of actions to the answer area and arrange them in the correct order.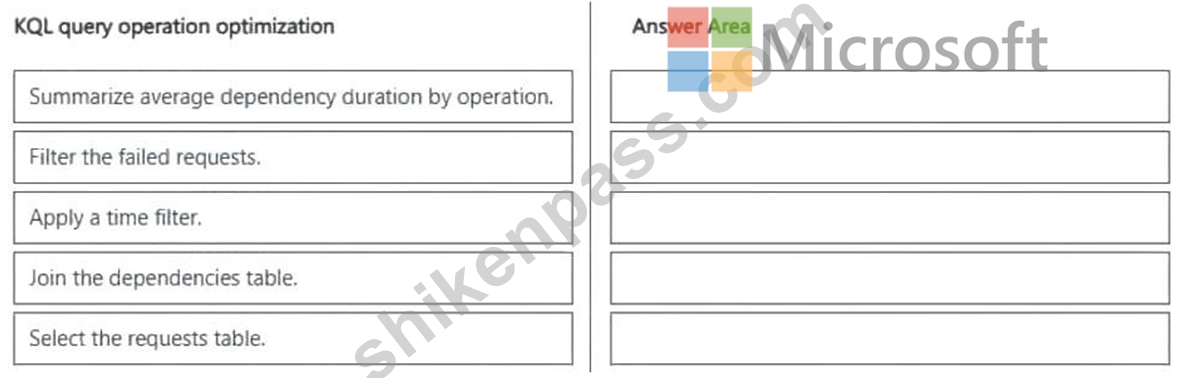
正解:
解説: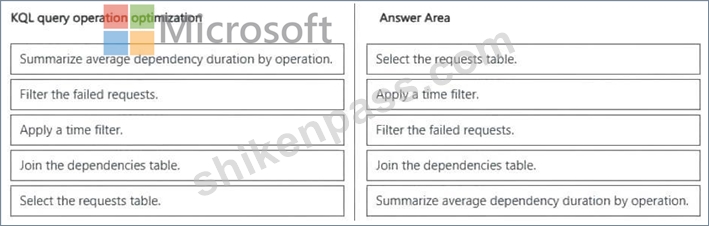
Explanation:
Step 1: Select the requests table
Starts the query stream with the primary base table.
Step 2: Apply a time filter
Such as (where timestamp >= ago(1d))
Restricts the dataset to the last 24 hours immediately to optimize performance by reducing the scan size.
Step 3: Filter the failed requests
where success == false or resultCode checks
Narrows down rows to only failures before performing resource-heavy operations.
Step 4: Join the dependencies table
(join AppDependencies): Correlates the filtered request subset with dependency data using common tracking identifiers.
Step 5: Summarize average dependency duration by operation (summarize avg(duration) by operation) Computes the final aggregated metrics grouped by the operation name.
Reference:
https://learn.microsoft.com/en-us/azure/azure-monitor/logs/get-started-queries
質問 # 35
......
ITテストと認定は当面の競争が激しい世界でこれまで以上に重要になりました。それは異なる世界の未来を意味しています。MicrosoftのAI-200「Developing AI Cloud Solutions on Azure」の試験はあなたの職場生涯で重要な画期的な出来事になり、新しいチャンスを発見するかもしれません。ところが、MicrosoftのAI-200の試験にどうやって合格しますか。心配することはないですよ、ヘルプがあなたの手元にありますから。ShikenPASSを利用したら恐いことはないです。ShikenPASSのMicrosoftのAI-200「Developing AI Cloud Solutions on Azure」の試験問題と解答は試験準備のパイオニアですから。
AI-200トレーリングサンプル: https://www.shikenpass.com/AI-200-shiken.html