High-quality Snowflake Exam SPS-C01 Introduction - SPS-C01 Free Download
As a market leader, our company is able to attract quality staffs, it actively seeks out those who are energetic, persistent, and professional to various SPS-C01 certificate and good communicator. And we strongly believe that the key of our company's success is its people, skills, knowledge and experience. Over 50% of the account executives and directors have been with the Group for more than ten years. The successful selection, development and SPS-C01 training of personnel are critical to our company's ability to provide a high pass rate of SPS-C01 exam questions for you to pass the SPS-C01 exam.
| Section | Weight | Objectives |
|---|
| Topic 1: Snowpark API and Development | 30% | - Multi-language support
- 1. Java and Scala API basics
- 2. Environment setup and dependencies
- Python API fundamentals
- 1. DataFrame creation from tables, views, SQL
- 2. Column operations and functions
- 3. Data persistence and writing results
|
| Topic 2: Snowpark Concepts and Architecture | 25% | - Session management and connection
- 1. Authentication and connection settings
- 2. Create and configure Snowpark sessions
- Snowpark architecture and execution model
- 1. Lazy evaluation and DAG execution
- 2. Client-side vs server-side processing
- 3. Transformations vs actions
|
| Topic 3: Performance and Best Practices | 10% | - Security and governance
- 1. Data protection and compliance
- 2. Access control and permissions
- Optimization techniques
- 1. Query pushdown and execution plans
- 2. Caching and warehouse sizing
- 3. Minimizing data movement
|
| Topic 4: Data Transformations and Operations | 35% | - DataFrame manipulation
- 1. Filtering, sorting, grouping, aggregation
- 2. Joins, unions, set operations
- 3. Selection, projection, renaming, casting
- Advanced operations
- 1. Window functions and analytics
- 2. Pivot and unpivot transformations
- 3. Semi-structured data processing
- User-defined logic
- 1. UDFs, UDAFs, UDTFs
- 2. Stored procedures with Snowpark
|
>> Exam SPS-C01 Introduction <<
Latest SPS-C01 Test Question - Pass4sure SPS-C01 Pass Guide
You can conveniently test your performance by checking your score each time you use our Snowflake SPS-C01 practice exam software (desktop and web-based). It is heartening to announce that all TestSimulate users will be allowed to capitalize on a free Snowflake SPS-C01 Exam Questions demo of all three formats of Snowflake SPS-C01 practice test.
Snowflake Certified SnowPro Specialty - Snowpark Sample Questions (Q82-Q87):
NEW QUESTION # 82
A Snowpark application needs to process large volumes of sensor data stored in a Snowflake table named , which includes columns , 'timestamp' , and The application must calculate a rolling average of for each over a 5-minute window. The data is not perfectly ordered by 'timestamp' within each 'sensor_id'. What is the MOST efficient and accurate way to implement this rolling average calculation using Snowpark?
- A. Using a Window specification with 'orderBy('timestamp')' and 'rowsBetween(Window.unboundedPreceding, Window.currentRow)' in conjunction with and a UDF to manually calculate the rolling average within each group.
- B. Using after applying a filter to select only the data within the 5-minute window, updating the filter for each new window.
- C. Using a Window specification with 'orderBy('timestamp')' and 'rowsBetween(Window.unboundedPreceding, Window.currentRow)' to calculate the cumulative average, then subtracting the average from 5 minutes ago. The query will then be grouped on the sensor id.
- D. Using a Window specification with 0)' and the 'avg()' window function. (Where 'to_seconds' converts a duration to seconds)
- E. Implementing a Python UDTF (User-Defined Table Function) that iterates through the data for each calculates the rolling average manually, and emits the results as rows.
Answer: D
Explanation:
Option D is the most efficient and accurate. 'partitionBy('sensor_id')' ensures that the rolling average is calculated separately for each sensor. 'orderBy('timestamp'Y orders the data within each partition by timestamp. 0)' defines the 5- minute window relative to the current row, accurately capturing all readings within that window even if they are slightly out of order. 'avg(Y then efficiently calculates the average within that window. Other options are either less efficient (e.g., UDTF iteration) or less accurate (e.g., incorrect window definitions, filtering).
NEW QUESTION # 83
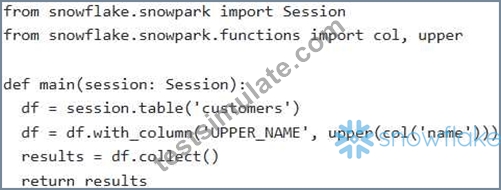
Consider the following Snowpark Python code snippet:
- A. The function will retrieve all rows from the 'customers' table and store them in a local Pandas DataFrame before applying the function.
- B. This code requires a configured Anaconda environment to run successfully.
- C. The code demonstrates the Snowpark architecture, where transformations are translated into SQL and executed in Snowflake's engine. Only the final 'collect()' brings the results back to the client.
- D.
- E. The 'upper()' function will be executed on the client-side (where the Python code is running) for each row in the 'customers' table.
Answer: C,D
Explanation:
Options A and D are correct. Snowpark leverages Snowflake's compute resources by translating DataFrame operations (like 'with_column' and 'upper') into SQL that is executed within the data warehouse. Only the 'collect()' action materializes the results and brings them back to the client. B is wrong because the upper function executes on the server side and is translated into SQL. C is wrong because collect happens at the end after 'upper' is calculated in Snowflake. E is incorrect as the core Snowpark functionality does not require a full Anaconda environment setup - dependencies can be configured otherwise.
NEW QUESTION # 84
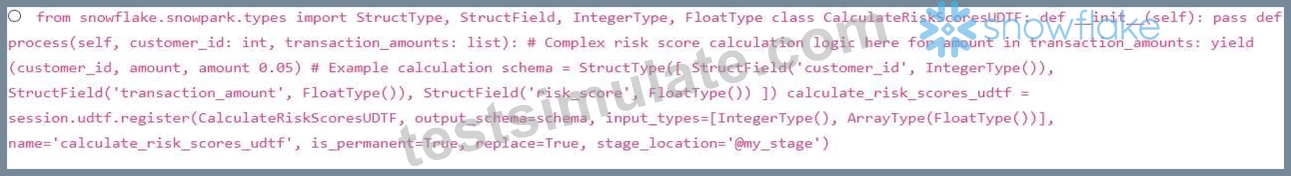
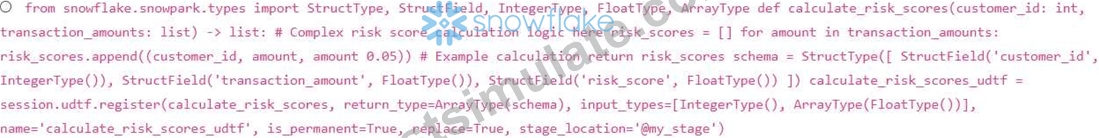
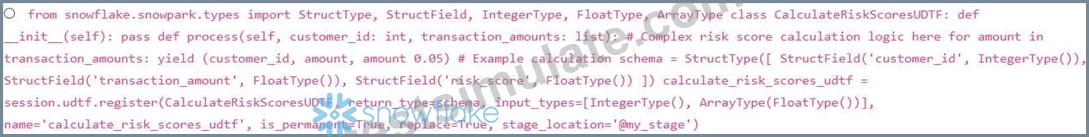
You have developed a Python function that performs complex data transformation on customer data'. You want to operationalize this function as a UDTF in Snowpark to process large datasets efficiently. The function takes a customer ID and a list of transaction amounts as input and returns a table with calculated risk scores for each transaction. Which of the following code snippets correctly defines and registers this UDTF in Snowpark, ensuring proper type handling and scalability?
- A.
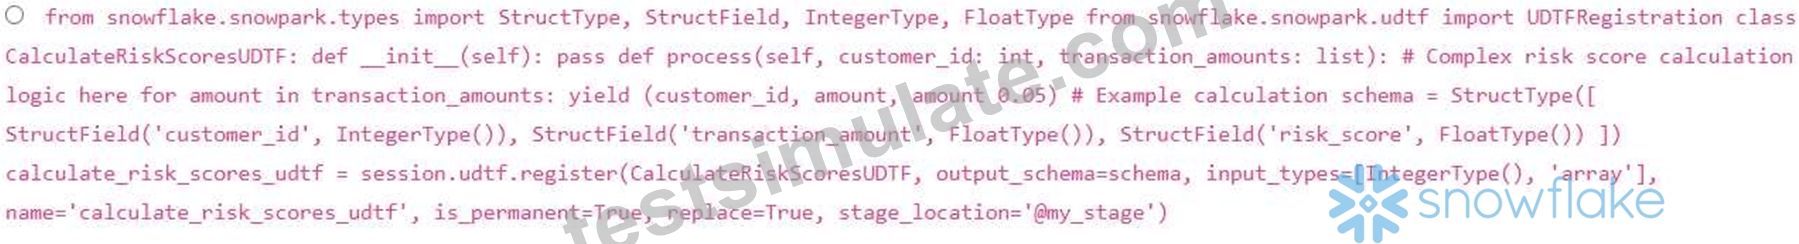
- B. Options B and C are the most correct.
- C.
- D.
- E.
Answer: B
Explanation:
Options B and C correctly defines the UDTF.Option B uses return_type and option C uses output_schema, both work. Option A is incorrect because a UDTF needs to be defined as a class with a 'process' method that yields rows, not as a function that returns a list. Option D uses an incorrect way to specify ArrayType ('array') . The other options are either syntactically incorrect or do not follow the correct UDTF definition pattern.
NEW QUESTION # 85
You are building a Snowpark application that processes a large number of PDF files stored in a Snowflake stage. You need to extract text from each PDF file using a Python UDF and store the extracted text in a Snowflake table. You are considering different approaches for loading the PDF files into the UDE Which of the following approaches would provide the BEST performance and scalability, while minimizing network traffic and memory usage?
- A. Use the 'GET_OBJECT Snowflake SQL command to retrieve each file's contents and then pass the results as arguments into the UDF for processing. This allows use of pure SQL statements to access the files.
- B. Use the 'snowflake.snowpark.functions.read' function in Python to read the PDF files directly from the stage within the UDF. This loads the file contents into a variable available for processing.
- C. Pass the file path of each PDF file in the Snowflake stage to the UDF as a string. Within the UDF, use the 'snowflake.snowpark.files.SnowflakeFile' class to open and read the file. This will allow efficient access to the file directly from the stage.
- D. Load the PDF files into a pandas DataFrame within the Snowpark application, then pass the DataFrame to the UDF. This way the PDF can be available to all workers in the dataframe.
- E. Download all PDF files from the Snowflake stage to a local directory on the machine running the Snowpark application, then load the files from the local directory into the UDF.
Answer: C
Explanation:
Option C is the most efficient approach. 'snowflake.snowpark.files.SnowflakeFile' allows the UDF to directly access the PDF files stored in the Snowflake stage without transferring the entire file to the client. This minimizes network traffic and memory usage. Option A requires loading all PDF files into a pandas DataFrame, which can consume a significant amount of memory. Option B has issues relating to the file size and content restrictions and isn't suitable for many files. Option D involves downloading all files to a local directory, which is not scalable and introduces unnecessary overhead. Option E using 'GET OBJECT is outside the scope of the python api.
NEW QUESTION # 86
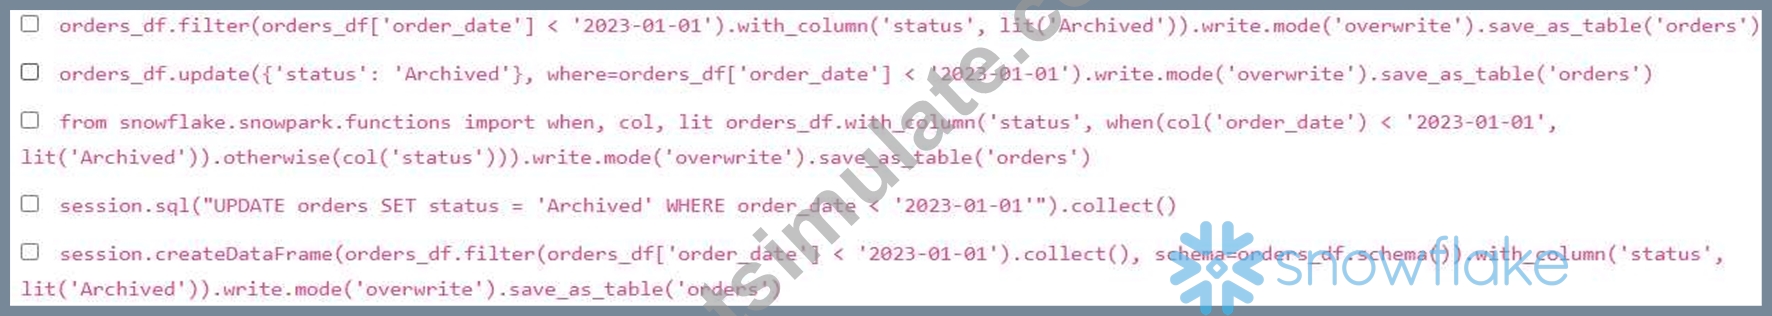
Consider a Snowflake table 'orders' with columns 'order_id', 'customer_id', 'order_date', and 'status'. You need to update the 'status' of all orders placed before January 1, 2023, to 'Archived'. Which of the following approaches is the most efficient and idiomatic way to achieve this using Snowpark DataFrames, assuming 'orders df DataFrame represents the 'orders' table?
- A. Option D
- B. Option A
- C. Option C
- D. Option B
- E. Option E
Answer: A,C
Explanation:
Options C and D are both valid and efficient solutions. Option C leverages Snowpark's 'with_column' and 'when' functions to conditionally update the 'status' column within the DataFrame and persists the changes back to the table using 'save_as_table'. Using lit function makes sure that 'Archived' status is passed as a literal. Option D uses a direct SQL update statement executed through the Snowpark session. This bypasses DataFrame operations but directly modifies the table, which can sometimes be more efficient for simple update operations. Option A is almost correct but the with_column and filter are applied separately. Option B doesn't work due to the way update functions are implemented in Snowpark. Option E unnecessarily collects the filtered data back to the driver, creating a new DataFrame from the collected data, then applying 'with_column'. This is an inefficient approach.
NEW QUESTION # 87
......
TestSimulate ensures your success with money back assurance. There is no chance of losing the exam if you rely on TestSimulate’s SPS-C01 Study Guides and dumps. If you do not get through the exam, you take back your money. The money offer is the best evidence on the remarkable content of TestSimulate.
Latest SPS-C01 Test Question: https://www.testsimulate.com/SPS-C01-study-materials.html
- www.troytecdumps.com Provides Snowflake SPS-C01 Exam Questions 2026 🚆 Download ▷ SPS-C01 ◁ for free by simply searching on ( www.troytecdumps.com ) 🤕SPS-C01 Excellect Pass Rate
- Free PDF Quiz Snowflake - SPS-C01 - Snowflake Certified SnowPro Specialty - Snowpark Latest Exam Introduction 🌔 Download [ SPS-C01 ] for free by simply searching on ➠ www.pdfvce.com 🠰 🤹SPS-C01 Reliable Exam Questions
- www.prepawaypdf.com Provides Snowflake SPS-C01 Exam Questions 2026 🌹 Immediately open ⇛ www.prepawaypdf.com ⇚ and search for ✔ SPS-C01 ️✔️ to obtain a free download 🥿Instant SPS-C01 Download
- Pdfvce Provides Snowflake SPS-C01 Exam Questions 2026 🦌 Search for ⇛ SPS-C01 ⇚ and download it for free immediately on ⇛ www.pdfvce.com ⇚ 🤾SPS-C01 Exam Answers
- SPS-C01 Exams 📱 SPS-C01 Excellect Pass Rate 🚼 Exam SPS-C01 Details 🦕 The page for free download of [ SPS-C01 ] on ➥ www.examcollectionpass.com 🡄 will open immediately 🛫SPS-C01 Reliable Exam Questions
- Pdfvce Provides Snowflake SPS-C01 Exam Questions 2026 👒 Open website ( www.pdfvce.com ) and search for 「 SPS-C01 」 for free download 🦈Pdf SPS-C01 Pass Leader
- www.examcollectionpass.com Provides Snowflake SPS-C01 Exam Questions 2026 🚾 Open ➤ www.examcollectionpass.com ⮘ and search for 「 SPS-C01 」 to download exam materials for free 🍆Latest SPS-C01 Exam Bootcamp
- Exam SPS-C01 Details 🐲 SPS-C01 Pdf Format 🍋 Exam SPS-C01 Reviews ⏺ Search for ⇛ SPS-C01 ⇚ and obtain a free download on ➡ www.pdfvce.com ️⬅️ 🦕Prep SPS-C01 Guide
- 100% Pass 2026 SPS-C01: High Hit-Rate Exam Snowflake Certified SnowPro Specialty - Snowpark Introduction 🎫 Easily obtain free download of ➠ SPS-C01 🠰 by searching on ▛ www.troytecdumps.com ▟ 🐍Exam SPS-C01 Format
- Pdfvce Provides Snowflake SPS-C01 Exam Questions 2026 ✌ Open website 《 www.pdfvce.com 》 and search for ▛ SPS-C01 ▟ for free download 👱SPS-C01 Authorized Pdf
- SPS-C01 Test Registration 🖱 SPS-C01 Latest Test Sample 🥺 SPS-C01 Pdf Format 😯 Immediately open ➥ www.prepawaypdf.com 🡄 and search for ⮆ SPS-C01 ⮄ to obtain a free download 🕧Pdf SPS-C01 Pass Leader
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.4shared.com, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes