Latest Databricks Certified-Data-Engineer-Professional Study Notes - New Certified-Data-Engineer-Professional Dumps Questions

BONUS!!! Download part of PDF4Test Certified-Data-Engineer-Professional dumps for free: https://drive.google.com/open?id=1DPVDo0ZeMBU74leVbSm_MxUfCcKZlxlU
The advantages of our Certified-Data-Engineer-Professional study materials are plenty and the price is absolutely reasonable. The clients can not only download and try out our products freely before you buy them but also enjoy the free update and online customer service at any time during one day. The clients can use the practice software to test if they have mastered the Certified-Data-Engineer-Professional Study Materials and use the function of stimulating the test to improve their performances in the real test. So our products are absolutely your first choice to prepare for the test Certified-Data-Engineer-Professional certification.
| Section | Weight | Objectives |
|---|
| Topic 1: Data Transformation, Cleansing, and Quality | ~12% | - Apply advanced Spark transformations
- Enforce data quality and quarantine bad data
|
| Topic 2: Cost and Performance Optimization | ~13% | - Leverage system tables and observability tools
- Optimize queries, clusters, and storage
|
| Topic 3: Data Modeling | ~10% | - Apply dimensional modeling techniques
- Design scalable Delta Lake schemas and clustering
|
| Topic 4: CI/CD, Testing, and Deployment | ~6% | - Deploy with Declarative Automation Bundles, CLI, and REST API
- Implement testing and deployment pipelines
|
| Topic 5: Security and Governance | ~10% | - Manage Unity Catalog permissions and ACLs
- Implement row-level security, column masking, and compliance
|
| Topic 6: Streaming Workloads and Change Data Capture | ~11% | - Implement reliable streaming pipelines
- Apply AUTO CDC APIs and exactly-once semantics
|
| Topic 7: Developing Code for Data Processing using Python and SQL | ~22% | - Implement scalable Python/SQL code and project structures
- Manage dependencies, libraries, and UDFs
- Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader
|
| Topic 8: Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation
|
| Topic 9: Monitoring, Logging, and Troubleshooting | ~8% | - Use Spark UI, Query Profiler, and system tables
- Diagnose common pipeline and job failures
|
>> Latest Databricks Certified-Data-Engineer-Professional Study Notes <<
New Certified-Data-Engineer-Professional Dumps Questions | Reliable Certified-Data-Engineer-Professional Test Duration
To stay updated and competitive in the market you have to upgrade your skills and knowledge level. Fortunately, with the Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) certification exam you can do this job easily and quickly. To do this you just need to pass the Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) certification exam. The Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) certification exam is the top-rated and career advancement Databricks Certified-Data-Engineer-Professional certification in the market.
Databricks Certified Data Engineer Professional Sample Questions (Q208-Q213):
NEW QUESTION # 208
An hourly batch job is configured to ingest data files from a cloud object storage container where each batch represent all records produced by the source system in a given hour. The batch job to process these records into the Lakehouse is sufficiently delayed to ensure no late-arriving data is missed. The user_id field represents a unique key for the data, which has the following schema:
user_id BIGINT, username STRING, user_utc STRING, user_region STRING, last_login BIGINT, auto_pay BOOLEAN, last_updated BIGINT New records are all ingested into a table named account_history which maintains a full record of all data in the same schema as the source. The next table in the system is named account_current and is implemented as a Type 1 table representing the most recent value for each unique user_id.
Assuming there are millions of user accounts and tens of thousands of records processed hourly, which implementation can be used to efficiently update the described account_current table as part of each hourly batch job?
- A. Filter records in account history using the last updated field and the most recent hour processed, as well as the max last iogin by user id write a merge statement to update or insert the most recent value for each user id.
- B. Filter records in account history using the last updated field and the most recent hour processed, making sure to deduplicate on username; write a merge statement to update or insert the most recent value for each username.
- C. Overwrite the account current table with each batch using the results of a query against the account history table grouping by user id and filtering for the max value of last updated.
- D. Use Delta Lake version history to get the difference between the latest version of account history and one version prior, then write these records to account current.
- E. Use Auto Loader to subscribe to new files in the account history directory; configure a Structured Streaminq trigger once job to batch update newly detected files into the account current table.
Answer: A
Explanation:
This is the correct answer because it efficiently updates the account current table with only the most recent value for each user id. The code filters records in account history using the last updated field and the most recent hour processed, which means it will only process the latest batch of data. It also filters by the max last login by user id, which means it will only keep the most recent record for each user id within that batch. Then, it writes a merge statement to update or insert the most recent value for each user id into account current, which means it will perform an upsert operation based on the user id column.
NEW QUESTION # 209
When scheduling Structured Streaming jobs for production, which configuration automatically recovers from query failures and keeps costs low?
- A. Cluster: Existing All-Purpose Cluster;
Retries: Unlimited;
Maximum Concurrent Runs: 1 - B. Cluster: New Job Cluster;
Retries: None;
Maximum Concurrent Runs: 1 - C. Cluster: New Job Cluster;
Retries: Unlimited;
Maximum Concurrent Runs: Unlimited - D. Cluster: Existing All-Purpose Cluster;
Retries: Unlimited;
Maximum Concurrent Runs: 1 - E. Cluster: Existing All-Purpose Cluster;
Retries: None;
Maximum Concurrent Runs: 1
Answer: A
Explanation:
The configuration that automatically recovers from query failures and keeps costs low is to use a new job cluster, set retries to unlimited, and set maximum concurrent runs to 1. This configuration has the following advantages:
A new job cluster is a cluster that is created and terminated for each job run. This means that the cluster resources are only used when the job is running, and no idle costs are incurred. This also ensures that the cluster is always in a clean state and has the latest configuration and libraries for the job.
Setting retries to unlimited means that the job will automatically restart the query in case of any failure, such as network issues, node failures, or transient errors. This improves the reliability and availability of the streaming job, and avoids data loss or inconsistency. Setting maximum concurrent runs to 1 means that only one instance of the job can run at a time. This prevents multiple queries from competing for the same resources or writing to the same output location, which can cause performance degradation or data corruption. Therefore, this configuration is the best practice for scheduling Structured Streaming jobs for production, as it ensures that the job is resilient, efficient, and consistent.
NEW QUESTION # 210
A junior data engineer has configured a workload that posts the following JSON to the Databricks REST API endpoint 2.0/jobs/create.
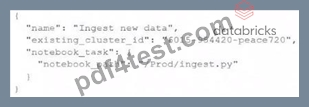
Assuming that all configurations and referenced resources are available, which statement describes the result of executing this workload three times?
- A. The logic defined in the referenced notebook will be executed three times on new clusters with the configurations of the provided cluster ID.
- B. One new job named "Ingest new data" will be defined in the workspace, but it will not be executed.
- C. Three new jobs named "Ingest new data" will be defined in the workspace, and they will each run once daily.
- D. The logic defined in the referenced notebook will be executed three times on the referenced existing all purpose cluster.
- E. Three new jobs named "Ingest new data" will be defined in the workspace, but no jobs will be executed.
Answer: E
Explanation:
Databricks jobs create will create a new job with the same name each time it is run.
In order to overwrite the extsting job you need to run databricks jobs reset
NEW QUESTION # 211
A data team is working to optimize an existing large, fast-growing table 'orders' with high cardinality columns, which experiences significant data skew and requires frequent concurrent writes. The team notice that the columns 'user_id', 'event_timestamp' and 'product_id' are heavily used in analytical queries and filters, although those keys may be subject to change in the future due to different business requirements. Which partitioning strategy should the team choose to optimize the table for immediate data skipping, incremental management over time, and flexibility?
- A. Use z-order after partitiing the table: OPTIMIZE orders ZORDER BY (user_id, product_id) WHERE event_timestamp = current date () - 1 DAY
- B. Partition the table with: ALTER TABLE orders PARTITION BY user_id, product_id, event_timestamp
- C. Z-order the table with OPTIMIZE orders ZORDER BY (user_id, product_id, event_timestamp)
- D. Cluster the table with: ALTER TABLE orders CLUSTER BY user_id, product_id, event_timestamp
Answer: C
Explanation:
Z-ordering optimizes data skipping for selective queries on high-cardinality columns without physically repartitioning the table, making it flexible if query patterns change. Using OPTIMIZE ...
ZORDER BY (user_id, product_id, event_timestamp) improves query performance for filters and joins while allowing incremental writes, avoiding the data skew and maintenance overhead that explicit partitioning or clustering could introduce.
NEW QUESTION # 212
A data engineering team is collaborating on a Databricks project where each team member needs to develop and test code independently before merging changes into the main branch.
They want to avoid accidental overwrites or branch switching issues while ensuring that all work is version- controlled and can be integrated into their CI/CD pipeline.
How should the data engineer achieve collaboration?
- A. Team members use the Databricks CLI to clone the Git repository and perform Git operations from a cluster's web terminal.
- B. Team members edit notebooks directly in the workspace's shared folder and periodically copy changes into a Git folder for version control.
- C. Each team member creates their own Databricks Git folder, mapped to the same remote Git repository, and works in their own development branch within their personal folder.
- D. All team members work in the same Databricks Git folder and perform Git operations (pull, push, commit, branch switching) directly in that shared folder.
Answer: C
Explanation:
Using separate Databricks Git folders per user mapped to the same remote repository allows each team member to work independently on their own branch without interfering with others.
This prevents accidental overwrites or branch conflicts while ensuring all changes are version- controlled and easily integrated into CI/CD workflows.
NEW QUESTION # 213
......
Our Certified-Data-Engineer-Professional valid practice questions are designed by many experts in the field of qualification examination, from the user's point of view, combined with the actual situation of users, designed the most practical Certified-Data-Engineer-Professional learning materials. We believe that no one will spend all their time preparing for Certified-Data-Engineer-Professional Exam, whether you are studying professional knowledge, or all of which have to occupy your time to review the exam. Using the Certified-Data-Engineer-Professional test prep, you will find that you can grasp the knowledge what you need in the exam in a short time.
New Certified-Data-Engineer-Professional Dumps Questions: https://www.pdf4test.com/Certified-Data-Engineer-Professional-dump-torrent.html
- 100% Certified-Data-Engineer-Professional Accuracy 🧞 Latest Certified-Data-Engineer-Professional Exam Question ⚗ Latest Certified-Data-Engineer-Professional Exam Questions 🤸 Enter “ www.verifieddumps.com ” and search for ➡ Certified-Data-Engineer-Professional ️⬅️ to download for free 📼Certified-Data-Engineer-Professional Exam Quiz
- Certified-Data-Engineer-Professional Pdf Free 🚼 Certified-Data-Engineer-Professional Authorized Test Dumps 🕥 New APP Certified-Data-Engineer-Professional Simulations 💅 Simply search for ✔ Certified-Data-Engineer-Professional ️✔️ for free download on ⮆ www.pdfvce.com ⮄ 🚻Certified-Data-Engineer-Professional Test Voucher
- Pass Guaranteed 2026 Certified-Data-Engineer-Professional: Latest Latest Databricks Certified Data Engineer Professional Study Notes 🔔 Search on 《 www.pdfdumps.com 》 for ⇛ Certified-Data-Engineer-Professional ⇚ to obtain exam materials for free download ⬅️Certified-Data-Engineer-Professional Dumps
- Databricks Certified-Data-Engineer-Professional PDF Questions - An Easy Way To Prepare For Exam ☀ Search for ⇛ Certified-Data-Engineer-Professional ⇚ and download it for free on ( www.pdfvce.com ) website 🎳Latest Braindumps Certified-Data-Engineer-Professional Ebook
- Pass Guaranteed Quiz Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional –Professional Latest Study Notes 📫 Open ▛ www.torrentvce.com ▟ enter ⇛ Certified-Data-Engineer-Professional ⇚ and obtain a free download 🦽Certified-Data-Engineer-Professional Reliable Exam Online
- Top Latest Certified-Data-Engineer-Professional Study Notes - Leader in Qualification Exams - Unparalleled Databricks Databricks Certified Data Engineer Professional 🧚 Search for ➽ Certified-Data-Engineer-Professional 🢪 and easily obtain a free download on ▛ www.pdfvce.com ▟ 👭Certified-Data-Engineer-Professional Pdf Free
- Latest Braindumps Certified-Data-Engineer-Professional Ebook 🐳 Latest Braindumps Certified-Data-Engineer-Professional Ebook 🌛 Certified-Data-Engineer-Professional Exam Quiz 🟨 Simply search for “ Certified-Data-Engineer-Professional ” for free download on 「 www.prepawayexam.com 」 🍼Certified-Data-Engineer-Professional Test Voucher
- Pass Guaranteed Quiz Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional –Professional Latest Study Notes 🍋 Download “ Certified-Data-Engineer-Professional ” for free by simply entering 【 www.pdfvce.com 】 website 🧅Certified-Data-Engineer-Professional Pdf Free
- Certified-Data-Engineer-Professional test online - Databricks Certified-Data-Engineer-Professional test dumps insides ⤴ Go to website ➥ www.practicevce.com 🡄 open and search for ☀ Certified-Data-Engineer-Professional ️☀️ to download for free 🚜Test Certified-Data-Engineer-Professional Study Guide
- Latest Certified-Data-Engineer-Professional Exam Price 🕧 New Certified-Data-Engineer-Professional Test Online 🐃 100% Certified-Data-Engineer-Professional Accuracy 🤡 Search for ⏩ Certified-Data-Engineer-Professional ⏪ and download it for free immediately on “ www.pdfvce.com ” ⛹Latest Certified-Data-Engineer-Professional Exam Question
- Certified-Data-Engineer-Professional test online - Databricks Certified-Data-Engineer-Professional test dumps insides 🕯 Download “ Certified-Data-Engineer-Professional ” for free by simply searching on ➤ www.examcollectionpass.com ⮘ ➡100% Certified-Data-Engineer-Professional Accuracy
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
P.S. Free & New Certified-Data-Engineer-Professional dumps are available on Google Drive shared by PDF4Test: https://drive.google.com/open?id=1DPVDo0ZeMBU74leVbSm_MxUfCcKZlxlU