実際的なDatabricks-Machine-Learning-Professional試験復習試験-試験の準備方法-素敵なDatabricks-Machine-Learning-Professional参考資料

P.S. CertShikenがGoogle Driveで共有している無料かつ新しいDatabricks-Machine-Learning-Professionalダンプ:https://drive.google.com/open?id=1T8IH-Y0p7eWa2ZZQavsXZaFGYctXKVeH
当社のDatabricks-Machine-Learning-Professionalトレーニング資料は国内外で有名です。主な理由は、コア競争力を持たない他の会社があるためです。市場には多くの複雑な類似製品があります。独自に必要です。他の製品とのDatabricks-Machine-Learning-Professionalテストの質問は、Databricks-Machine-Learning-Professional学習教材を更新する最も中核的な専門家チームがあることです。製品のポイント。
Databricks Databricks-Machine-Learning-Professional 認定試験の出題範囲:
| トピック | 出題範囲 |
|---|
| トピック 1 | - 構造化ストリーミングではデータが順不同で到着する可能性があることを特定する
- モデル サービングがモデルのデプロイメントに 1 つの汎用クラスターをどのように使用するかを特定する
|
| トピック 2 | - ネストされた実行を追跡するための要件を特定する
- MLflow フレーバーと MLflow フレーバーを使用する利点について説明する
|
| トピック 3 | - 他のユースケースのソリューションとしてパフォーマンスの低いデータ ストレージを特定する
- ストリーミング展開で複雑なビジネス ロジックを処理する必要がある理由を説明する
|
| トピック 4 | - HTTP Webhook の使用例と Webhook URL が必要な場所を特定する
- 汎用クラスターよりもジョブ クラスターを使用する利点を特定する
|
| トピック 5 | - pyfunc MLflow フレーバーを使用する利点について説明する
- MLflow を使用してパラメーター、モデル、評価メトリクスを手動でログに記録する
|
| トピック 6 | - 表示された Webhook をトリガーするコード ブロックを特定する
- 基本的な目的とモデル レジストリとのユーザー インタラクションを説明する
|
| トピック 7 | - 事前計算されたバッチ予測をクエリすることのライブ サービングの利点を特定する
- ETL パイプラインの一般的な処理ツールとしての構造化ストリーミングについて説明する
|
| トピック 8 | - 機械学習ワークフローでのフィーチャー ストア テーブルの作成、上書き、マージ、読み取り
- デルタ テーブル履歴の表示と以前のバージョンのデルタ テーブルの読み込み
|
| トピック 9 | - リアルタイム展開の必要性として JIT 機能の値を特定する
- すべての Webhook を一覧表示する方法と Webhook を削除する方法を説明する
|
| トピック 10 | - 更新されたモデルのパフォーマンスがより最近のデータで向上するかどうかをテストする
- 更新されたモデルを再トレーニングしてデプロイすることがドリフトの解決策となる可能性がある時期を特定する
|
| トピック 11 | - 各段階のモデル サービングのデプロイとエンドポイントを説明する
- 機能ドリフトやラベル ドリフトが発生する可能性があるシナリオを特定する
|
>> Databricks-Machine-Learning-Professional試験復習 <<
Databricks-Machine-Learning-Professional参考資料、Databricks-Machine-Learning-Professional合格率書籍
お客様の暇が少ないので、勉強する時間が少ないことを考えています。Databricks-Machine-Learning-Professional試験資料は便利で、覚えやすいです。また、もう一つの特徴は時間を節約することです。つまり、Databricks-Machine-Learning-Professional試験資料を短い時間で勉強すると、Databricks-Machine-Learning-Professional試験を受けることができます。大切なのはDatabricks-Machine-Learning-Professional試験資料の的中率が高いです。
Databricks Certified Machine Learning Professional 認定 Databricks-Machine-Learning-Professional 試験問題 (Q34-Q39):
質問 # 34
A machine learning engineer wants to delete an active MLflow Model Registry Webhook with webhook ID webhook_id for a specific model.
They are using the following code block:
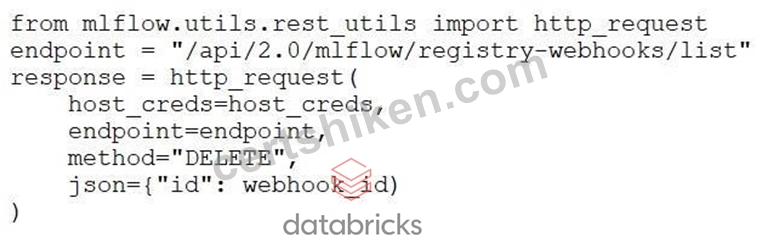
Which change does the machine learning engineer need to make to this code block so it will successfully accomplish the task?
- A. Replace list with delete in the endpoint URL
- B. Replace DELETE with POST in the call to http_request
- C. There are no necessary changes
- D. Replace list with webhooks in the endpoint URL
正解:A
解説:
To delete a webhook using the MLflow REST API, the correct endpoint is:
/api/2.0/mlflow/registry-webhooks/delete
In the provided code, the endpoint incorrectly uses "list", which retrieves webhooks rather than deleting them. The HTTP method "DELETE" is correct, so the only necessary change is to replace list with delete in the endpoint URL.
質問 # 35
Which of the following machine learning model deployment paradigms is the most common for machine learning projects?
- A. None of these deployments
- B. On-device
- C. Batch
- D. Streaming
- E. Real-time
正解:D
質問 # 36
A Machine Learning Engineer needs a continuous deployment pipeline for their models hosted on Databricks Model Serving. The deployment automation should execute after a model is trained and registered using MLflow. The goal of the automation is to deploy the latest version of the model from the MLflow Model Registry only if the model can meet the company's strict latency requirements (P95 < 300ms) while serving production traffic. How can the engineer validate that new models meet their latency requirements when served in production?
- A. Serve the latest model on Databricks Model Serving and use a load testing client to generate requests at the production request rate. Use the load testing client to calculate P95 latency and verify it is less than 300ms.
- B. A/B test the latest model with Databricks Model Serving so that the latest model receives 5% of production traffic and the current model receives the rest. Use inference tables to calculate P95 latency and verify it is less than 300ms.
- C. Use the MLflow Get Run API to retrieve the model metrics from MLflow Tracking and verify that the model_latency metric is less than 300ms.
- D. Use the MLflow Get Run API to retrieve the model metrics from MLflow Tracking and verify that the inference_latency metric is less than 300ms.
正解:B
解説:
Validating latency requirements must be done under real production serving conditions. Routing a small percentage of live production traffic to the new model using Databricks Model Serving allows accurate measurement of end-to-end serving latency. Inference tables capture request latency metrics, enabling calculation of the P95 latency and ensuring it meets the strict production threshold before full rollout.
質問 # 37
A machine learning engineer is using the following code block as part of a batch deployment pipeline:
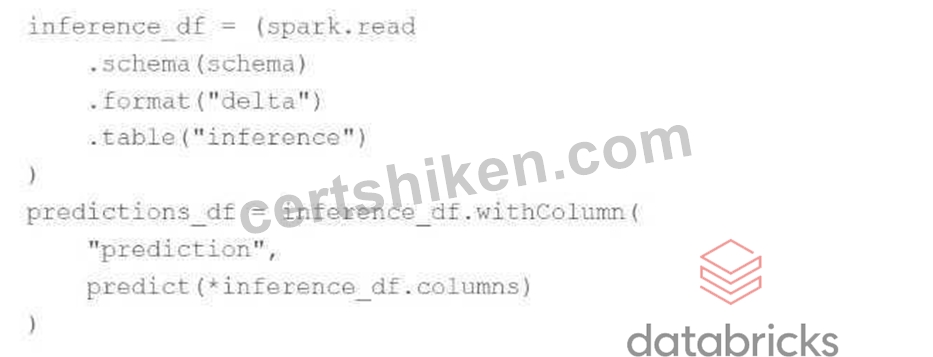
Which of the following changes needs to be made so this code block will work when the inference table is a stream source?
- A. Replace formatfdelta") with format("stream")
- B. Replace "inference" with the path to the location of the Delta table
- C. Replace predict with a stream-friendly prediction function
- D. Replace spark.read with spark.readStream
- E. Replace schema(schema) with option("maxFilesPerTriqqer", 1}
正解:E
質問 # 38
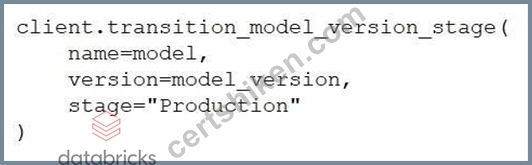
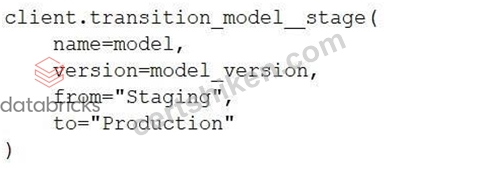
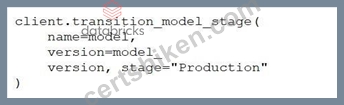
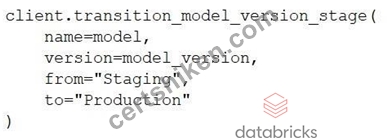
A machine learning engineer wants to move their model version model_version for the MLflow Model Registry model model from the Staging stage to the Production stage using MLflow Client client. Which code block can they use to accomplish the task?
正解:A
解説:
The correct method for transitioning a model version to a new stage using the MLflow Client is client.transition_model_version_stage(name, version, stage). This updates the stage of a specific model version in the Model Registry, such as moving it from "Staging" to "Production". The stage parameter specifies the target stage only -- there is no from argument.
質問 # 39
......
CertShiken を選択して100%のDatabricks-Machine-Learning-Professional合格率を確保することができて、もしDatabricks-Machine-Learning-Professional試験に失敗したら、CertShikenが全額で返金いたします。
Databricks-Machine-Learning-Professional参考資料: https://www.certshiken.com/Databricks-Machine-Learning-Professional-shiken.html
- 試験の準備方法-認定するDatabricks-Machine-Learning-Professional試験復習試験-正確的なDatabricks-Machine-Learning-Professional参考資料 🥫 ➤ Databricks-Machine-Learning-Professional ⮘の試験問題は☀ www.mogiexam.com ️☀️で無料配信中Databricks-Machine-Learning-Professional参考資料
- Databricks-Machine-Learning-Professional再テスト 🦗 Databricks-Machine-Learning-Professional再テスト 🏸 Databricks-Machine-Learning-Professional模擬対策 🥘 ➡ www.goshiken.com ️⬅️にて限定無料の「 Databricks-Machine-Learning-Professional 」問題集をダウンロードせよDatabricks-Machine-Learning-Professional認証資格
- Databricks-Machine-Learning-Professional的中率 🕒 Databricks-Machine-Learning-Professional問題集無料 🅾 Databricks-Machine-Learning-Professional的中率 👫 ⮆ Databricks-Machine-Learning-Professional ⮄を無料でダウンロード( www.topexam.jp )で検索するだけDatabricks-Machine-Learning-Professional認証資格
- Databricks-Machine-Learning-Professional関連復習問題集 🥚 Databricks-Machine-Learning-Professional関連日本語内容 👮 Databricks-Machine-Learning-Professional対策学習 Ⓜ 【 www.goshiken.com 】サイトにて➤ Databricks-Machine-Learning-Professional ⮘問題集を無料で使おうDatabricks-Machine-Learning-Professional認証資格
- 高品質なDatabricks-Machine-Learning-Professional試験復習一回合格-完璧なDatabricks-Machine-Learning-Professional参考資料 🍋 { www.xhs1991.com }を入力して✔ Databricks-Machine-Learning-Professional ️✔️を検索し、無料でダウンロードしてくださいDatabricks-Machine-Learning-Professional合格記
- 有効的なDatabricks-Machine-Learning-Professional試験復習 - 合格スムーズDatabricks-Machine-Learning-Professional参考資料 | 高品質なDatabricks-Machine-Learning-Professional合格率書籍 🍶 今すぐ{ www.goshiken.com }で{ Databricks-Machine-Learning-Professional }を検索して、無料でダウンロードしてくださいDatabricks-Machine-Learning-Professional関連復習問題集
- Databricks Databricks-Machine-Learning-Professional Exam | Databricks-Machine-Learning-Professional試験復習 - あなたのDatabricks-Machine-Learning-Professional試験の合格的なプロバイダー 🛅 最新➡ Databricks-Machine-Learning-Professional ️⬅️問題集ファイルは✔ www.goshiken.com ️✔️にて検索Databricks-Machine-Learning-Professional認証資格
- Databricks-Machine-Learning-Professional関連日本語内容 🛅 Databricks-Machine-Learning-Professional日本語試験対策 🧊 Databricks-Machine-Learning-Professional認証資格 📹 [ www.goshiken.com ]サイトにて最新☀ Databricks-Machine-Learning-Professional ️☀️問題集をダウンロードDatabricks-Machine-Learning-Professional参考資料
- 試験の準備方法-認定するDatabricks-Machine-Learning-Professional試験復習試験-正確的なDatabricks-Machine-Learning-Professional参考資料 🧲 今すぐ▛ www.passtest.jp ▟で{ Databricks-Machine-Learning-Professional }を検索して、無料でダウンロードしてくださいDatabricks-Machine-Learning-Professional教育資料
- Databricks-Machine-Learning-Professional試験復習からDatabricks Certified Machine Learning Professionalまで, 便利に合格する 🚕 検索するだけで▛ www.goshiken.com ▟から➠ Databricks-Machine-Learning-Professional 🠰を無料でダウンロードDatabricks-Machine-Learning-Professional模擬対策
- 高品質なDatabricks-Machine-Learning-Professional試験復習一回合格-完璧なDatabricks-Machine-Learning-Professional参考資料 🦃 ⇛ www.shikenpass.com ⇚を開いて✔ Databricks-Machine-Learning-Professional ️✔️を検索し、試験資料を無料でダウンロードしてくださいDatabricks-Machine-Learning-Professional問題集無料
- www.flirtic.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
さらに、CertShiken Databricks-Machine-Learning-Professionalダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1T8IH-Y0p7eWa2ZZQavsXZaFGYctXKVeH