Do you feel Anthropic CCAR-P exam preparation is tough? TestPassKing desktop and web-based online Anthropic CCAR-P practice test software will give you a clear idea about the final CCAR-P Test Pattern. Practicing with the Anthropic CCAR-P practice test, you can evaluate your Anthropic CCAR-P exam preparation.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Developer Productivity & Operational Enablement | 7% | - AI-assisted developer workflows - Claude tooling configuration for teams - Developer enablement - Debugging and operational issue resolution |
| Topic 2: Stakeholder Communication & Lifecycle Management | 14% | - Stakeholder management - Communicating architectural decisions - Service-level agreements - Architecture documentation - Discovery and requirements gathering - Solution lifecycle management |
| Topic 3: Governance, Safety & Risk Management | 14% | - Security and risk management - Regulatory and compliance requirements - AI safety and guardrails - Ethical AI considerations - Human-in-the-loop validation |
| Topic 4: Claude Models, Prompting & Context Engineering | 13% | - System prompts and prompt templates - Claude model selection and trade-offs - Prompt reuse and context engineering strategies - Guardrails - Context window optimization |
| Topic 5: Integration | 19% | - Authentication and authorization analysis - Enterprise system integration - Claude integration mechanisms
|
| Topic 6: Evaluation, Testing & Optimization | 16% | - System issue diagnosis - Evaluation framework design - Evaluation metrics and datasets - Production monitoring and optimization - A/B testing - Cost and performance optimization |
| Topic 7: Solution Design & Architecture | 17% | - Translating business problems into Claude-based AI solutions - Multi-agent systems and orchestration - End-to-end architecture design - Alignment with business value, cost, performance, and SLAs - Architectural patterns
|
The candidates can benefit themselves by using our CCAR-P test engine and get a lot of test questions like exercises and answers. Our CCAR-P exam questions will help them modify the entire syllabus in a short time. And the Software version of our CCAR-P Study Materials have the advantage of simulating the real exam, so that the candidates have more experience of the practicing the real exam questions.
NEW QUESTION # 91
You are classifying token-management tactics by where each tactic applies in the request lifecycle: "Input Preparation," "Prompt Construction," or "Output Handling."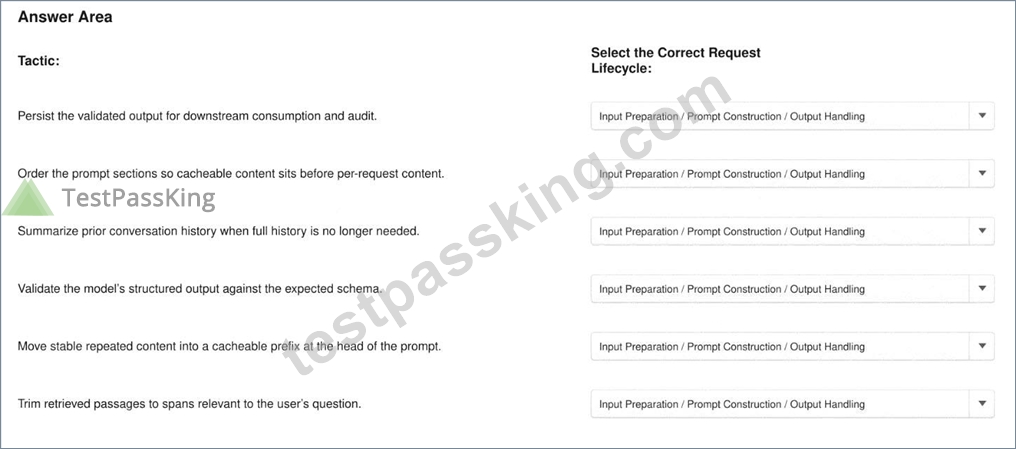
Answer:
Explanation: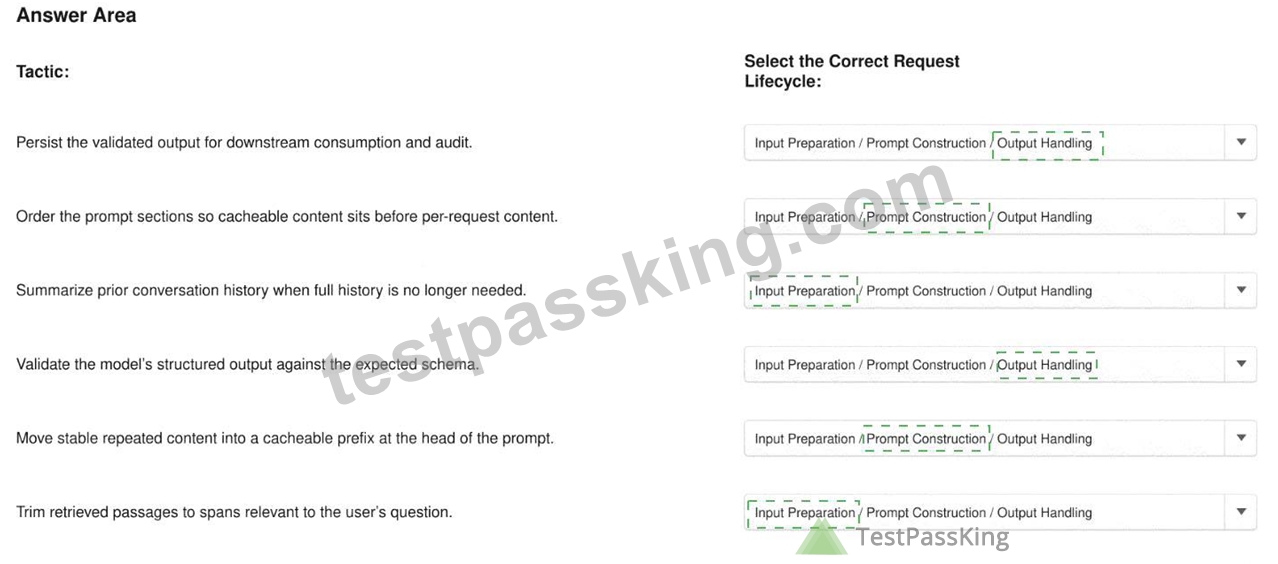
Explanation:
* Persist the validated output for downstream consumption and audit - Output Handling
* Order prompt sections so cacheable content appears before per-request content - Prompt Construction
* Summarize prior conversation history when full history is no longer needed - Input Preparation
* Validate the model's structured output against the expected schema - Output Handling
* Move stable repeated content into a cacheable prefix at the beginning of the prompt - Prompt Construction
* Trim retrieved passages to spans relevant to the user's question - Input Preparation Input preparation determines what evidence and history should enter the request, so summarization and retrieval trimming belong there. Prompt construction determines ordering and cache boundaries; stable repeated instructions must precede dynamic per-request content to maximize cache reuse. Output handling begins after generation and includes schema validation, persistence, auditing, and downstream delivery.
Mixing these responsibilities creates inefficient prompts and weak validation boundaries. Anthropic's context guidance emphasizes curating the smallest useful context because unnecessary tokens can reduce recall and accuracy. Prompt caching similarly depends on a stable reusable prefix, while structured outputs or schema validation protect downstream systems from malformed responses. Context windows ; prompt caching
NEW QUESTION # 92
You are reviewing a customer-support agent's configuration. Each candidate tool falls into one of four categories: (1) required to complete defined tasks, (2) frequently used and reduces hand-offs, (3) occasionally useful for unrelated work, (4) speculative future utility.
Which categories should typically remain in the agent configuration?
Answer: B
Explanation:
Category 1 tools are necessary for the agent to complete its approved responsibilities and must remain.
Category 2 tools are also justified when they are regularly used and eliminate predictable hand-offs without expanding the agent beyond its defined operating role.
Categories 3 and 4 create capability bloat. A tool that is occasionally useful only for unrelated work does not belong to this agent's responsibility boundary. A speculative tool has no validated requirement and adds attack surface, context consumption, authorization complexity, evaluation burden, and operational dependencies without demonstrated value.
Tool inclusion should be based on task traceability: every configured capability should map to a documented user journey, responsibility, permission scope, and evaluation case. Anthropic recommends least privilege so that a successful injection or model error can cause minimal damage. Mitigate Jailbreaks and Prompt Injections The architect should periodically review tool-call telemetry and remove unused capabilities. New tools can be added when a validated workflow requires them, after security review and evaluation. The objective is not the smallest possible catalog regardless of usefulness; it is the smallest catalog that reliably completes the agent's approved tasks.
Study Guide references/topics: Capability-bloat analysis; tool necessity; hand-off reduction; least privilege; attack-surface management; tool lifecycle review.
NEW QUESTION # 93
You are reviewing a peer's end-to-end design for a Claude-based platform expected to scale to thousands of concurrent users.
For each statement, indicate Yes if it reflects sound architectural practice. Otherwise, select No.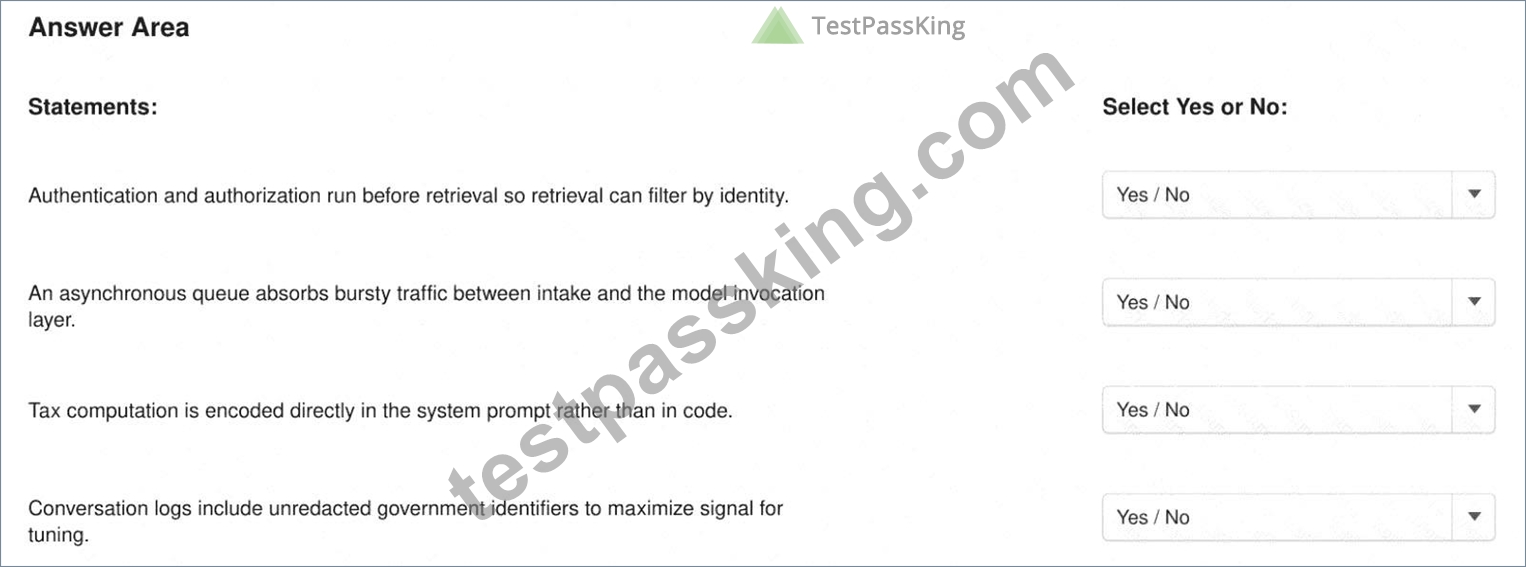
Answer:
Explanation: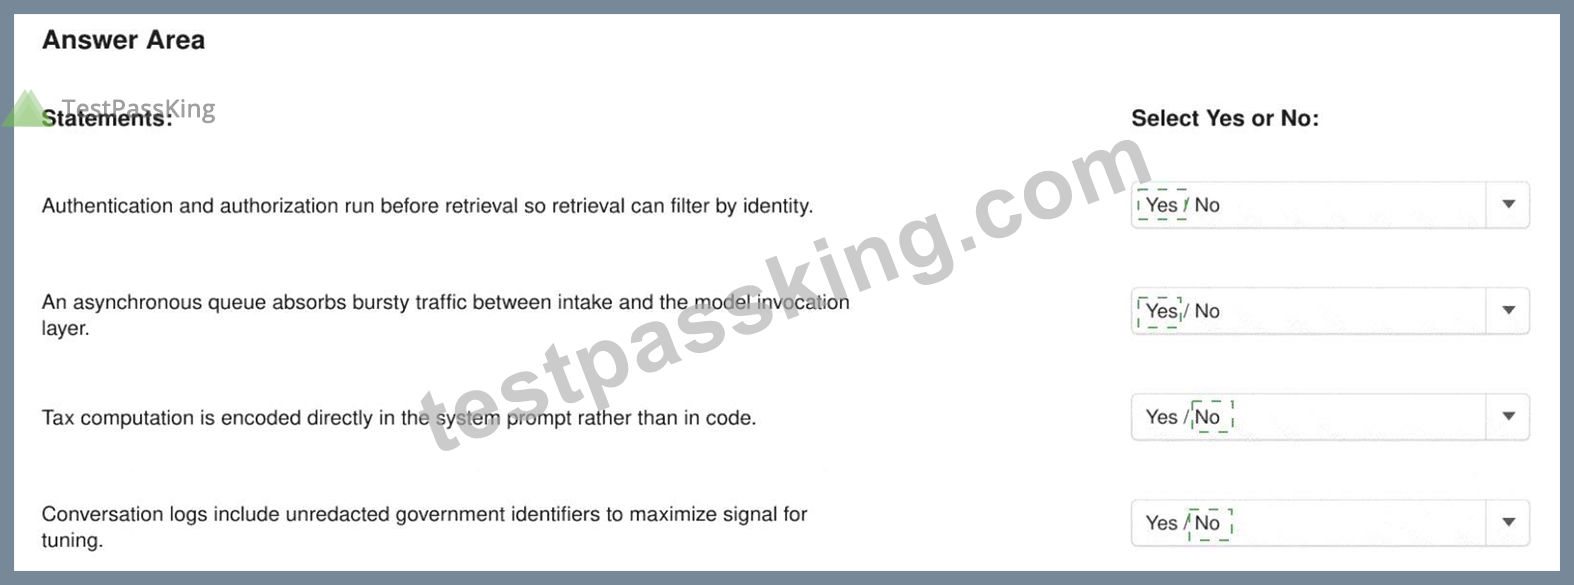
Explanation:
Authentication and authorization run before retrieval so retrieval can filter by identity - Yes An asynchronous queue absorbs bursty traffic between intake and the model-invocation layer - Yes Tax computation is encoded directly in the system prompt rather than in code - No Conversation logs include unredacted government identifiers to maximize tuning signal - No Authentication and authorization must precede retrieval so unauthorized information never enters model context. An asynchronous queue is appropriate for burst absorption, backpressure, controlled concurrency, and retry management at scale. Deterministic tax computation should be implemented in validated code or a controlled calculation tool, not delegated to probabilistic prompt interpretation. Including unredacted government identifiers in conversation logs violates data-minimization principles and creates unnecessary privacy, security, and regulatory exposure. Sensitive fields should be removed, tokenized, or redacted before logging or model use unless specifically required and authorized. The resulting design separates deterministic computation, access control, scalable orchestration, and language reasoning into appropriate architectural layers.
NEW QUESTION # 94
You are identifying the highest-impact optimization for a deployment whose token cost is dominated by a long, repeated system prompt and a large retrieved context per request.
Which optimization most directly targets the dominant cost driver?
Answer: C
NEW QUESTION # 95
You are evaluating prompting claims in a peer's design document.
For each claim, select yes if the claim reflects sound practice. Otherwise, select no.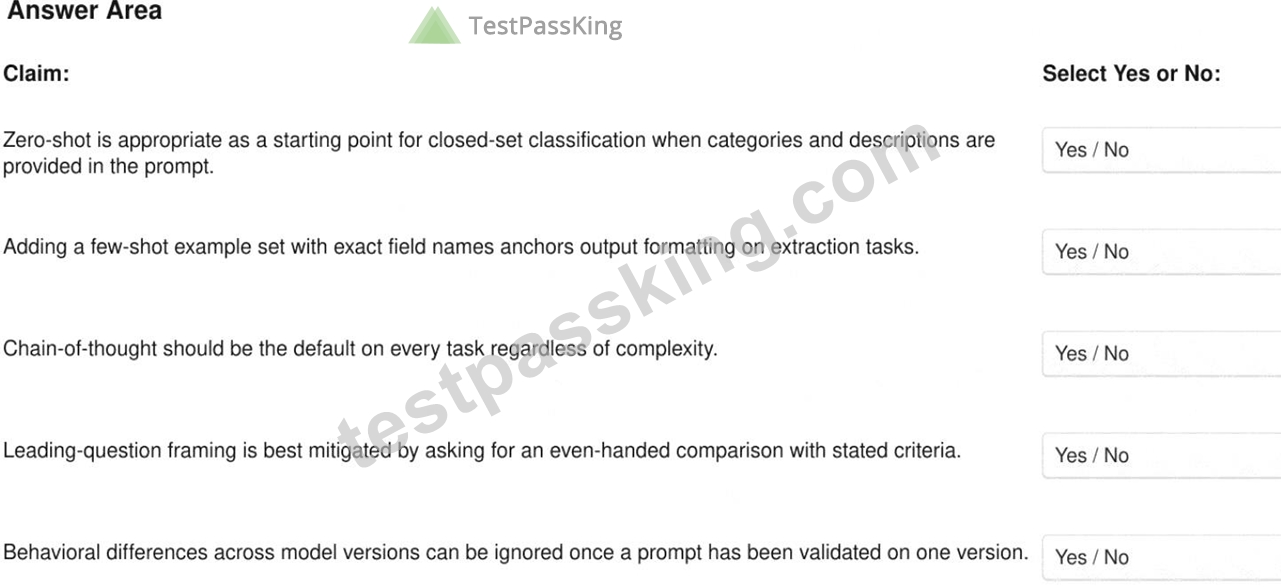
Answer:
Explanation: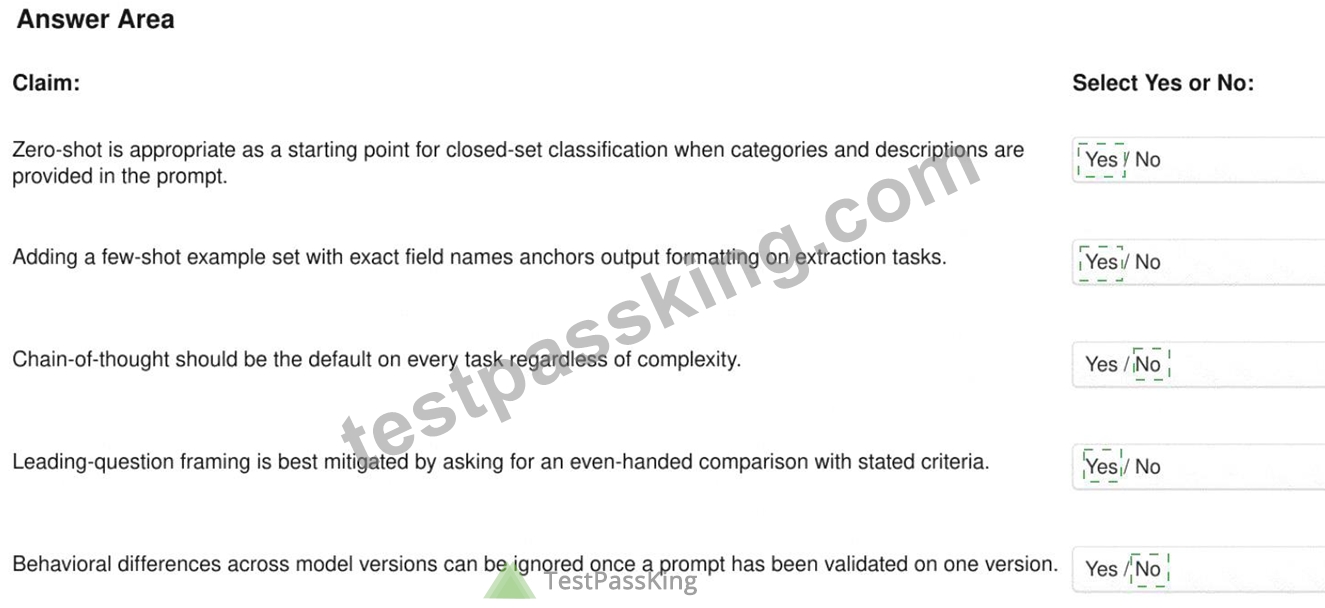
Explanation:
Yes, Yes, No, Yes, No
Zero-shot prompting is a reasonable baseline for a clearly defined closed-set classifier because the model receives both the permissible labels and their meanings. Performance should then be measured against an evaluation set before additional prompt complexity is introduced. Few-shot examples are also sound for extraction because examples containing the exact field names demonstrate the required schema and reduce formatting ambiguity. Anthropic identifies examples as one of the most reliable methods for steering output format, structure, and consistency. Prompting Best Practices Chain-of-thought is not an unconditional default. Additional reasoning is appropriate when the task requires substantive decomposition or complex judgment, but routine classification and extraction may gain little while consuming more tokens and increasing latency. The technique should be selected according to evaluated task requirements.
An even-handed comparison governed by explicit criteria mitigates leading-question bias by requiring symmetrical treatment of alternatives rather than presupposing a preferred conclusion. Finally, prompt validation is model-specific. New model versions may follow instructions differently, change formatting behavior, alter tool selection, or produce different latency and cost characteristics. Anthropic's migration guidance consequently recommends reevaluating prompts and workloads against the new baseline. Model Migration Guide Study Guide references/topics: Zero-shot prompting; few-shot examples; reasoning techniques; neutral framing; model migration and regression evaluation.
NEW QUESTION # 96
......
A lot of applicants have studied from Anthropic CCAR-P practice material. They have rated it positively because they have cracked Anthropic CCAR-P Certification on their first try. TestPassKing guarantees its customers that they can pass the CCAR-P test on the first attempt.
Valid CCAR-P Exam Cram: https://www.testpassking.com/CCAR-P-exam-testking-pass.html