Our company always put the quality of the AI-500 practice materials on top priority. In the past ten years, we have made many efforts to perfect our AI-500 study materials. Our AI-500 study questions cannot tolerate any small mistake. All staff has made great dedication to developing the AI-500 Exam simulation. Our professional experts are devoting themselves on the compiling and updating the exam materials and our services are ready to guide you 24/7 when you have any question.
| Section | Weight | Objectives |
|---|---|---|
| Evaluate, optimize, and monitor multi-agent solutions | 20–25% | - Assess performance and reliability
|
| Develop multi-agent solutions in Azure | 30–35% | - Manage state and memory
|
| Architect multi-agent solutions | 15–20% | - Design logical architecture for multi-agent systems
|
| Secure, govern, and deploy multi-agent solutions | 20–25% | - Apply security and compliance
|
>> Valid Test AI-500 Tutorial <<
Compared with the other products in the market, our AI-500 latest questions grasp of the core knowledge and key point of the real exam, the targeted and efficient Designing and Implementing Multi-Agent AI Solutions study training dumps guarantee our candidates to pass the test easily. Passing exam won’t be a problem anymore as long as you are familiar with our AI-500 Exam Material (only about 20 to 30 hours practice). High accuracy and high quality are the reasons why you should choose us.
NEW QUESTION # 62
You need to modify claim Approval to prevent the prompt injection issue. Which guardrail should you use?
Answer: B
Explanation:
The malicious text is contained in an uploaded email rather than being typed directly as the user ' s prompt.
Microsoft classifies malicious instructions embedded in external or retrieved content as an indirect prompt- injection attack. Prompt Shields for documents is designed to detect those attacks in document content before the content can steer the model away from its system instructions. Prompt Shields for user prompts addresses direct attacks originating in the user ' s prompt and therefore targets the wrong attack surface here.
Groundedness evaluates whether a response is supported by context; it does not prevent an injected instruction from changing agent behavior. Task Adherence can assess whether an agent follows its task constraints, but it is not the primary control for document-borne prompt injection. Because the source of the attack is the uploaded email, the document-oriented Prompt Shields control is the technically aligned guardrail. The same configuration should be paired with auditable identity, trace, and evaluation data so reviewers can prove which principal acted, which policy was applied, and why a request was allowed or blocked. That is particularly important for production multi-agent systems with external tools.
Official Microsoft reference: Microsoft Foundry guardrails - intervention points and indirect attacks
NEW QUESTION # 63
You have a Microsoft Foundry multi-agent customer support solution. The solution includes an orchestrator that starts a single conversation trace when a user request arrives and can invoke two agents named Agent1 and Agent2 concurrently. Each agent can invoke Model Context Protocol (MCP)-hosted tools and dependent REST APIs.
The solution uses OpenTelemetry SDKs to emit logs, metrics, and traces via OTLP to an OpenTelemetry Collector. The solution emits the conversation ID, trace ID, and span ID for agent invocations, tool invocations, and external API calls.
You have a monitoring dashboard that includes:
* Latency
* Throughput
* Reliability
* Token usage
* Content safety triggers
* Time to First Token (TTFT)
Alert rules are configured for latency anomalies and tool invocation failures.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.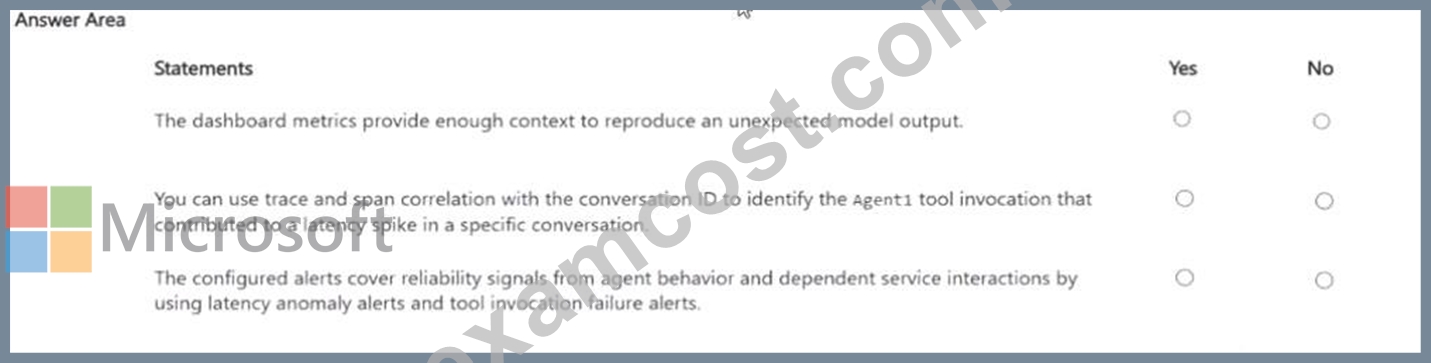
Answer:
Explanation:
Explanation:
No / Yes / Yes
Aggregate dashboard metrics do not provide enough execution context to reproduce a specific unexpected model output, so the first statement is false. Reproduction normally requires detailed trace data such as model inputs/outputs, ordered agent spans, tool calls, and dependency results. The second statement is true because the solution emits conversation, trace, and span identifiers across agent, MCP tool, and REST API calls.
OpenTelemetry correlation can therefore isolate the Agent1 tool span that contributed to a latency spike in one conversation. The third statement is also true: latency-anomaly alerts and tool-invocation failure alerts cover important reliability signals from both agent execution and dependent service interactions. They are not the entire observability strategy, but they do address the reliability conditions described. The correct sequence is No, Yes, Yes. The evaluation should also preserve correlation identifiers and version information where possible so a failed score can be traced back to the exact agent, model, tool call, or retrieval step that produced it. This turns the metric into an actionable diagnostic rather than only a dashboard number.
Official Microsoft reference: Microsoft Foundry - agent tracing concepts
NEW QUESTION # 64
You have a Microsoft Agent Framework multi-agent workflow. The workflow includes a context provider that injects a condensed memory summary into each agent invocation. Requirements and acceptance criteria are stored in GitHub issues.
During a long-running workflow, the acceptance criteria changes. Later agents sometimes apply the earlier criteria. Token telemetry shows condensed summaries grow across handoffs. causing older content to be truncated.
You need to ensure that the later agents use the current requirements. The solution must limit context window growth.
What should you do?
Answer: A
Explanation:
GitHub issues are the authoritative source for current requirements, and those requirements can change while a long-running workflow is still executing. Each handoff should therefore reconstruct context from the current issue state and discard memory that has been invalidated by newer requirements. Keeping an accumulated summary allows obsolete criteria to remain present and also causes the prompt to grow until older content is truncated. Persisting the transcript in Cosmos DB preserves history but does not make that history current.
Giving subagents a GitHub lookup tool while continuing to inject the stale summary can expose the model to conflicting versions of the same requirement. Microsoft Agent Framework context providers are intended to inject current external context at invocation time, making C the approach that simultaneously preserves freshness and bounds context growth. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Microsoft Agent Framework - Context providers
NEW QUESTION # 65
You have a Microsoft Foundry multi-agent solution.
Historical chat logs are limited and include customer Personally Identifiable Information (Pll).
The agents frequently produce invalid arguments when they call APIs by using structured function calls.
You need to create an initial fine-tuning dataset to improve the API-call behavior. The solution must minimize privacy exposure.
How should you configure the pipeline? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Initial example source: Synthetic generation; Generation task type: Tool use.
The historical chat logs are both sparse and privacy-sensitive, so using them directly as the initial fine-tuning corpus creates unnecessary PII exposure. Microsoft Foundry synthetic-data generation is intended to create diverse training examples when production data is limited and can avoid carrying customer identifiers into the dataset. The specific behavior that needs improvement is structured API/function calling, so the generator should use the Tool use task type. Tool-use generation can use an API/OpenAPI definition to create conversations that include valid tool selection and parameter construction, which directly trains the failure mode described. A general Q & A generator would not systematically teach function-call schemas. Therefore Synthetic generation plus Tool use is the configuration that both targets invalid arguments and minimizes privacy exposure. At implementation time, the same rule should be expressed through the framework or service configuration rather than left only as a natural-language convention. That makes the behavior repeatable across runs, easier to test, and less sensitive to model variability.
Official Microsoft reference: Microsoft Foundry - synthetic fine-tuning data generation
NEW QUESTION # 66
You have a Microsoft Foundry agent that answers questions about products. You evaluate the agent responses and discover the following issues:
* Questions about a product named product1 make up 40 percent of user traffic, and responses are returned in inconsistent formats.
* Questions about a product named product2 appear infrequently in the existing logs but have high escalation rates.
The available chat logs include customer names and contact details, and the labeling budget enables subject matter experts (SMEs) to review only a limited subset of training examples.
You need to design a dataset preparation plan to fine-tune the agent. The solution must meet the following requirements:
* Match usage patterns for the product1 questions.
* Cover the product2 questions.
* Meet General Data Protection Regulation < GDPR) and Health Insurance Portability and Accountability Act (HIPAA) privacy requirements for names and contact details.
* Minimize SME review efforts during labeling.
What should you include in the design? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Data acquisition: Production examples for high-volume product1 and synthetic examples for sparse product2; Curation: De-identify source records; Labeling: Use active learning to prioritize SME review.
Product1 represents a large share of real traffic, so production examples best preserve its true usage distribution. Product2 appears infrequently but has high escalation impact, making synthetic generation appropriate for filling the coverage gap without waiting for more production traffic. Because the available logs contain names and contact information, those records should be de-identified before they are reused for training or labeling. Finally, the SME budget is limited, so active learning should prioritize the examples where expert labels are most informative instead of reviewing a uniform random sample. Microsoft Foundry guidance supports synthetic fine-tuning data when real examples are sparse, and Microsoft healthcare/privacy tooling supports de-identification of sensitive identifiers. This design balances representativeness, rare-case coverage, privacy, and labeling efficiency. At implementation time, the same rule should be expressed through the framework or service configuration rather than left only as a natural-language convention. That makes the behavior repeatable across runs, easier to test, and less sensitive to model variability.
Official Microsoft reference: Microsoft Foundry - synthetic fine-tuning data generation
NEW QUESTION # 67
......
Will you feel nervous when you are in the exam, and if you do, you can try our exam dumps.AI-500 Soft test engine can stimulate the real environment, through this , you can know the procedure of the real exam, so that you can release your nervous . And you can build up your confidence when you face the real exam. Besides, AI-500 Exam Dumps of us offer you free update for one year after purchasing, and our system will send the latest version to you automatically. We have online and offline chat service stuff, and if you have any questions, just have chat with them.
AI-500 New Braindumps Sheet: https://www.examcost.com/AI-500-practice-exam.html