P.S. Free & New DP-750 dumps are available on Google Drive shared by PracticeVCE: https://drive.google.com/open?id=13Yrj0LWJsa8xImdBBHfvpFOBlWbSaOlY
Our DP-750 Test Braindumps are by no means limited to only one group of people. Whether you are trying this exam for the first time or have extensive experience in taking exams, our DP-750 latest exam torrent can satisfy you. This is due to the fact that our DP-750 test braindumps are humanized designed and express complex information in an easy-to-understand language. You will never have language barriers, and the learning process is very easy for you. What are you waiting for? If you are preparing to take the test, you can rely on our learning materials. You will also be the next beneficiary. After you get Microsoft certification, you can get boosted and high salary to enjoy a good life.
| Section | Weight | Objectives |
|---|---|---|
| Set up and configure an Azure Databricks environment | 15–20% | - Integrate with Azure services
|
| Prepare and process data | 30–35% | - Ingest and transform data
|
| Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
|
| Deploy and maintain data pipelines and workloads | 30–35% | - Build and orchestrate pipelines
|
>> Valid Exam DP-750 Vce Free <<
Our company is a professional certificate test materials provider, and we have rich experiences in providing exam materials. DP-750 exam materials are reliable, and we can help you pass the exam just one time. DP-750 exam dumps are also known as high pass rate, and the pas rate reaches 98.95%. We are pass guaranteed and money back guaranteed in case you fail to pass the exam. Moreover, we have free demo for DP-750 Exam Materials for you to have a general understanding of the product.
NEW QUESTION # 43
You have an Azure Databricks workspace.
You have an Apache Spark Structured Streaming job named Job1 that processes data continuously and fails periodically due to transient errors.
You need to ensure that Job1 meets the following requirements:
- Resumes processing from the point that Job1 failed
- Minimizes how long it takes to restart Job1
- Minimizes the costs to restart Job1
What should you do?
Answer: B
Explanation:
You must use checkpointing.
Checkpointing is the native Apache Spark mechanism designed specifically to handle failures in Structured Streaming jobs. It saves the exact execution state and progress to cloud storage (like Azure Data Lake Storage), allowing the job to resume precisely where it left off without data loss.
Resumes from Failure Point: The checkpoint directory stores the stream offsets. When restarted, Spark reads these offsets to pick up exactly where it failed.
Minimizes Restart Time: By saving the state, Spark does not need to recompute historical streaming data or re-evaluate the entire stream architecture from scratch.
Minimizes Restart Costs: It prevents the reprocessing of duplicate data, saving valuable cluster compute time and reducing cloud infrastructure costs.
Reference:
https://www.linkedin.com/posts/shilpa-das-ln_what-is-checkpointing-in-spark-checkpointing- activity-7297113790393815041-AhPg
NEW QUESTION # 44
You have an Azure Databricks workspace named Workspace1 that is attached to a Unity Catalog metastore named metastore1 You need to register an Azure Storage account named account1 that has a hierarchical namespace enabled as an external location The external location must use a managed identity to authenticate to account1 and the solution must follow the principle of least privilege.
Which three actions should you perform in sequence' To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.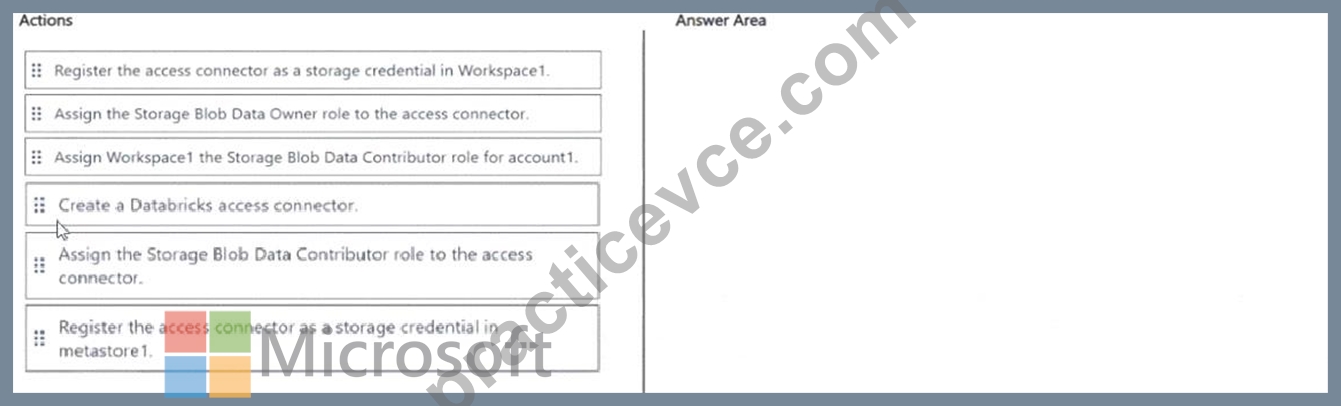
Answer:
Explanation: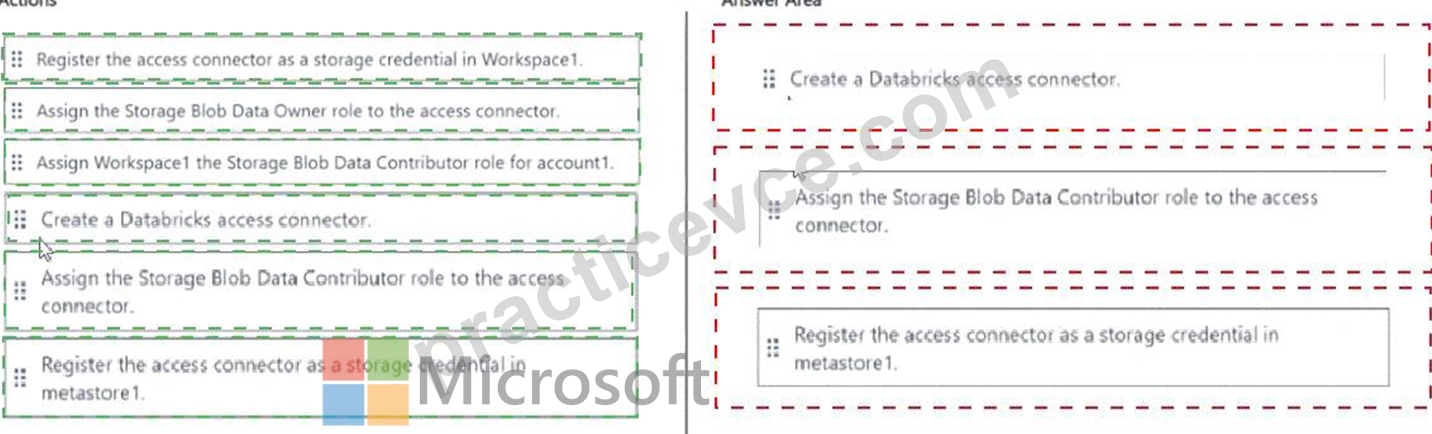
Explanation:
Registering an ADLS Gen2 account as an external location in Unity Catalog requires three steps in a specific order:
Step 1: Create a Databricks Access Connector. This Azure resource wraps a system-assigned or user-assigned managed identity. It is the credential-less authentication bridge between Databricks and Azure Storage - no SAS tokens or access keys are stored anywhere in the workspace.
Step 2: Create a Storage Credential in Unity Catalog that references the Access Connector. This object tells Unity Catalog 'use this identity when accessing storage.' The Storage Credential is the reusable authentication object.
Step 3: Create an External Location that maps a Unity Catalog path to the specific ADLS Gen2 container using the Storage Credential. This is the object that grants Databricks users access to files under that path, and it respects the principle of least privilege by scoping access to a specific container.
Reference: https://learn.microsoft.com/en-us/azure/databricks/connect/unity-catalog/storage-credentials
NEW QUESTION # 45
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Sales_orders. Sales.orders stores historical sales data.
You receive a daily CSV file daily that contains new sales records only. The file does NOT contain updates to existing rows You need to load the daily data into Sales.orders. The solution must meet the following requirements:
* Preserve the existing data.
* Add only the new records.
* Minimize processing effort.
Which command should include in the loading strategy?
Answer: C
Explanation:
The correct answer is C - INSERT INTO.
The scenario is clear: the daily file contains only new records, no updates to existing rows. INSERT INTO is the right command because it appends the new rows to Sales.orders without touching the existing historical data. All three requirements are satisfied: existing data is preserved, only new records are added, and the loading strategy is as simple as it gets.
Option A (INSERT OVERWRITE) replaces the existing data with just today's file. After the first day you'd have only 24 hours of history - all prior sales records would be gone. Option B (UPDATE) modifies specific existing rows based on a match condition; it doesn't load new records at all.
Because the source file is guaranteed to contain only new records and no duplicates of existing rows, a full MERGE is unnecessary overhead. Simple INSERT INTO is both correct and the most efficient approach.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/delta-insert-into
NEW QUESTION # 46
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains two Delta tables named Table1 and Table2 of the same data type.
Table1 contains a column named Columnl. Table2 contains a column named Column2. You run the following query.
SELECT Column1
FROM Table1
GROUP BY Column1
HAVING COUNT(") > 1
INTERSECT
SELECT C0lumn2
FROM Table2
GROUP BY Column2
HAVING COUNT(') > 1;
What occurs when you run the query?
Answer: D
Explanation:
The correct answer is B - values appear in both tables more than once.
Reading the query from the inside out: each subquery identifies values that appear more than once within their own table. The first subquery returns Column1 values that are duplicated in Table1. The second returns Column2 values that are duplicated in Table2. INTERSECT then returns only the values that appear in both result sets - meaning values that are duplicated in Table1 AND also duplicated in Table2.
Option A describes a UNION result (values in either table), not INTERSECT. Option C only considers duplicates in Table1, ignoring the Table2 condition - that would be the first subquery in isolation. Option D describes values exclusive to Table2 (EXCEPT or MINUS), the opposite of INTERSECT's requirement that values appear in both sets.
INTERSECT always requires membership in both operands - that's its fundamental definition in standard SQL.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/sql-ref-syntax-qry-select- setops
NEW QUESTION # 47
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to recommend a pipeline that ingests files from cloud storage, performs cleansing and enrichment transformations, and writes created Delta tables for analytics. The solution must minimize development effort and provide built-in monitoring and automatic retries.
What should you include in the recommendation?
Answer: B
Explanation:
The correct answer is C - a Lakeflow Spark Declarative Pipelines (SDP) pipeline.
SDP is tailor-made for exactly this pattern: ingest from cloud storage, transform through cleansing and enrichment stages, and publish Delta tables to Unity Catalog. What sets it apart from the other options is built- in monitoring (the pipeline graph shows row counts, expectation metrics, and run history) and automatic retries (failed tasks retry automatically based on pipeline settings, without manual re-run triggers).
Option A (Structured Streaming job) gives you the streaming engine but nothing else - monitoring, alerting, and retry logic all have to be built from scratch. Option B (scheduled notebook job) is a batch approach that requires manual monitoring and lacks the declarative lineage tracking SDP provides. Option D (Azure Data Factory with data flows) works but adds a separate Azure service to manage, introduces ADF licensing costs, and doesn't integrate natively with Unity Catalog governance.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/what-is-delta-live-tables
NEW QUESTION # 48
......
The Microsoft DP-750 exam PDF is the collection of real, valid, and updated Microsoft DP-750 practice questions. The Microsoft DP-750 PDF dumps file works with all smart devices. You can use the DP-750 PDF Questions on your tablet, smartphone, or laptop and start DP-750 exam preparation anytime and anywhere.
DP-750 Pdf Format: https://www.practicevce.com/Microsoft/DP-750-practice-exam-dumps.html
2026 Latest PracticeVCE DP-750 PDF Dumps and DP-750 Exam Engine Free Share: https://drive.google.com/open?id=13Yrj0LWJsa8xImdBBHfvpFOBlWbSaOlY