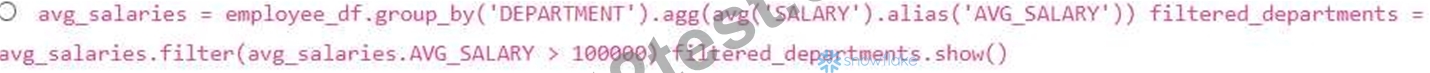Free PDF SPS-C01 - Snowflake Certified SnowPro Specialty - Snowpark Newest Latest Test Pdf

BTW, DOWNLOAD part of Fast2test SPS-C01 dumps from Cloud Storage: https://drive.google.com/open?id=11bGee5VFpXxHkrpqtCW8LgxD1Fb9QXWB
With the Snowflake SPS-C01 certification exam you will get an opportunity to learn new and in-demand skills. In this way, you will stay updated and competitive in the market and advance your career easily. To do this you just need to pass the Snowflake Certified SnowPro Specialty - Snowpark SPS-C01 Certification Exam.
| Section | Objectives |
|---|
| User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
- 1. Stored procedures in Snowpark
- 2. Python UDFs
|
| Testing, Debugging, and Deployment | - Production readiness
- 1. Deployment strategies
- 2. Debugging Snowpark applications
|
| Snowpark Fundamentals | - Snowpark architecture and concepts
- 1. Snowpark APIs and supported languages
- 2. Snowflake execution model overview
|
| Performance Optimization and Best Practices | - Efficient Snowpark execution
- 1. Pushdown optimization concepts
- 2. Resource utilization tuning
|
| Data Engineering with Snowpark | - Pipeline development
- 1. Integration with Snowflake data pipelines
- 2. Batch processing workflows
|
| DataFrame Operations and Data Processing | - Data transformation workflows
- 1. Filtering, selecting, and aggregations
- 2. Joins and window functions
|
>> Latest SPS-C01 Test Pdf <<
SPS-C01 Braindumps & SPS-C01 Preparation
Fast2test can provide you with a reliable and comprehensive solution to pass Snowflake certification SPS-C01 exam. Our solution can 100% guarantee you to pass the exam, and also provide you with a one-year free update service. You can also try to free download the Snowflake Certification SPS-C01 Exam testing software and some practice questions and answers to on Fast2test website.
Snowflake Certified SnowPro Specialty - Snowpark Sample Questions (Q162-Q167):
NEW QUESTION # 162
Consider a Snowpark DataFrame with columns 'DEPARTMENT, 'SALARY , and 'YEAR. You want to find the average salary for each department over all years and then filter the departments to only include those where the average salary is greater than 100000. Which of the following approaches is the MOST efficient and correct way to achieve this using Snowpark Python?
Answer: D
Explanation:
Options A, B, C, and D are technically valid but use 'avg' or 'col' instead of the recommended 'sf.mean' and 'sf.cor for Snowpark. Option E, is most efficient as it leverages Snowpark's functions ('sf.mean' and 'sf.col') correctly and splits the operation in two steps for clarity and potential optimization. 'col' can be used, 'sf.col' is the recommended way.
NEW QUESTION # 163
You are developing a Snowpark stored procedure in Python that utilizes the 'requests' library to fetch data from an external API. Your Snowflake account is configured to use Anaconda packages. You encounter an error indicating that the 'requests' library is not found. Which of the following steps are MOST effective in ensuring the 'requests' library is available to your stored procedure?
- A. Enable Anaconda integration for your Snowflake account, ensuring 'requests' is available in the Snowflake Anaconda channel, and then create the stored procedure using 'imports=['snowflake://packages/requests/']'.
- B. Specify the 'requests library in the stored procedure's 'packages argument during creation: 'CREATE OR REPLACE PROCEDURE
- C. Include the 'requests' library directly in the stored procedure code using a base64 encoded string.
- D. Install the 'requestS library directly onto the Snowflake compute nodes using SnowSQL's command.
- E. Manually upload the 'requests' library's ' .py' files to an internal stage and import them within the stored procedure.
Answer: B
Explanation:
The 'packages' argument in the 'CREATE OR REPLACE PROCEDURE statement is the correct way to specify dependencies on Anaconda packages. Snowflake will automatically resolve and make these packages available to the stored procedure. Option B is incomplete; while Anaconda integration is necessary, it doesn't automatically import the library. Options A, C and E are incorrect and not best practices.
NEW QUESTION # 164
You are developing a Snowpark stored procedure to process PDF files stored in a Snowflake stage. You need to extract text from these PDF files and store the extracted text in a Snowflake table. Due to security requirements, you cannot use any external packages that require internet access. Which of the following approaches can you use to accomplish this task securely and efficiently? (Select all that apply)
- A. Develop a custom Java UDF (User-Defined Function) that uses a secure, open-source PDF parsing library (e.g., PDFBox) and register it with Snowflake. Call this UDF from the Snowpark stored procedure to extract the text.
- B. Use Snowpark's built-in PDF parsing functions to extract the text. Snowflake provides native support for PDF parsing, eliminating the need for external libraries.
- C. Implement an external function using AWS Lambda or Azure Functions to parse the PDF files and extract the text. Configure the external function to have no internet access.
- D. Convert the PDF files to a text-based format (e.g., TXT) using an external tool before loading them into Snowflake. Then, use Snowpark to process the text files.
- E. Use the function to read the PDF files as binary data. Implement a pure-Python PDF parsing library directly within the stored procedure to extract the text. Ensure the library code is included directly in the stored procedure code.
Answer: A,E
Explanation:
Options B and C are correct. Option B: Java UDFs allow you to leverage existing Java libraries (like PDFBox, which can be included in the UDF's JAR file) to parse PDFs securely within the Snowflake environment. Option C: Using and a pure-Python PDF parsing library (which doesn't require external network access) is another viable approach. The entire library's code must be embedded within the stored procedure. Option A is incorrect because Snowflake does not have built-in PDF parsing functions. Option D is not ideal as you are trying to avoid any external dependencies and internet access. Option E, although workable, adds an external preprocessing step which isn't the most efficient way.
NEW QUESTION # 165
You are tasked with building a data pipeline that uses Snowpark to process customer data in a table called 'CUSTOMERS'. The table contains sensitive information, and you need to ensure that any Personally Identifiable Information (PII) is removed from the table after 30 days. You decide to implement a mechanism to automatically delete records older than 30 days. Which of the following approaches would you consider when designing the deletion process with consideration of cost, performance and security?
- A. Implement a dynamic data masking policy on the PII columns instead of deleting records. Set the policy to mask data older than 30 days.
- B. Create a Snowpark Stored Procedure that executes the 'DataFrame.delete()' operation and schedule this stored procedure to run daily using a Snowflake Task.
- C. Implement a Snowflake Task that executes a SQL 'DELETE statement directly against the 'CUSTOMERS' table, filtering records based on the 'created_at' column.
- D. Implement a Snowflake Stream on the 'CUSTOMERS' table. Create another table 'CUSTOMERS ARCHIVE' with the same schema and stream data older than 30 days using 'DataFrame.copy_into_table', then truncate data from original CUSTOMERS table
- E. Schedule a daily Snowpark script to read the entire 'CUSTOMERS' table, filter out records older than 30 days based on the 'created_at' column, and then use DataFrame.delete()' to remove those records from the table.
Answer: A,B,C
Explanation:
Options B, C and E are viable and have tradeoffs. A and D will be less ideal. Option A : This approach can be very inefficient as it requires scanning the entire table daily to identify records for deletion. This can lead to high costs and performance issues. Option B : Using a Snowflake Task with a direct SQL DELETE statement is generally more efficient than reading the entire table in Snowpark, especially for large tables. Snowflake can optimize the DELETE operation internally. Option C : Encapsulating the deletion logic in a Snowpark Stored Procedure and scheduling it with a Snowflake Task allows you to leverage Snowpark's capabilities while benefiting from Snowflake's task scheduling and optimization. This can offer a good balance of flexibility and performance. Option D : This is an archive solution, not deletion; it's not as fast or space saving as truncating. Option E : Data masking is a secure alternative. It preserves the records while redacting sensitive data. No need to scan for old records, so its best on performance, cost, and security.
NEW QUESTION # 166
You are tasked with optimizing a Snowpark Python stored procedure that performs complex data transformations on a DataFrame. The procedure frequently encounters out-of-memory errors when processing large datasets. Which of the following strategies could you implement to mitigate these memory issues within the stored procedure's code ? Choose all that apply.
- A. Utilize the 'repartition()' or functions to control the number of partitions in the DataFrame and potentially reduce memory consumption per partition.
- B. Use smaller data types (e.g., ' Int16' instead of ' Int64') where appropriate to minimize memory footprint.
- C. Increase the warehouse size to provide more memory resources.
- D. Implement data filtering and aggregation as early as possible in the transformation pipeline to reduce the size of the DataFrame.
- E. Leverage the 'sample()' function to work with a smaller subset of the data for testing and debugging.
Answer: A,B,D
Explanation:
Options B, C, and D directly address memory management within the stored procedure. Option B: 'repartition()' and allow you to control how the data is distributed across partitions. By adjusting the number of partitions, you can influence the amount of memory required to process each partition. Fewer, larger partitions can sometimes be problematic, whereas many smaller partitions might improve memory management but increase overhead. The best strategy depends on the specifics of the data and the transformations. Option C: Performing filtering and aggregation early reduces the volume of data that needs to be processed in subsequent steps, directly reducing memory consumption. This is a common optimization technique in data processing pipelines. Option D: Using smaller data types can significantly reduce memory footprint, especially when dealing with large datasets. Using 'Int16' when the range of values allows for it, instead of defaulting to Int64', can halve the memory usage for that column. Option A (increasing the warehouse size) provides more resources but doesn't address the underlying code inefficiencies that lead to memory errors. It's a valid approach, but should be considered after code-level optimizations. Option E(using 'sample()') is primarily for testing and debugging and does not solve the memory issue when processing the full dataset.
NEW QUESTION # 167
......
Our website has helped thousands of people getting the certification by offering valid SPS-C01 dumps torrent. The key of our success is that our SPS-C01 practice exam covers the comprehensive knowledge and the best quality of service. Our questions and answers in our SPS-C01 Training Materials are certified by our IT professionals. One-year free update will be allowed after payment.
SPS-C01 Braindumps: https://www.fast2test.com/SPS-C01-premium-file.html
- Valid SPS-C01 Exam Voucher 🟡 SPS-C01 Valid Torrent 🌽 Flexible SPS-C01 Testing Engine 🧀 Copy URL 【 www.dumpsquestion.com 】 open and search for ▷ SPS-C01 ◁ to download for free 🌀SPS-C01 Reliable Braindumps Files
- Valid Exam SPS-C01 Preparation 💏 Practice SPS-C01 Test Engine 🚲 Practice SPS-C01 Test Engine ☀ The page for free download of ➤ SPS-C01 ⮘ on ▷ www.pdfvce.com ◁ will open immediately 🌅Practice SPS-C01 Test Online
- SPS-C01 High Quality 🧙 Authentic SPS-C01 Exam Hub 🤭 Flexible SPS-C01 Testing Engine 🦔 Search for ➥ SPS-C01 🡄 on 「 www.dumpsmaterials.com 」 immediately to obtain a free download 🏰Practice SPS-C01 Test Online
- Snowflake Latest SPS-C01 Test Pdf: Snowflake Certified SnowPro Specialty - Snowpark - Pdfvce Easily Pass Exam If Choosing us ☮ Search for 【 SPS-C01 】 and download it for free on ▛ www.pdfvce.com ▟ website 🙊Training SPS-C01 Material
- Pass Guaranteed Quiz 2026 Pass-Sure SPS-C01: Latest Snowflake Certified SnowPro Specialty - Snowpark Test Pdf 🚢 Search for ➽ SPS-C01 🢪 and easily obtain a free download on 「 www.exam4labs.com 」 👶SPS-C01 Exam Consultant
- Practice SPS-C01 Test Engine 🤴 Authentic SPS-C01 Exam Hub 🔪 Valid SPS-C01 Exam Voucher ➿ Search for ☀ SPS-C01 ️☀️ and download it for free immediately on ▛ www.pdfvce.com ▟ 👛Exam SPS-C01 Questions Answers
- Pass Guaranteed Quiz 2026 Pass-Sure SPS-C01: Latest Snowflake Certified SnowPro Specialty - Snowpark Test Pdf 🥍 ➠ www.vce4dumps.com 🠰 is best website to obtain ⮆ SPS-C01 ⮄ for free download 😸SPS-C01 Latest Learning Materials
- SPS-C01 Certification Dump 🍳 Valid Exam SPS-C01 Preparation 🎂 SPS-C01 Reliable Braindumps Files 🐘 Easily obtain ➠ SPS-C01 🠰 for free download through ➡ www.pdfvce.com ️⬅️ 🗨Valid Exam SPS-C01 Preparation
- SPS-C01 High Quality 🛶 Valid SPS-C01 Exam Voucher 👠 SPS-C01 Latest Learning Materials 🧑 Immediately open { www.practicevce.com } and search for ✔ SPS-C01 ️✔️ to obtain a free download 🤐Valid SPS-C01 Test Questions
- Quiz Reliable Snowflake - SPS-C01 - Latest Snowflake Certified SnowPro Specialty - Snowpark Test Pdf 😼 Search for 《 SPS-C01 》 and download it for free immediately on ➽ www.pdfvce.com 🢪 🔩Valid SPS-C01 Exam Voucher
- SPS-C01 Exam Consultant 🚏 Practice SPS-C01 Test Engine 🛒 Flexible SPS-C01 Testing Engine 😕 Open ➡ www.practicevce.com ️⬅️ enter ▛ SPS-C01 ▟ and obtain a free download 🤣New SPS-C01 Test Forum
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.flirtic.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
P.S. Free & New SPS-C01 dumps are available on Google Drive shared by Fast2test: https://drive.google.com/open?id=11bGee5VFpXxHkrpqtCW8LgxD1Fb9QXWB