P.S. Free 2026 Snowflake ARA-C01 dumps are available on Google Drive shared by Actual4dump: https://drive.google.com/open?id=1eL1OsbRPD7SPE_wonhXTaF6KgCXlBLN6
As our loyal customer, some of them will choose different types of ARA-C01 study materials on our website. As you can see, they still keep up with absorbing new knowledge of our ARA-C01 training questions. Once you cultivate the good habit of learning our study materials, you will benefit a lot and keep great strength in society. Also, our ARA-C01 practice quiz has been regarded as the top selling products in the market. We have built our own reputation in the market.
| Section | Weight | Objectives |
|---|---|---|
| Accounts and Security | 25% | - Security principles and implementation scenarios - Security, compliance and governance architecture - Account and database strategy design |
| Performance Optimization | 20% | - Virtual warehouse configuration and sizing - Query performance tuning - Cost optimization and resource management - Clustering and partitioning strategies |
| Snowflake Architecture | 30% | - Object hierarchy and architectural impact - Data sharing architecture design - Data protection and recovery strategies - Development lifecycle and workload support - Data modeling and use cases |
| Data Engineering | 25% | - Data loading and unloading solutions - Transformation and processing frameworks - Data pipeline and integration design |
All of these advantages, you can avail of after passing the ARA-C01 exam. You must find the best resource to prepare for the Snowflake ARA-C01 test if you want to pass the Snowflake ARA-C01 Certification Exam. Without proper Snowflake ARA-C01 exam preparation, getting success in the Snowflake ARA-C01 exam is impossible.
NEW QUESTION # 74
An Architect needs to design a data unloading strategy for Snowflake, that will be used with the COPY INTO
<location> command.
Which configuration is valid?
Answer: C
Explanation:
For the configuration of data unloading in Snowflake, the valid option among the provided choices is "C." This is because Snowflake supports unloading data into Google Cloud Storage using the COPY INTO
<location> command with specific configurations. The configurations listed in option C, such as Parquet file format with UTF-8 encoding and gzip compression, are all supported by Snowflake. Notably, Parquet is a columnar storage file format, which is optimal for high-performance data processing tasks in Snowflake. The UTF-8 file encoding and gzip compression are both standard and widely used settings that are compatible with Snowflake's capabilities for data unloading to cloud storage platforms.References:
* Snowflake Documentation on COPY INTO command
* Snowflake Documentation on Supported File Formats
* Snowflake Documentation on Compression and Encoding Options
NEW QUESTION # 75
What is a characteristic of Role-Based Access Control (RBAC) as used in Snowflake?
Answer: D
Explanation:
Role-Based Access Control (RBAC) is the Snowflake Access Control Framework that allows privileges to be granted by object owners to roles, and roles, in turn, can be assigned to users to restrict or allow actions to be performed on objects. A characteristic of RBAC as used in Snowflake is:
* Privileges can be granted at the database level and can be inherited by all underlying objects. This means that a role that has a certain privilege on a database, such as CREATE SCHEMA or USAGE, can also perform the same action on any schema, table, view, or other object within that database, unless explicitly revoked. This simplifies the access control management and reduces the number of grants required.
* A user can create managed access schemas to support future grants and ensure only schema owners can grant privileges to other roles. This means that a user can create a schema with the MANAGED ACCESS option, which changes the default behavior of object ownership and privilege granting within the schema. In a managed access schema, object owners lose the ability to grant privileges on their objects to other roles, and only the schema owner or a role with the MANAGE GRANTS privilege can do so. This enhances the security and governance of the schema and its objects.
The other options are not characteristics of RBAC as used in Snowflake:
* A user can use a "super-user" access along with securityadmin to bypass authorization checks and access all databases, schemas, and underlying objects. This is not true, as there is no such thing as a
"super-user" access in Snowflake. The securityadmin role is a predefined role that can manage users and roles, but it does not have any privileges on any database objects by default. To access any object, the securityadmin role must be explicitly granted the appropriate privilege by the object owner or another role with the grant option.
* A user can create managed access schemas to support current and future grants and ensure only object owners can grant privileges to other roles. This is not true, as this contradicts the definition of a managed access schema. In a managed access schema, object owners cannot grant privileges on their objects to other roles, and only the schema owner or a role with the MANAGE GRANTS privilege can do so.
Overview of Access Control
A Functional Approach For Snowflake's Role-Based Access Controls
Snowflake Role-Based Access Control simplified
Snowflake RBAC security prefers role inheritance to role composition
Overview of Snowflake Role Based Access Control
NEW QUESTION # 76
A table contains five columns and it has millions of records. The cardinality distribution of the columns is shown below: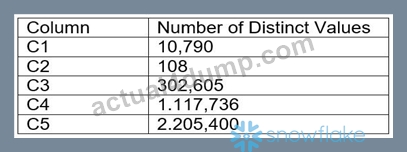
Column C4 and C5 are mostly used by SELECT queries in the GROUP BY and ORDER BY clauses.
Whereas columns C1, C2 and C3 are heavily used in filter and join conditions of SELECT queries.
The Architect must design a clustering key for this table to improve the query performance.
Based on Snowflake recommendations, how should the clustering key columns be ordered while defining the multi-column clustering key?
Answer: B
Explanation:
According to the Snowflake documentation, the following are some considerations for choosing clustering for a table1:
* Clustering is optimal when either:
* You require the fastest possible response times, regardless of cost.
* Your improved query performance offsets the credits required to cluster and maintain the table.
* Clustering is most effective when the clustering key is used in the following types of query predicates:
* Filter predicates (e.g. WHERE clauses)
* Join predicates (e.g. ON clauses)
* Grouping predicates (e.g. GROUP BY clauses)
* Sorting predicates (e.g. ORDER BY clauses)
* Clustering is less effective when the clustering key is not used in any of the above query predicates, or when the clustering key is used in a predicate that requires a function or expression to be applied to the key (e.g. DATE_TRUNC, TO_CHAR, etc.).
* For most tables, Snowflake recommends a maximum of 3 or 4 columns (or expressions) per key.
Adding more than 3-4 columns tends to increase costs more than benefits.
Based on these considerations, the best option for the clustering key columns is C. C1, C3, C2, because:
* These columns are heavily used in filter and join conditions of SELECT queries, which are the most effective types of predicates for clustering.
* These columns have high cardinality, which means they have many distinct values and can help reduce the clustering skew and improve the compression ratio.
* These columns are likely to be correlated with each other, which means they can help co-locate similar rows in the same micro-partitions and improve the scan efficiency.
* These columns do not require any functions or expressions to be applied to them, which means they can be directly used in the predicates without affecting the clustering.
References: 1: Considerations for Choosing Clustering for a Table | Snowflake Documentation
NEW QUESTION # 77
A Snowflake Architect is designing an application and tenancy strategy for an organization where strong legal isolation rules as well as multi-tenancy are requirements.
Which approach will meet these requirements if Role-Based Access Policies (RBAC) is a viable option for isolating tenants?
Answer: C
NEW QUESTION # 78
Which technique efficiently ingests and consumes semi-structured data for Snowflake data lake workloads?
Answer: C
Explanation:
Schema-on-read is a fundamental pattern for Snowflake data lake workloads involving semi-structured data such as JSON, Avro, or Parquet (Answer C). Data is ingested in its raw form and interpreted at query time using Snowflake's VARIANT type and functions like FLATTEN.
This approach provides flexibility as data structures evolve, reduces ingestion complexity, and avoids the need to predefine rigid schemas. Schema-on-write is more appropriate for structured data warehouses but is less efficient for rapidly changing semi-structured data. IDEF1X is a data modeling notation, not an ingestion technique. Information schema is a metadata repository.
For SnowPro Architect candidates, understanding schema-on-read is critical when designing scalable, flexible data lake architectures in Snowflake.
NEW QUESTION # 79
......
Considering many exam candidates are in a state of anguished mood to prepare for the ARA-C01 exam, our company made three versions of ARA-C01 real exam materials to offer help. All these variants due to our customer-oriented tenets. As a responsible company over ten years, we are trustworthy. In the competitive economy, this company cannot remain in the business for long. But we keep being the leading position in contrast. We are reactive to your concerns and also proactive to new trends happened in this ARA-C01 Exam.
Latest ARA-C01 Dumps Files: https://www.actual4dump.com/Snowflake/ARA-C01-actualtests-dumps.html
P.S. Free & New ARA-C01 dumps are available on Google Drive shared by Actual4dump: https://drive.google.com/open?id=1eL1OsbRPD7SPE_wonhXTaF6KgCXlBLN6