DOWNLOAD the newest Prep4SureReview Professional-Machine-Learning-Engineer PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=10wSVxMIaDpCN8Q3S0bZiwq5R2dXkNnF4
Entering a strange environment, we will inevitably be very nervous. And our emotions will affect our performance. That is why some of the condidats fail in their real exam. But if you buy our Professional-Machine-Learning-Engineer exam questions, then you won't worry about this problem. Our Professional-Machine-Learning-Engineer study guide has arranged a mock exam to ensure that the user can take the exam in the best possible state. We simulated the most realistic examination room environment so that users can really familiarize themselves with the examination room. And our Professional-Machine-Learning-Engineer Practice Engine can give you 100% pass guarantee.
| Section | Objectives |
|---|---|
| Data preparation and processing | - Feature engineering
|
| ML model development | - Evaluation
|
| Designing ML solutions | - ML architecture design
|
| ML pipeline automation and orchestration | - Pipeline design
|
| Deployment and operations | - Monitoring and maintenance
|
>> Professional-Machine-Learning-Engineer Test Questions Fee <<
Checking our Professional-Machine-Learning-Engineer free demo is a great way of learning the pattern of exam materials and if it suits what you wanted. There are valid Professional-Machine-Learning-Engineer test questions and accurate answers along with the professional explanations in our study guide. All real questions just need to practice one or two days and remember the answers will save you much time in Professional-Machine-Learning-Engineer Real Exam. Come and join us.
NEW QUESTION # 170
You are developing an ML model that uses sliced frames from video feed and creates bounding boxes around specific objects. You want to automate the following steps in your training pipeline: ingestion and preprocessing of data in Cloud Storage, followed by training and hyperparameter tuning of the object model using Vertex AI jobs, and finally deploying the model to an endpoint. You want to orchestrate the entire pipeline with minimal cluster management. What approach should you use?
Answer: B
Explanation:
* Option A is incorrect because using Kubeflow Pipelines on Google Kubernetes Engine is not the most convenient way to orchestrate the entire pipeline with minimal cluster management. Kubeflow Pipelines is an open-source platform that allows you to build, run, and manage ML pipelines using containers1. Google Kubernetes Engine is a service that allows you to create and manage clusters of virtual machines that run Kubernetes, an open-source system for orchestrating containerized applications2. However, this option requires more effort and resources than option B, as it involves creating and configuring the clusters, installing and maintaining Kubeflow Pipelines, and writing and running the pipeline code.
* Option B is correct because using Vertex AI Pipelines with TensorFlow Extended (TFX) SDK is the best way to orchestrate the entire pipeline with minimal cluster management. Vertex AI Pipelines is a service that allows you to create and run scalable and portable ML pipelines on Google Cloud3. TensorFlow Extended (TFX) is a framework that provides a set of components and libraries for building production-ready ML pipelines using TensorFlow4. You can use Vertex AI Pipelines with TFX SDK to ingest and preprocess the data in Cloud Storage, train and tune the object model using Vertex AI jobs, and deploy the model to an endpoint, using predefined or custom components. Vertex AI Pipelines handles the underlying infrastructure and orchestration for you, so you don't need to worry about cluster management or scalability.
* Option C is incorrect because using Vertex AI Pipelines with Kubeflow Pipelines SDK is not the most suitable way to orchestrate the entire pipeline with minimal cluster management. Kubeflow Pipelines SDK is a library that allows you to build and run ML pipelines using Kubeflow Pipelines5. You can use Vertex AI Pipelines with Kubeflow Pipelines SDK to create and run ML pipelines on Google Cloud, using containers. However, this option is less convenient and consistent than option B, as it requires you to use different APIs and tools for different steps of the pipeline, such as Vertex AI SDK for training and deployment, and Kubeflow Pipelines SDK for ingestion and preprocessing. Moreover, this option does not leverage the benefits of TFX, such as the standard components, the metadata store, or the ML Metadata library.
* Option D is incorrect because using Cloud Composer for the orchestration is not the most efficient way to orchestrate the entire pipeline with minimal cluster management. Cloud Composer is a service that allows you to create and run workflows using Apache Airflow, an open-source platform for orchestrating complex tasks. You can use Cloud Composer to orchestrate the entire pipeline, by creating and managing DAGs (directed acyclic graphs) that define the dependencies and order of the tasks. However, this option is more complex and costly than option B, as it involves creating and configuring the environments, installing and maintaining Airflow, and writing and running the DAGs.
References:
* Kubeflow Pipelines documentation
* Google Kubernetes Engine documentation
* Vertex AI Pipelines documentation
* TensorFlow Extended documentation
* Kubeflow Pipelines SDK documentation
* [Cloud Composer documentation]
* [Vertex AI documentation]
* [Cloud Storage documentation]
* [TensorFlow documentation]
NEW QUESTION # 171
You need to quickly build and train a model to predict the sentiment of customer reviews with custom categories without writing code. You do not have enough data to train a model from scratch. The resulting model should have high predictive performance. Which service should you use?
Answer: D
Explanation:
AutoML Natural Language is a service that allows you to build and train custom natural language models without writing code. You can use AutoML Natural Language to perform sentiment analysis with custom categories, such as positive, negative, or neutral. You can also use pre-trained models or transfer learning to leverage existing knowledge and reduce the amount of data required to train a model from scratch. AutoML Natural Language provides a user-friendly interface and a powerful AutoML engine that optimizes your model for high predictive performance.
Cloud Natural Language API is a service that provides pre-trained models for common natural language tasks, such as sentiment analysis, entity analysis, and syntax analysis. However, it does not allow you to customize the categories or use your own data for training.
AI Hub pre-made Jupyter Notebooks are interactive documents that contain code, text, and visualizations for various machine learning scenarios. However, they require some coding skills and data preparation to use them effectively.
AI Platform Training built-in algorithms are pre-configured machine learning algorithms that you can use to train models on AI Platform. However, they do not support sentiment analysis as a natural language task.
References:
* AutoML Natural Language documentation
* Cloud Natural Language API documentation
* AI Hub documentation
* AI Platform Training documentation
NEW QUESTION # 172
You have a high-traffic ecommerce application that uses a recommendation model deployed on an Agent Platform endpoint. During flash sales, traffic quickly spikes from 1,000 to 50,000 queries per second (QPS). During these spikes, the application returns 503: Service Unavailable errors because the autoscaler cannot provision new resources quickly enough to meet the sudden demand. Your need to eliminate service disruptions during the start of the sale. How should you configure the endpoint?
Answer: C
NEW QUESTION # 173
You have created a Vertex Al pipeline that automates custom model training You want to add a pipeline component that enables your team to most easily collaborate when running different executions and comparing metrics both visually and programmatically. What should you do?
Answer: A
Explanation:
Vertex AI Experiments is a managed service that allows you to track, compare, and manage experiments with Vertex AI. You can use Vertex AI Experiments to record the parameters, metrics, and artifacts of each pipeline run, and compare them in a graphical interface. Vertex AI TensorBoard is a tool that lets you visualize the metrics of your models, such as accuracy, loss, and learning curves. By logging metrics to Vertex ML Metadata and using Vertex AI Experiments and TensorBoard, you can easily collaborate with your team and find the best model configuration for your problem. References: Vertex AI Pipelines: Metrics visualization and run comparison using the KFP SDK, Track, compare, manage experiments with Vertex AI Experiments, Vertex AI Pipelines
NEW QUESTION # 174
You are designing an architecture with a serverless ML system to enrich customer support tickets with informative metadata before they are routed to a support agent. You need a set of models to predict ticket priority, predict ticket resolution time, and perform sentiment analysis to help agents make strategic decisions when they process support requests. Tickets are not expected to have any domain-specific terms or jargon.
The proposed architecture has the following flow: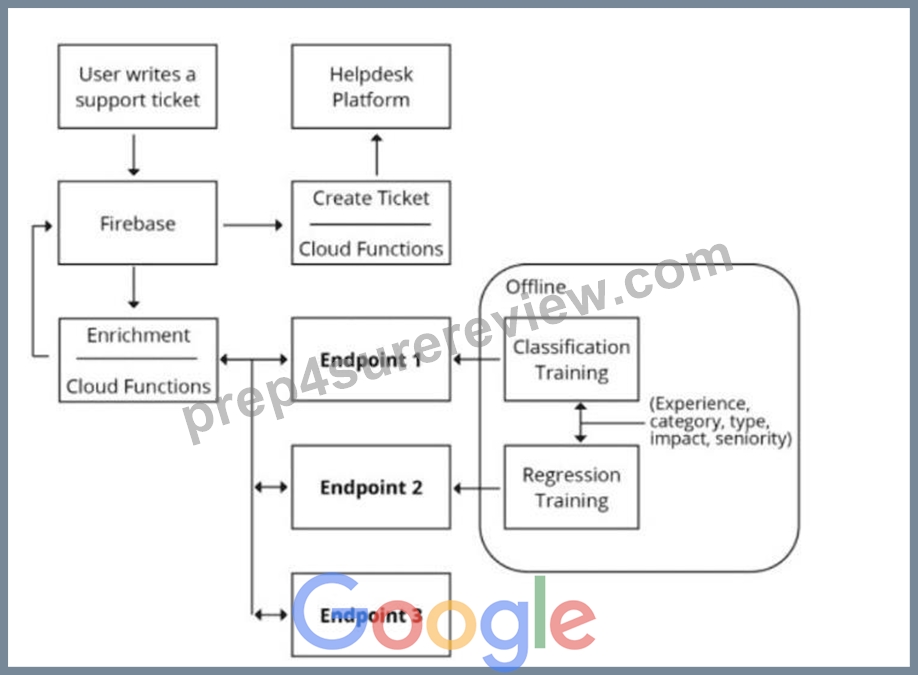
Which endpoints should the Enrichment Cloud Functions call?
Answer: A
Explanation:
Vertex AI is a unified platform for building and deploying ML models on Google Cloud. It supports both custom and AutoML models, and provides various tools and services for ML development, such as Vertex Pipelines, Vertex Vizier, Vertex Explainable AI, and Vertex Feature Store. Vertex AI can be used to create models for predicting ticket priority and resolution time, as these are domain-specific tasks that require custom training data and evaluation metrics. Cloud Natural Language API is a pre-trained service that provides natural language understanding capabilities, such as sentiment analysis, entity analysis, syntax analysis, and content classification. Cloud Natural Language API can be used to perform sentiment analysis on the support tickets, as this is a general task that does not require domain-specific knowledge or jargon. The other options are not suitable for the given architecture. AutoML Natural Language and AutoML Vision are services that allow users to create custom natural language and vision models using their own data and labels.
They are not needed for sentiment analysis, as Cloud Natural Language API already provides this functionality. Cloud Vision API is a pre-trained service that provides image analysis capabilities, such as object detection, face detection, text detection, and image labeling. It is not relevant for the support tickets, as they are not expected to have any images. References:
* Vertex AI documentation
* Cloud Natural Language API documentation
NEW QUESTION # 175
......
Prep4SureReview Google Professional-Machine-Learning-Engineer Dumps are the certification training material that guarantees 100% sail through the test at the first attempt. The accuracy rate of Prep4SureReview test answers and test questions is very high, so you only need to use the training material that guarantees you will pass the exam at the first time. If you don't believe it, try our free demo. If you don't pass the exam, Prep4SureReview will give you a FULL REFUND. So you have nothing to lose. Having used it, you can find it is high quality dumps. Hurry to have a try. We provide you with free demo and you can visit Prep4SureReview.com to download those questions.
Certification Professional-Machine-Learning-Engineer Dump: https://www.prep4surereview.com/Professional-Machine-Learning-Engineer-latest-braindumps.html
2026 Latest Prep4SureReview Professional-Machine-Learning-Engineer PDF Dumps and Professional-Machine-Learning-Engineer Exam Engine Free Share: https://drive.google.com/open?id=10wSVxMIaDpCN8Q3S0bZiwq5R2dXkNnF4