2026 Latest TrainingDumps AI-200 PDF Dumps and AI-200 Exam Engine Free Share: https://drive.google.com/open?id=1-2083pW4UgnUu3W0NckYbupBJcLk_W_Z
TrainingDumps is the trustworthy platform for you to get the reference study material for AI-200 exam preparation. The AI-200 questions and answers are compiled by our experts who have rich hands-on experience in this industry. So the contents of AI-200 pdf cram cover all the important knowledge points of the actual test, which ensure the high hit-rate and can help you 100% pass. Besides, we will always accompany you during the AI-200 Exam Preparation, so if you have any doubts, please contact us at any time. Hope you achieve good result in the AI-200 real test.
| Section | Objectives |
|---|---|
| Implement Azure AI solutions | - Implement computer vision solutions - Implement generative AI solutions using Azure OpenAI - Implement natural language processing solutions - Implement knowledge mining with Azure AI Search |
| Plan and manage Azure AI solutions | - Monitor and optimize AI solutions - Plan security and compliance requirements - Select appropriate Azure AI services |
| Implement and monitor AI workloads | - Monitor performance and troubleshoot issues - Deploy AI models and services |
>> Microsoft AI-200 Exam Sample Online <<
Our Microsoft AI-200 Exam Dumps effect in helping candidates' certification exam. Original questions are also important. These would provide a forum where certification training can be carried on. Our dumps torrent is perfect and practice test is also the latest. After you purchase our product, we offer free update service for one year.
NEW QUESTION # 55
Drag and Drop Question
You are investigating high latency in an AI search application that processes millions of requests daily. Telemetry is stored in Azure Monitor Logs.
You must create a KQL query that correlates information from the AppRequests table and the AppDependencies table. The query must meet the following requirements:
- Include only data from the last 24 hours.
- Filter for failed requests only.
- Calculate the average duration of dependencies, grouped by operation.
The query must be optimized for performance by minimizing the initial data scan.
You need to create the query.
Which five actions should you perform in sequence? To answer, move all actions from the list of actions to the answer area and arrange them in the correct order.
Answer:
Explanation: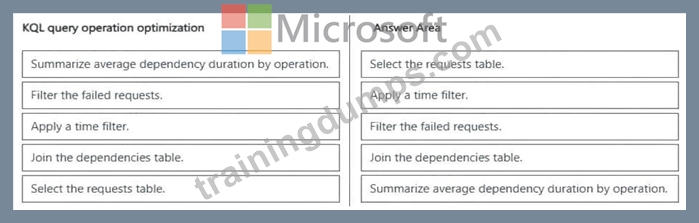
Explanation:
Step 1: Select the requests table
Starts the query stream with the primary base table.
Step 2: Apply a time filter
Such as (where timestamp >= ago(1d))
Restricts the dataset to the last 24 hours immediately to optimize performance by reducing the scan size.
Step 3: Filter the failed requests
where success == false or resultCode checks
Narrows down rows to only failures before performing resource-heavy operations.
Step 4: Join the dependencies table
(join AppDependencies): Correlates the filtered request subset with dependency data using common tracking identifiers.
Step 5: Summarize average dependency duration by operation (summarize avg(duration) by operation) Computes the final aggregated metrics grouped by the operation name.
Reference:
https://learn.microsoft.com/en-us/azure/azure-monitor/logs/get-started-queries
NEW QUESTION # 56
Case Study 2 - Proseware Inc.
Background
Proseware Inc. develops AI-powered knowledge management solutions for enterprise customers.
The company is modernizing its platform to support semantic search, intelligent document retrieval, and real-time partner integrations.
The engineering team uses Python and Azure SDKs. The architecture is being redesigned to support containerized microservices, vector search workloads, and serverless backend processing.
Planned Application Architecture
Microservices are containerized by using Docker.
Code for containerized microservices and Azure Function apps is developed locally but stored in a GitHub repository.
Custom images for containerized microservices are stored in Azure Container Registry (ACR).
Base images are stored in Docker Hub. Custom images must be rebuilt automatically whenever their base images are updated.
Azure Cosmos DB for NoSQL stores documents, metadata, and vector embeddings.
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Azure Container Apps (ACA) apps host backend API services that provide semantic search across Azure Cosmos DB for NoSQL documents. API services process Service Bus messages and update search indexes.
Azure Kubernetes Service (AKS) processes batch vector embedding regeneration for existing Azure Cosmos DB for NoSQL documents (whenever the embedding model is changed).
An extranet-facing containerized webhook allows business partners to submit documents to be processed by internal AI workflows for semantic search and retrieval.
Monitoring
Telemetry generated by Azure resources is sent to Azure Monitor.
A Log Analytics workspace is used to collect ACA apps logs, AKS container logs, and Azure Functions apps logs.
Monitoring of Azure Functions is currently implemented by using Azure Application Insights SDK instrumentation.
Business Requirements
Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Backend API services must scale automatically during business hours.
Cold start delay of backend APIs must be minimized.
Secrets must be stored outside of container images.
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Azure Cosmos DB for NoSQL RU consumption must be minimized.
Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
The partner-facing containerized webhook service must run on Azure App Service.
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
Azure App Service must supply secrets at runtime without relying on external services.
Resources and workloads must be deployed by using Bicep templates through an automated, version-controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Known Issues
RU consumption spikes during vector similarity queries.
Drag and Drop Question
You need to configure event-driven scaling for the backend API services to meet the technical requirements.
Which settings should you use for each element? To answer, move the appropriate settings to the correct elements. You may use each setting once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Scenario, technical requirements.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Box 1: Azure Service Bus
Scaler TypeType
Set the scale rule type to custom.
KEDA Scaler Name: Set the type inside the custom specification block to azure-service-bus.
Box 2: messageCount
Trigger Metadata Values
The metadata block dictates how KEDA calculates the required replica count.
Configure the following core metadata parameters:
queueName: The explicit string name of your targeted Azure Service Bus
*-> queue.messageCount: The target integer threshold of concurrent pending messages assigned per replica (e.g., 5 or 10). KEDA uses this value to scale out systematically.
activationMessageCount: Set to 1 or 0. This defines the exact metric floor required to transition the container app out of a dormant state.
namespace: The canonical name of your Service Bus namespace
Box 3: 0
Min-Replicas ConfigurationValue
Set --min-replicas to 0.
Setting this value to zero enables full serverless cost efficiency. KEDA actively handles the background polling, allowing your backend API containers to scale down completely and run zero active replicas when the Service Bus queue contains zero pending messages.
Reference:
https://oneuptime.com/blog/post/2026-02-16-how-to-set-up-keda-based-auto-scaling-with-queue-triggers-in-azure-container-apps/view
NEW QUESTION # 57
You store embeddings in a property named embedding in an Azure Cosmos DB for NoSQL container.
You must retrieve the five most similar documents to an input embedding.
You need to construct the similarity query.
What should you do?
Answer: A
Explanation:
To retrieve the five most similar documents from Azure Cosmos DB for NoSQL using vector search, you must limit the number of results.
When performing vector similarity searches using the VectorDistance() function, you must restrict the output size directly in the query.
Reference:
https://stemhash.com/semantic-search-with-llms/
NEW QUESTION # 58
You manage an Azure Cosmos DB for a NoSQL API account named account1. The account contains a database named db1, which contains a container named container1. You configure account1 with a session consistency level.
You plan to develop an application named App1 that will access container1. Individual instances of App1 must perform reads and writes. App1 must allow multiple nodes to participate in the same session.
You need to configure an object to share the session token between the nodes.
Which object should you use?
Answer: A
NEW QUESTION # 59
You are developing a microservices-based application that uses Azure Container Apps. The application consists of several containerized services that handle tasks, such as processing orders, managing inventory, and generating reports.
Report generation must be implemented as follows:
Process reports every Sunday at midnight.
Minimize app resources during report generation.
Record metrics in the same location as other containers.
Use the same virtual network as other containers.
Answer:
Explanation:
Explanation:
NEW QUESTION # 60
......
Do some fresh things each day that moves you out of your comfort zone. If you stay cozy every day, you will gradually become lazy. Now, you have the opportunity to change your current conditions. Our AI-200 real exam dumps are specially prepared for you. Try our AI-200 study tool and absorb new knowledge. After a period of learning, you will find that you are making progress. The knowledge you have studied on our AI-200 Exam Question will enrich your life and make you wise. Our AI-200 real exam dumps are manufactured carefully, which could endure the test of practice. Stable and healthy development is our long lasting pursuit. In order to avoid fake products, we strongly advise you to purchase our AI-200 exam question on our official website.
AI-200 Exam Introduction: https://www.trainingdumps.com/AI-200_exam-valid-dumps.html
BTW, DOWNLOAD part of TrainingDumps AI-200 dumps from Cloud Storage: https://drive.google.com/open?id=1-2083pW4UgnUu3W0NckYbupBJcLk_W_Z