Perhaps your ability cannot meet the requirement of a high salary job. So you cannot get the job because of lack of ability. You must really want to improve yourself. Now, our Databricks-Certified-Professional-Data-Engineer exam questions can help you realize your dreams. Not only our Databricks-Certified-Professional-Data-Engineer study braindumps can help you obtain the most helpful knowledge and skills to let you stand out by solving the probleme the others can't, but also our Databricks-Certified-Professional-Data-Engineer praparation guide can help you get the certification for sure.
| Section | Weight | Objectives |
|---|---|---|
| Data Ingestion & Acquisition | 7% | - Schema inference and evolution - Auto Loader and streaming ingestion - Connecting to diverse data sources |
| Developing Code for Data Processing using Python and SQL | 22% | - Data transformation and aggregation - Integration with Databricks APIs and tools - Batch and incremental processing logic |
| Data Modelling | 6% | - Schema design and management - Medallion Architecture implementation - Delta Lake table design |
| Data Sharing and Federation | 5% | - Unity Catalog data sharing - Cross-workspace and cross-cloud access |
| Data Transformation, Cleansing, and Quality | 10% | - Data validation and quality checks - Handling missing or inconsistent data - Standardization and normalization |
| Ensuring Data Security and Compliance | 10% | - Compliance standards implementation - Data encryption and masking - Access control and permissions |
| Data Governance | 7% | - Unity Catalog management - Data lineage and metadata tracking - Policy enforcement |
| Monitoring and Alerting | 10% | - Setting up alerts and notifications - Performance and health monitoring - Pipeline observability and logging |
| Debugging and Deploying | 10% | - Deployment using bundles, CLI, and APIs - Troubleshooting pipelines and errors - CI/CD and DevOps practices |
| Cost & Performance Optimisation | 13% | - Query optimization and caching - Cluster configuration and scaling - Storage optimization (partitioning, Z-order, indexing) |
>> Databricks-Certified-Professional-Data-Engineer New Study Notes <<
If you want to have a general review of what you have learned, you can choose us. Databricks-Certified-Professional-Data-Engineer Online test engine has testing history and performance review, and it can help you have a general review of what you have learnt last time. Besides Databricks-Certified-Professional-Data-Engineer Online test engine support all web browsers, and it is convenient and easy to learn, and you can have offline practice if you like. Databricks-Certified-Professional-Data-Engineer Training Materials are high quality and you can pass the exam just one time if you choose us. We offer you free update for one year, and the update version for Databricks-Certified-Professional-Data-Engineer exam dumps will be sent to your email automatically.
NEW QUESTION # 214
How are Delt tables stored?
Answer: C
Explanation:
Explanation
The answer is A Directory where parquet data files are stored, a sub directory _delta_log where meta data, and the transaction log is stored as JSON files.
Timeline Description automatically generated
NEW QUESTION # 215
Review the following error traceback: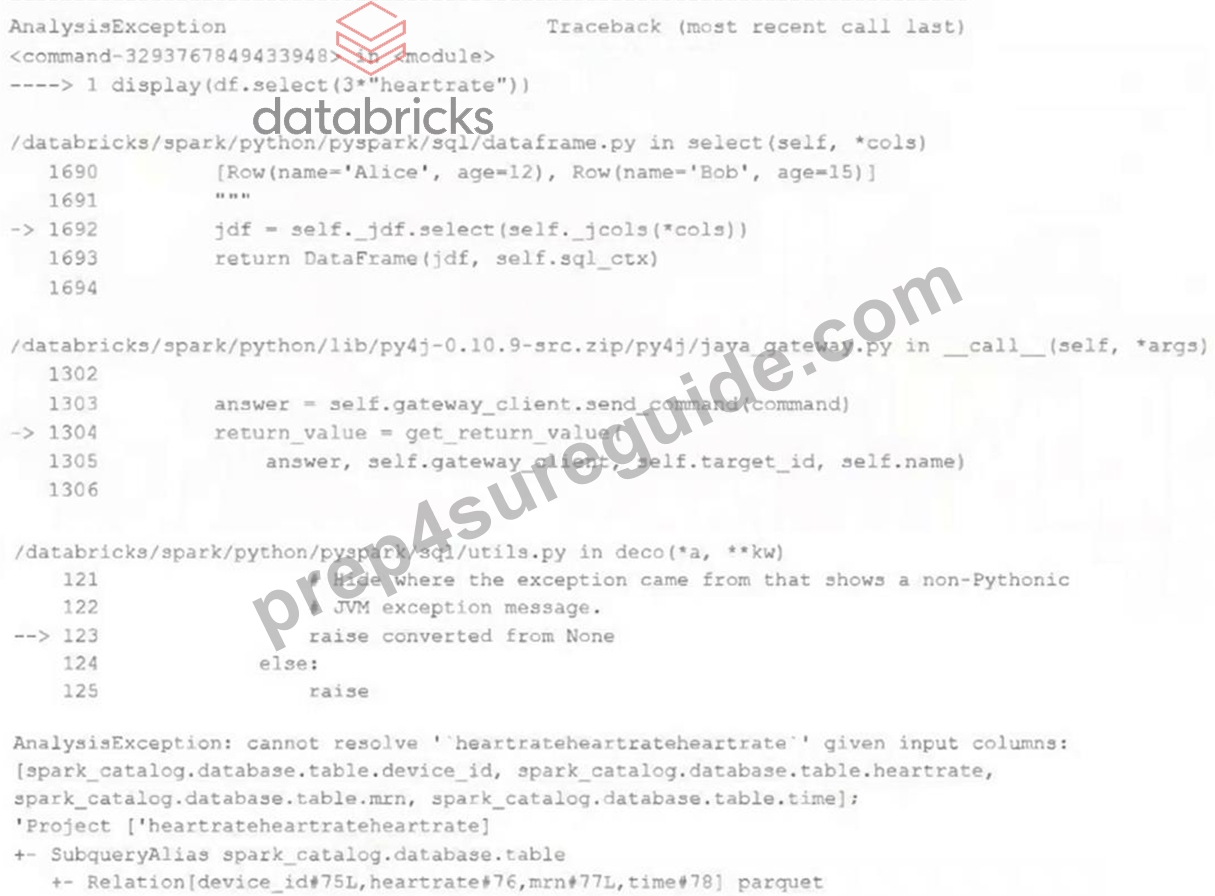
Which statement describes the error being raised?
Answer: C
Explanation:
Explanation
The error is a Py4JJavaError, which means that an exception was thrown in Java code called by Python code using Py4J. Py4J is a library that enables Python programs to dynamically access Java objects in a Java Virtual Machine (JVM). PySpark uses Py4J to communicate with Spark's JVM-based engine. The error message shows that the exception was thrown by org.apache.spark.sql.AnalysisException, which means that an error occurred during the analysis phase of Spark SQL query processing. The error message also shows that the cause of the exception was "cannot resolve 'heartrateheartrateheartrate' given input columns". This means that Spark could not find a column named heartrateheartrateheartrate in the input DataFrame or Dataset. The reason for this error is that there is a syntax error in the code that caused this exception. The code is:
df.withColumn("heartrate", heartrate * 3)
The code tries to create a new column called heartrate by multiplying an existing column called heartrate by 3.
However, the code does not correctly identify the heartrate column as a column object, but rather as a plain Python variable. This causes PySpark to concatenate the variable name with itself three times, resulting in heartrateheartrateheartrate, which is not a valid column name. To fix this error, the code should use one of the following ways to identify the heartrate column as a column object:
df.withColumn("heartrate", df["heartrate"] * 3) df.withColumn("heartrate", df.heartrate * 3) df.withColumn("heartrate", col("heartrate") * 3) Verified References: [Databricks Certified Data Engineer Professional], under "Spark Core" section; Py4J Documentation, under "What is Py4J?"; Databricks Documentation, under "Query plans - Analysis phase"; Databricks Documentation, under "Accessing columns".
NEW QUESTION # 216
An hourly batch job is configured to ingest data files from a cloud object storage container where each batch represent all records produced by the source system in a given hour. The batch job to process these records into the Lakehouse is sufficiently delayed to ensure no late-arriving data is missed. Theuser_idfield represents a unique key for the data, which has the following schema:
user_id BIGINT, username STRING, user_utc STRING, user_region STRING, last_login BIGINT, auto_pay BOOLEAN, last_updated BIGINT New records are all ingested into a table namedaccount_historywhich maintains a full record of all data in the same schema as the source. The next table in the system is namedaccount_currentand is implemented as a Type 1 table representing the most recent value for each uniqueuser_id.
Assuming there are millions of user accounts and tens of thousands of records processed hourly, which implementation can be used to efficiently update the describedaccount_currenttable as part of each hourly batch job?
Answer: B
Explanation:
This is the correct answer because it efficiently updates the account current table with only the most recent value for each user id. The code filters records in account history using the last updated field and the most recent hour processed, which means it will only process the latest batch of data. It also filters by the max last login by user id, which means it will only keep the most recent record for each user id within that batch. Then, it writes a merge statement to update or insert the most recent value for each user id into account current, which means it will perform an upsert operation based on the user id column. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Upsert into a table using merge" section.
NEW QUESTION # 217
A data engineer is attempting to execute the following PySpark code:
df = spark.read.table("sales")
result = df.groupBy("region").agg(sum("revenue"))
However, upon inspecting the execution plan and profiling the Spark job, they observe excessive data shuffling during the aggregation phase.
Which technique should be applied to reduce shuffling during the groupBy aggregation operation?
Answer: A
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
Databricks documents that shuffle occurs when Spark redistributes data across partitions for grouping or joining. To optimize aggregation performance, repartitioning by the grouping key (region) ensures rows with the same key are co-located in the same partition, thus minimizing shuffle movement. Caching improves reuse of DataFrames but does not reduce shuffle volume. coalesce() reduces the number of partitions after computation and cannot prevent shuffle. Broadcast joins are unrelated to single-table aggregations. The recommended practice for reducing shuffle in aggregation is explicit repartitioning by the grouping column.
NEW QUESTION # 218
Which statement regarding stream-static joins and static Delta tables is correct?
Answer: A
Explanation:
This is the correct answer because stream-static joins are supported by Structured Streaming when one of the tables is a static Delta table. A static Delta table is a Delta table that is not updated by any concurrent writes, such as appends or merges, during the execution of a streaming query. In this case, each microbatch of a stream-static join will use the most recent version of the static Delta table as of each microbatch, which means it will reflect any changes made to the static Delta table before the start of each microbatch. Verified References: [Databricks Certified Data Engineer Professional], under "Structured Streaming" section; Databricks Documentation, under "Stream and static joins" section.
NEW QUESTION # 219
......
If you have the Databricks-Certified-Professional-Data-Engineer certification, it will be very easy for you to achieve your dream. But it is not an easy thing for many candidates to pass the Databricks-Certified-Professional-Data-Engineer exam. By chance, our company can help you solve the problem and get your certification, because our company has compiled the Databricks-Certified-Professional-Data-Engineer question torrent that not only have high quality but also have high pass rate. We believe that our Databricks-Certified-Professional-Data-Engineer exam questions will help you get the certification in the shortest. So hurry to buy our Databricks-Certified-Professional-Data-Engineer exam torrent, you will like our products.
Databricks-Certified-Professional-Data-Engineer Pdf Torrent: https://www.prep4sureguide.com/Databricks-Certified-Professional-Data-Engineer-prep4sure-exam-guide.html