Wenn Sie ExamFragen wählen, versprechen wir Ihnen eine 100%-Pass-Garantie zur Microsoft DP-750 Zertifizierungsprüfung. Sonst erstatteten wir Ihnen Ihre an uns geleisteten Zahlung.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
| Topic 2: Set up and configure an Azure Databricks environment | 15–20% | - Integrate with Azure services
|
| Topic 3: Prepare and process data | 30–35% | - Ingest and transform data
|
| Topic 4: Secure and govern Unity Catalog objects | 15–20% | - Manage data sharing and permissions
|
Machen Sie sich noch Sorge darum, dass Sie keine enchten und zuversichtlichen Schulungsunterlagen zur Microsoft DP-750 Zertifizierungsprüfung finden können? Schulungsunterlagen zur Microsoft DP-750 Zertifizierungsprüfung aus ExamFragen sind von den erfahrenen IT-Experten zusammengechlossen, sie sind kombniert von Fragen und Antworten, daher sind sie nicht vergleichbar. Ihre Genauigkeit ist auch zweifellos. Wählen Sie ExamFragen, dann wählen Sie Erfolg.
63. Frage
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes numerical data to a table named Table1 by using a data quality validation rule named rule1.
You need to modify rule1 to meet the following requirements:
Ensure that amount is always greater than 0.
Prevent an update to Table1 from being committed when data that violates rule1 is detected.
Which statement should you execute?
Antwort: D
Begründung:
The correct answer is C - @dlt.expect_or_fail.
Lakeflow Spark Declarative Pipelines (SDP) offers three expectation decorators, each with a different violation response:
@dlt.expect - logs the violation as a metric but writes all records, including bad ones, to the table. Suitable for monitoring only.
@dlt.expect_or_drop - drops violating records and continues the pipeline. The table receives only clean rows, but the pipeline update commits successfully.
@dlt.expect_or_fail - fails the entire pipeline update when a violation is detected. The table update is never committed. This is the correct choice when data integrity is non-negotiable: 'Prevent an update to Table1 from being committed when data that violates rule1 is detected.'
@dlt.expect_all_or_drop takes a dictionary of rules and drops violating rows but still commits - it doesn't halt the pipeline.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/expectations
64. Frage
You have an Azure Databricks workspace.
You have an Apache Spark Structured Streaming job named Job1 that processes data continuously and fails periodically due to transient errors.
You need to ensure that Job1 meets the following requirements:
- Resumes processing from the point that Job1 failed
- Minimizes how long it takes to restart Job1
- Minimizes the costs to restart Job1
What should you do?
Antwort: B
Begründung:
You must use checkpointing.
Checkpointing is the native Apache Spark mechanism designed specifically to handle failures in Structured Streaming jobs. It saves the exact execution state and progress to cloud storage (like Azure Data Lake Storage), allowing the job to resume precisely where it left off without data loss.
Resumes from Failure Point: The checkpoint directory stores the stream offsets. When restarted, Spark reads these offsets to pick up exactly where it failed.
Minimizes Restart Time: By saving the state, Spark does not need to recompute historical streaming data or re-evaluate the entire stream architecture from scratch.
Minimizes Restart Costs: It prevents the reprocessing of duplicate data, saving valuable cluster compute time and reducing cloud infrastructure costs.
Reference:
https://www.linkedin.com/posts/shilpa-das-ln_what-is-checkpointing-in-spark-checkpointing- activity-7297113790393815041-AhPg
65. Frage
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes numerical data to a Delta table named Table1 Table1 stores order data and contains two columns named Ordertd and Quantity that have the following requirements:
* Orderld must always be present.
* Quantity must be greater than 0.
You need to enforce the requirements during ingestion by using validation checks. The solution must evaluate each record independently and minimize custom code.
What should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Antwort:
Begründung:
Explanation:
Lakeflow pipeline expectations provide declarative row-level data-quality validation. An expectation uses a SQL Boolean expression that is evaluated independently for every record passing through the pipeline. This minimizes custom code because the required validation can be expressed directly as a constraint rather than implemented through a separate validation process or custom function. Microsoft Learn The correct expression is OrderId IS NOT NULL AND Quantity > 0. The first condition enforces the requirement that every order record contains an OrderId. The second condition ensures that Quantity is strictly greater than zero. OrderId > 0 would impose an additional numeric-range requirement that the question does not specify. Checking only Quantity > 0 would fail to validate the required presence of OrderId. Checking Quantity IS NOT NULL AND OrderId > 0 reverses the stated requirements.
Aggregate checks operate across collections of records rather than validating each record independently.
Schema inference determines data structure and types but does not enforce these business-value requirements.
Therefore, a row-level validation check containing both required conditions is the correct solution.
66. Frage
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job1 runs every hour.
Occasionally, Job1 takes longer than one hour to complete.
You need to configure the job scheduling behavior to meet the following requirements:
* Overlapping runs must be prevented to avoid data corruption.
* Scheduled runs must not be discarded when another run is already active.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.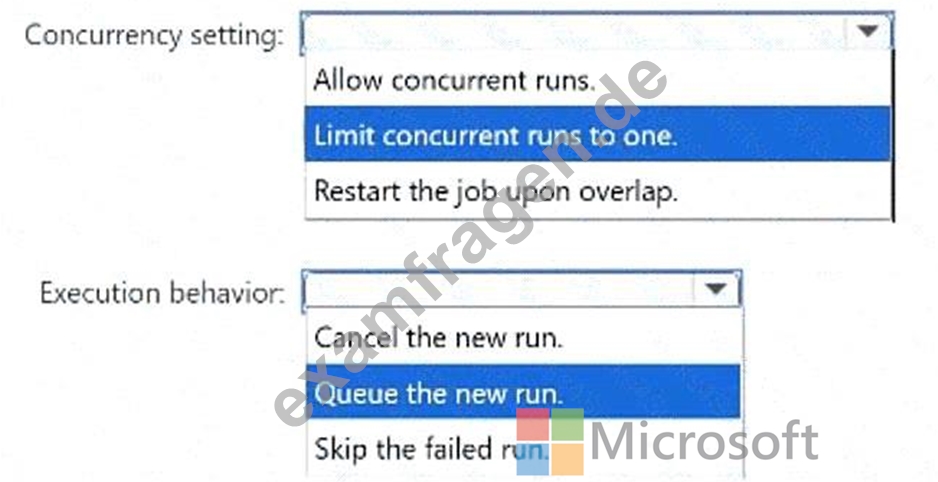
Antwort:
Begründung: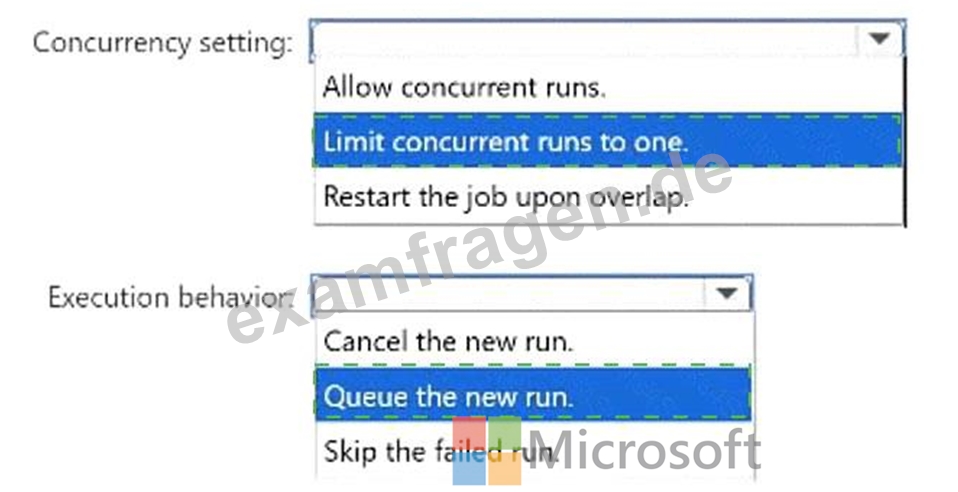
Explanation:
Concurrency setting: Limit concurrent runs to one.
Execution behavior: Queue the new run.
Limiting concurrent runs to one ensures that only one instance of Job1 can execute at a time. This prevents two hourly runs from simultaneously modifying the same tables, files, checkpoints, or downstream systems, thereby reducing the risk of duplicate processing and data corruption. When a scheduled trigger occurs while an earlier execution is still active, queueing the new run preserves that execution and starts it after the active run finishes. Allowing concurrent runs would violate the non-overlap requirement. Restarting the job during an overlap could interrupt partially completed work. Canceling the new run or skipping it would avoid simultaneous execution, but the scheduled processing interval could be lost. Single-run concurrency combined with queueing therefore serializes the executions without discarding scheduled work.
67. Frage
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to recommend a pipeline that ingests files from cloud storage, performs cleansing and enrichment transformations, and writes created Delta tables for analytics. The solution must minimize development effort and provide built-in monitoring and automatic retries.
What should you include in the recommendation?
Antwort: D
Begründung:
The correct answer is C - a Lakeflow Spark Declarative Pipelines (SDP) pipeline.
SDP is tailor-made for exactly this pattern: ingest from cloud storage, transform through cleansing and enrichment stages, and publish Delta tables to Unity Catalog. What sets it apart from the other options is built- in monitoring (the pipeline graph shows row counts, expectation metrics, and run history) and automatic retries (failed tasks retry automatically based on pipeline settings, without manual re-run triggers).
Option A (Structured Streaming job) gives you the streaming engine but nothing else - monitoring, alerting, and retry logic all have to be built from scratch. Option B (scheduled notebook job) is a batch approach that requires manual monitoring and lacks the declarative lineage tracking SDP provides. Option D (Azure Data Factory with data flows) works but adds a separate Azure service to manage, introduces ADF licensing costs, and doesn ' t integrate natively with Unity Catalog governance.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/what-is-delta-live-tables
68. Frage
......
Die Microsoft Zertifizierungen sind heute immer mehr populär, weil diese international anerkannt sind. Deshalb nehmen immer mehr Leute Microsoft an Zertifizierungsprüfungen teil. Darunter ist die Microsoft DP-750 Prüfung eine der wichtigsten Prüfungen. Und, Wie können Sie sich auf die Microsoft DP-750 Prüfung vorbereiten? Lernen alle Kenntnisse sehr fleißig auswendig? Oder Benutzen die hocheffektiven Prüfungsunterlagen?
DP-750 Testking: https://www.examfragen.de/DP-750-pruefung-fragen.html