Most experts agree that the best time to ask for more dough is after you feel your DP-750 performance has really stood out. Our DP-750 guide materials provide such a learning system where you can improve your study efficiency to a great extent. During the process of using our DP-750 Study Materials, you focus yourself on the exam bank within the given time, and we will refer to the real exam time to set your DP-750 practice time, which will make you feel the actual DP-750 exam environment and build up confidence.
| Section | Weight | Objectives |
|---|---|---|
| Prepare and process data | 30-35% | - Ingest and transform data
|
| Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
>> Valid Test DP-750 Vce Free <<
Nobody wants to be stranded in the same position in his or her company. And nobody wants to be a normal person forever. Maybe you want to get the DP-750 certification, but daily work and long-time traffic make you busier to improve yourself. However, there is a piece of good news for you. Thanks to our DP-750 Training Materials, you can learn for your DP-750 certification anytime, everywhere. And you will be bound to pass the exam with our DP-750 exam questions.
NEW QUESTION # 31
What is the best way to reduce Databricks compute cost for intermittent workloads?
Answer: A
Explanation:
Autoscaling adjusts resources based on workload demand, and auto-termination shuts down idle clusters, reducing cost significantly. All-purpose clusters are always on. Increasing size raises cost. Single-node clusters limit scalability and are not suitable for production workloads.
NEW QUESTION # 32
Case Study 1 - Contoso, Inc.
Overview
Company Information
Contoso, Inc. is a renewable energy provider that operates solar and wind farms across North America.
Existing Environment
Azure Environment
Contoso has a single Azure Databricks workspace named Workspace1 in the West US Azure region. Workspace1 is enabled for Unity Catalog.
Workspace1 contains all-purpose clusters for both development and production workloads.
The company's Azure environment contains:
- In the West US, Central US, and East US Azure regions, Azure event hubs that stream telemetry data and an Azure Data Lake Storage Gen2 account in each region for each hub
- A single Azure SQL database in the West US region that hosts enterprise resource planning (ERP) data
- An Azure Database for PostgreSQL server in the West US region that stores operational maintenance data Data Environment Contoso ingests the following operational and business data:
- Telemetry data: More than 40,000 IoT sensors across 28 sites emit JSON telemetry events every few seconds. Each site sends the events to the nearest event hub, which writes the data into the corresponding Data Lake Storage Gen2 account. These files frequently experience schema drift.
- Maintenance logs: Maintenance systems generate historical repair logs, daily incremental updates, technician notes, and unstructured attachments that are stored in the Data Lake Storage Gen2 accounts.
- Operational maintenance data: Structured operational maintenance data is stored on the Azure Database for PostgreSQL server.
- External weather data: Hourly weather forecasts are retrieved from a REST API and written to the Data Lake Storage Gen2 accounts.
- ERP data: Daily CSV extracts of 50 to 100 GB contain equipment metadata, work orders, and purchase order information.
Problem Statements
The company's existing analytics environment has several issues:
Ingestion
- Telemetry pipelines fall behind during peak loads.
- Telemetry ingestion fails when schema drift occurs.
- Streaming pipelines reprocess events after a pipeline restarts.
Compute
Production and development workloads run on the same all-purpose clusters.
Production and development workloads do NOT support autoscaling or workload isolation.
Governance
- The ERP data is duplicated across systems and development teams.
- Naming conventions are inconsistent across development teams, regions, and products.
- Ownership of the IoT sensors changes over time, and analysts must track the full history of the ownership.
- Occasionally, equipment manufacturers must correct data-entry mistakes in equipment names.
Historical values are NOT required.
Pipeline operations
- Pipelines lack resiliency, alerting, and centralized scheduling.
Requirements
Planned Changes
Contoso plans to implement the following changes:
- Implement scalable data pipeline orchestration.
- Create a managed analytics catalog in Unity Catalog.
- Implement a consistent approach to creating curated datasets.
- Establish a centralized governance model across ingestion, cleansed, and curated layers.
- Grant data engineers access to the ERP tables by using minimal development effort.
- Adopt a compute strategy that isolates production workloads and supports autoscaling.
- Adopt a slowly changing dimension (SCD) approach to address current data modeling issues.
Technical Requirements
Contoso identifies the following environment and compute requirements:
- Ensure that production ingestion workloads run on compute clusters that can scale automatically during telemetry spikes.
- Provide fast and consistent performance for business intelligence (BI) workloads.
- Prevent development activity from affecting production pipelines.
- Production ingestion workloads must run as scheduled, non-interactive pipelines rather than on shared interactive development clusters.
Contoso identifies the following data ingestion and processing requirements:
- Auto-scale ingestion pipelines to handle bursty workloads.
- Handle schema drift for the maintenance and telemetry data.
- Ingest file-based telemetry data by using minimal operational effort.
- Store all the ingested data in a format that supports incremental processing.
- Support the continuous ingestion of telemetry data from the event hubs by using exactly-once semantics.
- Support the ingestion of the structured maintenance data from the Azure Database for PostgreSQL server.
- Build a new telemetry pipeline that ingests raw events from the event hubs, cleanses the data, and publishes curated tables to Unity Catalog.
- Ensure that the Apache Spark Structured Streaming pipelines reading from the event hubs write the data into a managed Delta table named telemetry.raw_events. The pipelines must support schema drift and resume processing after failures without reprocessing the data.
Contoso identifies the following data modeling and optimization requirements:
- Build curated tables that standardize business logic.
- Overwrite equipment metadata attributes, such as name, manufacturer, model, and commissioning date, when the attributes change. Historical values are NOT required.
Contoso identifies the following pipeline deployment and operation requirements:
- Orchestrate multi-step ingestion and transformation workflows.
- Define a clear execution order and dependencies.
- Automatically retry failed steps and notify operators.
- Schedule ingestion and transformation workloads consistently.
Governance Requirements
Contoso identifies the following governance requirements:
- Centralize the metadata catalog.
- Provide isolated development areas that follow standard naming conventions.
- Establish a consistent structure for organizing raw, cleansed, and curated data.
- Provide a read-only mechanism to reference the ERP data through a foreign catalog.
Business Requirements
Contoso identifies the following business requirements:
- Improve ingestion reliability and reduce operational effort.
- Standardize data definitions across development teams.
Hotspot Question
You need to complete the PySpark code for the Spark Structured Streaming pipelines. The solution must meet the data ingestion and processing requirements.
How should you complete the code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.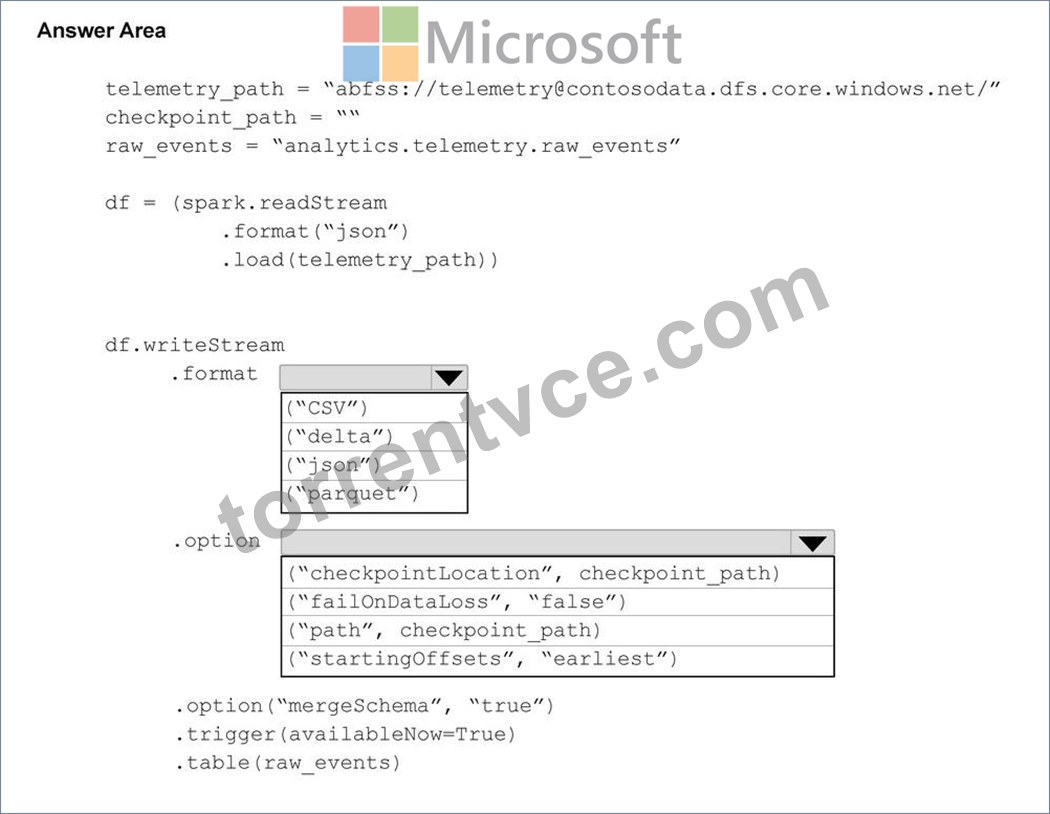
Answer:
Explanation: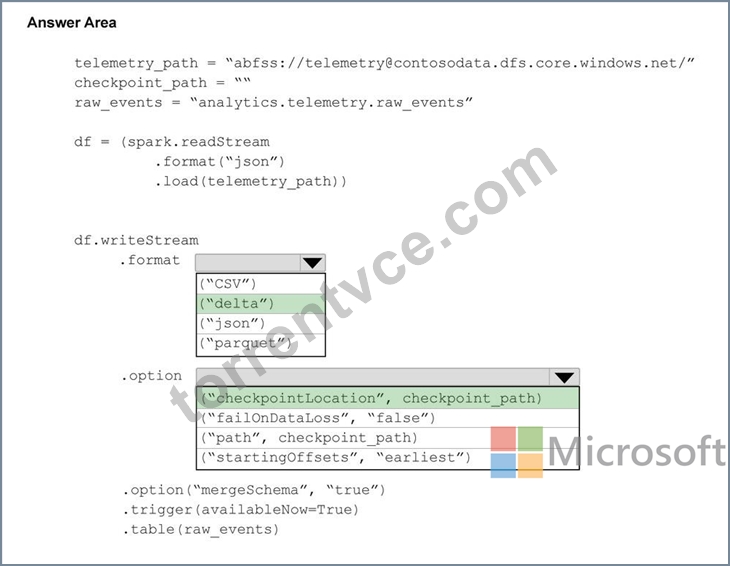
NEW QUESTION # 33
You have an Azure Databticks workspace that is enabled for Unity Catalog and contains a catalog named catalog1.
You have a group named group!
You plan to create a schema named schema1 in catalog1.
You need to ensure that group1 meets the following requirements:
* Can create tables in schema1
* Can modify and query tables
* Cannot grant permissions for the schema and its objects
How should you complete the SQL statements? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.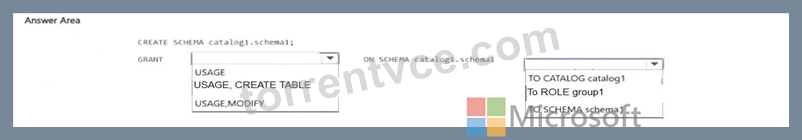
Answer:
Explanation: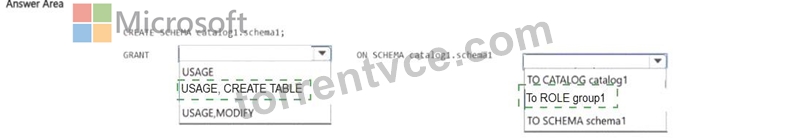
Explanation:
The correct SQL grants group1 the ability to work within the schema without delegating that ability to anyone else:
GRANT USE SCHEMA ON schema1 TO group1 - required as a prerequisite to access any object inside the schema.
GRANT CREATE TABLE ON SCHEMA schema1 TO group1 - allows creating new tables.
GRANT SELECT, MODIFY ON SCHEMA schema1 TO group1 - SELECT for queries, MODIFY for INSERT/UPDATE/DELETE operations.
Crucially, MANAGE is NOT granted. In Unity Catalog, MANAGE is what allows a principal to grant and revoke privileges on the schema and its objects. Leaving it out means group1 can do all the data work but cannot redistribute those permissions - precisely what the requirement 'Cannot grant permissions for the schema and its objects' demands.
Reference: https://learn.microsoft.com/en-us/azure/databricks/data-governance/unity-catalog/manage- privileges/privileges
NEW QUESTION # 34
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a complex job named Job1 that contains eight tasks. Job1 takes multiple hours to complete.
During the last job run, the final task fails due to a transient issue.
You need to retry the last task without rerunning tasks that have already completed.
What should you do?
Answer: C
Explanation:
Repairing the current job run allows Lakeflow Jobs to rerun the failed task while preserving the successful status of tasks that already completed. This prevents several hours of successful processing from being repeated and reduces both recovery time and compute consumption. If downstream tasks had been skipped because of the failure, they can also be included in the repair operation as appropriate. Updating job parameters changes configuration but does not retry the failed task in the existing run. Restarting Job1 creates a new run and ordinarily executes the workflow again from its beginning. Disabling and reenabling the schedule only changes whether future scheduled runs can start; it does not repair the failed execution. Repair Run is specifically designed for recovering selected failed or skipped tasks in a multi-task workflow.
NEW QUESTION # 35
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to recommend a pipeline that ingests files from cloud storage, performs cleansing and enrichment transformations, and writes created Delta tables for analytics. The solution must minimize development effort and provide built-in monitoring and automatic retries.
What should you include in the recommendation?
Answer: B
Explanation:
The correct answer is C - a Lakeflow Spark Declarative Pipelines (SDP) pipeline.
SDP is tailor-made for exactly this pattern: ingest from cloud storage, transform through cleansing and enrichment stages, and publish Delta tables to Unity Catalog. What sets it apart from the other options is built- in monitoring (the pipeline graph shows row counts, expectation metrics, and run history) and automatic retries (failed tasks retry automatically based on pipeline settings, without manual re-run triggers).
Option A (Structured Streaming job) gives you the streaming engine but nothing else - monitoring, alerting, and retry logic all have to be built from scratch. Option B (scheduled notebook job) is a batch approach that requires manual monitoring and lacks the declarative lineage tracking SDP provides. Option D (Azure Data Factory with data flows) works but adds a separate Azure service to manage, introduces ADF licensing costs, and doesn't integrate natively with Unity Catalog governance.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/what-is-delta-live-tables
NEW QUESTION # 36
......
The earlier you get DP-750 exam certification, the more helpful for you to have better development in IT industry. Maybe you have heard that the important DP-750 exam will take more time or training fee, because you haven't use our DP-750 exam software provided by our TorrentVCE. The complex collection and analysis of DP-750 Exam Materials have been finished by our professional team for you. You just need to effectively review and pass DP-750 exam successfully.
Reliable DP-750 Test Online: https://www.torrentvce.com/DP-750-valid-vce-collection.html