New Databricks-Certified-Professional-Data-Engineer Test Review & Best Databricks-Certified-Professional-Data-Engineer Practice

Are you still hesitating about which kind of Databricks-Certified-Professional-Data-Engineer exam torrent should you choose to prepare for the exam in order to get the related certification at ease? I am glad to introduce our Databricks-Certified-Professional-Data-Engineer study materials to you. Our company has already become a famous brand all over the world in this field since we have engaged in compiling the Databricks-Certified-Professional-Data-Engineer practice materials for more than ten years and have got a fruitful outcome. In order to let you have a general idea about our Databricks-Certified-Professional-Data-Engineer training materials, we have prepared the free demo in our website for you to download.
Databricks Certified Professional Data Engineer (Databricks-Certified-Professional-Data-Engineer) certification exam is designed for data professionals who want to validate their skills and knowledge in building and deploying data engineering solutions using Databricks. Databricks is a unified data analytics platform that provides a collaborative environment for data engineers, data scientists, and business analysts to work together on big data projects. Databricks Certified Professional Data Engineer Exam certification exam covers a range of topics such as data ingestion, data processing, data transformation, and data storage using Databricks.
Databricks Certified Professional Data Engineer exam is a valuable certification for professionals who want to showcase their expertise in big data processing using Databricks. Databricks Certified Professional Data Engineer Exam certification demonstrates that the candidate has the necessary skills and knowledge to design and implement scalable data pipelines using Databricks. Databricks Certified Professional Data Engineer Exam certification also provides a competitive advantage to professionals in the job market and opens up new career opportunities in the field of big data engineering.
>> New Databricks-Certified-Professional-Data-Engineer Test Review <<
Best Databricks-Certified-Professional-Data-Engineer Practice & Databricks-Certified-Professional-Data-Engineer Trustworthy Pdf
Databricks PDF Questions format, web-based practice test, and desktop-based Databricks-Certified-Professional-Data-Engineer practice test formats. All these three Databricks-Certified-Professional-Data-Engineer exam dumps formats features surely will help you in preparation and boost your confidence to pass the challenging Databricks Databricks-Certified-Professional-Data-Engineer Exam with good scores.
Databricks Certified Professional Data Engineer exam is an excellent choice for data engineers who want to demonstrate their expertise in using Databricks to process big data. Databricks Certified Professional Data Engineer Exam certification exam is recognized globally and highly valued by organizations that use Databricks for their big data processing needs. By passing the exam, data engineers can validate their knowledge and skills and increase their chances of career advancement.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q100-Q105):
NEW QUESTION # 100
A data engineer has ingested data from an external source into a PySpark DataFrame raw_df. They need to
briefly make this data available in SQL for a data analyst to perform a quality assurance check on the data.
Which of the following commands should the data engineer run to make this data available in SQL for only
the remainder of the Spark session?
- A. raw_df.createTable("raw_df")
- B. raw_df.saveAsTable("raw_df")
- C. There is no way to share data between PySpark and SQL
- D. raw_df.write.save("raw_df")
- E. raw_df.createOrReplaceTempView("raw_df")
Answer: E
NEW QUESTION # 101
Which of the following technologies can be used to identify key areas of text when parsing Spark Driver log4j output?
- A. pyspsark.ml.feature
- B. Julia
- C. C++
- D. Scala Datasets
- E. Regex
Answer: E
Explanation:
Regex, or regular expressions, are a powerful way of matching patterns in text. They can be used to identify key areas of text when parsing Spark Driver log4j output, such as the log level, the timestamp, the thread name, the class name, the method name, and the message. Regex can be applied in various languages and frameworks, such as Scala, Python, Java, Spark SQL, and Databricks notebooks. References:
* https://docs.databricks.com/notebooks/notebooks-use.html#use-regular-expressions
* https://docs.databricks.com/spark/latest/spark-sql/udf-scala.html#using-regular-expressions-in-udfs
* https://docs.databricks.com/spark/latest/sparkr/functions/regexp_extract.html
* https://docs.databricks.com/spark/latest/sparkr/functions/regexp_replace.html
NEW QUESTION # 102
if you run the command VACUUM transactions retain 0 hours? What is the outcome of this command?
- A. Command runs successful and compacts all of the data in the table
- B. Command will be successful, but no data is removed
- C. Command will fail if you have an active transaction running
- D. Command will be successful, but historical data will be removed
- E. Command will fail, you cannot run the command with retentionDurationcheck enabled
Answer: E
Explanation:
Explanation
The answer is,
Command will fail, you cannot run the command with retentionDurationcheck enabled.
1.VACUUM [ [db_name.]table_name | path] [RETAIN num HOURS] [DRY RUN]
*Recursively vacuum directories associated with the Delta table and remove data files that are no longer in the latest state of the transaction log for the table and are older than a retention threshold. Default is 7 Days.
*The reason this check is enabled is because, DELTA is trying to prevent unintentional deletion of history, and also one important thing to point out is with 0 hours of retention there is a possibility of data loss(see below kb) Documentation in VACUUM https://docs.delta.io/latest/delta-utility.html
https://kb.databricks.com/delta/data-missing-vacuum-parallel-write.html
NEW QUESTION # 103
Which of the following describes a benefit of a data lakehouse that is unavailable in a traditional data
warehouse?
- A. A data lakehouse couples storage and compute for complete control
- B. A data lakehouse captures snapshots of data for version control purposes
- C. A data lakehouse utilizes proprietary storage formats for data
- D. A data lakehouse provides a relational system of data management
- E. A data lakehouse enables both batch and streaming analytics
Answer: E
NEW QUESTION # 104
A member of the data engineering team has submitted a short notebook that they wish to schedule as part of a larger data pipeline. Assume that the commands provided below produce the logically correct results when run as presented.
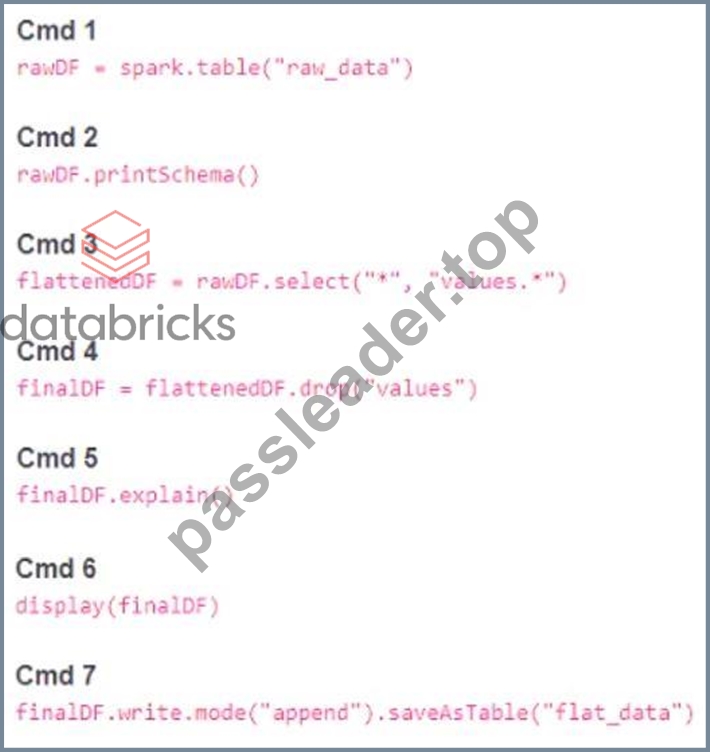
Which command should be removed from the notebook before scheduling it as a job?
- A. Cmd 6
- B. Cmd 3
- C. Cmd 4
- D. Cmd 2
- E. Cmd 5
Answer: A
Explanation:
Explanation
Cmd 6 is the command that should be removed from the notebook before scheduling it as a job. This command is selecting all the columns from the finalDF dataframe and displaying them in the notebook. This is not necessary for the job, as the finalDF dataframe is already written to a table in Cmd 7. Displaying the dataframe in the notebook will only consume resources and time, and it will not affect the output of the job.
Therefore, Cmd 6 is redundant and should be removed.
The other commands are essential for the job, as they perform the following tasks:
Cmd 1: Reads the raw_data table into a Spark dataframe called rawDF.
Cmd 2: Prints the schema of the rawDF dataframe, which is useful for debugging and understanding the data structure.
Cmd 3: Selects all the columns from the rawDF dataframe, as well as the nested columns from the values struct column, and creates a new dataframe called flattenedDF.
Cmd 4: Drops the values column from the flattenedDF dataframe, as it is no longer needed after flattening, and creates a new dataframe called finalDF.
Cmd 5: Explains the physical plan of the finalDF dataframe, which is useful for optimizing and tuning the performance of the job.
Cmd 7: Writes the finalDF dataframe to a table called flat_data, using the append mode to add new data to the existing table.
NEW QUESTION # 105
......
Best Databricks-Certified-Professional-Data-Engineer Practice: https://www.passleader.top/Databricks/Databricks-Certified-Professional-Data-Engineer-exam-braindumps.html
- Databricks Databricks-Certified-Professional-Data-Engineer Exam Questions 2026 in PDF Format ⏫ Copy URL ☀ www.examcollectionpass.com ️☀️ open and search for ( Databricks-Certified-Professional-Data-Engineer ) to download for free 🤪Study Databricks-Certified-Professional-Data-Engineer Reference
- Databricks-Certified-Professional-Data-Engineer Question Explanations 🌞 Exam Databricks-Certified-Professional-Data-Engineer Experience 🧉 Braindumps Databricks-Certified-Professional-Data-Engineer Torrent ↔ Search on “ www.pdfvce.com ” for ➤ Databricks-Certified-Professional-Data-Engineer ⮘ to obtain exam materials for free download 🧙Databricks-Certified-Professional-Data-Engineer Unlimited Exam Practice
- Don't Miss Up to 1 year of Free Updates – Buy Databricks-Certified-Professional-Data-Engineer Dumps Now 🥾 Search for { Databricks-Certified-Professional-Data-Engineer } on ▷ www.dumpsmaterials.com ◁ immediately to obtain a free download 😑Databricks-Certified-Professional-Data-Engineer Unlimited Exam Practice
- Frenquent Databricks-Certified-Professional-Data-Engineer Update 🦚 Braindumps Databricks-Certified-Professional-Data-Engineer Torrent 🔴 Databricks-Certified-Professional-Data-Engineer Valid Exam Format 🕤 Easily obtain free download of ✔ Databricks-Certified-Professional-Data-Engineer ️✔️ by searching on ⏩ www.pdfvce.com ⏪ 🍑Databricks-Certified-Professional-Data-Engineer Question Explanations
- Braindumps Databricks-Certified-Professional-Data-Engineer Torrent 🌰 Braindumps Databricks-Certified-Professional-Data-Engineer Torrent 😅 New Databricks-Certified-Professional-Data-Engineer Exam Prep ⬅️ Go to website [ www.prepawayete.com ] open and search for ➽ Databricks-Certified-Professional-Data-Engineer 🢪 to download for free ⤴Databricks-Certified-Professional-Data-Engineer New Exam Braindumps
- Pdfvce Is the Most Reliable Platform for Databricks Databricks-Certified-Professional-Data-Engineer Exam Preparation 💿 Easily obtain free download of ⏩ Databricks-Certified-Professional-Data-Engineer ⏪ by searching on ✔ www.pdfvce.com ️✔️ 🔖Databricks-Certified-Professional-Data-Engineer Valid Exam Format
- Don't Miss Up to 1 year of Free Updates – Buy Databricks-Certified-Professional-Data-Engineer Dumps Now 🐏 Search for 【 Databricks-Certified-Professional-Data-Engineer 】 and obtain a free download on [ www.troytecdumps.com ] ⏬Databricks-Certified-Professional-Data-Engineer Valid Exam Format
- Databricks-Certified-Professional-Data-Engineer Question Explanations 🥘 Study Databricks-Certified-Professional-Data-Engineer Reference 🕕 Databricks-Certified-Professional-Data-Engineer Questions Answers 🤜 Search for “ Databricks-Certified-Professional-Data-Engineer ” and obtain a free download on ⇛ www.pdfvce.com ⇚ 🤑New Databricks-Certified-Professional-Data-Engineer Exam Prep
- How Can You Avoid Wasting Your Money by Purchasing the Databricks Databricks-Certified-Professional-Data-Engineer Exam Questions? 📣 Search for ▶ Databricks-Certified-Professional-Data-Engineer ◀ and obtain a free download on { www.practicevce.com } 🎧New Databricks-Certified-Professional-Data-Engineer Exam Prep
- Databricks-Certified-Professional-Data-Engineer Question Explanations 👤 Frenquent Databricks-Certified-Professional-Data-Engineer Update 📫 Study Materials Databricks-Certified-Professional-Data-Engineer Review 🎈 Copy URL ⇛ www.pdfvce.com ⇚ open and search for ⇛ Databricks-Certified-Professional-Data-Engineer ⇚ to download for free 🕘New Databricks-Certified-Professional-Data-Engineer Exam Prep
- Don't Miss Up to 1 year of Free Updates – Buy Databricks-Certified-Professional-Data-Engineer Dumps Now 🩺 Simply search for ( Databricks-Certified-Professional-Data-Engineer ) for free download on ⇛ www.dumpsquestion.com ⇚ 🌶Sample Databricks-Certified-Professional-Data-Engineer Test Online
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes