BONUS!!! Download part of Fast2test MLA-C01 dumps for free: https://drive.google.com/open?id=1BEuLQKbPGjQK1aHkqyTAskhCXDXXiFul
Our MLA-C01 study materials are easy to be mastered and boost varied functions. We compile Our MLA-C01 preparation questions elaborately and provide the wonderful service to you thus you can get a good learning and preparation for the MLA-C01 exam. Now there are introduces on the web for you to know the characteristics and functions of our MLA-C01 Training Materials in detail. And we also have free demo on the web for you to have a try on our MLA-C01 exam questions. You will be touched by our great quality of MLA-C01 study guide.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
>> Pass4sure MLA-C01 Exam Prep <<
We provide updated and real Amazon MLA-C01 exam questions that are sufficient to clear the AWS Certified Machine Learning Engineer - Associate (MLA-C01) exam in one go. The product of Fast2test is created by seasoned professionals and is frequently updated to reflect changes in the content of the MLA-C01 Exam Questions.
NEW QUESTION # 118
A company wants to build a real-time analytics application that uses streaming data from social media. An ML engineer must implement a solution that ingests and transforms 5 GB of data each minute. The solution also must load the data into a data store that supports fast queries for the real-time analytics. Which solution will meet these requirements?
Answer: A
Explanation:
Amazon Kinesis Data Streams is designed for high-throughput ingestion of streaming data such as social media feeds. Amazon Managed Service for Apache Flink enables real-time transformations on that data. Amazon DynamoDB provides low-latency reads and writes, making it suitable for fast queries in real-time analytics. This combination fully meets the scale and speed requirements.
NEW QUESTION # 119
A company is using an AWS Lambda function to monitor the metrics from an ML model. An ML engineer needs to implement a solution to send an email message when the metrics breach a threshold.
Which solution will meet this requirement?
Answer: B
NEW QUESTION # 120
Case study
An ML engineer is developing a fraud detection model on AWS. The training dataset includes transaction logs, customer profiles, and tables from an on-premises MySQL database. The transaction logs and customer profiles are stored in Amazon S3.
The dataset has a class imbalance that affects the learning of the model's algorithm. Additionally, many of the features have interdependencies. The algorithm is not capturing all the desired underlying patterns in the data.
Before the ML engineer trains the model, the ML engineer must resolve the issue of the imbalanced data.
Which solution will meet this requirement with the LEAST operational effort?
Answer: B
Explanation:
Problem Description:
* The training dataset has a class imbalance, meaning one class (e.g., fraudulent transactions) has fewer samples compared to the majority class (e.g., non-fraudulent transactions). This imbalance affects the model's ability to learn patterns from the minority class.
Why SageMaker Data Wrangler?
* SageMaker Data Wrangler provides a built-in operation called "Balance Data," which includes oversampling and undersampling techniques to address class imbalances.
* Oversampling the minority class replicates samples of the minority class, ensuring the algorithm receives balanced inputs without significant additional operational overhead.
Steps to Implement:
* Import the dataset into SageMaker Data Wrangler.
* Apply the "Balance Data" operation and configure it to oversample the minority class.
* Export the balanced dataset for training.
Advantages:
* Ease of Use: Minimal configuration is required.
* Integrated Workflow: Works seamlessly with the SageMaker ecosystem for preprocessing and model training.
* Time Efficiency: Reduces manual effort compared to external tools or scripts.
NEW QUESTION # 121
A company stores historical data in .csv files in Amazon S3. Only some of the rows and columns in the .csv files are populated. The columns are not labeled. An ML engineer needs to prepare and store the data so that the company can use the data to train ML models.
Select and order the correct steps from the following list to perform this task. Each step should be selected one time or not at all. (Select and order three.)
* Create an Amazon SageMaker batch transform job for data cleaning and feature engineering.
* Store the resulting data back in Amazon S3.
* Use Amazon Athena to infer the schemas and available columns.
* Use AWS Glue crawlers to infer the schemas and available columns.
* Use AWS Glue DataBrew for data cleaning and feature engineering.
Answer:
Explanation: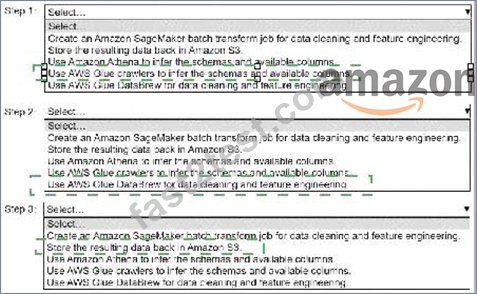
Explanation:
Step 1: Use AWS Glue crawlers to infer the schemas and available columns.
Step 2: Use AWS Glue DataBrew for data cleaning and feature engineering.
Step 3: Store the resulting data back in Amazon S3.
Step 1: Use AWS Glue Crawlers to Infer Schemas and Available Columns
Why? The data is stored in .csv files with unlabeled columns, and Glue Crawlers can scan the raw data in Amazon S3 to automatically infer the schema, including available columns, data types, and any missing or incomplete entries.
How? Configure AWS Glue Crawlers to point to the S3 bucket containing the .csv files, and run the crawler to extract metadata. The crawler creates a schema in the AWS Glue Data Catalog, which can then be used for subsequent transformations.
Step 2: Use AWS Glue DataBrew for Data Cleaning and Feature Engineering Why? Glue DataBrew is a visual data preparation tool that allows for comprehensive cleaning and transformation of data. It supports imputation of missing values, renaming columns, feature engineering, and more without requiring extensive coding.
How? Use Glue DataBrew to connect to the inferred schema from Step 1 and perform data cleaning and feature engineering tasks like filling in missing rows/columns, renaming unlabeled columns, and creating derived features.
Step 3: Store the Resulting Data Back in Amazon S3
Why? After cleaning and preparing the data, it needs to be saved back to Amazon S3 so that it can be used for training machine learning models.
How? Configure Glue DataBrew to export the cleaned data to a specific S3 bucket location. This ensures the processed data is readily accessible for ML workflows.
Order Summary:
Use AWS Glue crawlers to infer schemas and available columns.
Use AWS Glue DataBrew for data cleaning and feature engineering.
Store the resulting data back in Amazon S3.
This workflow ensures that the data is prepared efficiently for ML model training while leveraging AWS services for automation and scalability.
NEW QUESTION # 122
A company is building an Amazon SageMaker AI pipeline for an ML model. The pipeline uses distributed processing and distributed training.
An ML engineer needs to encrypt network communication between instances that run distributed jobs. The ML engineer configures the distributed jobs to run in a private VPC.
What should the ML engineer do to meet the encryption requirement?
Answer: D
Explanation:
In Amazon SageMaker, distributed training and distributed processing jobs often involve multiple instances exchanging data over the network. By default, when these jobs run inside a VPC, network traffic remains private but is not automatically encrypted between instances. When compliance or security requirements mandate encryption of in-transit data, additional configuration is required.
The correct solution is to enable inter-container traffic encryption, which ensures that all network communication between containers running on different instances is encrypted using TLS. Amazon SageMaker provides a built-in feature for this purpose. When inter-container traffic encryption is enabled, SageMaker automatically configures secure communication channels between all nodes participating in a distributed job, including training clusters and processing jobs.
Option A (Network isolation) is incorrect because network isolation prevents containers from making outbound network calls and accessing the internet. It does not encrypt traffic between instances.
Option B (Security groups) is incorrect because security groups control network access and traffic flow, not encryption. They can restrict which instances can communicate, but they do not provide data-in-transit encryption.
Option D (VPC flow logs) is incorrect because VPC flow logs are used for monitoring and auditing network traffic, not for encrypting it.
AWS documentation explicitly states that enabling inter-container traffic encryption is the recommended and supported approach for encrypting data exchanged between instances during distributed SageMaker jobs. This feature aligns with enterprise security best practices and regulatory requirements for protecting sensitive ML training data in transit.
Therefore, Option C is the only solution that directly fulfills the encryption requirement for distributed SageMaker workloads.
NEW QUESTION # 123
......
For candidates who are going to buy MLA-C01 learning materials online, they may pay more attention to that money safety. We apply international recognition third party for the payment, and therefore your account and money safety can be guaranteed if you choose MLA-C01 exam materials from us. In attrition, in order to build up your confidence for MLA-C01 Exam Dumps, we are pass guarantee and money back guarantee. If you fail to pass the exam in your first attempt, we will give you full refund and no other questions will be asked. You give us trust, and we help you pass the exam successfully.
MLA-C01 Test Questions Vce: https://www.fast2test.com/MLA-C01-premium-file.html
DOWNLOAD the newest Fast2test MLA-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1BEuLQKbPGjQK1aHkqyTAskhCXDXXiFul