P.S. Kostenlose und neue AIF-C01 Prüfungsfragen sind auf Google Drive freigegeben von ZertSoft verfügbar: https://drive.google.com/open?id=1cxyYqHZQbTTm3cvlfukyL8CcRJWB0lMK
ZertSoft zusammengestellt Amazon ZertSoft AIF-C01 mit Original-Prüfungsfragen und präzise Antworten, wie sie in der eigentlichen Prüfung erscheinen. Eine der Tatsachen Sicherstellung einer hohen Qualität der AWS Certified AI Practitioner-Prüfung ist die ständig und regelmäßig zu aktualisieren. ZertSoft ernennt nur die besten und kompetentesten Autoren für ihre Produkte und die Prüfung ZertSoft AIF-C01 zum Zeitpunkt des Kaufs ist absoluter Erfolg.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Fundamentals of Generative AI | 24% | - Define generative AI and foundation models - Explain capabilities and use cases of generative AI - Differentiate between generative AI and traditional ML - Describe concepts: prompts, embeddings, fine-tuning, retrieval-augmented generation (RAG) |
| Topic 2: Fundamentals of AI and ML | 20% | - Describe common ML workflows and lifecycle - Identify types of ML: supervised, unsupervised, reinforcement learning - Define artificial intelligence (AI), machine learning (ML), and deep learning - Recognize key concepts: data, models, training, inference, evaluation |
| Topic 3: Security, Compliance, and Governance for AI Solutions | 14% | - Data protection and privacy in AI workflows - Compliance requirements and regulations - Security controls for AI data and models - Governance frameworks for AI lifecycle |
| Topic 4: Applications of Foundation Models | 28% | - Describe use cases for text, image, video, and code generation - Identify AWS services for generative AI: Amazon Bedrock, Amazon Titan - Recognize tools for building and deploying generative AI solutions - Explain integration of foundation models into applications |
| Topic 5: Guidelines for Responsible AI | 14% | - Describe ethical and societal impacts of AI - Explain bias detection and reduction - Identify risks and mitigation strategies for AI systems - Define responsible AI principles: fairness, transparency, privacy, safety |
Mit langjähriger Forschung im Gebiet der IT-Zertifizierungsprüfung spielen wir ZertSoft eine führende Rolle in diesem Gewerbe. Die Softwaren, die wir entwickeln, sind umfassend und enthaltet große Menge Prüfungsaufgaben. Amazon AIF-C01 Prüfungssoftware ist eine der Bestseller. Sie hilft gut die Prüfungsteilnehmer, die Amazon AIF-C01 zu bestehen. Und es ist allgemein bekannt, dass mit die Amazon AIF-C01 Zertifizierung wird Ihre Karriere im IT-Gewerbe leichter sein!
192. Frage
A company wants to use a large language model (LLM) on Amazon Bedrock for sentiment analysis. The company wants to classify the sentiment of text passages as positive or negative.
Which prompt engineering strategy meets these requirements?
Antwort: D
Begründung:
Providing examples of text passages with corresponding positive or negative labels in the prompt followed by the new text passage to be classified is the correct prompt engineering strategy for using a large language model (LLM) on Amazon Bedrock for sentiment analysis.
* Example-Driven Prompts:
* This strategy, known as few-shot learning, involves giving the model examples of input-output pairs (e.g., text passages with their sentiment labels) to help it understand the task context.
* It allows the model to learn from these examples and apply the learned pattern to classify new text passages correctly.
* Why Option A is Correct:
* Guides the Model: Providing labeled examples teaches the model how to perform sentiment analysis effectively, increasing accuracy.
* Contextual Relevance: Aligns the model's responses to the specific task of classifying sentiment.
* Why Other Options are Incorrect:
* B. Detailed explanation of sentiment analysis: Unnecessary for the model's operation; it requires examples, not explanations.
* C. New text passage without context: Provides no guidance or learning context for the model.
* D. Unrelated task examples: Would confuse the model and lead to inaccurate results.
193. Frage
A company is using Amazon SageMaker to develop AI models.
Select the correct SageMaker feature or resource from the following list for each step in the AI model lifecycle workflow. Each SageMaker feature or resource should be selected one time or not at all. (Select TWO.)
* SageMaker Clarify
* SageMaker Model Registry
* SageMaker Serverless Inference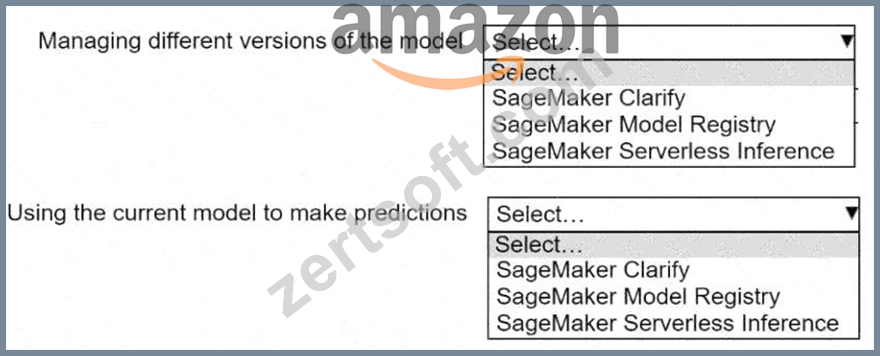
Antwort:
Begründung: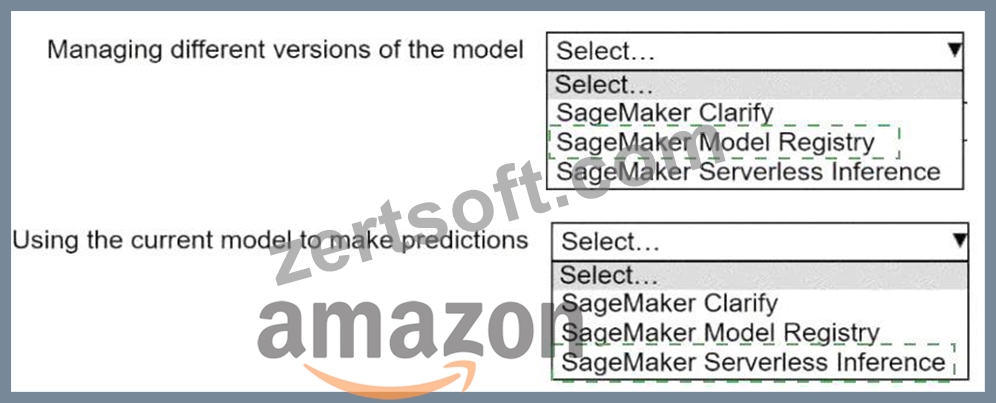
Explanation: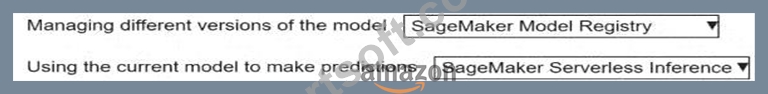
SageMaker Model Registry, SageMaker Serverless interference
This question requires selecting the appropriate Amazon SageMaker feature for two distinct steps in the AI model lifecycle. Let's break down each step and evaluate the options:
Step 1: Managing different versions of the model
The goal here is to identify a SageMaker feature that supports version control and management of machine learning models. Let's analyze the options:
* SageMaker Clarify: This feature is used to detect bias in models and explain model predictions, helping with fairness and interpretability. It does not provide functionality for managing model versions.
* SageMaker Model Registry: This is a centralized repository in Amazon SageMaker that allows users to catalog, manage, and track different versions of machine learning models. It supports model versioning, approval workflows, and deployment tracking, making it ideal for managing different versions of a model.
* SageMaker Serverless Inference: This feature enables users to deploy models for inference without managing servers, automatically scaling based on demand. It is focused on inference (predictions), not on managing model versions.
Conclusion for Step 1: The SageMaker Model Registry is the correct choice for managing different versions of the model.
Exact Extract Reference: According to the AWS SageMaker documentation, "The SageMaker Model Registry allows you to catalog models for production, manage model versions, associate metadata, and manage approval status for deployment." (Source: AWS SageMaker Documentation - Model Registry,
https://docs.aws.amazon.com/sagemaker/latest/dg/model-registry.html).
Step 2: Using the current model to make predictions
The goal here is to identify a SageMaker feature that facilitates making predictions (inference) with a deployed model. Let's evaluate the options:
* SageMaker Clarify: As mentioned, this feature focuses on bias detection and explainability, not on performing inference or making predictions.
* SageMaker Model Registry: While the Model Registry helps manage and catalog models, it is not used directly for making predictions. It can store models, but the actual inference process requires a deployment mechanism.
* SageMaker Serverless Inference: This feature allows users to deploy models for inference without managing infrastructure. It automatically scales based on traffic and is specifically designed for making predictions in a cost-efficient, serverless manner.
Conclusion for Step 2: SageMaker Serverless Inference is the correct choice for using the current model to make predictions.
Exact Extract Reference: The AWS documentation states, "SageMaker Serverless Inference is a deployment option that allows you to deploy machine learning models for inference without configuring or managing servers. It automatically scales to handle inference requests, making it ideal for workloads with intermittent or unpredictable traffic." (Source: AWS SageMaker Documentation - Serverless Inference, https://docs.aws.
amazon.com/sagemaker/latest/dg/serverless-inference.html).
Why Not Use the Same Feature Twice?
The question specifies that each SageMaker feature or resource should be selected one time or not at all. Since SageMaker Model Registry is used for version management and SageMaker Serverless Inference is used for predictions, each feature is selected exactly once. SageMaker Clarify is not applicable to either step, so it is not selected at all, fulfilling the question's requirements.
:
AWS SageMaker Documentation: Model Registry (https://docs.aws.amazon.com/sagemaker/latest/dg/model- registry.html) AWS SageMaker Documentation: Serverless Inference (https://docs.aws.amazon.com/sagemaker/latest/dg
/serverless-inference.html)
AWS AI Practitioner Study Guide (conceptual alignment with SageMaker features for model lifecycle management and inference) Let's format this question according to the specified structure and provide a detailed, verified answer based on AWS AI Practitioner knowledge and official AWS documentation. The question focuses on selecting an AWS database service that supports storage and queries of embeddings as vectors, which is relevant to generative AI applications.
194. Frage
A company wants to identify groups for its customers based on the customers' demographics and buying patterns.
Which algorithm should the company use to meet this requirement?
Antwort: B
Begründung:
The correct answer is B because K-means is an unsupervised learning algorithm used for clustering data points into groups (clusters) based on feature similarity. It is ideal for customer segmentation use cases where the goal is to discover natural groupings based on buying behavior and demographics without pre-labeled data.
From AWS documentation:
"K-means is a clustering algorithm that assigns data points to one of K groups based on feature similarity. It is commonly used in marketing and customer segmentation to group users with similar characteristics." Explanation of other options:
A). K-nearest neighbors is a supervised classification algorithm, not intended for clustering.
C). Decision tree is also a supervised learning method used for classification or regression tasks.
D). Support vector machine is used for classification and regression, not unsupervised clustering.
Referenced AWS AI/ML Documents and Study Guides:
* AWS ML Specialty Guide - Unsupervised Learning and Clustering
* AWS ML Algorithm Selection Guide
* Amazon SageMaker Built-in Algorithms - K-means Clustering
195. Frage
A company is developing a customer service agent by using Amazon Bedrock. The company wants to ensure that the agent does not disclose personally identifiable information (PII) during conversations with users.
Which Amazon Bedrock feature meets these requirements?
Antwort: D
Begründung:
The verified answer is A. Amazon Bedrock Guardrails. AWS documentation states that Amazon Bedrock Guardrails helps detect sensitive information, including personally identifiable information, in input prompts or model responses by using sensitive information filters. AWS also states that these filters can be configured to block or mask detected PII. This directly matches the requirement to prevent a customer service agent from disclosing PII during conversations.
Bedrock Guardrails supports handling sensitive information in two key ways. A block action can block requests or responses that include sensitive information, and a mask action can anonymize or redact detected information in model requests or responses. AWS gives examples of PII categories such as names, email addresses, phone numbers, usernames, passwords, addresses, credit card numbers, PINs, and other sensitive identifiers. For a customer service agent, this is exactly the right feature because PII could appear in either the user input or the model response.
Amazon Bedrock Flows is incorrect because flows help orchestrate generative AI workflows. They do not primarily provide PII filtering. Amazon Bedrock Knowledge Bases is incorrect because knowledge bases support Retrieval Augmented Generation by connecting models to enterprise data sources. They help ground responses but do not directly block PII disclosure. Amazon Bedrock Data Automation is incorrect because BDA is used to transform and extract insights from multimodal content such as documents, images, audio, and video. It is not the runtime guardrail feature for blocking or masking PII in conversations.
Therefore, the correct Amazon Bedrock feature is Amazon Bedrock Guardrails.
196. Frage
A company is training ML models on datasets. The datasets contain some classes that have more examples than other classes. The company wants to measure how well the model balances detecting and labeling the classes.
Which metric should the company use?
Antwort: A
Begründung:
The correct answer is D - F1 score, which is the harmonic mean of precision and recall. AWS documentation states that the F1 score is the preferred metric when evaluating ML models trained on imbalanced datasets, where one class appears significantly more often than others. Accuracy becomes misleading in these situations because a model can achieve high accuracy simply by predicting the majority class. Precision alone measures correctness of positive predictions, while recall measures completeness-neither fully captures class balancing performance. The F1 score provides a combined measurement that reflects how well the model identifies minority classes while avoiding excessive false positives. AWS's ML Specialty Guide recommends using F1 for classification tasks where "class distribution is uneven or where both false negatives and false positives matter." This metric provides a fairer assessment of overall model performance across all class categories.
Referenced AWS Documentation:
AWS Certified Machine Learning Specialty Guide - Metrics for Imbalanced Classes Amazon SageMaker Developer Guide - Evaluating Classification Models
197. Frage
......
ZertSoft haben schon viele Prüfungsteilnehmer bei dem Bestehen der Amazon AIF-C01 Prüfung geholfen. Unsere Schlüssel ist die Amazon AIF-C01 Prüfungsunterlagen, die von unserer professionellen IT-Gruppe für mehrere Jahre geforscht werden. Die Antworten davon werden auch ausführlich analysiert. Die Prüfung werden immer aktualisiert. Deshalb aktualisieren wir die Prüfungsunterlagen der Amazon AIF-C01 immer wieder. Wir tun unser Bestes, um den sicheren Erfolg zu garantieren.
AIF-C01 Lernressourcen: https://www.zertsoft.com/AIF-C01-pruefungsfragen.html
Laden Sie die neuesten ZertSoft AIF-C01 PDF-Versionen von Prüfungsfragen kostenlos von Google Drive herunter: https://drive.google.com/open?id=1cxyYqHZQbTTm3cvlfukyL8CcRJWB0lMK