Study Databricks-Certified-Professional-Data-Engineer Plan - 100% Pass-Sure Questions Pool
Desktop and web-based Databricks-Certified-Professional-Data-Engineer practice exams are available at PassSureExam for thorough preparation. Going through these Databricks Databricks-Certified-Professional-Data-Engineer mock exams boosts your learning and reduces mistakes in the Databricks Databricks-Certified-Professional-Data-Engineer Test Preparation. Customization features of Databricks Databricks-Certified-Professional-Data-Engineer practice tests allow you to change the settings of the Databricks-Certified-Professional-Data-Engineer test sessions.
The DCPDE exam is a comprehensive assessment that covers a wide range of topics related to data engineering on Databricks. Databricks-Certified-Professional-Data-Engineer Exam consists of multiple-choice questions and performance-based tasks that require candidates to demonstrate their ability to design, build, and deploy scalable data pipelines on the Databricks platform.
Databricks Certified Professional Data Engineer certification is a valuable credential for data engineers who want to validate their skills and expertise in using Databricks. Databricks Certified Professional Data Engineer Exam certification demonstrates to employers and clients that the candidate has the knowledge and skills required to design and implement data solutions using Databricks. It also helps data engineers differentiate themselves in a competitive job market and provides opportunities for career advancement.
>> Study Databricks-Certified-Professional-Data-Engineer Plan <<
Databricks Databricks-Certified-Professional-Data-Engineer Practice Test For Supreme Achievement 2026
Nowadays there is a growing tendency in getting a certificate. Databricks-Certified-Professional-Data-Engineer study materials offer you an opportunity to get the certificate easily. Databricks-Certified-Professional-Data-Engineer exam dumps are edited by the experienced experts who are familiar with the dynamics of the exam center, therefore Databricks-Certified-Professional-Data-Engineer Study Materials of us are the essence for the exam. Besides we are pass guarantee and money back guarantee. Any other questions can contact us anytime.
Databricks Certified Professional Data Engineer certification is a valuable credential for professionals who want to advance their careers in data engineering. Databricks Certified Professional Data Engineer Exam certification demonstrates the candidates' proficiency in using Databricks to build efficient and scalable data processing systems. Databricks Certified Professional Data Engineer Exam certification also validates the candidates' ability to work with big data technologies and handle complex data workflows. Overall, the Databricks Certified Professional Data Engineer certification is an excellent way for professionals to showcase their expertise in data engineering and increase their value in the job market.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q159-Q164):
NEW QUESTION # 159
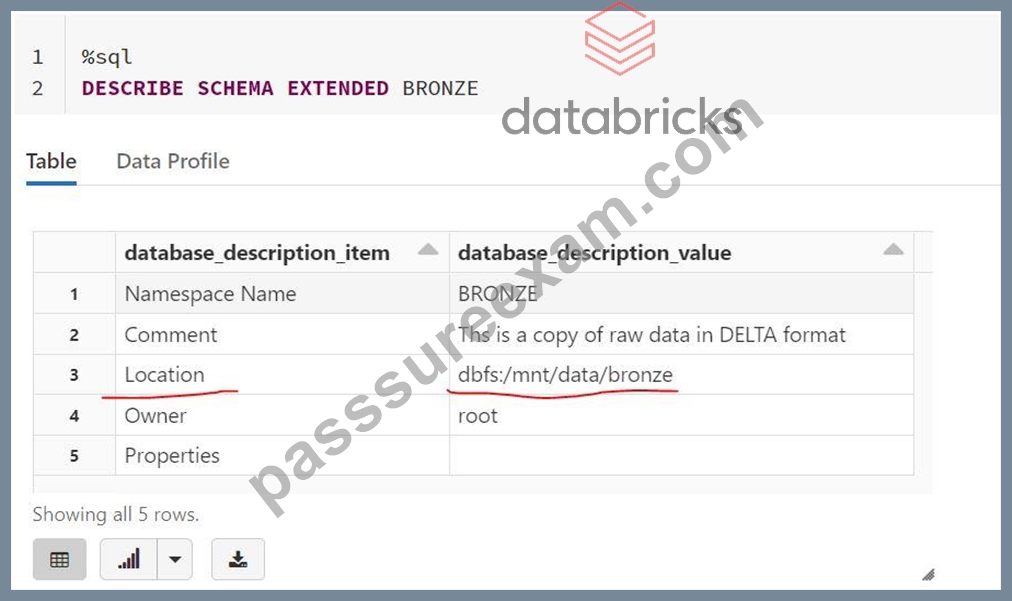
How do you check the location of an existing schema in Delta Lake?
- A. Check unity catalog UI
- B. Run SQL command SHOW LOCATION schema_name
- C. Run SQL command DESCRIBE SCHEMA EXTENDED schema_name
E Schemas are internally in-store external hive meta stores like MySQL or SQL Server - D. Use Data explorer
Answer: C
Explanation:
Explanation
Here is an example of how it looks
Graphical user interface, text, application, email Description automatically generated
NEW QUESTION # 160
At the end of the inventory process, a file gets uploaded to the cloud object storage, you are asked to build a process to ingest data which of the following method can be used to ingest the data in-crementally, schema of the file is expected to change overtime ingestion process should be able to handle these changes automatically.
Below is the auto loader to command to load the data, fill in the blanks for successful execution of below code.
1.spark.readStream
2..format("cloudfiles")
3..option("_______","csv)
4..option("_______", 'dbfs:/location/checkpoint/')
5..load(data_source)
6..writeStream
7..option("_______",' dbfs:/location/checkpoint/')
8..option("_______", "true")
9..table(table_name))
- A. cloudfiles.format, cloudfiles.schemalocation, checkpointlocation, append
- B. cloudfiles.format, cloudfiles.schemalocation, checkpointlocation, mergeSchema
- C. format, checkpointlocation, schemalocation, overwrite
- D. cloudfiles.format, checkpointlocation, cloudfiles.schemalocation, overwrite
- E. cloudfiles.format, cloudfiles.schemalocation, checkpointlocation, overwrite
Answer: B
Explanation:
Explanation
The answer is cloudfiles.format, cloudfiles.schemalocation, checkpointlocation, mergeSchema.
Here is the end to end syntax of streaming ELT, below link contains complete options Auto Loader options | Databricks on AWS
1.spark.readStream
2..format("cloudfiles") # Returns a stream data source, reads data as it arrives based on the trigger.
3..option("cloudfiles.format","csv") # Format of the incoming files
4..option("cloudfiles.schemalocation", "dbfs:/location/checkpoint/") The location to store the inferred schema and subsequent changes
5..load(data_source)
6..writeStream
7..option("checkpointlocation","dbfs:/location/checkpoint/") # The location of the stream's checkpoint
8..option("mergeSchema", "true") # Infer the schema across multiple files and to merge the schema of each file. Enabled by default for Auto Loader when inferring the schema.
9..table(table_name)) # target table
NEW QUESTION # 161
A nightly job ingests data into a Delta Lake table using the following code:
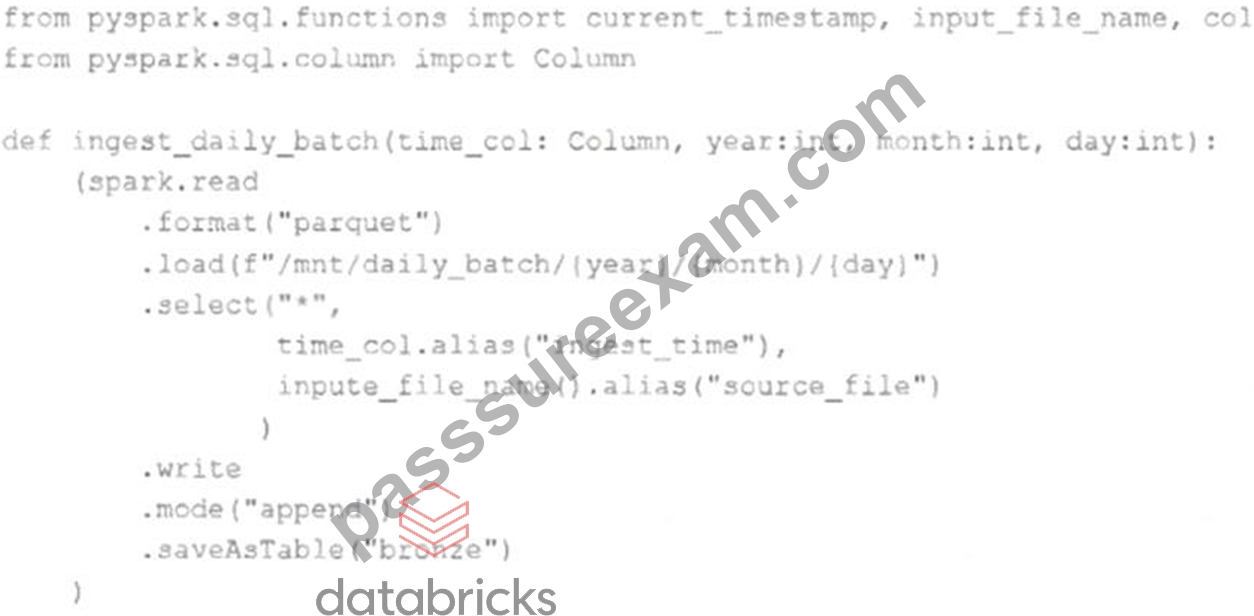
The next step in the pipeline requires a function that returns an object that can be used to manipulate new records that have not yet been processed to the next table in the pipeline.
Which code snippet completes this function definition?
def new_records():
- A. return spark.readStream.load("bronze")
- B. return spark.readStream.table("bronze")
- C.
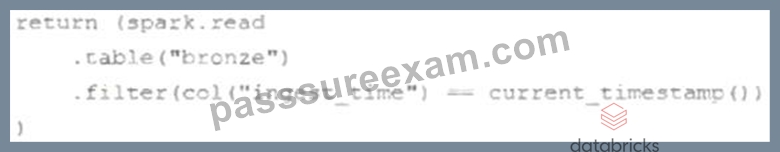
- D.
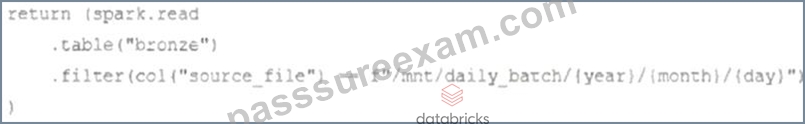
- E. return spark.read.option("readChangeFeed", "true").table ("bronze")
Answer: D
Explanation:
https://docs.databricks.com/en/delta/delta-change-data-feed.html
NEW QUESTION # 162
The data science team has created and logged a production using MLFlow. The model accepts a list of column names and returns a new column of type DOUBLE.
The following code correctly imports the production model, load the customer table containing the customer_id key column into a Dataframe, and defines the feature columns needed for the model.
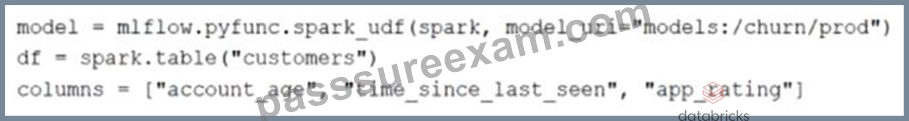
Which code block will output DataFrame with the schema'' customer_id LONG, predictions DOUBLE''?
- A. Df.apply(model, columns). Select (''customer_id, prediction''
- B. Df. Select (''customer_id''.
Model (''columns) alias (''predictions'') - C. Model, predict (df, columns)
- D. Df, map (lambda k:midel (x [columns]) ,select (''customer_id predictions'')
Answer: C
Explanation:
Given the information that the model is registered with MLflow and assumingpredictis the method used to apply the model to a set of columns, we use themodel.predict()function to apply the model to the DataFrame dfusing the specifiedcolumns. Themodel.predict()function is designed to take in a DataFrame and a list of column names as arguments, applying the trained model to these features to produce a predictionscolumn.
When working with PySpark, this predictions column needs to be selected alongside thecustomer_idto create a new DataFrame with the schemacustomer_id LONG, predictions DOUBLE.
References:
* MLflow documentation on using Python function models: https://www.mlflow.org/docs/latest/models.
html#python-function-python
* PySpark MLlib documentation on model prediction:https://spark.apache.org/docs/latest/ml-pipeline.
html#pipeline
NEW QUESTION # 163
A junior data engineer has configured a workload that posts the following JSON to the Databricks REST API endpoint 2.0/jobs/create .
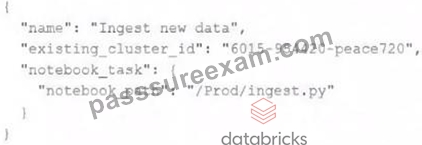
Assuming that all configurations and referenced resources are available, which statement describes the result of executing this workload three times?
- A. The logic defined in the referenced notebook will be executed three times on the referenced existing all purpose cluster.
- B. The logic defined in the referenced notebook will be executed three times on new clusters with the configurations of the provided cluster ID.
- C. One new job named " Ingest new data " will be defined in the workspace, but it will not be executed.
- D. Three new jobs named " Ingest new data " will be defined in the workspace, but no jobs will be executed.
- E. Three new jobs named " Ingest new data " will be defined in the workspace, and they will each run once daily.
Answer: D
Explanation:
This is the correct answer because the JSON posted to the Databricks REST API endpoint 2.0/jobs/create defines a new job with a name, an existing cluster id, and a notebook task. However, it does not specify any schedule or trigger for the job execution. Therefore, three new jobs with the same name and configuration will be created in the workspace, but none of them will be executed until they are manually triggered or scheduled.
Verified References: [Databricks Certified Data Engineer Professional], under "Monitoring and Logging" section; [Databricks Documentation], under "Jobs API - Create" section.
NEW QUESTION # 164
......
Databricks-Certified-Professional-Data-Engineer Visual Cert Exam: https://www.passsureexam.com/Databricks-Certified-Professional-Data-Engineer-pass4sure-exam-dumps.html
- New Databricks-Certified-Professional-Data-Engineer Braindumps Files 🥳 New Databricks-Certified-Professional-Data-Engineer Braindumps Files 🤸 Latest Braindumps Databricks-Certified-Professional-Data-Engineer Ebook 🏍 Easily obtain free download of ⏩ Databricks-Certified-Professional-Data-Engineer ⏪ by searching on ➤ www.vce4dumps.com ⮘ 🤩Databricks-Certified-Professional-Data-Engineer Dumps
- Pdfvce Databricks Databricks-Certified-Professional-Data-Engineer Desktop-based Practice Test Software 🐇 Copy URL 「 www.pdfvce.com 」 open and search for ▷ Databricks-Certified-Professional-Data-Engineer ◁ to download for free 🆔Databricks-Certified-Professional-Data-Engineer Guaranteed Passing
- Databricks-Certified-Professional-Data-Engineer Latest Examprep 🏈 Latest Databricks-Certified-Professional-Data-Engineer Questions 🥺 Databricks-Certified-Professional-Data-Engineer Guaranteed Passing 🐫 Copy URL ➽ www.examcollectionpass.com 🢪 open and search for [ Databricks-Certified-Professional-Data-Engineer ] to download for free 📧Latest Databricks-Certified-Professional-Data-Engineer Material
- Free PDF Databricks - Databricks-Certified-Professional-Data-Engineer - Latest Study Databricks Certified Professional Data Engineer Exam Plan 💢 Open ▛ www.pdfvce.com ▟ enter ➥ Databricks-Certified-Professional-Data-Engineer 🡄 and obtain a free download 🍴Databricks-Certified-Professional-Data-Engineer Dumps
- Latest Databricks-Certified-Professional-Data-Engineer Exam Pdf 🛶 Latest Braindumps Databricks-Certified-Professional-Data-Engineer Ebook 🤺 Valid Databricks-Certified-Professional-Data-Engineer Test Papers 〰 Copy URL ▷ www.troytecdumps.com ◁ open and search for ➥ Databricks-Certified-Professional-Data-Engineer 🡄 to download for free 🙉Latest Databricks-Certified-Professional-Data-Engineer Questions
- Free Databricks-Certified-Professional-Data-Engineer Learning Cram 🧉 Databricks-Certified-Professional-Data-Engineer Guaranteed Passing ❤️ Databricks-Certified-Professional-Data-Engineer Dumps 🐡 Download ➠ Databricks-Certified-Professional-Data-Engineer 🠰 for free by simply searching on “ www.pdfvce.com ” 🧈Databricks-Certified-Professional-Data-Engineer Latest Examprep
- Databricks-Certified-Professional-Data-Engineer Guaranteed Passing 🥏 Guaranteed Databricks-Certified-Professional-Data-Engineer Success 📹 Exam Databricks-Certified-Professional-Data-Engineer PDF 🤠 Search for 「 Databricks-Certified-Professional-Data-Engineer 」 on ▷ www.practicevce.com ◁ immediately to obtain a free download 🎹Databricks-Certified-Professional-Data-Engineer Practice Test Fee
- Popular Databricks-Certified-Professional-Data-Engineer Study Materials Offer You Splendid Exam Questions - Pdfvce 🛷 Copy URL ➡ www.pdfvce.com ️⬅️ open and search for ( Databricks-Certified-Professional-Data-Engineer ) to download for free 🐕New Databricks-Certified-Professional-Data-Engineer Braindumps Files
- 2026 Databricks Databricks-Certified-Professional-Data-Engineer Useful Study Plan 🎼 Open ✔ www.examcollectionpass.com ️✔️ and search for ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ to download exam materials for free 🎨Guaranteed Databricks-Certified-Professional-Data-Engineer Success
- Choose Any Databricks Databricks-Certified-Professional-Data-Engineer Exam Dumps Format and Start Preparation 🦦 The page for free download of ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ on 《 www.pdfvce.com 》 will open immediately ☘Guaranteed Databricks-Certified-Professional-Data-Engineer Success
- Popular Databricks-Certified-Professional-Data-Engineer Study Materials Offer You Splendid Exam Questions - www.exam4labs.com 🍑 Search for ▷ Databricks-Certified-Professional-Data-Engineer ◁ and download it for free immediately on 「 www.exam4labs.com 」 🩳Latest Databricks-Certified-Professional-Data-Engineer Exam Pdf
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, jacobscott67888.blogspot.com, Disposable vapes