P.S. Free & New DP-750 dumps are available on Google Drive shared by Itcerttest: https://drive.google.com/open?id=1C9EO9roP6oCFMIuoehTiPrOem5HaIb4_
Microsoft Certification DP-750 Exam is very popular among the IT people to enroll in the exam. Passing Microsoft certification DP-750 exam can not only chang your work and life can bring, but also consolidate your position in the IT field. But the fact is that the passing rate is very low.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Deploy and manage data pipelines and workloads | 30-35% | - Lakehouse architecture operations
|
| Topic 2: Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
| Topic 3: Configure and manage Azure Databricks environments | 15-20% | - Security and authentication setup
|
| Topic 4: Prepare and process data | 30-35% | - Data ingestion
|
Our DP-750 study materials are famous at home and abroad, the main reason is because we have other companies that do not have core competitiveness, there are many complicated similar products on the market, if you want to stand out is the selling point of needs its own. Our DP-750 Study Materials with other product of different thing is we have the most core expert team to update our DP-750 study materials , learning platform to changes with the change of the exam outline.
NEW QUESTION # 40
You have an Azure Databricks workspace that is enabled for Unity Catalog. You plan to run the following PySpark code.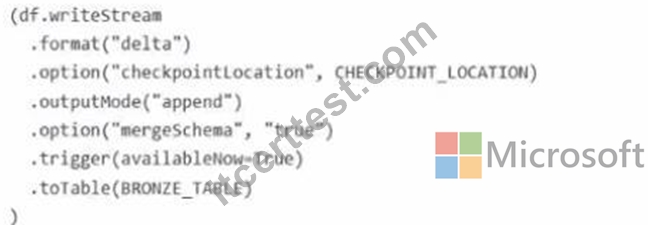
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.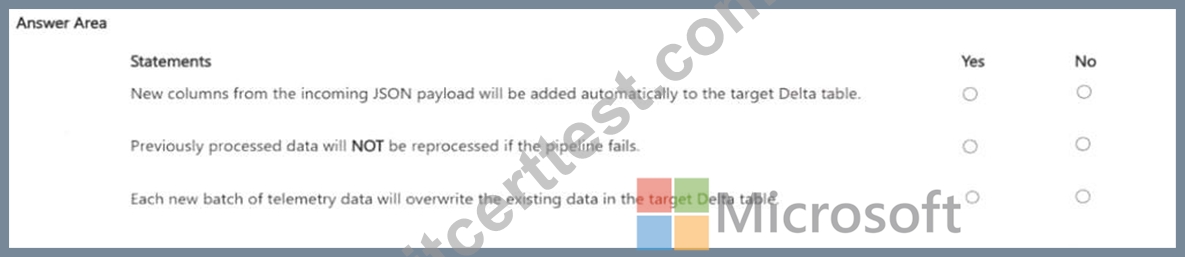
Answer:
Explanation: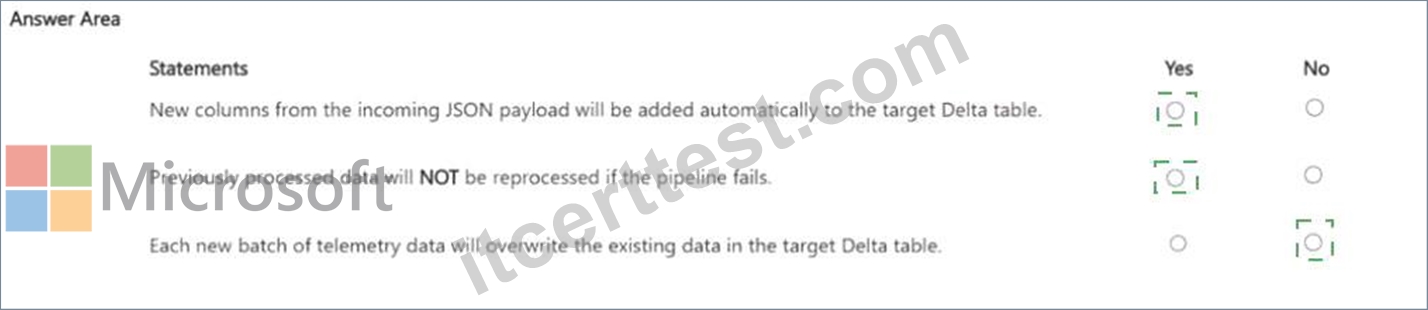
Explanation:
For HOTSPOT questions, each statement must be evaluated against the actual PySpark code shown in the answer area. Key evaluation principles:
DataFrames are immutable - every transformation returns a new DataFrame; the original is unchanged.
Transformations (filter, select, groupBy, join) are lazy and only execute when an action (show, count, write) is called.
Null handling: df.filter(col != None) is incorrect in PySpark due to SQL null semantics; use col.isNotNull() or dropna() instead. Schema changes: using mergeSchema=true or schema evolution handles new columns.
Write modes: 'overwrite' replaces existing data; 'append' adds to it.
Always check whether the code uses the correct Delta format (.format('delta')), Unity Catalog three-part naming, and whether write operations include a checkpointLocation for streaming queries. Evaluate each statement strictly on what the code does, not on what it might intend to do.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
NEW QUESTION # 41
Hotspot Question
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job1 runs every hour.
Occasionally, the job run takes longer than one hour to complete. Overlapping runs must be prevented to avoid data corruption.
You need to configure the job scheduling behavior.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.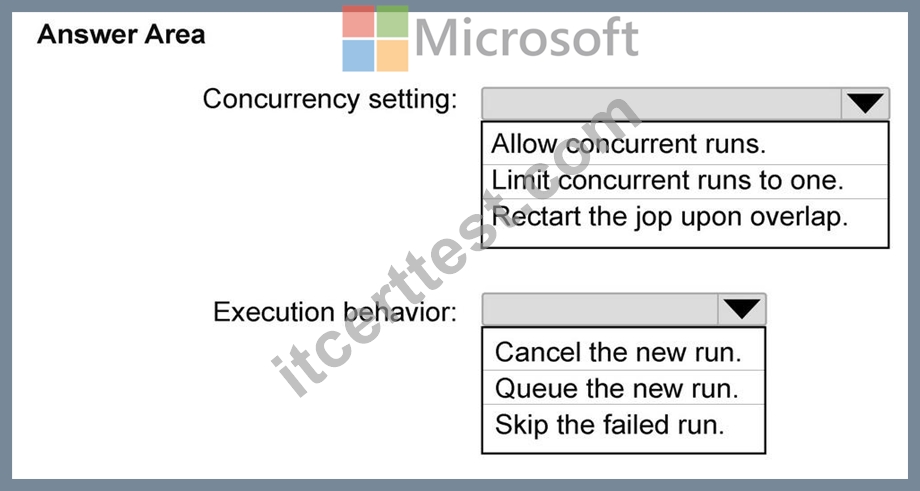
Answer:
Explanation: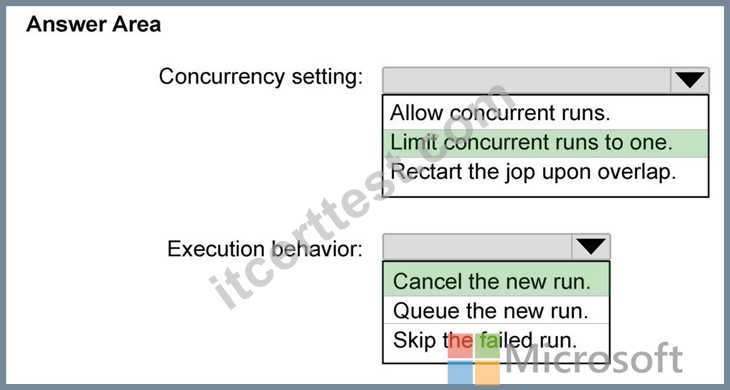
NEW QUESTION # 42
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Sales. Sales stores transaction data and contains the following columns:
* transactionjd (string)
* transaction date (date)
* amount (decimal)
You need to implement the following data quality requirements by using table-level data quality enforcement:
* amount must be greater than 0.
* transaction id must never be null.
* Invalid records must be rejected when data is written to the Sales table.
What should you do?
Answer: B
Explanation:
The correct answer is D - a NOT NULL constraint on transaction_id and a CHECK constraint on amount.
Delta Lake table constraints are enforced at write time by the Delta engine itself. A NOT NULL constraint rejects any INSERT or UPDATE that would place a null in transaction_id. A CHECK constraint with amount
> 0 rejects any row where amount is zero or negative. Combined, they implement exactly the stated quality rules: bad rows are rejected when data is written, not filtered away at read time.
Options A and C (SELECT with WHERE / views) are read-time constructs - they don ' t prevent invalid data from entering the table. A clever pipeline bypass could write directly to the table and skip the view entirely. Option B (row-level security with WHERE conditions) is an access-control feature for restricting which rows users see, not for enforcing data quality on writes. Table constraints are the only mechanism that genuinely blocks bad data at the storage layer.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/delta-constraints
NEW QUESTION # 43
You have an Azure Databricks workspace that is enabled for Unity Catalog. You plan to run the following PySpark code.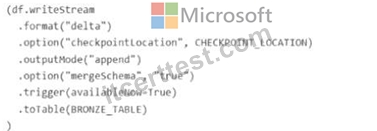
For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
For HOTSPOT questions, each statement must be evaluated against the actual PySpark code shown in the answer area. Key evaluation principles:
DataFrames are immutable - every transformation returns a new DataFrame; the original is unchanged.
Transformations (filter, select, groupBy, join) are lazy and only execute when an action (show, count, write) is called.
Null handling: df.filter(col != None) is incorrect in PySpark due to SQL null semantics; use col.isNotNull() or dropna() instead. Schema changes: using mergeSchema=true or schema evolution handles new columns.
Write modes: ' overwrite ' replaces existing data; ' append ' adds to it.
Always check whether the code uses the correct Delta format (.format( ' delta ' )), Unity Catalog three-part naming, and whether write operations include a checkpointLocation for streaming queries. Evaluate each statement strictly on what the code does, not on what it might intend to do.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
NEW QUESTION # 44
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline in Azure Databricks. The pipeline ingests transaction data into a table named Table1.
You need to ensure that in the event of an invalid record, the pipeline continues to run. The solution must meet the following requirements:
- Invalid records must NOT be written to Table1.
- Invalid records must be preserved for review.
- Minimize development effort.
What should you do?
Answer: C
Explanation:
To meet your pipeline requirements, use the expect_or_drop expectation constraint to ensure invalid records are not written to the table while allowing the pipeline to continue running. To preserve and review invalid records without custom development, capture the failed rows by isolating the inverse rule (expect_or_drop) in a quarantine flow.
Summary of the Behavior Matrix
Pipeline continues to run: Achieved via drop or warn behaviors (the fail policy is excluded because it halts execution).
Invalid records not written to the clean table: Achieved via the drop policy, which discards records from the downstream dataset.
Records preserved for review: Achieved by querying the automated, built-in Lakeflow Event Log Delta table, which automatically captures the details of any rejected or flagged rows without requiring custom code.
Minimized development: Eliminates the need to construct secondary "quarantine" storage tables manually.
Reference:
https://docs.databricks.com/aws/en/ldp/best-practices
NEW QUESTION # 45
......
A good brand is not a cheap product, but a brand that goes well beyond its users' expectations. The value of a brand is that the DP-750 study materials are more than just exam preparation tool -- it should be part of our lives, into our daily lives. Do this, therefore, our DP-750 Study Materials has become the industry well-known brands, but even so, we have never stopped the pace of progress, we have been constantly updated the DP-750 study materials.
Simulation DP-750 Questions: https://www.itcerttest.com/DP-750_braindumps.html
P.S. Free 2026 Microsoft DP-750 dumps are available on Google Drive shared by Itcerttest: https://drive.google.com/open?id=1C9EO9roP6oCFMIuoehTiPrOem5HaIb4_