BONUS!!! Download part of ITExamSimulator Professional-Machine-Learning-Engineer dumps for free: https://drive.google.com/open?id=17v_knvi8rzPZeZw5KpYfWZoY0XpLu_dr
If you are then you do not need to worry about it. Just visit the "ITExamSimulator" and explore the top features of Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) exam questions and if you think the ITExamSimulator Professional-Machine-Learning-Engineer Exam Questions can help you then download ITExamSimulator Professional-Machine-Learning-Engineer exam questions and start Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) exam preparation today.
| Section | Objectives |
|---|---|
| Topic 1: ML pipeline automation and orchestration | - Pipeline design
|
| Topic 2: Data preparation and processing | - Data ingestion and pipelines
|
| Topic 3: ML model development | - Evaluation
|
| Topic 4: Deployment and operations | - Model deployment
|
| Topic 5: Designing ML solutions | - Framing ML problems
|
>> Google Professional-Machine-Learning-Engineer Test Questions Vce <<
The social environment is constantly changing, and our Professional-Machine-Learning-Engineer guide quiz is also advancing with the times. The content of Professional-Machine-Learning-Engineer exam materials is constantly updated. You can save a lot of time for collecting real-time information. In order to ensure that you can see the updated Professional-Machine-Learning-Engineer practice prep as soon as possible, our system sends the updated information to your email address first timing. In order to avoid the omission of information, please check your email regularly.
NEW QUESTION # 359
You are analyzing customer data for a healthcare organization that is stored in Cloud Storage. The data contains personally identifiable information (PII) You need to perform data exploration and preprocessing while ensuring the security and privacy of sensitive fields What should you do?
Answer: B
Explanation:
According to the official exam guide1, one of the skills assessed in the exam is to "design, build, and productionalize ML models to solve business challenges using Google Cloud technologies". Cloud Data Loss Prevention (DLP) API2 is a service that provides programmatic access to a powerful detection engine for personally identifiable information and other privacy-sensitive data in unstructured data streams, such as text blocks and images. Cloud DLP API helps you discover, classify, and protect your sensitive data by using techniques such as de-identification, masking, tokenization, and bucketing. You can use Cloud DLP API to de-identify the PII data before performing data exploration andpreprocessing, and retain the data utility for ML purposes. Therefore, option A is the best way to perform data exploration and preprocessing while ensuring the security and privacy of sensitive fields. The other options are not relevant or optimal for this scenario.
References:
* Professional ML Engineer Exam Guide
* Cloud Data Loss Prevention (DLP) API
* Google Professional Machine Learning Certification Exam 2023
* Latest Google Professional Machine Learning Engineer Actual Free Exam Questions
NEW QUESTION # 360
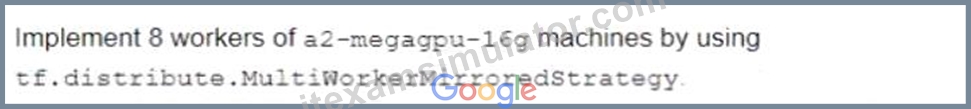
You are pre-training a large language model on Google Cloud. This model includes custom TensorFlow operations in the training loop Model training will use a large batch size, and you expect training to take several weeks You need to configure a training architecture that minimizes both training time and compute costs What should you do?



Answer: B
Explanation:
According to the official exam guide1, one of the skills assessed in the exam is to "design, build, and productionalize ML models to solve business challenges using Google Cloud technologies". TPUs2 are Google's custom-developed application-specific integrated circuits (ASICs) used to accelerate machine learning workloads. TPUs are designed to handle large batch sizes, high dimensional data, and complex computations. TPUs can significantly reduce the training time and compute costs of large language models, especially when used with distributed training strategies, such as MultiWorkerMirroredStrategy3. Therefore, option D is the best way to configure a training architecture that minimizes both training time and compute costs for the given use case. The other options are not relevant or optimal for this scenario. References:
* Professional ML Engineer Exam Guide
* TPUs
* MultiWorkerMirroredStrategy
* Google Professional Machine Learning Certification Exam 2023
* Latest Google Professional Machine Learning Engineer Actual Free Exam Questions
NEW QUESTION # 361
You work on the data science team at a manufacturing company. You are reviewing the company's historical sales data, which has hundreds of millions of records. For your exploratory data analysis, you need to calculate descriptive statistics such as mean, median, and mode; conduct complex statistical tests for hypothesis testing; and plot variations of the features over time You want to use as much of the sales data as possible in your analyses while minimizing computational resources. What should you do?
Answer: C
Explanation:
D Use BigQuery to calculate the descriptive statistics, and use Google Data Studio to visualize the time plots. Use Vertex Al Workbench user-managed notebooks to run the statistical analyses.
Explanation:
BigQuery is a powerful tool for analyzing large datasets and can be used to quickly calculate descriptive statistics, such as mean, median, and mode, on large amounts of data. By using BigQuery, you can analyze the entire dataset and minimize the computational resources required for your analyses.
Once you have calculated the descriptive statistics, you can use Vertex Al Workbench user-managed notebooks to visualize the time plots and run the statistical analyses. Vertex Al Workbench allows you to interactively explore the data, create visualizations, and perform advanced statistical analysis. It's also possible to run these notebooks on a powerful GPU which will help to increase the speed of the analysis.
NEW QUESTION # 362
You work for a large hotel chain and have been asked to assist the marketing team in gathering predictions for a targeted marketing strategy. You need to make predictions about user lifetime value (LTV) over the next 30 days so that marketing can be adjusted accordingly. The customer dataset is in BigQuery, and you are preparing the tabular data for training with AutoML Tables. This data has a time signal that is spread across multiple columns. How should you ensure that AutoML fits the best model to your data?
Answer: A
Explanation:
https://cloud.google.com/automl-tables/docs/data-best-practices#time
NEW QUESTION # 363
You need to analyze user activity data from your company's mobile applications. Your team will use BigQuery for data analysis, transformation, and experimentation with ML algorithms. You need to ensure real-time ingestion of the user activity data into BigQuery. What should you do?
Answer: D
Explanation:
The best option to ensure real-time ingestion of the user activity data into BigQuery is to run a Dataflow streaming job to ingest the data into BigQuery. Dataflow is a fully managed service that can handle both batch and stream processing of data, and can integrate seamlessly with BigQuery and other Google Cloud services.
Dataflow can also use Apache Beam as the programming model, which provides a unified and portable API for developing data pipelines. By using Dataflow, you can avoid the complexity and overhead of managing your own infrastructure, and focus on the logic and transformation of your data. Dataflow can also handle various types of data, such as structured, unstructured, or binary data, and can apply windowing, aggregation, and other operations on the data streams.
The other options are not optimal for the following reasons:
* A. Configuring Pub/Sub to stream the data into BigQuery is not a good option, as Pub/Sub is a messaging service that can publish and subscribe to data streams, but cannot perform any transformation or processing on the data. Pub/Sub can be used as a source or a sink for Dataflow, but not as a standalone solution for ingesting data into BigQuery.
* B. Running an Apache Spark streaming job on Dataproc to ingest the data into BigQuery is not a good option, as it requires setting up and managing your own cluster of virtual machines, which can increase the cost and complexity of your solution. Moreover, Apache Spark is not natively integrated with BigQuery, and requires using connectors or intermediate storage to write data to BigQuery, which can introduce latency and inefficiency.
* D. Configuring Pub/Sub and a Dataflow streaming job to ingest the data into BigQuery is not a bad option, but it is not necessary, as Dataflow can directly read data from the mobile applications without using Pub/Sub as an intermediary. Using Pub/Sub can add an extra layer of abstraction and reliability, but it can also increase the cost and complexity of your solution, and introduce some delay in the data ingestion.
References:
* Professional ML Engineer Exam Guide
* Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate
* Google Cloud launches machine learning engineer certification
* Dataflow documentation
* BigQuery documentation
NEW QUESTION # 364
......
Everybody should recognize the valuable of our life; we can't waste our time, so you need a good way to help you get your goals straightly. Of course, our Professional-Machine-Learning-Engineer latest exam torrents are your best choice. I promise you that you can learn from the Professional-Machine-Learning-Engineer Exam Questions not only the knowledge of the certificate exam, but also the ways to answer questions quickly and accurately. Now, you can free download the demo of our Professional-Machine-Learning-Engineer test torrent to have a check on our wonderful quality.
Professional-Machine-Learning-Engineer Study Material: https://www.itexamsimulator.com/Professional-Machine-Learning-Engineer-brain-dumps.html
BTW, DOWNLOAD part of ITExamSimulator Professional-Machine-Learning-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=17v_knvi8rzPZeZw5KpYfWZoY0XpLu_dr