BONUS!!! Download part of ITexamReview AI-300 dumps for free: https://drive.google.com/open?id=1ULSdhmpiJvh1KNJCGxx3ghQfVw1j1qB7
There is no doubt that among our three different versions of AI-300 guide torrent, the most prevalent one is PDF version, and this is particularly suitable and welcomed by youngsters. There are some features of this version: first of all, PDF version of our AI-300 prep guide can be printed into paper, though which you are able to do some note-writing and highlight the important exam points. Besides our AI-300 Exam Torrent support free demo download, as we mentioned before, it is an ideal way for you to be fully aware of our AI-300 prep guide and then purchasing them if suitable and satisfactory.
| Section | Objectives |
|---|---|
| Topic 1: Optimize generative AI systems and model performance | - Tune prompts, system messages, and grounding strategies - Implement cost management and scaling strategies for GenAI workloads - Optimize inference performance, caching, and throughput - Fine-tune and distill models for specific use cases |
| Topic 2: Design and implement an MLOps infrastructure | - Implement security, governance, and compliance for MLOps - Configure source control, CI/CD pipelines, and automation for ML workflows - Set up Azure Machine Learning workspace and compute targets - Manage environments, data stores, and model registries |
| Topic 3: Implement generative AI quality assurance and observability | - Implement logging, tracing, and telemetry for GenAI applications - Conduct red teaming, adversarial testing, and content filtering - Evaluate generative AI outputs for quality, safety, and grounding - Monitor latency, token usage, cost, and error rates |
| Topic 4: Design and implement a GenAIOps infrastructure | - Set up Microsoft Foundry and Azure AI services for generative AI workloads - Implement RAG (Retrieval-Augmented Generation) pipelines and vector search - Manage API keys, rate limits, and responsible AI guardrails - Configure prompt orchestration, prompt flows, and agent frameworks |
| Topic 5: Implement machine learning model lifecycle and operations | - Monitor model performance, data drift, and operational health - Train, register, and version models using Azure Machine Learning - Retrain, update, and manage model versions in production - Deploy models to real-time and batch endpoints |
It is a truth universally acknowledged that the exam is not easy but the related AI-300 certification is of great significance for workers in this field, I am glad to tell you that our company aims to help you to pass the AI-300 examination as well as gaining the related certification in a more efficient and simpler way. During nearly ten years, our AI-300 Exam Questions have met with warm reception and quick sale in the international market. Our AI-300 study materials are not only as reasonable priced as other makers, but also they are distinctly superior.
NEW QUESTION # 132
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have an Azure Machine Learning workspace. You connect to a terminal session from the Notebooks page in Azure Machine Learning studio.
You plan to add a new Jupyter kernel that will be accessible from the same terminal session.
You need to perform the task that must be completed before you can add the new kernel.
Solution: Delete the Python 3.8 - AzureML kernel.
Does the solution meet the goal?
Answer: B
Explanation:
Correct:
* Create an environment.
Incorrect:
* Delete the Python 3.6 - AzureML kernel.
* Delete the Python 3.8 - AzureML kernel.
Note:
Before you can add a new Jupyter kernel on an Azure Machine Learning compute instance terminal, you must create a Conda environment.
Required Workflow
To officially provision and expose the new kernel to your Azure Machine Learning studio Notebooks, you need to execute the following full process from your terminal session:
Create the environment: Provision a new isolated environment (e.g., using conda create -n newenv python=3.10).
Activate the environment: Run conda activate newenv.
Install dependencies: Add the required ipykernel package using conda install ipykernel or pip install ipykernel.
Register the kernel: Bind the new environment configuration to the global Jupyter directory by running:
python -m ipykernel install --user --name newenv --display-name "My New Kernel" Reference:
https://docs.azure.cn/en-us/machine-learning/how-to-access-terminal
NEW QUESTION # 133
Hotspot Question
You monitor an Azure Machine Learning classification training experiment named train_classification on Azure Notebooks.
You must store a table named table as an artifact in Azure Machine Learning Studio during model training.
You need to collect and list the metrics by using MLflow.
How should you complete the code segment? To answer, select the appropriate option in the answer area.
NOTE: Each correct selection is worth one point.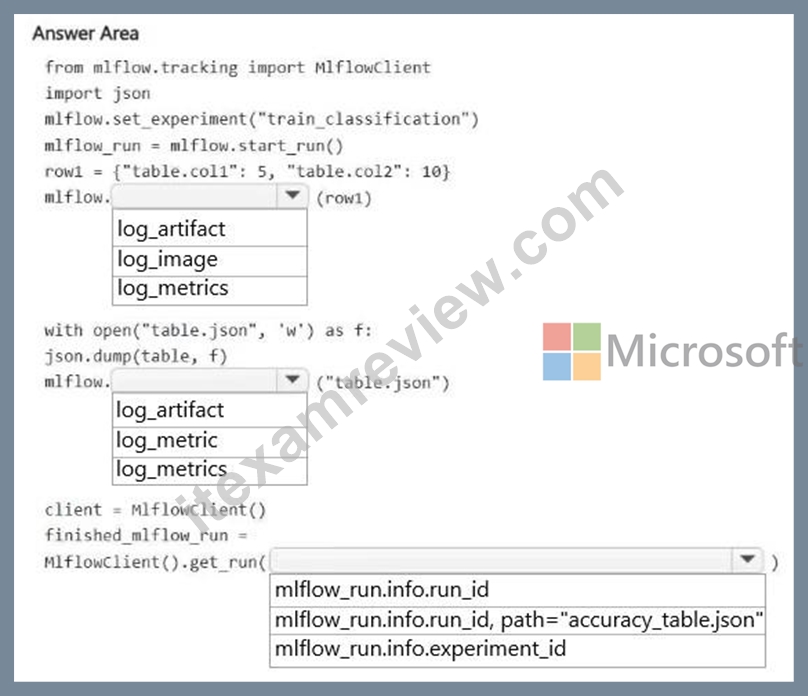
Answer:
Explanation: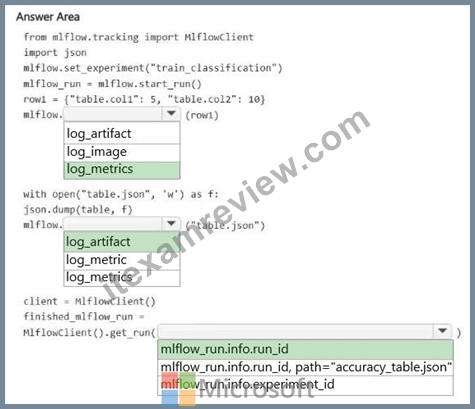
Explanation:
Box 1: log_metrics
Log Metrics dictionary
The dictionary row1 contains key-value pairs representing metrics. The mlflow.log_metrics() function is used to log multiple metrics simultaneously.
Box 2: log_artifact
Save Table Artifact
The code writes a JSON file locally and needs to upload it to the experiment run. The mlflow.log_artifact() function logs a local file or directory as an artifact in Azure Machine Learning Studio.
Box 3: mlflow_run.info.run_id
Retrieve Run ID
To fetch the finalized run data using the MlflowClient, you need to pass the unique run ID string.
This identifier is accessed via the active run object using mlflow_run.info.run_id. Note that you also need to use the instantiated client object variable instead of the class name MlflowClient to call the method correctly.
Reference:
https://levelup.gitconnected.com/mlops-mastering-mlflow-unlocking-efficient-model-management-and-experiment-tracking-d9d0e71cc697
NEW QUESTION # 134
Drag and Drop Question
A team deploys a generative AI application that uses a model deployed in Microsoft Foundry. The application must support latency monitoring under production load.
You need to enable performance observability.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.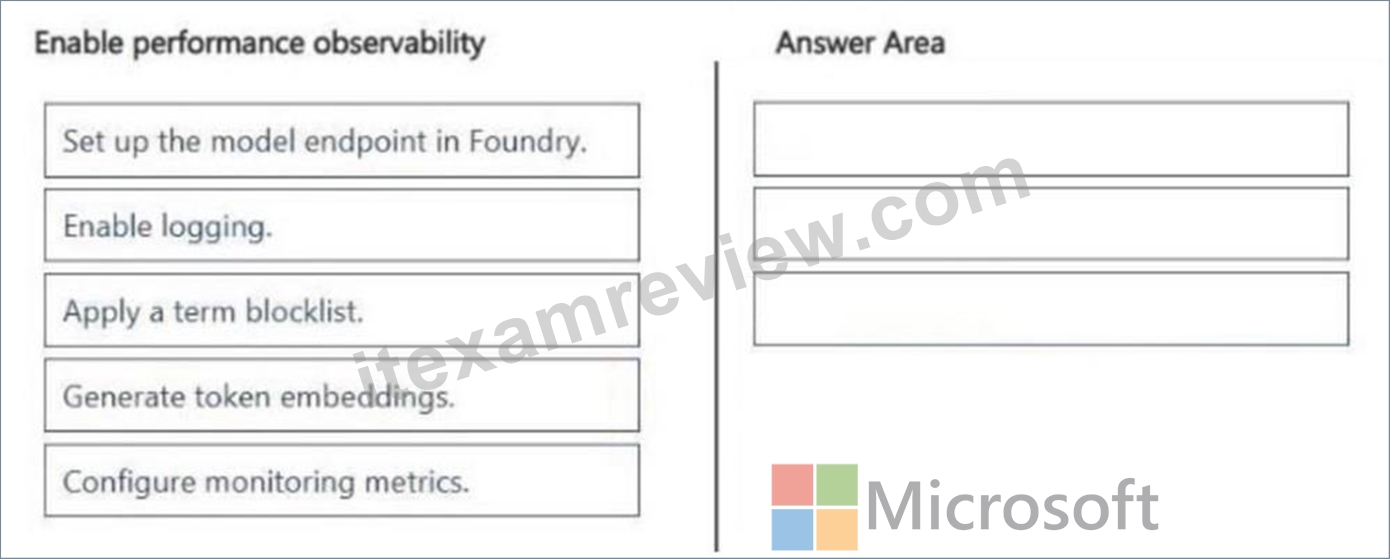
Answer:
Explanation: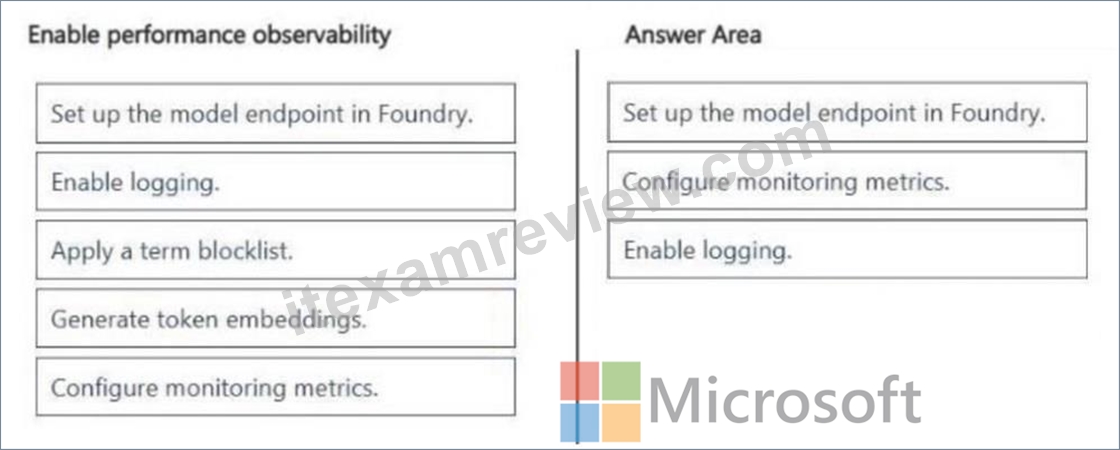
NEW QUESTION # 135
Hotspot Question
A team is preparing a generative AI application for production deployment. The application generates structured responses that must be evaluated for quality before each release.
The organization requires repeatable evaluation results that can be compared across builds and environments.
You need to configure evaluation inputs so quality metrics can be reliably calculated across test runs.
How should you prepare the evaluation inputs? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.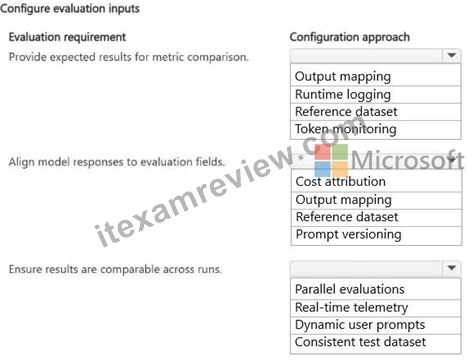
Answer:
Explanation: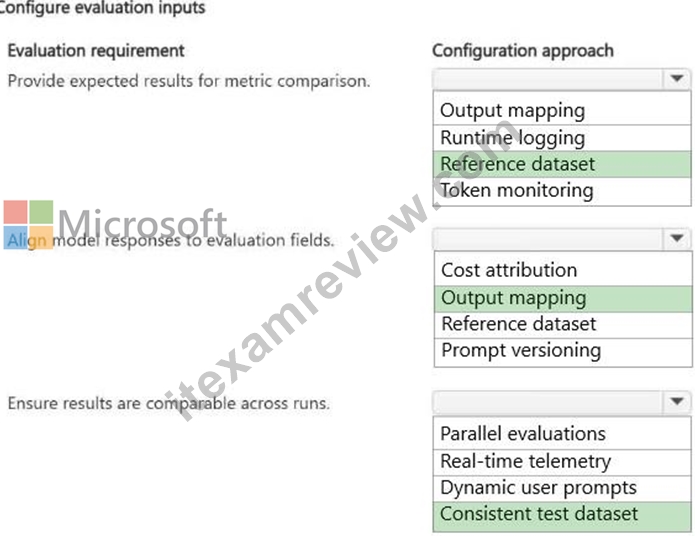
Explanation:
Box 1: Reference dataset
Provide expected results for metric comparison.
A reference dataset contains predefined input prompts matched with ground-truth "expected results" (or golden outputs). To calculate quality metrics reliably and compare them across builds and environments, the evaluation framework needs this baseline data to score the generated outputs against a consistent benchmark.
Box 2: Output mapping
Align model responses to evaluation fields.
Output mapping is the process of aligning generative model responses to specific evaluation fields. For structured outputs, your evaluation dataset needs to know exactly which part of the generated response corresponds to the ground truth or target metrics. Configuring output mapping ensures that data fields are aligned consistently across different test runs, making the evaluation repeatable and comparable across builds and environments.
Box 3: Consistent test dataset
Ensure results are comparable across runs.
A consistent test dataset is used to reliably compare evaluation metrics across different builds and environments, you must test the application using the exact same inputs each time. A fixed, high-quality test dataset ensures that changes in metrics reflect changes in the model or application logic rather than variations in the test data itself.
Reference:
https://testquality.com/llm-evaluation-metrics-testing-strategies/
https://www.freecodecamp.org/news/how-to-evaluate-and-select-the-right-llm-for-your-genai-application/
NEW QUESTION # 136
A team is experimenting with traditional models for a classification workflow in Azure Machine Learning.
The team requires a consistent way to manage assets that are created during experimentation.
You need to ensure that artifacts can be reused and governed across projects.
Which asset should you register?
Answer: A
Explanation:
In an Azure Machine Learning classification workflow, you should register Models.
Registration creates a versioned asset in your workspace or a centralized registry, which is essential for ensuring that artifacts are reusable, governed, and trackable across different projects and environments.
Key Assets for Reuse and Governance
To maintain a consistent and governed workflow, you should focus on registering these specific assets:
Models: The primary artifact. Registering a model allows you to track its lineage (which experiment created it), version it, and deploy it consistently across environments.
Components: These are self-contained pieces of code that perform specific steps in a pipeline (e.g., data cleaning, training). Registering them allows different teams to reuse the same
"traditional" classification logic without rewriting code.
Environments: Encapsulates the software dependencies (Python packages, Docker images) required for your model to run. Registering these ensures reproducibility across different compute targets.
Data Assets: Registering your training and testing datasets as versioned assets ensures that you can always audit exactly what data was used to train a specific model version.
Reference:
https://learn.microsoft.com/en-us/azure/machine-learning/concept-azure-machine-learning-v2
NEW QUESTION # 137
......
If you possess a certificate, it can help you enter a better company and improve your salary. AI-300 exam braindunps of us will help you obtain your certificate successfully. We are a professional certificate exam materials provider, and we have rich experiences in offering high-quality exam materials. In addition, we have a professional team to collect and research the latest information for AI-300 Exam Dumps. We offer you free update for 365 days, so that you can obtain the latest information for the exam. And the latest version for AI-300 exam barindumps will be sent to your email automatically.
AI-300 Exam Bible: https://www.itexamreview.com/AI-300-exam-dumps.html
What's more, part of that ITexamReview AI-300 dumps now are free: https://drive.google.com/open?id=1ULSdhmpiJvh1KNJCGxx3ghQfVw1j1qB7