P.S. Free 2026 Databricks Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by ExamDumpsVCE: https://drive.google.com/open?id=1CrnI1DE3dpnZX6W7CUD-w-AzkPLblOsh
All these three Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) exam questions formats offered by the ExamDumpsVCE are easy to use and perfectly work with all the latest web browsers, operating systems, and devices. The ExamDumpsVCE Databricks-Generative-AI-Engineer-Associate web-based practice test software and desktop practice test software both are the mock Databricks Databricks-Generative-AI-Engineer-Associate Exam that will give you real-time Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) exam environment for quick preparation.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> Databricks-Generative-AI-Engineer-Associate Latest Mock Test <<
While most people would think passing Databricks certification Databricks-Generative-AI-Engineer-Associate exam is difficult. However, if you choose ExamDumpsVCE, you will find gaining Databricks certification Databricks-Generative-AI-Engineer-Associate exam certificate is not so difficult. ExamDumpsVCE training tool is very comprehensive and includes online services and after-sales service. Professional research data is our online service and it contains simulation training examination and practice questions and answers about Databricks Certification Databricks-Generative-AI-Engineer-Associate Exam. ExamDumpsVCE's after-sales service is not only to provide the latest exam practice questions and answers and dynamic news about Databricks Databricks-Generative-AI-Engineer-Associate certification, but also constantly updated exam practice questions and answers and binding.
NEW QUESTION # 89
A Generative AI Engineer is developing an LLM application that users can use to generate personalized birthday poems based on their names.
Which technique would be most effective in safeguarding the application, given the potential for malicious user inputs?
Answer: D
Explanation:
In this case, the Generative AI Engineer is developing an application to generate personalized birthday poems, but there's a need to safeguard againstmalicious user inputs. The best solution is to implement asafety filter (option A) to detect harmful or inappropriate inputs.
* Safety Filter Implementation:Safety filters are essential for screening user input and preventing inappropriate content from being processed by the LLM. These filters can scan inputs for harmful language, offensive terms, or malicious content and intervene before the prompt is passed to the LLM.
* Graceful Handling of Harmful Inputs:Once the safety filter detects harmful content, the system can provide a message to the user, such as "I'm unable to assist with this request," instead of processing or responding to malicious input. This protects the system from generating harmful content and ensures a controlled interaction environment.
* Why Other Options Are Less Suitable:
* B (Reduce Interaction Time): Reducing the interaction time won't prevent malicious inputs from being entered.
* C (Continue the Conversation): While it's possible to acknowledge malicious input, it is not safe to continue the conversation with harmful content. This could lead to legal or reputational risks.
* D (Increase Compute Power): Adding more compute doesn't address the issue of harmful content and would only speed up processing without resolving safety concerns.
Therefore, implementing asafety filterthat blocks harmful inputs is the most effective technique for safeguarding the application.
NEW QUESTION # 90
A Generative AI Engineer I using the code below to test setting up a vector store: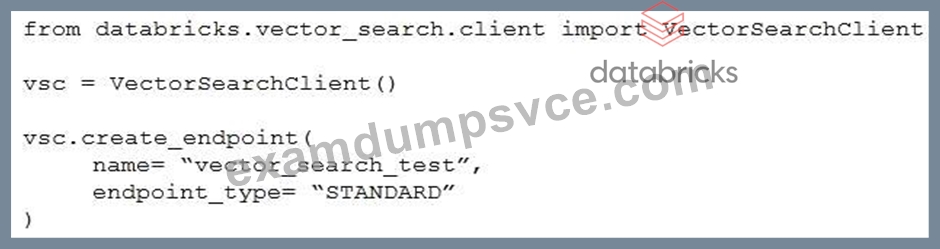
Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?
Answer: B
Explanation:
Context: The Generative AI Engineer is setting up a vector store using Databricks' VectorSearchClient. This is typically done to enable fast and efficient retrieval of vectorized data for tasks like similarity searches.
Explanation of Options:
* Option A: vsc.get_index(): This function would be used to retrieve an existing index, not create one, so it would not be the logical next step immediately after creating an endpoint.
* Option B: vsc.create_delta_sync_index(): After setting up a vector store endpoint, creating an index is necessary to start populating and organizing the data. The create_delta_sync_index() function specifically creates an index that synchronizes with a Delta table, allowing automatic updates as the data changes. This is likely the most appropriate choice if the engineer plans to use dynamic data that is updated over time.
* Option C: vsc.create_direct_access_index(): This function would create an index that directly accesses the data without synchronization. While also a valid approach, it's less likely to be the next logical step if the default setup (typically accommodating changes) is intended.
* Option D: vsc.similarity_search(): This function would be used to perform searches on an existing index; however, an index needs to be created and populated with data before any search can be conducted.
Given the typical workflow in setting up a vector store, the next step after creating an endpoint is to establish an index, particularly one that synchronizes with ongoing data updates, henceOption B.
NEW QUESTION # 91
A Generative Al Engineer is building a production-ready LLM system which replies directly to customers.
The solution makes use of the Foundation Model API via provisioned throughput. They are concerned that the LLM could potentially respond in a toxic or otherwise unsafe way. They also wish to perform this with the least amount of effort.
Which approach will do this?
Answer: A
Explanation:
The task is to prevent toxic or unsafe responses in an LLM system using the Foundation Model API with minimal effort. Let's assess the options.
* Option A: Host Llama Guard on Foundation Model API and use it to detect unsafe responses
* Llama Guard is a safety-focused model designed to detect toxic or unsafe content. Hosting it via the Foundation Model API (a Databricks service) integrates seamlessly with the existing system, requiring minimal setup (just deployment and a check step), and leverages provisioned throughput for performance.
* Databricks Reference:"Foundation Model API supports hosting safety models like Llama Guard to filter outputs efficiently"("Foundation Model API Documentation," 2023).
* Option B: Add some LLM calls to their chain to detect unsafe content before returning text
* Using additional LLM calls (e.g., prompting an LLM to classify toxicity) increases latency, complexity, and effort (crafting prompts, chaining logic), and lacks the specificity of a dedicated safety model.
* Databricks Reference:"Ad-hoc LLM checks are less efficient than purpose-built safety solutions" ("Building LLM Applications with Databricks").
* Option C: Add a regex expression on inputs and outputs to detect unsafe responses
* Regex can catch simple patterns (e.g., profanity) but fails for nuanced toxicity (e.g., sarcasm, context-dependent harm), requiring significant manual effort to maintain and update rules.
* Databricks Reference:"Regex-based filtering is limited for complex safety needs"("Generative AI Cookbook").
* Option D: Ask users to report unsafe responses
* User reporting is reactive, not preventive, and places burden on users rather than the system. It doesn't limit unsafe outputs proactively and requires additional effort for feedback handling.
* Databricks Reference:"Proactive guardrails are preferred over user-driven monitoring" ("Databricks Generative AI Engineer Guide").
Conclusion: Option A (Llama Guard on Foundation Model API) is the least-effort, most effective approach, leveraging Databricks' infrastructure for seamless safety integration.
NEW QUESTION # 92
A generative AI engineer is deploying an AI agent authored with MLflow's ChatAgent interface for a retail company ' s customer support system on Databricks. The agent must handle thousands of inquiries daily, and the engineer needs to track its performance and quality in real-time to ensure it meets service-level agreements. Which metrics are automatically captured by default and made available for monitoring when the agent is deployed using the Mosaic AI Agent Framework?
Answer: D
Explanation:
When deploying an agent via the Mosaic AI Agent Framework (which leverages Databricks Model Serving), operational metrics are captured automatically by default. These include system-level telemetry such as the number of requests per second (volume), the time taken for the model to respond (latency), and the rate of 4xx
/5xx HTTP errors. These are essential for monitoring Service Level Agreements (SLAs). However, Quality metrics (B), such as correctness, groundedness, or adherence to custom guidelines, cannot be determined " automatically " by the serving infrastructure because they require either human feedback or an LLM-as-a- judge evaluation (using Databricks Agent Evaluation). While Databricks makes it easy to generate quality metrics using the mlflow.evaluate API or the inference table, they are not " default operational metrics " that appear without additional evaluation configuration.
NEW QUESTION # 93
A Generative AI Engineer is designing an LLM-powered live sports commentary platform. The platform provides real-time updates and LLM-generated analyses for any users who would like to have live summaries, rather than reading a series of potentially outdated news articles.
Which tool below will give the platform access to real-time data for generating game analyses based on the latest game scores?
Answer: A
Explanation:
* Problem Context: The engineer is developing an LLM-powered live sports commentary platform that needs to provide real-time updates and analyses based on the latest game scores. The critical requirement here is the capability to access and integrate real-time data efficiently with the platform for immediate analysis and reporting.
* Explanation of Options:
* Option A: DatabricksIQ: While DatabricksIQ offers integration and data processing capabilities, it is more aligned with data analytics rather than real-time feature serving, which is crucial for immediate updates necessary in a live sports commentary context.
* Option B: Foundation Model APIs: These APIs facilitate interactions with pre-trained models and could be part of the solution, but on their own, they do not provide mechanisms to access real- time game scores.
* Option C: Feature Serving: This is the correct answer as feature serving specifically refers to the real-time provision of data (features) to models for prediction. This would be essential for an LLM that generates analyses based on live game data, ensuring that the commentary is current and based on the latest events in the sport.
* Option D: AutoML: This tool automates the process of applying machine learning models to real-world problems, but it does not directly provide real-time data access, which is a critical requirement for the platform.
Thus,Option C(Feature Serving) is the most suitable tool for the platform as it directly supports the real-time data needs of an LLM-powered sports commentary system, ensuring that the analyses and updates are based on the latest available information.
NEW QUESTION # 94
......
In the PDF version, real Databricks-Generative-AI-Engineer-Associate exam questions are available. These Databricks Databricks-Generative-AI-Engineer-Associate real questions are printable and portable. You can take this PDF document anywhere and study for the Databricks Certified Generative AI Engineer Associate (Databricks-Generative-AI-Engineer-Associate) exam without time restrictions. ExamDumpsVCE regularly make changes in the Databricks-Generative-AI-Engineer-Associate PDF format when required. Databricks-Generative-AI-Engineer-Associate questions in this format are relevant to the actual test.
Latest Databricks-Generative-AI-Engineer-Associate Test Questions: https://www.examdumpsvce.com/Databricks-Generative-AI-Engineer-Associate-valid-exam-dumps.html
DOWNLOAD the newest ExamDumpsVCE Databricks-Generative-AI-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1CrnI1DE3dpnZX6W7CUD-w-AzkPLblOsh