DP-750 exam dumps are so comprehensive that you do not need any other study material. The DP-750 study material is all-inclusive and contains straightaway questions and answers comprising all the important topics in the actual DP-750 demo vce. DP-750 latest download demo is available for all of you. You can know the exam format and part questions of our Complete DP-750 Exam Dumps. Besides, we can ensure 100% passing and offer the Money back guarantee when you choose our DP-750 pdf dumps.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Prepare and process data | 30-35% | - Ingest and transform data
|
| Topic 2: Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Topic 3: Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Topic 4: Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
>> Vce Microsoft DP-750 Free <<
The study materials from our company can help you get your certification easily, we believe that you have been unable to hold yourself back to understand our Implementing Data Engineering Solutions Using Azure Databricks guide torrent, if you use our study materials, it will be very easy for you to save a lot of time. In order to meet the needs of all customers, Our DP-750 study torrent has a long-distance aid function. If you feel confused about our DP-750 test torrent when you use our products, do not hesitate and send a remote assistance invitation to us for help, we are willing to provide remote assistance for you in the shortest time.
NEW QUESTION # 72
You manage Declarative Automation Bundles by using the Databricks CLI.
You run the following command in a terminal window.
databricks bundle init
What occurs when you run the command?
Answer: B
Explanation:
The databricks bundle init command initializes a new bundle project from a selected default or custom project template. It prompts for relevant project values and creates the local project structure and starter configuration files. It does not deploy resources; deployment is performed with databricks bundle deploy. It does not merely validate an existing configuration, because validation uses databricks bundle validate. Running deployed bundle resources requires databricks bundle run followed by the resource key. The distinction matters in an automated bundle lifecycle: initialization scaffolds the project, validation checks configuration, deployment creates or updates workspace resources, and run starts a configured job or pipeline. Therefore, option A accurately describes the initialization command's function. Microsoft Learn
NEW QUESTION # 73
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named db1.sales_orders.
dbl sales_orders is updated nightly and has change data feed (CDF) enabled.
You need to ingest all the changes from the dbl.sales.ordets table, including inserts, updates, and deletes, into a downstream pipeline.
How should you complete the PsySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.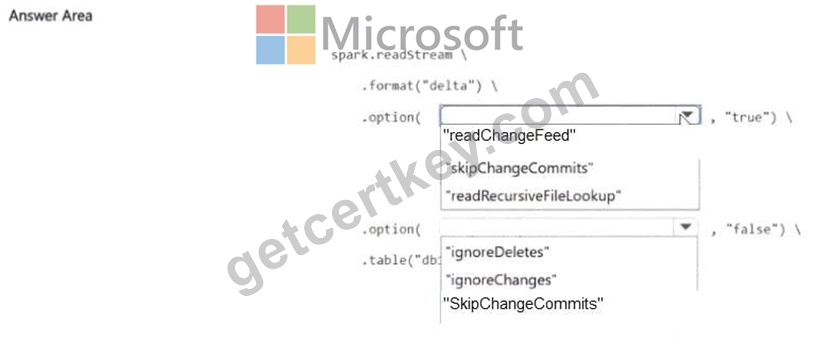
Answer:
Explanation: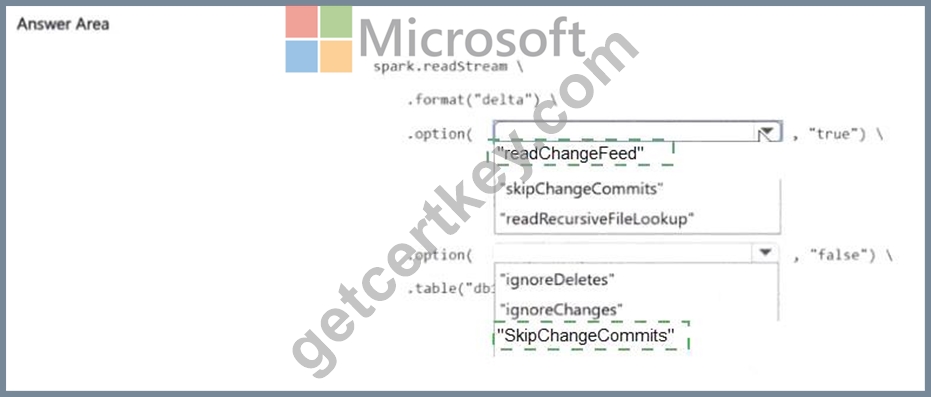
Explanation:
When Change Data Feed (CDF) is enabled on a Delta table, reading the full change stream - inserts, updates, and deletes - requires this pattern:
spark.readStream.format('delta').option('readChangeFeed', 'true').table('db1.sales_orders') The readChangeFeed option switches the reader from the default 'new rows only' mode to a mode that returns all change events. Each row in the resulting DataFrame includes a _change_type column (insert, update_preimage, update_postimage, delete) so downstream processing can distinguish what happened to each record.
Without readChangeFeed = true, streaming a Delta table only surfaces newly appended rows. Deletes and updates are invisible, making it unsuitable for true CDC pipelines. The stream also supports startingVersion or startingTimestamp options to begin from a specific point in table history rather than the current moment.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/delta-change-data-feed
NEW QUESTION # 74
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains two Delta tables named Table1 and Table2 of the same data type.
Table1 contains a column named Columnl. Table2 contains a column named Column2. You run the following query.
SELECT Column1
FROM Table1
GROUP BY Column1
HAVING COUNT(") > 1
INTERSECT
SELECT C0lumn2
FROM Table2
GROUP BY Column2
HAVING COUNT(') > 1;
What occurs when you run the query?
Answer: C
Explanation:
The correct answer is B - values appear in both tables more than once.
Reading the query from the inside out: each subquery identifies values that appear more than once within their own table. The first subquery returns Column1 values that are duplicated in Table1. The second returns Column2 values that are duplicated in Table2. INTERSECT then returns only the values that appear in both result sets - meaning values that are duplicated in Table1 AND also duplicated in Table2.
Option A describes a UNION result (values in either table), not INTERSECT. Option C only considers duplicates in Table1, ignoring the Table2 condition - that would be the first subquery in isolation. Option D describes values exclusive to Table2 (EXCEPT or MINUS), the opposite of INTERSECT's requirement that values appear in both sets.
INTERSECT always requires membership in both operands - that's its fundamental definition in standard SQL.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/sql-ref-syntax-qry-select- setops
NEW QUESTION # 75
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Sales. Sales stores transaction data and contains the following columns:
* transactionjd (string)
* transaction date (date)
* amount (decimal)
You need to implement the following data quality requirements by using table-level data quality enforcement:
* amount must be greater than 0.
* transaction id must never be null.
* Invalid records must be rejected when data is written to the Sales table.
What should you do?
Answer: B
Explanation:
The correct answer is D - a NOT NULL constraint on transaction_id and a CHECK constraint on amount.
Delta Lake table constraints are enforced at write time by the Delta engine itself. A NOT NULL constraint rejects any INSERT or UPDATE that would place a null in transaction_id. A CHECK constraint with amount
> 0 rejects any row where amount is zero or negative. Combined, they implement exactly the stated quality rules: bad rows are rejected when data is written, not filtered away at read time.
Options A and C (SELECT with WHERE / views) are read-time constructs - they don ' t prevent invalid data from entering the table. A clever pipeline bypass could write directly to the table and skip the view entirely. Option B (row-level security with WHERE conditions) is an access-control feature for restricting which rows users see, not for enforcing data quality on writes. Table constraints are the only mechanism that genuinely blocks bad data at the storage layer.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/delta-constraints
NEW QUESTION # 76
You have an Azure Databricks workspace that uses serverless compute.
You need to ingest data by using Lakeflow Jobs. New records must be processed as soon as they become available.
Which type of job trigger should you use for the ingestion?
Answer: C
Explanation:
The correct answer is D - Continuous trigger.
A Continuous trigger keeps the job running as a perpetual loop. As soon as one micro-batch or iteration completes, the next begins. New records are picked up with the shortest possible latency - as close to real- time as a Lakeflow Jobs pipeline gets.
File Arrival (Option B) is event-driven but introduces per-file trigger overhead and is best suited for file-based ingestion rather than continuous streaming workloads. Scheduled (Option C) runs at fixed clock intervals - if new data arrives between runs, it waits until the next scheduled execution. Manual (Option A) requires a human to start each run.
The question specifies serverless compute, which pairs naturally with Continuous trigger because serverless handles cluster lifecycle automatically - the job stays active without managing a persistent cluster. 'New records must be processed as soon as they become available' is the exact use case the Continuous trigger is designed for.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/triggers
NEW QUESTION # 77
......
Our company is a reliable and leading company in the business of DP-750 test dumps, we are famous for the commitment. We have in this business for years, and we have a team of high efficiency. The DP-750 test dumps are quite efficient and correct, we have the professional team for update of the DP-750 test material, and if we have any new version, we will send it to you timely, it will help you to pass the exam successfully.
Exam DP-750 Book: https://www.getcertkey.com/DP-750_braindumps.html