참고: Itexamdump에서 Google Drive로 공유하는 무료 2026 Nutanix NCM-MCI 시험 문제집이 있습니다: https://drive.google.com/open?id=1DzXPr-BLtNAz7AnuyHFllMg7_YibAW0l
지금 사회에 능력자들은 아주 많습니다.it인재들도 더욱더 많아지고 있습니다.많은 it인사들은 모두 관연 it인증시험에 참가하여 자격증취득을 합니다.자기만의 자리를 확실히 지키고 더 높은 자리에 오르자면 필요한 스펙이니까요.NCM-MCI시험은Nutanix인증의 중요한 시험이고 또 많은 it인사들은Nutanix자격증을 취득하려고 노력하고 있습니다.
| 주제 | 소개 |
|---|---|
| 주제 1 |
|
| 주제 2 |
|
| 주제 3 |
|
| 주제 4 |
|
| 주제 5 |
|
Itexamdump는 고객님께서Nutanix NCM-MCI첫번째 시험에서 패스할수 있도록 최선을 다하고 있습니다. 만일 어떤 이유로 인해 고객님이Nutanix NCM-MCI시험에서 실패를 한다면 Itexamdump는Nutanix NCM-MCI덤프비용 전액을 환불 해드립니다. 시중에서 가장 최신버전인Nutanix NCM-MCI덤프로 시험패스 예약하세요.
질문 # 10
Task 9
Part1
An administrator logs into Prism Element and sees an alert stating the following:
Cluster services down on Controller VM (35.197.75.196)
Correct this issue in the least disruptive manner.
Part2
In a separate request, the security team has noticed a newly created cluster is reporting.
CVM [35.197.75.196] is using the default password.
They have provided some new security requirements for cluster level security.
Security requirements:
Update the default password for the root user on the node to match the admin user password: Note: 192.168.x.x is not available. To access a node use the Host IP (172.30.0.x) from a CVM or the supplied external IP address.
Update the default password for the nutanix user on the CVM to match the admin user password.
Resolve the alert that is being reported.
Output the cluster-wide configuration of the SCMA policy to Desktop\Files\output.txt before changes are made.
Enable the Advance intrusion Detection Environment (AIDE) to run on a weekly basis for the cluster.
Enable high-strength password policies for the cluster.
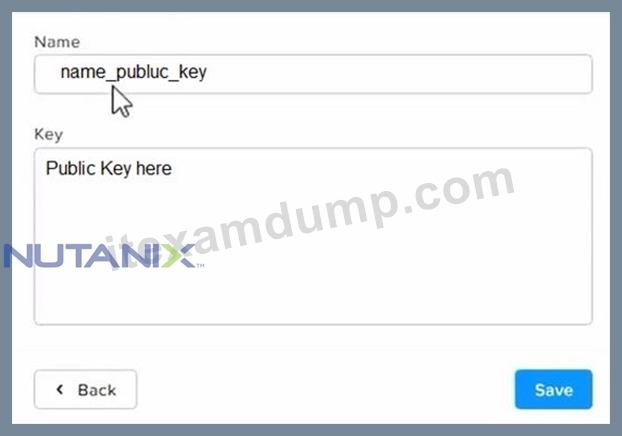
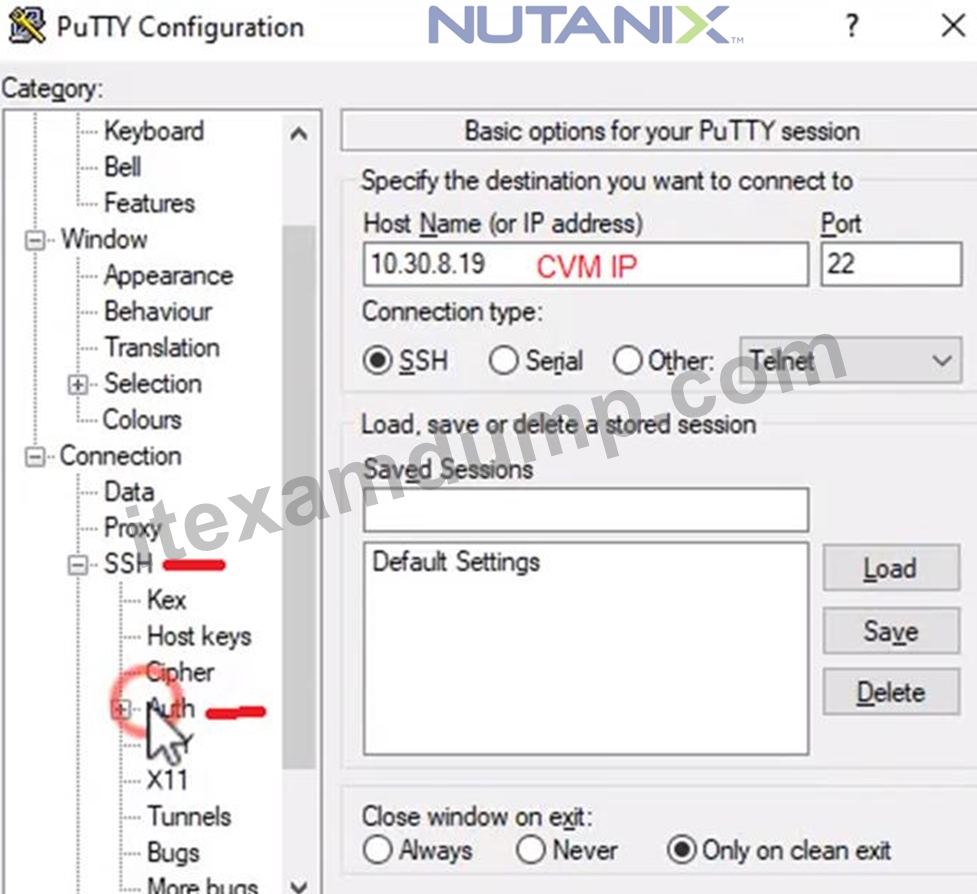
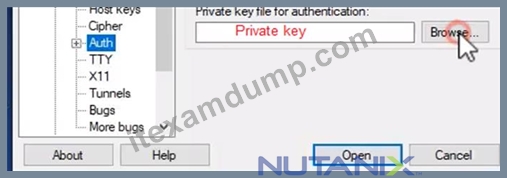
Ensure CVMs require SSH keys for login instead of passwords. (SSH keys are located in the Desktop\Files\SSH folder).
Ensure the clusters meets these requirements. Do not reboot any cluster components.
정답:
설명:
See the Explanation for step by step solution
Explanation:
To correct the issue of cluster services down on Controller VM (35.197.75.196) in the least disruptive manner, you need to do the following steps:
Log in to Prism Element using the admin user credentials.
Go to the Alerts page and click on the alert to see more details.
You will see which cluster services are down on the Controller VM. For example, it could be cassandra, curator, stargate, etc.
To start the cluster services, you need to SSH to the Controller VM using the nutanix user credentials. You can use any SSH client such as PuTTY or Windows PowerShell to connect to the Controller VM. You will need the IP address and the password of the nutanix user, which you can find in Desktop\Files\SSH\nutanix.txt.
Once you are logged in to the Controller VM, run the command:
cluster status | grep -v UP
This will show you which services are down on the Controller VM.
To start the cluster services, run the command:
cluster start
This will start all the cluster services on the Controller VM.
To verify that the cluster services are running, run the command:
cluster status | grep -v UP
This should show no output, indicating that all services are up.
To clear the alert, go back to Prism Element and click on Resolve in the Alerts page.
To meet the security requirements for cluster level security, you need to do the following steps:
To update the default password for the root user on the node to match the admin user password, you need to SSH to the node using the root user credentials. You can use any SSH client such as PuTTY or Windows PowerShell to connect to the node. You will need the IP address and the password of the root user, which you can find in Desktop\Files\SSH\root.txt.
Once you are logged in to the node, run the command:
passwd
This will prompt you to enter a new password for the root user. Enter the same password as the admin user, which you can find in Desktop\Files\SSH\admin.txt.
To update the default password for the nutanix user on the CVM to match the admin user password, you need to SSH to the CVM using the nutanix user credentials. You can use any SSH client such as PuTTY or Windows PowerShell to connect to the CVM. You will need the IP address and the password of the nutanix user, which you can find in Desktop\Files\SSH\nutanix.txt.
Once you are logged in to the CVM, run the command:
passwd
This will prompt you to enter a new password for the nutanix user. Enter the same password as the admin user, which you can find in Desktop\Files\SSH\admin.txt.
To resolve the alert that is being reported, go back to Prism Element and click on Resolve in the Alerts page.
To output the cluster-wide configuration of SCMA policy to Desktop\Files\output.txt before changes are made, you need to log in to Prism Element using the admin user credentials.
Go to Security > SCMA Policy and click on View Policy Details. This will show you the current settings of SCMA policy for each entity type.
Copy and paste these settings into a new text file named Desktop\Files\output.txt.
To enable AIDE (Advanced Intrusion Detection Environment) to run on a weekly basis for the cluster, you need to log in to Prism Element using the admin user credentials.
Go to Security > AIDE Configuration and click on Enable AIDE. This will enable AIDE to monitor file system changes on all CVMs and nodes in the cluster.
Select Weekly as the frequency of AIDE scans and click Save.
To enable high-strength password policies for the cluster, you need to log in to Prism Element using the admin user credentials.
Go to Security > Password Policy and click on Edit Policy. This will allow you to modify the password policy settings for each entity type.
For each entity type (Admin User, Console User, CVM User, and Host User), select High Strength as the password policy level and click Save.
To ensure CVMs require SSH keys for login instead of passwords, you need to log in to Prism Element using the admin user credentials.
Go to Security > Cluster Lockdown and click on Configure Lockdown. This will allow you to manage SSH access settings for the cluster.
Uncheck Enable Remote Login with Password. This will disable password-based SSH access to the cluster.
Click New Public Key and enter a name for the key and paste the public key value from Desktop\Files\SSH\id_rsa.pub. This will add a public key for key-based SSH access to the cluster.
Click Save and Apply Lockdown. This will apply the changes and ensure CVMs require SSH keys for login instead of passwords.
Part1
Enter CVM ssh and execute:
cluster status | grep -v UP
cluster start
If there are issues starting some services, check the following:
Check if the node is in maintenance mode by running the ncli host ls command on the CVM. Verify if the parameter Under Maintenance Mode is set to False for the node where the services are down. If the parameter Under Maintenance Mode is set to True, remove the node from maintenance mode by running the following command:
* nutanix@cvm$ ncli host edit id=<host id> enable-maintenance-mode=false You can determine the host ID by using ncli host ls.
See the troubleshooting topics related to failed cluster services in the Advanced Administration Guide available from the Nutanix Portal's Software Documentation page. (Use the filters to search for the guide for your AOS version). These topics have information about common and AOS-specific logs, such as Stargate, Cassandra, and other modules.
* Check for any latest FATALs for the service that is down. The following command prints all the FATALs for a CVM. Run this command on all CVMs.
nutanix@cvm$ for i in `svmips`; do echo "CVM: $i"; ssh $i "ls -ltr /home/nutanix/data/logs/*.FATAL"; done NCC Health Check: cluster_services_down_check (nutanix.com) Part2 Update the default password for the root user on the node to match the admin user password echo -e "CHANGING ALL AHV HOST ROOT PASSWORDS.\nPlease input new password: "; read -rs password1; echo "Confirm new password: "; read -rs password2; if [ "$password1" == "$password2" ]; then for host in $(hostips); do echo Host $host; echo $password1 | ssh root@$host "passwd --stdin root"; done; else echo "The passwords do not match"; fi Update the default password for the nutanix user on the CVM sudo passwd nutanix Output the cluster-wide configuration of the SCMA policy ncli cluster get-hypervisor-security-config Output Example:
nutanix@NTNX-372a19a3-A-CVM:10.35.150.184:~$ ncli cluster get-hypervisor-security-config Enable Aide : false Enable Core : false Enable High Strength P... : false Enable Banner : false Schedule : DAILY Enable iTLB Multihit M... : false Enable the Advance intrusion Detection Environment (AIDE) to run on a weekly basis for the cluster.
ncli cluster edit-hypervisor-security-params enable-aide=true
ncli cluster edit-hypervisor-security-params schedule=weekly
Enable high-strength password policies for the cluster.
ncli cluster edit-hypervisor-security-params enable-high-strength-password=true Ensure CVMs require SSH keys for login instead of passwords
https://portal.nutanix.com/page/documents/kbs/details?targetId=kA0600000008gb3CAA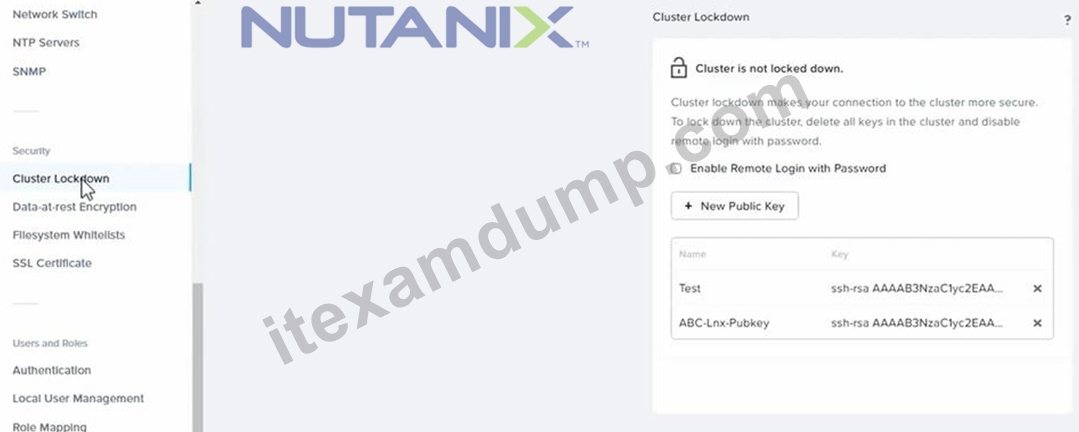
질문 # 11
Task 11
An administrator has noticed that after a host failure, the SQL03 VM was not powered back on from another host within the cluster. The Other SQL VMs (SQL01, SQL02) have recovered properly in the past.
Resolve the issue and configure the environment to ensure any single host failure affects a minimal number os SQL VMs.
Note: Do not power on any VMs
정답:
설명:
See the Explanation for step by step solution
Explanation:
One possible reason why the SQL03 VM was not powered back on after a host failure is that the cluster was configured with the default (best effort) VM high availability mode, which does not guarantee the availability of VMs in case of insufficient resources on the remaining hosts. To resolve this issue, I suggest changing the VM high availability mode to guarantee (reserved segments), which reserves some memory on each host for failover of VMs from a failed host. This way, the SQL03 VM will have a higher chance of being restarted on another host in case of a host failure.
To change the VM high availability mode to guarantee (reserved segments), you can follow these steps:
Log in to Prism Central and select the cluster where the SQL VMs are running.
Click on the gear icon on the top right corner and select Cluster Settings.
Under Cluster Services, click on Virtual Machine High Availability.
Select Guarantee (Reserved Segments) from the drop-down menu and click Save.
To configure the environment to ensure any single host failure affects a minimal number of SQL VMs, I suggest using anti-affinity rules, which prevent VMs that belong to the same group from running on the same host. This way, if one host fails, only one SQL VM will be affected and the other SQL VMs will continue running on different hosts.
To create an anti-affinity rule for the SQL VMs, you can follow these steps:
Log in to Prism Central and click on Entities on the left menu.
Select Virtual Machines from the drop-down menu and click on Create Group.
Enter a name for the group, such as SQL Group, and click Next.
Select the SQL VMs (SQL01, SQL02, SQL03) from the list and click Next.
Select Anti-Affinity from the drop-down menu and click Next.
Review the group details and click Finish.
I hope this helps. How else can I help?
https://portal.nutanix.com/page/documents/details?targetId=AHV-Admin-Guide-v6_5:ahv-affinity-policies-c.html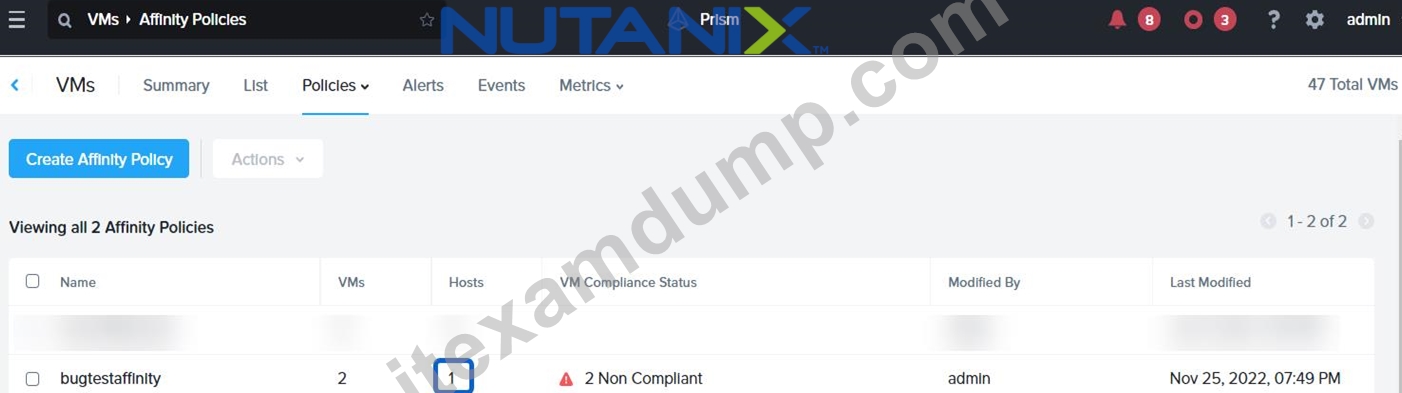
질문 # 12
Refer to the exhibit.
Task1
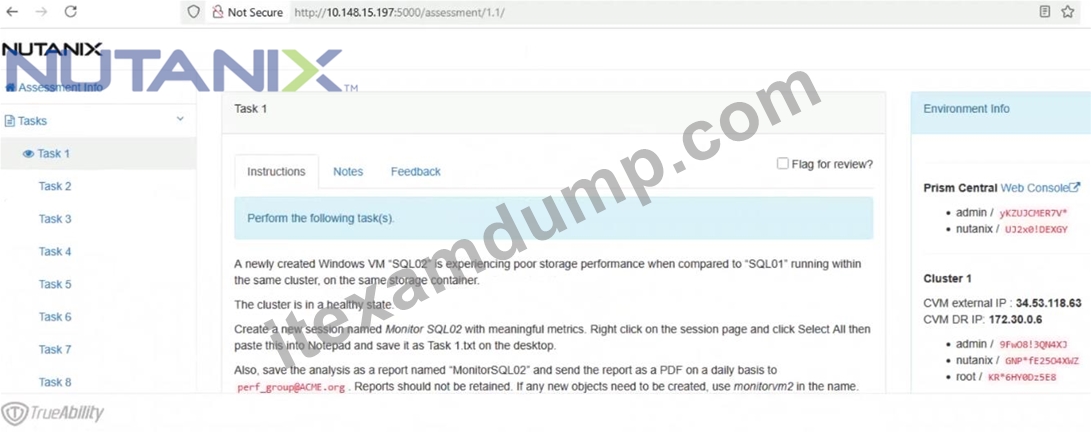
A newly created Windows VM "SQL02" is experiencing poor storage performance when compared to "SQL01" running within the same cluster, on the same storage container.
The cluster is in a healthy state.
Create a new session named Monitor SQL02 with meaningful metrics. Right click on the session page and click Select All then paste this into Notepad and save it as Task 1.txt on the desktop.
Also, save the analysis as a report named "MonitorSQL02" and send the report as a PDF on a daily basis to perf_group@ACME.org. Reports should not be retained. If any new objects need to be created, use monitorvm2 in the name.
Finally, correct the issue within "SQL02"
Notes:
Do not power on the VMs.
While you will be creating a session, you will need to examine the VM configurations to determine the issue.
Do not delete the VM to resolve the issue, any other destructive change is acceptable
정답:
설명:
See the Explanation
Explanation:
This is a classic Nutanix performance troubleshooting scenario. The issue is almost certainly that the VM was created using the wrong Disk Bus Type (IDE or SATA instead of SCSI).
Here is the step-by-step solution to complete Task 1.
Part 1: Analysis and Reporting
Create the Session
Log in to Prism Central (or Prism Element, depending on the exam environment, but Analysis is usually a PC feature).
Navigate to Operations -> Analysis.
Click New Session.
Name: Monitor SQL02
Entity: Search for and select the VM named SQL02.
Metrics: Since the issue is storage performance, search for and add these specific metrics:
Hypervisor IOPS (or Controller IOPS)
Hypervisor IO Latency (or Controller IO Latency)
Hypervisor IO Bandwidth
Click Save.
Save Session Data (Task 1.txt)
Open the "Monitor SQL02" session you just created.
(Per instructions): Right-click anywhere on the chart/data area -> Click Select All.
Copy the selected text (Ctrl+C).
Open Notepad on the provided desktop.
Paste the data.
Save the file as Task 1.txt on the Desktop.
Create and Schedule the Report
While still in the Analysis session, click the Create Report (or "Add to Report") button.
Report Name: MonitorSQL02
Report Settings:
Format: PDF
Frequency: Daily
Email Recipient: perf_group@ACME.org
Retention: 0 (or "Do not retain", as requested).
Note: If the system forces you to create a new Report object and MonitorSQL02 is rejected, use monitorvm2 as the name per the instructions.
Save/Schedule the report.
Part 2: Diagnose and Fix the Issue
The Issue:
VM SQL02 was likely created with its data disks set to IDE or SATA.
Why this causes poor performance: IDE/SATA are emulated hardware with high CPU overhead and low queue depths (single-threaded).
The Standard: SQL01 (the healthy VM) is using SCSI, which is multithreaded and optimized for virtualization.
The Fix (Steps):
Navigate to the VM list in Prism.
Select SQL02 and click Update (or Edit).
Scroll down to the Disks section.
Identify the data disk(s). You will see the Bus Type listed as IDE or SATA.
Do not delete the VM. instead, perform a disk conversion (destructive change to the disk is allowed, but we want to keep the data).
Method to Convert (Clone to SCSI):
Hover over the IDE/SATA disk to see the path/filename of the vDisk (or write it down).
Click Add New Disk.
Operation: select Clone from ADSF file.
Path: Browse to the storage container and select the file associated with the current IDE disk.
Bus Type: Select SCSI (This is the critical fix).
Index: Ensure it doesn't conflict with existing disks (usually index 1 or higher for data).
Click Add.
Once the new SCSI disk is added, find the original IDE/SATA disk and click the X to remove it.
Click Save.
Note: You do not need to power on the VM to verify. The change from IDE to SCSI allows the VM to use the Nutanix VirtIO drivers for maximum storage performance.
질문 # 13
Task 13
The application team is reporting performance degradation for a business-critical application that runs processes all day on Saturdays.
The team is requesting monitoring or processor, memory and storage utilization for the three VMs that make up the database cluster for the application: ORA01, ORA02 and ORA03.
The report should contain tables for the following:
At the cluster level, only for the current cluster:
The maximum percentage of CPU used
At the VM level, including any future VM with the prefix ORA:
The maximum time taken to process I/O Read requests
The Maximum percentage of time a VM waits to use physical CPU, out of the local CPU time allotted to the VM.
The report should run on Sundays at 12:00 AM for the previous 24 hours. The report should be emailed to appdev@cyberdyne.net when competed.
Create a report named Weekends that meets these requirements
Note: You must name the report Weekends to receive any credit. Any other objects needed can be named as you see fit. SMTP is not configured.
A: Click Next.
Click on Add to add this custom view to your report. Click Next.
Under the Report Settings option, select Weekly from the Schedule drop-down menu and choose Sunday as the day of week. Enter 12:00 AM as the time of day. Enter appdev@cyberdyne.net as the Email Recipient. Select CSV as the Report Output Format. Click Next.
Review the report details and click Finish.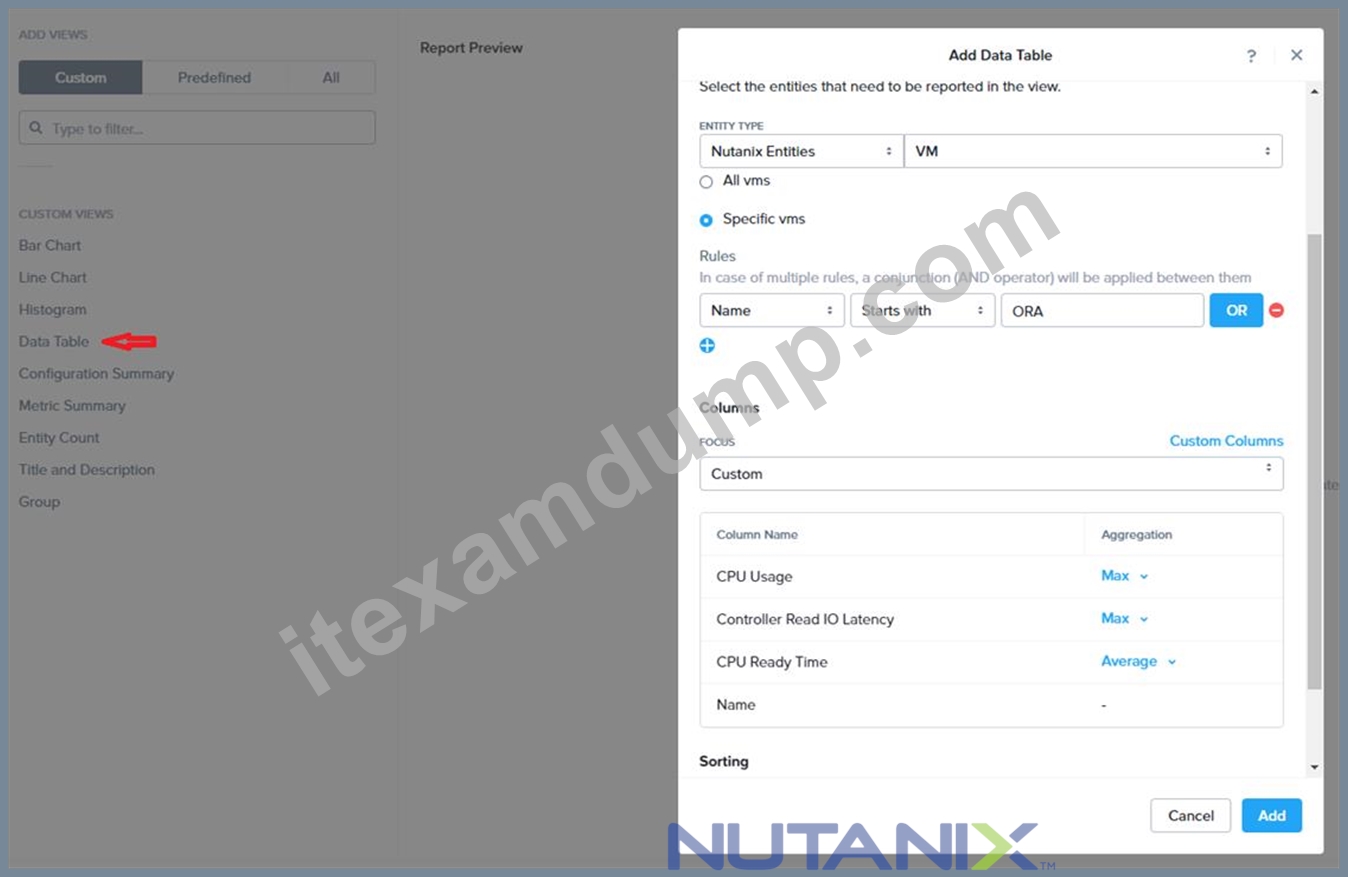
정답:
설명:
See the Explanation for step by step solution
Explanation:
To create a report named Weekends that meets the requirements, you can follow these steps:
Log in to Prism Central and click on Entities on the left menu.
Select Virtual Machines from the drop-down menu and click on Create Report.
Enter Weekends as the report name and a description if required. Click Next.
Under the Custom Views section, select Data Table. Click Next.
Under the Entity Type option, select Cluster. Click Next.
Under the Custom Columns option, add the following variable: CPU Usage (%). Click Next.
Under the Aggregation option for CPU Usage (%), select Max. Click Next.
Under the Filter option, select Current Cluster from the drop-down menu. Click Next.
Click on Add to add this custom view to your report. Click Next.
Under the Custom Views section, select Data Table again. Click Next.
Under the Entity Type option, select VM. Click Next.
Under the Custom Columns option, add the following variables: Name, I/O Read Latency (ms), VM Ready Time (%). Click Next.
Under the Aggregation option for I/O Read Latency (ms) and VM Ready Time (%), select Max. Click Next.
Under the Filter option, enter ORA* in the Name field. This will include any future VM with the prefix OR
질문 # 14
Topic 1, Performance Based Questions
Environment
You have been provisioned a dedicated environment for your assessment which includes the following:
Workstation
* windows Server 2019
* All software/tools/etc to perform the required tasks
* Nutanix Documentation and whitepapers can be found in desktop\files\Documentation
* Note that the workstation is the system you are currently togged into Nutanix Cluster
* There are three clusters provided. The connection information for the relevant cluster will be displayed to the high of the question Please make sure you are working on the correct cluster for each item Please ignore any licensing violations
* Cluster A is a 3-node cluster with Prism Central 2022.6 where most questions will be performed
* Cluster B is a one-node cluster and has one syslog item and one security item to perform
* Cluster D is a one-node duster with Prism Central 5.17 and has a security policy item to perform Important Notes
* If the text is too small and hard to read, or you cannot see an of the GUI. you can increase/decrease the zoom of the browser with CTRL + ,and CTRL + (the plus and minus keys) You will be given 3 hours to complete the scenarios for Nutanix NCMMCI Once you click the start button below, you will be provided with:
- A Windows desktop A browser page with the scenarios and credentials (Desktop\instructions) Notes for this exam delivery:
The browser can be scaled lo Improve visibility and fit all the content on the screen.
- Copy and paste hot-keys will not work Use your mouse for copy and paste.
- The Notes and Feedback tabs for each scenario are to leave notes for yourself or feedback for
- Make sure you are performing tasks on the correct components.
- Changing security or network settings on the wrong component may result in a falling grade.
- Do not change credentials on an component unless you are instructed to.
- All necessary documentation is contained in the Desktop\Files\Documentation directory Task 1 An administrator has been asked to configure a storage for a distributed application which uses large data sets across multiple worker VMs.
The worker VMs must run on every node. Data resilience is provided at the application level and low cost per GB is a Key Requirement.
Configure the storage on the cluster to meet these requirements. Any new object created should include the phrase Distributed_App in the name.
정답:
설명:
See the Explanation for step by step solution
Explanation:
To configure the storage on the cluster for the distributed application, you can follow these steps:
Log in to Prism Element of cluster A using the credentials provided.
Go to Storage > Storage Pools and click on Create Storage Pool.
Enter a name for the new storage pool, such as Distributed_App_Storage_Pool, and select the disks to include in the pool. You can choose any combination of SSDs and HDDs, but for low cost per GB, you may prefer to use more HDDs than SSDs.
Click Save to create the storage pool.
Go to Storage > Containers and click on Create Container.
Enter a name for the new container, such as Distributed_App_Container, and select the storage pool that you just created, Distributed_App_Storage_Pool, as the source.
Under Advanced Settings, enable Erasure Coding and Compression to reduce the storage footprint of the dat a. You can also disable Replication Factor since data resilience is provided at the application level. These settings will help you achieve low cost per GB for the container.
Click Save to create the container.
Go to Storage > Datastores and click on Create Datastore.
Enter a name for the new datastore, such as Distributed_App_Datastore, and select NFS as the datastore type. Select the container that you just created, Distributed_App_Container, as the source.
Click Save to create the datastore.
The datastore will be automatically mounted on all nodes in the cluster. You can verify this by going to Storage > Datastores and clicking on Distributed_App_Datastore. You should see all nodes listed under Hosts.
You can now create or migrate your worker VMs to this datastore and run them on any node in the cluster. The datastore will provide low cost per GB and high performance for your distributed application.
질문 # 15
......
Itexamdump의Nutanix인증 NCM-MCI시험덤프 공부가이드는 시장에서 가장 최신버전이자 최고의 품질을 지닌 시험공부자료입니다.IT업계에 종사중이라면 IT자격증취득을 승진이나 연봉협상의 수단으로 간주하고 자격증취득을 공을 들여야 합니다.회사다니면서 공부까지 하려면 몸이 힘들어 스트레스가 많이 쌓인다는것을 헤아려주는Itexamdump가 IT인증자격증에 도전하는데 성공하도록Nutanix인증 NCM-MCI시험대비덤프를 제공해드립니다.
NCM-MCI유효한 덤프공부: https://www.itexamdump.com/NCM-MCI.html
2026 Itexamdump 최신 NCM-MCI PDF 버전 시험 문제집과 NCM-MCI 시험 문제 및 답변 무료 공유: https://drive.google.com/open?id=1DzXPr-BLtNAz7AnuyHFllMg7_YibAW0l