2026 Latest PremiumVCEDump DP-100 PDF Dumps and DP-100 Exam Engine Free Share: https://drive.google.com/open?id=1NmurDpE5cgnm63ApBODnGlu9iyVWphC7
With the high employment pressure, more and more people want to ease the employment tension and get a better job. The best way for them to solve the problem is to get the DP-100 certification. Because the certification is the main symbol of their working ability, if they can own the DP-100 certification, they will gain a competitive advantage when they are looking for a job. An increasing number of people have become aware of that it is very important for us to gain the DP-100 Exam Questions in a short time. And our DP-100 exam questions can help you get the dreamng certification.
| Section | Objectives |
|---|---|
| Train machine learning models | - Train models using Azure Machine Learning - Tune hyperparameters and evaluate models |
| Design and prepare a machine learning solution | - Manage compute and data assets - Plan and configure Azure Machine Learning workspace - Select appropriate Azure services for machine learning workloads |
| Deploy and consume models | - Deploy models to endpoints - Monitor deployed models and endpoints |
| Optimize and manage models | - Improve model performance - Track experiments and manage model lifecycle |
| Explore and analyze data | - Ingest and prepare data for modeling - Perform exploratory data analysis |
>> Training DP-100 Solutions <<
you may like our DP-100 exam materials since they contain so many different versions. You can use it anytime, anywhere. Of course, you don't have to worry about the difference in content. The contents of all versions of DP-100 learning engine are the same. You only need to consider which version of the DP-100 study questions is more suitable for you, and then buy it. Of course, we don't mind if you buy more than one version, as long as you think it is suitable.
NEW QUESTION # 395
Hotspot Question
You are designing a machine learning solution.
You have the following requirements:
- Use a training script to train a machine learning model.
- Build a machine learning proof of concept without the use of code or
script.
You need to select a development tool for each requirement.
Which development tool should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.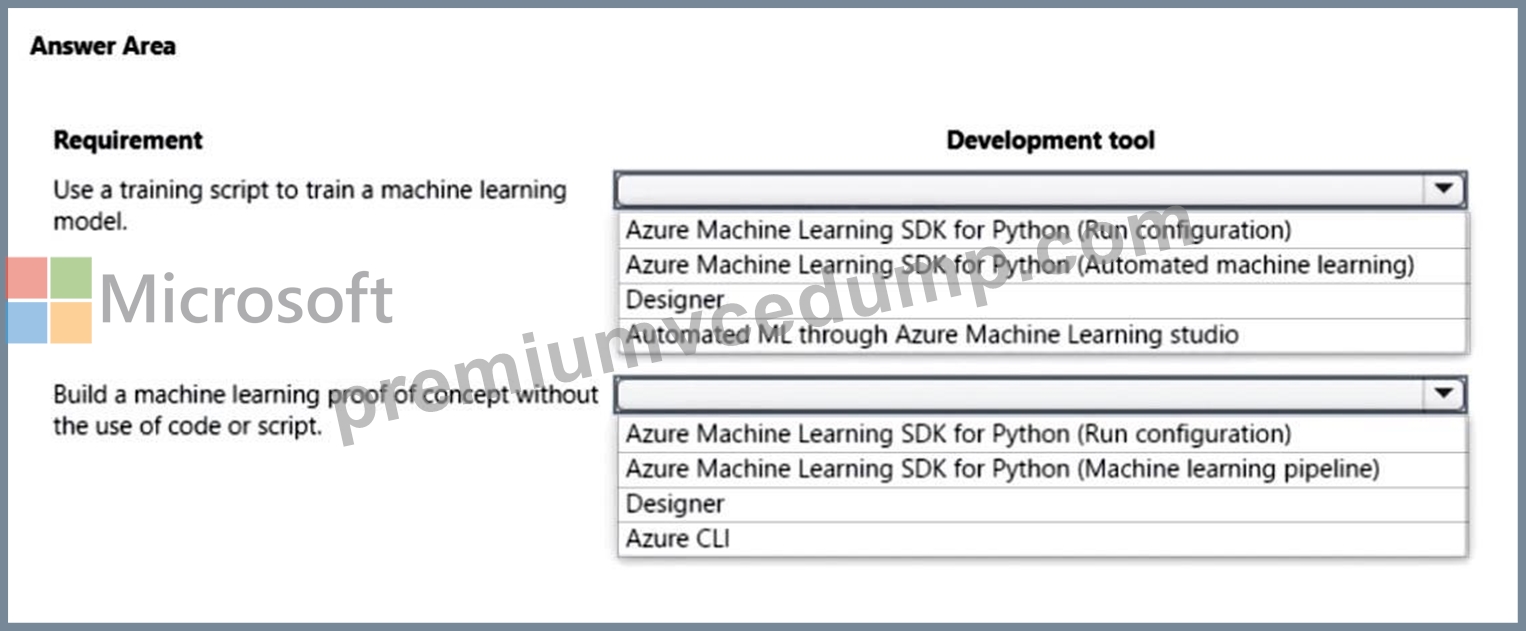
Answer:
Explanation: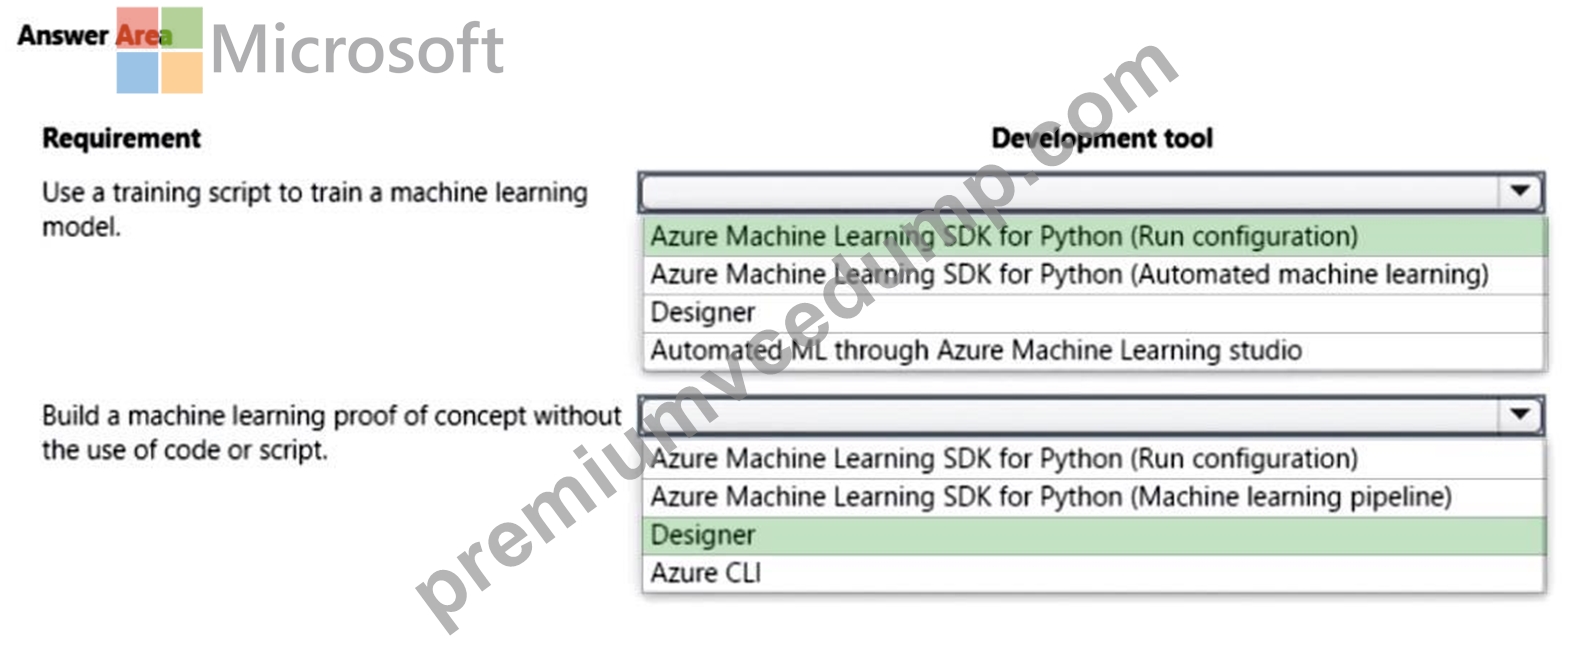
NEW QUESTION # 396
Hotspot Question
You are evaluating a Python NumPy array that contains six data points defined as follows:
data = [10, 20, 30, 40, 50, 60]
You must generate the following output by using the k-fold algorithm implantation in the Python Scikit-learn machine learning library:
train: [10 40 50 60], test: [20 30]
train: [20 30 40 60], test: [10 50]
train: [10 20 30 50], test: [40 60]
You need to implement a cross-validation to generate the output.
How should you complete the code segment? To answer, select the appropriate code segment in the dialog box in the answer area.
NOTE: Each correct selection is worth one point.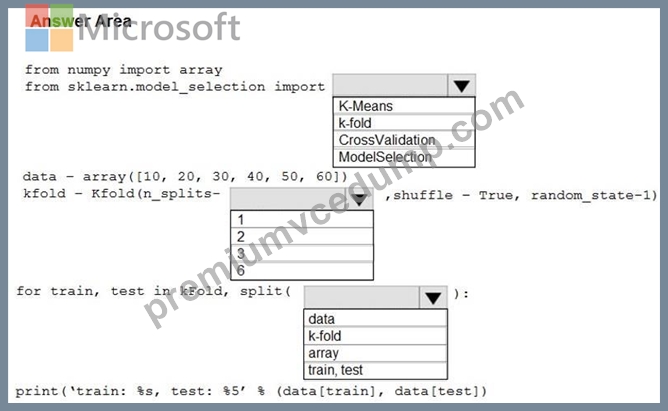
Answer:
Explanation: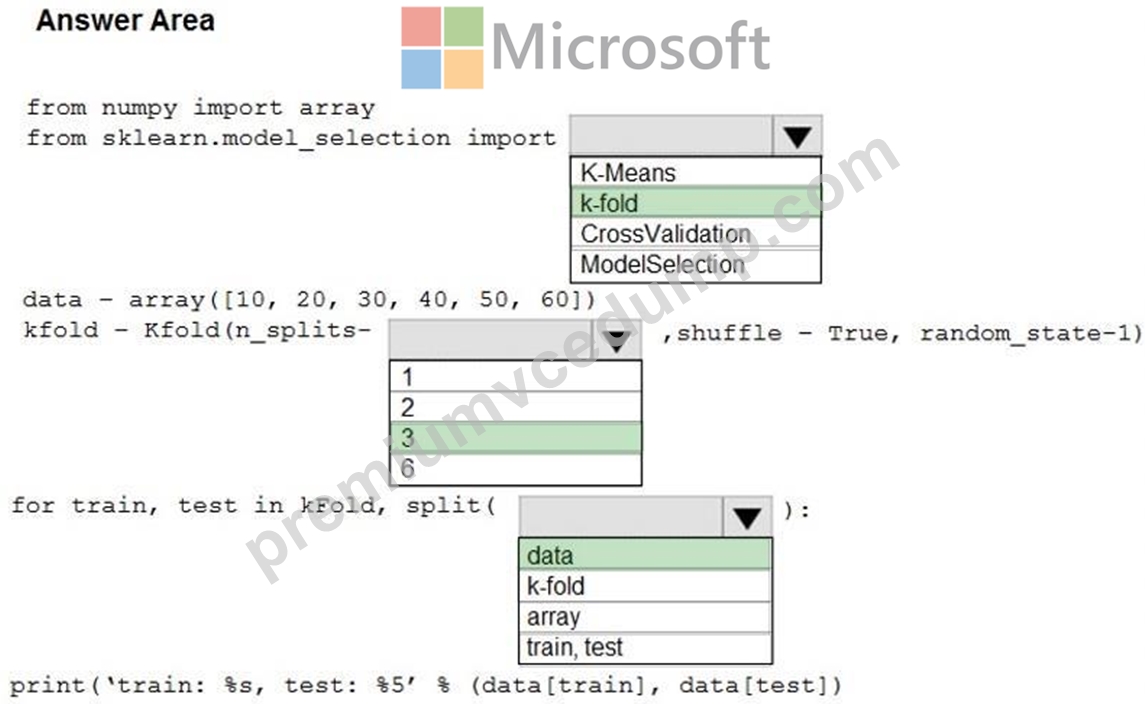
Explanation:
Box 1: k-fold
Box 2: 3
K-Folds cross-validator provides train/test indices to split data in train/test sets. Split dataset into k consecutive folds (without shuffling by default). The parameter n_splits ( int, default=3) is the number of folds. Must be at least 2.
Box 3: data
Example: Example:
>>>
>>> from sklearn.model_selection import KFold
>>> X = np.array([[1, 2], [3, 4], [1, 2], [3, 4]])
>>> y = np.array([1, 2, 3, 4])
>>> kf = KFold(n_splits=2)
>>> kf.get_n_splits(X)
>>> print(kf)
KFold(n_splits=2, random_state=None, shuffle=False)
>>> for train_index, test_index in kf.split(X):
... print("TRAIN:", train_index, "TEST:", test_index)
... X_train, X_test = X[train_index], X[test_index]
... y_train, y_test = y[train_index], y[test_index]
TRAIN: [2 3] TEST: [0 1]
TRAIN: [0 1] TEST: [2 3]
References:
https://scikit-learn.org/stable/modules/generated/sklearn.model_selection.KFold.html
NEW QUESTION # 397
You need to define an evaluation strategy for the crowd sentiment models.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.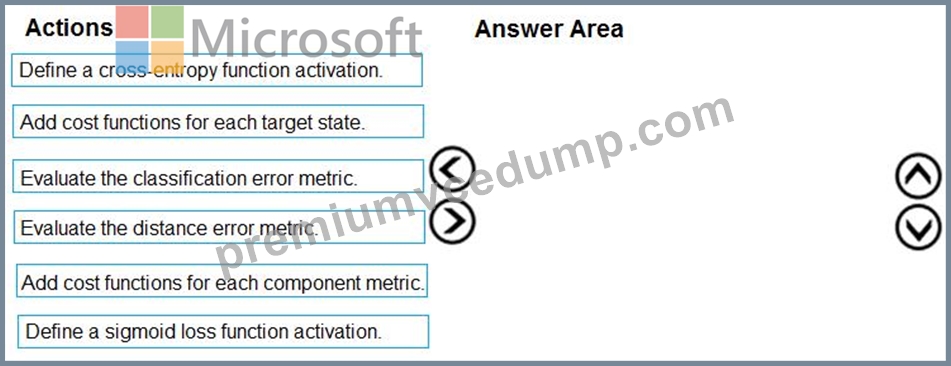
Answer:
Explanation: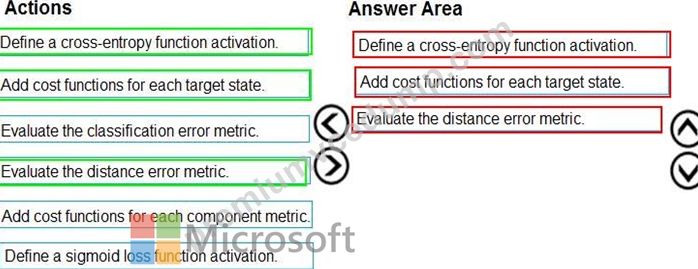
Explanation:
Step 1: Define a cross-entropy function activation
When using a neural network to perform classification and prediction, it is usually better to use cross-entropy error than classification error, and somewhat better to use cross-entropy error than mean squared error to evaluate the quality of the neural network.
Step 2: Add cost functions for each target state.
Step 3: Evaluated the distance error metric.
References:
https://www.analyticsvidhya.com/blog/2018/04/fundamentals-deep-learning-regularization-techniques/
NEW QUESTION # 398
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You create a model to forecast weather conditions based on historical data.
You need to create a pipeline that runs a processing script to load data from a datastore and pass the processed data to a machine learning model training script.
Solution: Run the following code: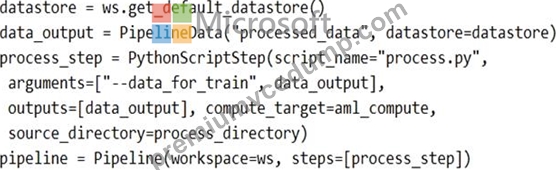
Does the solution meet the goal?
Answer: A
Explanation:
train_step is missing.
Reference:
https://docs.microsoft.com/en-us/python/api/azureml-pipeline-core/azureml.pipeline.core.pipelinedata?view=azure-ml-py
NEW QUESTION # 399
You use Azure Machine Learning Studio to build a machine learning experiment.
You need to divide data into two distinct datasets.
Which module should you use?
Answer: C
Explanation:
Explanation
The Group Data into Bins module supports multiple options for binning data. You can customize how the bin edges are set and how values are apportioned into the bins.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/group-data-into-bins
NEW QUESTION # 400
......
The Microsoft DP-100 exam questions on the platform have been gathered by subject matter experts to ensure that they accurately reflect the format and difficulty level of the actual Microsoft DP-100 exam. This makes these Designing and Implementing a Data Science Solution on Azure PDF Questions ideal for individuals looking to pass the Microsoft DP-100 Exam on their first try. You can evaluate the product with a free DP-100 demo.
DP-100 Reliable Exam Cost: https://www.premiumvcedump.com/Microsoft/valid-DP-100-premium-vce-exam-dumps.html
DOWNLOAD the newest PremiumVCEDump DP-100 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1NmurDpE5cgnm63ApBODnGlu9iyVWphC7