Databricks-Certified-Data-Engineer-Professional Exam Simulator Online, Valid Databricks-Certified-Data-Engineer-Professional Practice Questions

TestPassKing's experts have simplified the complex concepts and have added examples, simulations and graphs to explain whatever could be difficult for you to understand. Therefore even the average exam candidates can grasp all study questions without any difficulty. Additionally, the Databricks-Certified-Data-Engineer-Professional Exam takers can benefit themselves by using our testing engine and get numerous real exam like practice questions and answers. They will help them revising the entire syllabus within no time.
| Section | Weight | Objectives |
|---|
| Topic 1: Monitoring and Troubleshooting | 16% | - Performance Optimization
- Troubleshooting
- Monitoring
|
| Topic 2: Data Modeling and Storage | 20% | - Data Modeling
- File Formats
- Storage Optimization
|
| Topic 3: Data Quality and Governance | 12% | - Data Quality
- Data Lineage
- Governance
|
| Topic 4: Data Processing | 28% | - Structured Streaming
- Data Transformation
- Spark SQL
- ETL Pipelines
|
| Topic 5: Databricks Lakehouse Platform | 24% | - Delta Lake
- Data Management
- Unity Catalog
- Lakehouse Architecture
|
>> Databricks-Certified-Data-Engineer-Professional Exam Simulator Online <<
Valid Databricks-Certified-Data-Engineer-Professional Practice Questions | Exam Databricks-Certified-Data-Engineer-Professional Blueprint
The objective of the TestPassKing is to give you quick access to Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) actual questions. Offering Databricks Databricks-Certified-Data-Engineer-Professional updated dumps is the only factor behind the dominance of TestPassKing in the market. Our customers will see our Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) questions in the final certification test. We have a devoted team who puts in a lot of effort to keep the Databricks-Certified-Data-Engineer-Professional questions updated.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q137-Q142):
NEW QUESTION # 137
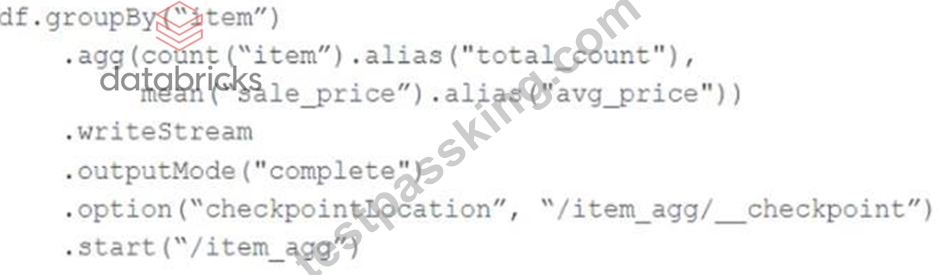
A data team's Structured Streaming job is configured to calculate running aggregates for item sales to update a downstream marketing dashboard. The marketing team has introduced a new field to track the number of times this promotion code is used for each item. A junior data engineer suggests updating the existing query as follows: Note that proposed changes are in bold.
Original query:
Proposed query:
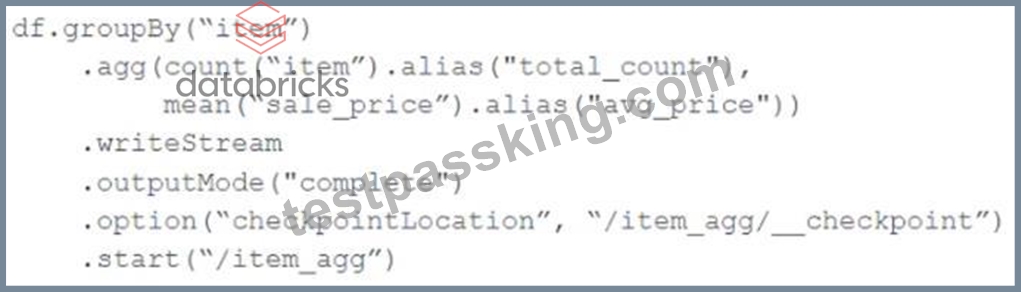
Which step must also be completed to put the proposed query into production?
- A. Register the data in the "/item_agg" directory to the Hive metastore
- B. Run REFRESH TABLE delta, /item_agg'
- C. Specify a new checkpointlocation
- D. Remove .option (mergeSchema', true') from the streaming write
- E. Increase the shuffle partitions to account for additional aggregates
Answer: C
Explanation:
When introducing a new aggregation or a change in the logic of a Structured Streaming query, it is generally necessary to specify a new checkpoint location. This is because the checkpoint directory contains metadata about the offsets and the state of the aggregations of a streaming query. If the logic of the query changes, such as including a new aggregation field, the state information saved in the current checkpoint would not be compatible with the new logic, potentially leading to incorrect results or failures. Therefore, to accommodate the new field and ensure the streaming job has the correct starting point and state information for aggregations, a new checkpoint location should be specified.
NEW QUESTION # 138
A platform engineer is creating catalogs and schemas for the development team to use.
The engineer has created an initial catalog, catalog_A, and initial schema, schema_A. The engineer has also granted USE CATALOG, USE SCHEMA, and CREATE TABLE to the development team so that the engineer can begin populating the schema with new tables.
Despite being owner of the catalog and schema, the engineer noticed that they do not have access to the underlying tables in Schema_A.
What explains the engineer's lack of access to the underlying tables?
- A. Users granted with USE CATALOG can modify the owner's permissions to downstream tables.
- B. The platform engineer needs to execute a REFRESH statement as the table permissions did not automatically update for owners.
- C. Permissions explicitly given by the table creator are the only way the Platform Engineer could access the underlying tables in their schema.
- D. The owner of the schema does not automatically have permission to tables within the schema, but can grant them to themselves at any point.
Answer: D
Explanation:
In Databricks, owning a catalog or schema does not automatically grant access to the tables within it. Table-level permissions are separate, so even the schema or catalog owner must be explicitly granted privileges on individual tables or use the ability to grant themselves access.
NEW QUESTION # 139
An organization processes customer data from web and mobile applications. Data includes names, emails, phone numbers, and location history. Data arrives both as batch files (from SFTP daily) and streaming JSON events (from Kafka in real-time).
To comply with data privacy policies, the following requirements must be met:
- Personally Identifiable Information (PII) such as email, phone
number, and IP address must be masked or anonymized before storage.
- Both batch and streaming pipelines must apply consistent PII
handling.
- Masking logic must be auditable and reproducible.
- The masked data must remain usable for downstream analytics.
How should the data engineer design a compliant data pipeline on Databricks that supports both batch and streaming modes, applies data masking to PII, and maintains traceability for audits?
- A. Ingest both batch and streaming data using Lakeflow Declarative Pipelines, and apply masking via Unity Catalog column masks at read time to avoid modifying the data during ingestion.
- B. Use Lakeflow Declarative Pipelines for batch and streaming ingestion, define a PII masking function, and apply it during Bronze ingestion before writing to Delta Lake.
- C. Allow PII to be stored unmasked in Bronze for lineage tracking, then apply masking logic in Gold tables used for reporting.
- D. Load batch data with notebooks and ingest streaming data with SQL Warehouses; use Unity Catalog column masks on Silver tables to redact fields after storage.
Answer: B
Explanation:
Databricks recommends applying data masking or anonymization before persisting PII to ensure compliance with privacy regulations such as GDPR and HIPAA. In a Lakeflow Declarative Pipeline, developers can define custom Python or SQL-based masking functions to standardize PII handling across both batch and streaming inputs.
This approach ensures that data entering the Delta Lake is already anonymized, guaranteeing consistent and auditable behavior. By applying masking during ingestion (in the Bronze layer), audit trails are preserved through pipeline event logs.
While Unity Catalog column masks (option C) can enforce dynamic masking at query time, they do not prevent PII storage. Thus, option D aligns with the best practice of securing PII before storage, while still supporting reproducibility and analytics usability.
NEW QUESTION # 140
A data engineer is configuring a Lakeflow Declarative Pipeline to process CDC (Change Data Capture) data from a source. The source events sometimes arrive out of order, and multiple updates may occur with the same update_timestamp but with different update_sequence_id.
What should the data engineer do to ensure events are sequenced correctly?
- A. Use dropDuplicates() to remove out-of-order and duplicate records in LDP.
- B. Use SEQUENCE BY STRUCT(event_timestamp, update_sequence_id) in AUTO CDC APIs.
- C. Set track_history_column_list to [event_timestamp, event_id] in AUTO CDC APIs.
- D. Use a window function to sort update_sequence_id within the same partition, i.e., update_timestamp in the LDP pipeline.
Answer: B
Explanation:
When handling CDC data, sequencing is critical because updates may arrive out of order or multiple changes may occur for the same record at the same timestamp. Databricks' AUTO CDC APIs provide built-in constructs to handle ordering logic.
The correct mechanism is to use the SEQUENCE BY clause in the CDC configuration.
Specifically, when both update_timestamp and update_sequence_id exist, the recommended approach is:
SEQUENCE BY STRUCT(event_timestamp, update_sequence_id)
This ensures that within the same record key, the engine applies updates in the exact sequence they occurred, resolving conflicts where multiple updates share the same timestamp but differ in sequence ID.
Option A (track_history_column_list) is used for historical tracking and auditing changes, not for sequencing logic. It ensures lineage but does not enforce correct event order.
Option B (dropDuplicates()) only removes exact duplicates; it cannot guarantee sequencing correctness when multiple updates exist.
Option C is correct: SEQUENCE BY STRUCT(event_timestamp, update_sequence_id) explicitly enforces ordering, as recommended by the CDC pipeline guidelines.
Option D (window function) would be a manual approach in Spark Structured Streaming, but Lakeflow Declarative Pipelines already provide native CDC sequencing support, making this unnecessary.
Thus, the best practice per Databricks CDC documentation is to use Option C with SEQUENCE BY STRUCT.
NEW QUESTION # 141
The data architect has mandated that all tables in the Lakehouse should be configured as external Delta Lake tables.
Which approach will ensure that this requirement is met?
- A. Whenever a database is being created, make sure that the location keyword is used Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
- B. When configuring an external data warehouse for all table storage. leverage Databricks for all ELT.
- C. Whenever a table is being created, make sure that the location keyword is used.
- D. When the workspace is being configured, make sure that external cloud object storage has been mounted.
- E. When tables are created, make sure that the external keyword is used in the create table statement.
Answer: C
Explanation:
This is the correct answer because it ensures that this requirement is met. The requirement is that all tables in the Lakehouse should be configured as external Delta Lake tables. An external table is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An external table can be created by using the location keyword to specify the path to an existing directory in a cloud storage system, such as DBFS or S3. By creating external tables, the data engineering team can avoid losing data if they drop or overwrite the table, as well as leverage existing data without moving or copying it.
NEW QUESTION # 142
......
Probably you’ve never imagined that preparing for your upcoming Databricks-Certified-Data-Engineer-Professional exam could be so easy. The good news is that Databricks-Certified-Data-Engineer-Professional test dumps have made it so! The brilliant Databricks-Certified-Data-Engineer-Professional test dumps are the product created by those professionals who have extensive experience of designing exam study materials. These professionals have deep exposure of the test candidates’ problems and requirements hence our Databricks-Certified-Data-Engineer-Professional Test Dumps cater to your need beyond your expectations.
Valid Databricks-Certified-Data-Engineer-Professional Practice Questions: https://www.testpassking.com/Databricks-Certified-Data-Engineer-Professional-exam-testking-pass.html
- Marvelous Databricks Databricks-Certified-Data-Engineer-Professional Exam Simulator Online 🕵 Search for { Databricks-Certified-Data-Engineer-Professional } and easily obtain a free download on ✔ www.examcollectionpass.com ️✔️ 🚁Databricks-Certified-Data-Engineer-Professional Valid Exam Testking
- Valid Databricks-Certified-Data-Engineer-Professional Exam Vce 🔑 Exam Databricks-Certified-Data-Engineer-Professional Simulations 👯 Reliable Databricks-Certified-Data-Engineer-Professional Test Voucher 📴 Search on ⇛ www.pdfvce.com ⇚ for ⏩ Databricks-Certified-Data-Engineer-Professional ⏪ to obtain exam materials for free download 😊Learning Databricks-Certified-Data-Engineer-Professional Mode
- 100% Pass 2026 Authoritative Databricks Databricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam Exam Simulator Online 🐗 Open ( www.troytecdumps.com ) enter 「 Databricks-Certified-Data-Engineer-Professional 」 and obtain a free download 🚈Valid Test Databricks-Certified-Data-Engineer-Professional Fee
- 100% Pass 2026 Databricks Databricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam –Professional Exam Simulator Online 📸 Immediately open ☀ www.pdfvce.com ️☀️ and search for “ Databricks-Certified-Data-Engineer-Professional ” to obtain a free download 🧪Learning Databricks-Certified-Data-Engineer-Professional Mode
- Guide Databricks-Certified-Data-Engineer-Professional Torrent 🐙 Accurate Databricks-Certified-Data-Engineer-Professional Prep Material 🌒 Reliable Databricks-Certified-Data-Engineer-Professional Test Online 🍦 Easily obtain ✔ Databricks-Certified-Data-Engineer-Professional ️✔️ for free download through ⇛ www.exam4labs.com ⇚ 🌸Valid Test Databricks-Certified-Data-Engineer-Professional Fee
- Databricks-Certified-Data-Engineer-Professional Exam Simulation: Databricks Certified Data Engineer Professional Exam - Databricks-Certified-Data-Engineer-Professional Training Materials 🛃 Search on “ www.pdfvce.com ” for [ Databricks-Certified-Data-Engineer-Professional ] to obtain exam materials for free download 🎡Learning Databricks-Certified-Data-Engineer-Professional Mode
- Reliable Databricks-Certified-Data-Engineer-Professional Test Camp ↗ Databricks-Certified-Data-Engineer-Professional Training Materials 🎈 Exam Databricks-Certified-Data-Engineer-Professional Simulations 🌮 Simply search for ☀ Databricks-Certified-Data-Engineer-Professional ️☀️ for free download on 「 www.practicevce.com 」 🏪Reliable Databricks-Certified-Data-Engineer-Professional Test Voucher
- Valid Test Databricks-Certified-Data-Engineer-Professional Fee ♿ Accurate Databricks-Certified-Data-Engineer-Professional Prep Material 🍮 Guide Databricks-Certified-Data-Engineer-Professional Torrent 😄 Open website ➠ www.pdfvce.com 🠰 and search for ✔ Databricks-Certified-Data-Engineer-Professional ️✔️ for free download 🚊Valid Test Databricks-Certified-Data-Engineer-Professional Fee
- Reliable Databricks-Certified-Data-Engineer-Professional Test Online 🕑 Databricks-Certified-Data-Engineer-Professional Brain Exam 💢 Valid Databricks-Certified-Data-Engineer-Professional Exam Online 🎰 Immediately open 【 www.examcollectionpass.com 】 and search for ➽ Databricks-Certified-Data-Engineer-Professional 🢪 to obtain a free download 🐠Guide Databricks-Certified-Data-Engineer-Professional Torrent
- Databricks Databricks-Certified-Data-Engineer-Professional Exam Simulator Online - Realistic Valid Databricks Certified Data Engineer Professional Exam Practice Questions 100% Pass Quiz 🚬 Open ✔ www.pdfvce.com ️✔️ enter ➠ Databricks-Certified-Data-Engineer-Professional 🠰 and obtain a free download 🖼Databricks-Certified-Data-Engineer-Professional Training Materials
- 100% Pass 2026 Authoritative Databricks Databricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam Exam Simulator Online 💿 Open website ⏩ www.examdiscuss.com ⏪ and search for ▷ Databricks-Certified-Data-Engineer-Professional ◁ for free download 🚋Databricks-Certified-Data-Engineer-Professional Valid Dumps
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, p.me-page.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes