Certified-Data-Engineer-Professional Latest Braindumps Ebook | Certified-Data-Engineer-Professional Pdf Pass Leader

With the development of technology, our Certified-Data-Engineer-Professional training engine will be updated regularly. Actually, we never stop researching the new functions of the study materials. Normally, we will release our new version of the Certified-Data-Engineer-Professional exam simulation on our website once it passed the tests. Many details will be perfected in the new version of our Certified-Data-Engineer-Professional Study Materials not not on the content, but also on the displays. And we have been in this career for over ten years, our Certified-Data-Engineer-Professional learning guide is perfect.
| Section | Objectives |
|---|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Build append-only pipelines for batch and streaming data using Delta
- 2. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 3. Ingest data from message buses and cloud storage
|
| Cost & Performance Optimisation | - Query Performance
- 1. Identify inefficient joins and excessive data shuffling
- 2. Use Query Profile to identify performance bottlenecks
- Delta Optimization
- 1. Apply data skipping and file pruning techniques
- 2. Understand deletion vectors and liquid clustering
- 3. Use Change Data Feed to address streaming table limitations and improve latency
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
|
| Data Governance | - Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
- Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
|
| Data Sharing and Federation | - Delta Sharing
- 1. Configure Databricks-to-Databricks Sharing
- 2. Configure sharing with external platforms using the open sharing protocol
- 3. Share live Lakehouse data with external computing platforms
- Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
|
| Developing Code for Data Processing using Python and SQL | - Building and Testing ETL Pipelines
- 1. Use APPLY CHANGES APIs for change data capture
- 2. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 3. Develop unit and integration tests for data processing code
- 4. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 5. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 6. Compare streaming tables and materialized views
- 7. Configure environments, dependencies, memory, and retry behavior
- 8. Use control flow operators in pipeline components
- Using Python and Tools for Development
- 1. Manage and troubleshoot third-party library installations and dependencies
- 2. Develop User-Defined Functions using Pandas/Python UDFs
- 3. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
|
| Monitoring and Alerting | - Monitoring
- 1. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 2. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 3. Use Query Profiler and Spark UI to monitor workloads
- 4. Use system tables for resource, cost, audit, and workload monitoring
- Alerting
- 1. Use SQL Alerts for data quality monitoring
- 2. Configure Lakeflow Jobs notifications for job status and performance issues
|
| Data Modelling | - Scalable Data Models
- 1. Optimize data layout using Liquid Clustering
- 2. Design and implement scalable data models using Delta Lake
- 3. Understand Liquid Clustering versus partitioning and Z-Ordering
- Dimensional Modelling
- 1. Design dimensional models for analytical workloads
|
| Ensuring Data Security and Compliance | - Data Security
- 1. Use row filters and column masks for sensitive data
- 2. Apply anonymization and pseudonymization techniques
- 3. Use ACLs to secure workspace objects and enforce least privilege
- Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
|
| Data Transformation, Cleansing, and Quality | - Data Quality
- 1. Develop data quarantining processes for invalid data
- 2. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 2. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- 3. Analyze errors and remediate failed job runs
- Deploying CI/CD
- 1. Integrate Git-based CI/CD workflows using Databricks Git Folders
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
>> Certified-Data-Engineer-Professional Latest Braindumps Ebook <<
2026 Certified-Data-Engineer-Professional – 100% Free Latest Braindumps Ebook | the Best Certified-Data-Engineer-Professional Pdf Pass Leader
TorrentExam provides you not only with the best materials and also with excellent service. If you buy TorrentExam questions and answers, free update for one year is guaranteed. So, you can always have the latest test materials. You fail, after you use our Databricks Certified-Data-Engineer-Professional Dumps, 100% guarantee to FULL REFUND. With it, what do you worry about? TorrentExam has a lot of confidence in our dumps and you also faith in our TorrentExam. In order to success, don't miss TorrentExam. If you miss TorrentExam, you will miss a chance to embrace the success.
Databricks Certified Data Engineer Professional Sample Questions (Q53-Q58):
NEW QUESTION # 53
A Delta Lake table representing metadata about content posts from users has the following schema:
user_id LONG, post_text STRING, post_id STRING, longitude FLOAT,
latitude FLOAT, post_time TIMESTAMP, date DATE
This table is partitioned by the date column. A query is run with the following filter:
longitude < 20 & longitude > -20
Which statement describes how data will be filtered?
- A. Statistics in the Delta Log will be used to identify data files that might include records in the filtered range.
- B. No file skipping will occur because the optimizer does not know the relationship between the partition column and the longitude.
- C. The Delta Engine will scan the parquet file footers to identify each row that meets the filter criteria.
- D. Statistics in the Delta Log will be used to identify partitions that might Include files in the filtered range.
- E. The Delta Engine will use row-level statistics in the transaction log to identify the flies that meet the filter criteria.
Answer: A
Explanation:
This is the correct answer because it describes how data will be filtered when a query is run with the following filter: longitude < 20 & longitude > -20. The query is run on a Delta Lake table that has the following schema: user_id LONG, post_text STRING, post_id STRING, longitude FLOAT, latitude FLOAT, post_time TIMESTAMP, date DATE. This table is partitioned by the date column.
When a query is run on a partitioned Delta Lake table, Delta Lake uses statistics in the Delta Log to identify data files that might include records in the filtered range. The statistics include information such as min and max values for each column in each data file. By using these statistics, Delta Lake can skip reading data files that do not match the filter condition, which can improve query performance and reduce I/O costs.
NEW QUESTION # 54
A data engineer wants to refactor the following DLT code, which includes multiple table definitions with very similar code.
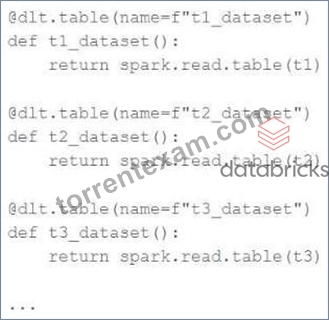
In an attempt to programmatically create these tables using a parameterized table definition, the data engineer writes the following code.
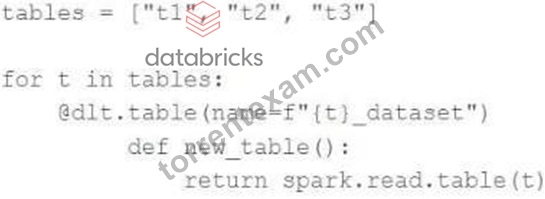
The pipeline runs an update with this refactored code, but generates a different DAG showing incorrect configuration values for these tables.
How can the data engineer fix this?
- A. Wrap the for loop inside another table definition, using generalized names and properties to replace with those from the inner table definition.
- B. Move the table definition into a separate function, and make calls to this function using different input parameters inside the for loop.
- C. Convert the list of configuration values to a dictionary of table settings, using table names as keys.
- D. Load the configuration values for these tables from a separate file, located at a path provided by a pipeline parameter.
Answer: B
Explanation:
In the provided refactored code, the for loop dynamically attempts to define multiple tables, but the use of a loop within the DLT (@dlt.table) decorator does not work properly because it results in a single function reference being overwritten for each iteration. This leads to an incorrect DAG because all the table definitions end up pointing to the last iteration of the loop.
NEW QUESTION # 55
A data engineer is attempting to execute the following PySpark code:
df = spark.read.table("sales")
result = df.groupBy("region").agg(sum("revenue"))
However, upon inspecting the execution plan and profiling the Spark job, they observe excessive data shuffling during the aggregation phase.
Which technique should be applied to reduce shuffling during the groupBy aggregation operation?
- A. Repartition by region before aggregation.
- B. Use coalesce() after the aggregation.
- C. Caching the DataFrame df.
- D. Use broadcast join.
Answer: A
Explanation:
Repartitioning the DataFrame by the grouping key ensures that records with the same region are colocated in the same partitions before the aggregation runs. This significantly reduces the amount of data shuffled during the groupBy operation, leading to more efficient execution.
NEW QUESTION # 56
The Databricks workspace administrator has configured interactive clusters for each of the data engineering groups. To control costs, clusters are set to terminate after 30 minutes of inactivity.
Each user should be able to execute workloads against their assigned clusters at any time of the day.
Assuming users have been added to a workspace but not granted any permissions, which of the following describes the minimal permissions a user would need to start and attach to an already configured cluster.
- A. Cluster creation allowed. "Can Attach To" privileges on the required cluster
- B. "Can Manage" privileges on the required cluster
- C. Cluster creation allowed. "Can Restart" privileges on the required cluster
- D. "Can Restart" privileges on the required cluster
- E. Workspace Admin privileges, cluster creation allowed. "Can Attach To" privileges on the required cluster
Answer: D
Explanation:
https://learn.microsoft.com/en-us/azure/databricks/security/auth-authz/access-control/cluster-acl
https://docs.databricks.com/en/security/auth-authz/access-control/cluster-acl.html
NEW QUESTION # 57
A team of data engineer are adding tables to a DLT pipeline that contain repetitive expectations for many of the same data quality checks.
One member of the team suggests reusing these data quality rules across all tables defined for this pipeline.
What approach would allow them to do this?
- A. Maintain data quality rules in a Delta table outside of this pipeline's target schema, providing the schema name as a pipeline parameter.
- B. Use global Python variables to make expectations visible across DLT notebooks included in the same pipeline.
- C. Maintain data quality rules in a separate Databricks notebook that each DLT notebook of file.
- D. Add data quality constraints to tables in this pipeline using an external job with access to pipeline configuration files.
Answer: A
Explanation:
Maintaining data quality rules in a centralized Delta table allows for the reuse of these rules across multiple DLT (Delta Live Tables) pipelines. By storing these rules outside the pipeline's target schema and referencing the schema name as a pipeline parameter, the team can apply the same set of data quality checks to different tables within the pipeline. This approach ensures consistency in data quality validations and reduces redundancy in code by not having to replicate the same rules in each DLT notebook or file.
NEW QUESTION # 58
......
With every Databricks Certified-Data-Engineer-Professional practice test attempt, you will see yourself improve gradually, and on Databricks Certified-Data-Engineer-Professional exam day, you will be able to finish the Databricks Certified Data Engineer Professional Certified-Data-Engineer-Professional exam as far as possible and space enough time to do an entire check for careless mistakes. Download the full version of TorrentExam Certified-Data-Engineer-Professional PDF Questions and practice tests and start your professional journey. We ensure you can pass the Databricks Certified Data Engineer Professional Certified-Data-Engineer-Professional exam on the first attempt.
Certified-Data-Engineer-Professional Pdf Pass Leader: https://www.torrentexam.com/Certified-Data-Engineer-Professional-exam-latest-torrent.html
- Pass Guaranteed 2026 Latest Databricks Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Latest Braindumps Ebook 🎿 Download ✔ Certified-Data-Engineer-Professional ️✔️ for free by simply entering { www.verifieddumps.com } website 😥Certified-Data-Engineer-Professional Brain Dumps
- Certified-Data-Engineer-Professional Valid Test Guide 🗽 Certified-Data-Engineer-Professional Test Answers 🕧 Valid Certified-Data-Engineer-Professional Guide Files 🌃 The page for free download of 《 Certified-Data-Engineer-Professional 》 on { www.pdfvce.com } will open immediately ⚪Certified-Data-Engineer-Professional Exam Reference
- Training Certified-Data-Engineer-Professional Material 🦐 Certified-Data-Engineer-Professional Valid Cram Materials 🧖 Certified-Data-Engineer-Professional Reliable Exam Dumps 🏡 Search for ▛ Certified-Data-Engineer-Professional ▟ and obtain a free download on ➽ www.prepawayexam.com 🢪 🐳Certified-Data-Engineer-Professional Valid Dumps Pdf
- Valid Certified-Data-Engineer-Professional Guide Files 💑 Certified-Data-Engineer-Professional Brain Dump Free 👐 Certified-Data-Engineer-Professional Dump 🙎 Search for ➤ Certified-Data-Engineer-Professional ⮘ and easily obtain a free download on ▶ www.pdfvce.com ◀ 😘Certified-Data-Engineer-Professional Dump
- Certified-Data-Engineer-Professional Dump 🍛 Real Certified-Data-Engineer-Professional Question 🕝 Certified-Data-Engineer-Professional Online Version 🕶 Search for ▶ Certified-Data-Engineer-Professional ◀ and download it for free on ➽ www.examcollectionpass.com 🢪 website 💛Test Certified-Data-Engineer-Professional King
- Pass Guaranteed 2026 Latest Databricks Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Latest Braindumps Ebook 🚲 Enter ▶ www.pdfvce.com ◀ and search for ⏩ Certified-Data-Engineer-Professional ⏪ to download for free 🌮Certified-Data-Engineer-Professional Valid Cram Materials
- Pass Guaranteed Quiz Accurate Databricks - Certified-Data-Engineer-Professional - Databricks Certified Data Engineer Professional Latest Braindumps Ebook 📲 Easily obtain free download of “ Certified-Data-Engineer-Professional ” by searching on ➡ www.examcollectionpass.com ️⬅️ ⚫Certified-Data-Engineer-Professional Exam Vce
- Professional Certified-Data-Engineer-Professional Latest Braindumps Ebook, Ensure to pass the Certified-Data-Engineer-Professional Exam ✔ Open [ www.pdfvce.com ] and search for ✔ Certified-Data-Engineer-Professional ️✔️ to download exam materials for free 🟫Certified-Data-Engineer-Professional Valid Dumps Pdf
- Real Certified-Data-Engineer-Professional Question 🤶 Certified-Data-Engineer-Professional Exam Answers 💭 Certified-Data-Engineer-Professional Valid Braindumps Book 🤯 Search on “ www.prep4sures.top ” for 《 Certified-Data-Engineer-Professional 》 to obtain exam materials for free download 🔨Certified-Data-Engineer-Professional Brain Dump Free
- Free PDF Quiz 2026 Databricks Certified-Data-Engineer-Professional: High Pass-Rate Databricks Certified Data Engineer Professional Latest Braindumps Ebook ⛵ Easily obtain { Certified-Data-Engineer-Professional } for free download through ➡ www.pdfvce.com ️⬅️ 🏨Certified-Data-Engineer-Professional Verified Answers
- Certified-Data-Engineer-Professional Online Version 🤠 Certified-Data-Engineer-Professional Valid Cram Materials 🔷 Certified-Data-Engineer-Professional Verified Answers 🤭 Search for ⇛ Certified-Data-Engineer-Professional ⇚ on 《 www.pdfdumps.com 》 immediately to obtain a free download 🦟Real Certified-Data-Engineer-Professional Question
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes