Databricks-Certified-Data-Engineer-Associate Reliable Test Voucher, Databricks-Certified-Data-Engineer-Associate Latest Exam Pass4sure

What's more, part of that Prep4cram Databricks-Certified-Data-Engineer-Associate dumps now are free: https://drive.google.com/open?id=1yk75PGKhHwyIAyXJaE8BkVO835SkXHhU
As far as the Databricks Certified Data Engineer Associate Exam (Databricks-Certified-Data-Engineer-Associate) exam questions are concerned, these Databricks Databricks-Certified-Data-Engineer-Associate exam questions are designed and verified by the experience and qualified Databricks-Certified-Data-Engineer-Associate exam trainers. They work together and strive hard to maintain the top standard of Databricks-Certified-Data-Engineer-Associate Exam Practice questions all the time. So you rest assured that with the Prep4cram Databricks Databricks-Certified-Data-Engineer-Associate exam questions you will ace your Databricks-Certified-Data-Engineer-Associate exam preparation and feel confident to solve all questions in the final Databricks Databricks-Certified-Data-Engineer-Associate exam.
Earning the Databricks-Certified-Data-Engineer-Associate Certification can help individuals advance their careers in the field of data engineering. Databricks Certified Data Engineer Associate Exam certification is recognized globally and can demonstrate to employers that the individual has the skills and knowledge required to work with Databricks effectively. It can also lead to better job opportunities and higher salaries.
>> Databricks-Certified-Data-Engineer-Associate Reliable Test Voucher <<
Free PDF Databricks - Databricks-Certified-Data-Engineer-Associate - Authoritative Databricks Certified Data Engineer Associate Exam Reliable Test Voucher
Databricks-Certified-Data-Engineer-Associate study guide is highly targeted. Good question materials software can really bring a lot of convenience to your learning and improve a lot of efficiency. How to find such good learning material software? People often take a roundabout route many times. If you want to use this Databricks-Certified-Data-Engineer-Associate Practice Exam to improve learning efficiency, our Databricks-Certified-Data-Engineer-Associate exam questions will be your best choice and you will be satisfied to find its good quality and high efficiency.
Databricks Certified Data Engineer Associate exam consists of 60 multiple-choice questions that must be completed within 90 minutes. Candidates are required to score at least 70% to pass the exam. Databricks-Certified-Data-Engineer-Associate Exam is administered online through the GAQM testing platform, which allows candidates to take the exam from anywhere in the world.
Databricks Certified Data Engineer Associate Exam Sample Questions (Q252-Q257):
NEW QUESTION # 252
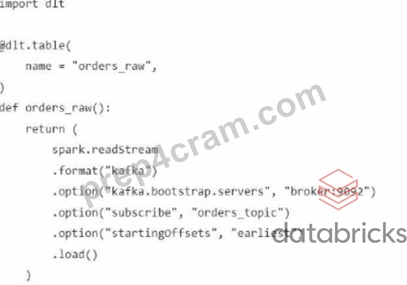
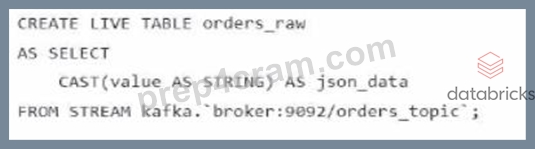
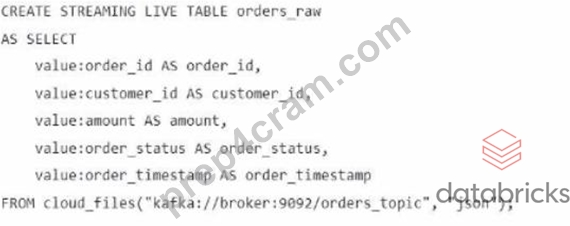
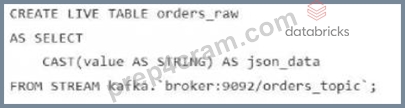
A data engineer streams customer orders into a Kafka topic (orders_topic) and is currently writing the ingestion script of a DLT pipeline. The data engineer needs to ingest the data from Kafka brokers to DLT using Databricks What is the correct code for ingesting the data?
Answer: A
NEW QUESTION # 253
A new data engineering team team. has been assigned to an ELT project. The new data engineering team will need full privileges on the database customers to fully manage the project.
Which of the following commands can be used to grant full permissions on the database to the new data engineering team?
- A. GRANT SELECT CREATE MODIFY USAGE PRIVILEGES ON DATABASE customers TO team;
- B. GRANT USAGE ON DATABASE customers TO team;
- C. GRANT ALL PRIVILEGES ON DATABASE team TO customers;
- D. GRANT SELECT PRIVILEGES ON DATABASE customers TO teams;
- E. GRANT ALL PRIVILEGES ON DATABASE customers TO team;
Answer: E
Explanation:
To grant full permissions on a database to a user, group, or service principal, the GRANT ALL PRIVILEGES ON DATABASE command can be used. This command grants all the applicable privileges on the database, such as CREATE, SELECT, MODIFY, and USAGE. The other options are either incorrect or incomplete, as they do not grant all the privileges or specify the wrong database or principal. Reference:
GRANT
Privileges
NEW QUESTION # 254
Which of the following describes a scenario in which a data engineer will want to use a single-node cluster?
- A. When they are manually running reports with a large amount of data
- B. When they are working with SQL within Databricks SQL
- C. When they are running automated reports to be refreshed as quickly as possible
- D. When they are concerned about the ability to automatically scale with larger data
- E. When they are working interactively with a small amount of data
Answer: E
Explanation:
The scenario in which a data engineer will want to use a single-node cluster is when they are working interactively with a small amount of data. A single-node cluster is a cluster consisting of an Apache Spark driver and no Spark workers1. A single-node cluster supports Spark jobs and all Spark data sources, including Delta Lake1. A single-node cluster is helpful for single-node machine learning workloads that use Spark to load and save data, and for lightweight exploratory data analysis1. A single-node cluster can run Spark locally, spawn one executor thread per logical core in the cluster, and save all log output in the driver log1. A single-node cluster can be created by selecting the Single Node button when configuring a cluster1.
The other options are not suitable for using a single-node cluster. When running automated reports to be refreshed as quickly as possible, a data engineer will want to use a multi-node cluster that can scale up and down automatically based on the workload demand2. When working with SQL within Databricks SQL, a data engineer will want to use a SQL Endpoint that can execute SQL queries on a serverless pool or an existing cluster3. When concerned about the ability to automatically scale with larger data, a data engineer will want to use a multi-node cluster that can leverage the Databricks Lakehouse Platform and the Delta Engine to handle large-scale data processing efficiently and reliably4. When manually running reports with a large amount of data, a data engineer will want to use a multi-node cluster that can distribute the computation across multiple workers and leverage the Spark UI to monitor the performance and troubleshoot the issues.
References:
* 1: Single Node clusters | Databricks on AWS
* 2: Autoscaling | Databricks on AWS
* 3: SQL Endpoints | Databricks on AWS
* 4: Databricks Lakehouse Platform | Databricks on AWS
* : [Spark UI | Databricks on AWS]
NEW QUESTION # 255
A data engineering team must version-control notebooks, review changes through pull requests, and deploy the same code to dev, staging, and production workspaces.
Which Databricks capability supports this workflow?
- A. Enabling notebook revision history and restoring snapshots as needed
- B. Exporting notebooks as DBC archives and emailing them between workspaces
- C. Storing notebook source files in DBFS /FileStore and copying them manually
- D. Databricks Git folders (Repos) integrated with a remote Git provider
Answer: D
Explanation:
Databricks Git folders provide native integration with providers such as GitHub, GitLab, Azure DevOps, and Bitbucket, supporting branching, commits, pulls, and pull-request workflows.
Combined with Databricks Asset Bundles or job Git sources, the same repository can be deployed across environments.
NEW QUESTION # 256
A data engineer uploads a CSV file using the Create or modify a table using file upload option in Databricks. To avoid incorrect schema inference, the engineer disables Automatically detect column types before creating a Unity Catalog-managed table.
What is the outcome?
- A. All columns are created with the STRING data type.
- B. Numeric columns are inferred as numeric types, while all other columns use STRING.
- C. Table creation fails because column types are not specified.
- D. Previously inferred column types are preserved.
Answer: A
Explanation:
When Automatically detect column types is disabled during file upload, Databricks does not infer specialized data types from the CSV values. Instead, every uploaded column is created as STRING. This behavior prevents values that resemble numbers, dates, or Boolean values from being automatically assigned potentially incorrect types. The engineer can subsequently transform or cast individual columns into the required target types as part of a controlled Silver-layer process. Option B is incorrect because partial numeric inference does not occur when automatic detection is disabled. Option C is incorrect because Databricks can create the table without manually supplied types by using STRING for every column. Option D is also incorrect because disabling detection determines the schema behavior for the table creation operation. Therefore, option A accurately describes the result.
NEW QUESTION # 257
......
Databricks-Certified-Data-Engineer-Associate Latest Exam Pass4sure: https://www.prep4cram.com/Databricks-Certified-Data-Engineer-Associate_exam-questions.html
- Valid Databricks-Certified-Data-Engineer-Associate Reliable Test Voucher - Authoritative Databricks-Certified-Data-Engineer-Associate Exam Tool Guarantee Purchasing Safety 💳 Open ✔ www.prepawayexam.com ️✔️ enter “ Databricks-Certified-Data-Engineer-Associate ” and obtain a free download 🤏Databricks-Certified-Data-Engineer-Associate Simulated Test
- HOT Databricks-Certified-Data-Engineer-Associate Reliable Test Voucher - The Best Databricks Databricks-Certified-Data-Engineer-Associate Latest Exam Pass4sure: Databricks Certified Data Engineer Associate Exam 🥱 Easily obtain 《 Databricks-Certified-Data-Engineer-Associate 》 for free download through [ www.pdfvce.com ] 🈵Databricks-Certified-Data-Engineer-Associate Valid Braindumps Ebook
- Databricks-Certified-Data-Engineer-Associate Question Explanations 🍒 Databricks-Certified-Data-Engineer-Associate Free Pdf Guide 🎠 Databricks-Certified-Data-Engineer-Associate Exam Simulations ⌛ 《 www.prep4away.com 》 is best website to obtain ⇛ Databricks-Certified-Data-Engineer-Associate ⇚ for free download 🙂Databricks-Certified-Data-Engineer-Associate Latest Braindumps Ppt
- Latest Databricks-Certified-Data-Engineer-Associate Exam Forum 🏇 Databricks-Certified-Data-Engineer-Associate Valid Braindumps Ebook 🔕 Databricks-Certified-Data-Engineer-Associate Certification Dumps 🦘 Search for ➤ Databricks-Certified-Data-Engineer-Associate ⮘ and download exam materials for free through ▷ www.pdfvce.com ◁ 🙈Databricks-Certified-Data-Engineer-Associate Latest Exam Test
- Databricks-Certified-Data-Engineer-Associate Latest Braindumps Ppt ↩ Valid Test Databricks-Certified-Data-Engineer-Associate Braindumps 🤤 Latest Databricks-Certified-Data-Engineer-Associate Exam Forum 🌛 Download ✔ Databricks-Certified-Data-Engineer-Associate ️✔️ for free by simply searching on 【 www.prepawaypdf.com 】 😛Databricks-Certified-Data-Engineer-Associate Latest Braindumps Ppt
- Buy Databricks-Certified-Data-Engineer-Associate Exam Dumps Now and Get Amazing Offers 🌀 Easily obtain ⇛ Databricks-Certified-Data-Engineer-Associate ⇚ for free download through 【 www.pdfvce.com 】 🚊Databricks-Certified-Data-Engineer-Associate Free Pdf Guide
- Databricks-Certified-Data-Engineer-Associate Free Pdf Guide 🕛 Valid Dumps Databricks-Certified-Data-Engineer-Associate Sheet 🎯 Exam Databricks-Certified-Data-Engineer-Associate Tutorials 😼 Search for ➥ Databricks-Certified-Data-Engineer-Associate 🡄 and download it for free on ▛ www.examcollectionpass.com ▟ website 👦Databricks-Certified-Data-Engineer-Associate Exam Simulations
- Reliable Databricks-Certified-Data-Engineer-Associate Reliable Test Voucher - Pass Databricks-Certified-Data-Engineer-Associate Exam 🍅 Download ⏩ Databricks-Certified-Data-Engineer-Associate ⏪ for free by simply searching on 【 www.pdfvce.com 】 🌉Databricks-Certified-Data-Engineer-Associate Certification Dumps
- Databricks-Certified-Data-Engineer-Associate Latest Test Simulator 🍵 Databricks-Certified-Data-Engineer-Associate Valid Braindumps Ebook 🐰 Databricks-Certified-Data-Engineer-Associate Latest Braindumps Ppt 🔊 Search for ( Databricks-Certified-Data-Engineer-Associate ) and download it for free on ⮆ www.prepawaypdf.com ⮄ website ↙Valid Dumps Databricks-Certified-Data-Engineer-Associate Sheet
- HOT Databricks-Certified-Data-Engineer-Associate Reliable Test Voucher - The Best Databricks Databricks-Certified-Data-Engineer-Associate Latest Exam Pass4sure: Databricks Certified Data Engineer Associate Exam 🕊 Download ➥ Databricks-Certified-Data-Engineer-Associate 🡄 for free by simply entering ⮆ www.pdfvce.com ⮄ website 🧞Databricks-Certified-Data-Engineer-Associate Latest Test Simulator
- Valid Databricks-Certified-Data-Engineer-Associate Reliable Test Voucher - Authoritative Databricks-Certified-Data-Engineer-Associate Exam Tool Guarantee Purchasing Safety 🌊 Go to website ✔ www.verifieddumps.com ️✔️ open and search for 【 Databricks-Certified-Data-Engineer-Associate 】 to download for free 🔭Databricks-Certified-Data-Engineer-Associate Free Pdf Guide
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, justpaste.me, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, buyerseller.xyz, Disposable vapes
What's more, part of that Prep4cram Databricks-Certified-Data-Engineer-Associate dumps now are free: https://drive.google.com/open?id=1yk75PGKhHwyIAyXJaE8BkVO835SkXHhU