Quiz Databricks - Reliable Databricks-Certified-Data-Engineer-Professional Official Study Guide
Many candidates find the Databricks Databricks-Certified-Data-Engineer-Professional exam preparation difficult. They often buy expensive study courses to start their Databricks Databricks-Certified-Data-Engineer-Professional certification exam preparation. However, spending a huge amount on such resources is difficult for many Databricks Databricks-Certified-Data-Engineer-Professional Exam applicants.
| Section | Weight | Objectives |
|---|
| Topic 1: Databricks Lakehouse Platform | 24% | - Delta Lake
- Data Management
- Lakehouse Architecture
- Unity Catalog
|
| Topic 2: Data Quality and Governance | 12% | - Data Quality
- Data Lineage
- Governance
|
| Topic 3: Data Processing | 28% | - Spark SQL
- ETL Pipelines
- Structured Streaming
- Data Transformation
|
| Topic 4: Monitoring and Troubleshooting | 16% | - Monitoring
- Performance Optimization
- Troubleshooting
|
| Topic 5: Data Modeling and Storage | 20% | - Data Modeling
- Storage Optimization
- File Formats
|
>> Databricks-Certified-Data-Engineer-Professional Official Study Guide <<
Reliable Databricks-Certified-Data-Engineer-Professional Exam Voucher | Databricks-Certified-Data-Engineer-Professional Valid Test Test
We are stable and reliable Databricks-Certified-Data-Engineer-Professional exam questions providers for persons who need them for their Databricks-Certified-Data-Engineer-Professional exam. We have been staying and growing in the market for a long time, and we will be here all the time, because our excellent quality and high pass rate of Databricks-Certified-Data-Engineer-Professional exam questons can meet your requirement. As for the high-effective Databricks-Certified-Data-Engineer-Professional training guide, there are thousands of candidates are willing to choose our Databricks-Certified-Data-Engineer-Professional study question, why don’t you have a try for our Databricks-Certified-Data-Engineer-Professional study materials, we will never let you down!
Databricks Certified Data Engineer Professional Exam Sample Questions (Q160-Q165):
NEW QUESTION # 160
A Delta table of weather records is partitioned by date and has the below schema:
date DATE, device_id INT, temp FLOAT, latitude FLOAT, longitude FLOAT
To find all the records from within the Arctic Circle, you execute a query with the below filter:
latitude > 66.3
Which statement describes how the Delta engine identifies which files to load?
- A. The Parquet file footers are scanned for min and max statistics for the latitude column
- B. All records are cached to attached storage and then the filter is applied
- C. All records are cached to an operational database and then the filter is applied
- D. The Hive metastore is scanned for min and max statistics for the latitude column
- E. The Delta log is scanned for min and max statistics for the latitude column
Answer: E
Explanation:
This is the correct answer because Delta Lake uses a transaction log to store metadata about each table, including min and max statistics for each column in each data file. The Delta engine can use this information to quickly identify which files to load based on a filter condition, without scanning the entire table or the file footers. This is called data skipping and it can improve query performance significantly. Verified Reference: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; [Databricks Documentation], under "Optimizations - Data Skipping" section.
In the Transaction log, Delta Lake captures statistics for each data file of the table. These statistics indicate per file:
- Total number of records
- Minimum value in each column of the first 32 columns of the table
- Maximum value in each column of the first 32 columns of the table
- Null value counts for in each column of the first 32 columns of the table When a query with a selective filter is executed against the table, the query optimizer uses these statistics to generate the query result. it leverages them to identify data files that may contain records matching the conditional filter.
For the SELECT query in the question, The transaction log is scanned for min and max statistics for the price column.
NEW QUESTION # 161
A data engineer wants to ingest a large collection of image files (JPEG and PNG) from cloud object storage into a Unity Catalog-managed table for analysis and visualization. Which two configurations and practices are recommended to incrementally ingest these images into the table? (Choose two.)
- A. Use Auto Loader and set cloudFiles.format to "IMAGE".
- B. Use the pathGlobFilter option to select only image files (e.g., "*.jpg,*.png").
- C. Move files to a volume and read with SQL editor.
- D. Use Auto Loader and set cloudFiles.format to "TEXT".
- E. Use Auto Loader and set cloudFiles.format to "BINARYFILE".
Answer: B,E
Explanation:
Databricks Auto Loader supports ingestion of binary file formats using the cloudFiles.format option. For ingesting JPEG or PNG image files, the correct setting is "BINARYFILE", which loads the raw binary content and file metadata into a DataFrame. Additionally, when processing files from object storage, it is best practice to apply pathGlobFilter to limit ingestion to specific file types and reduce unnecessary scanning of non-image files. Options like "IMAGE" or "TEXT" are invalid, and using volumes with SQL editors does not provide incremental ingestion. Therefore, combining Auto Loader with cloudFiles.format="BINARYFILE" and pathGlobFilter ensures scalable, incremental ingestion of image data into Unity Catalog tables.
NEW QUESTION # 162
A junior data engineer is working to implement logic for a Lakehouse table named silver_device_recordings. The source data contains 100 unique fields in a highly nested JSON structure.
The silver_device_recordings table will be used downstream to power several production monitoring dashboards and a production model. At present, 45 of the 100 fields are being used in at least one of these applications.
The data engineer is trying to determine the best approach for dealing with schema declaration given the highly-nested structure of the data and the numerous fields.
Which of the following accurately presents information about Delta Lake and Databricks that may impact their decision-making process?
- A. Because Databricks will infer schema using types that allow all observed data to be processed, setting types manually provides greater assurance of data quality enforcement.
- B. Human labor in writing code is the largest cost associated with data engineering workloads; as such, automating table declaration logic should be a priority in all migration workloads.
- C. Because Delta Lake uses Parquet for data storage, data types can be easily evolved by just modifying file footer information in place.
- D. Schema inference and evolution on .Databricks ensure that inferred types will always accurately match the data types used by downstream systems.
- E. The Tungsten encoding used by Databricks is optimized for storing string data; newly-added native support for querying JSON strings means that string types are always most efficient.
Answer: A
Explanation:
This is the correct answer because it accurately presents information about Delta Lake and Databricks that may impact the decision-making process of a junior data engineer who is trying to determine the best approach for dealing with schema declaration given the highly-nested structure of the data and the numerous fields. Delta Lake and Databricks support schema inference and evolution, which means that they can automatically infer the schema of a table from the source data and allow adding new columns or changing column types without affecting existing queries or pipelines. However, schema inference and evolution may not always be desirable or reliable, especially when dealing with complex or nested data structures or when enforcing data quality and consistency across different systems. Therefore, setting types manually can provide greater assurance of data quality enforcement and avoid potential errors or conflicts due to incompatible or unexpected data types.
NEW QUESTION # 163
A data engineer is using Lakeflow Declarative Pipeline to propagate row deletions from a source bronze table (user_bronze) to a target silver table (user_silver). The engineer wants deletions in user_bronze to automatically delete corresponding rows in user_silver during pipeline execution.
Which configuration ensures deletions in the bronze table are propagated to the silver table?
- A. Configure VACUUM on user_bronze to delete files, then rebuild user_silver from scratch.
- B. Enable CDF on user_silver, read its transaction log, and use MERGE to sync deletions.
- C. Enable Change Data Feed (CDF) on user_bronze, read its CDF stream, and use apply_changes() with apply_as_deletes=True for user_silver.
- D. Use apply_changes without CDF and filter rows where _soft_deleted is true.
Answer: C
Explanation:
According to Databricks documentation, Change Data Feed (CDF) allows pipelines to read incremental data changes, including inserts, updates, and deletes, from a Delta table. When deletions occur in the source table, reading the CDF stream ensures downstream consumers receive the deletion records. The Lakeflow Declarative Pipelines API provides the apply_changes() function (or auto-CDC pipelines) with the apply_as_deletes parameter to correctly apply those deletions to the target table. This enables automatic synchronization between bronze and silver layers. Options A and D either require manual handling or complete rebuilds, and C incorrectly applies CDF to the target rather than the source. Therefore, enabling CDF on the bronze table and using apply_as_deletes=True is the correct, Databricks-supported configuration.
NEW QUESTION # 164
A data engineer wants to refactor the following DLT code, which includes multiple table definitions with very similar code.
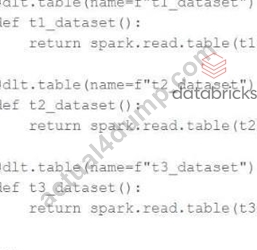
In an attempt to programmatically create these tables using a parameterized table definition, the data engineer writes the following code.
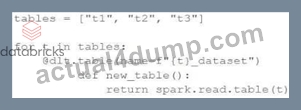
The pipeline runs an update with this refactored code, but generates a different DAG showing incorrect configuration values for these tables.
How can the data engineer fix this?
- A. Load the configuration values for these tables from a separate file, located at a path provided by a pipeline parameter.
- B. Convert the list of configuration values to a dictionary of table settings, using table names as keys.
- C. Move the table definition into a separate function, and make calls to this function using different input parameters inside the for loop.
- D. Wrap the for loop inside another table definition, using generalized names and properties to replace with those from the inner table definition.
Answer: C
Explanation:
In the provided refactored code, the for loop dynamically attempts to define multiple tables, but the use of a loop within the DLT (@dlt.table) decorator does not work properly because it results in a single function reference being overwritten for each iteration. This leads to an incorrect DAG because all the table definitions end up pointing to the last iteration of the loop.
NEW QUESTION # 165
......
In the 21st century, with the development of science and technology, the Internet is not only a entertainment platform, but also a world-class electronic library. On Actual4dump site you can find IT information knowledge treasure that belongs to you. Choosing Actual4dump's Databricks-Certified-Data-Engineer-Professional Exam Training materials is to choose to embrace the bright future. When you buy our Databricks-Certified-Data-Engineer-Professional exam training materials, we will ensure that you pass Databricks-Certified-Data-Engineer-Professional test.
Reliable Databricks-Certified-Data-Engineer-Professional Exam Voucher: https://www.actual4dump.com/Databricks/Databricks-Certified-Data-Engineer-Professional-actualtests-dumps.html
- Certified Databricks-Certified-Data-Engineer-Professional Questions 👰 Braindump Databricks-Certified-Data-Engineer-Professional Pdf 🥙 Databricks-Certified-Data-Engineer-Professional Practice Braindumps 🦁 Download ➠ Databricks-Certified-Data-Engineer-Professional 🠰 for free by simply entering ⇛ www.exam4labs.com ⇚ website 🖊Braindump Databricks-Certified-Data-Engineer-Professional Pdf
- Databricks Databricks-Certified-Data-Engineer-Professional Exam Dumps - Pass Exam in One Go 🎲 ☀ www.pdfvce.com ️☀️ is best website to obtain 《 Databricks-Certified-Data-Engineer-Professional 》 for free download 🎰Practice Databricks-Certified-Data-Engineer-Professional Mock
- 100% Pass 2026 Databricks Databricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam Fantastic Official Study Guide 🥈 Go to website “ www.vceengine.com ” open and search for 「 Databricks-Certified-Data-Engineer-Professional 」 to download for free 📀Databricks-Certified-Data-Engineer-Professional Latest Exam Labs
- 2026 Databricks-Certified-Data-Engineer-Professional Official Study Guide | Reliable Reliable Databricks-Certified-Data-Engineer-Professional Exam Voucher: Databricks Certified Data Engineer Professional Exam 100% Pass 😋 Open ▶ www.pdfvce.com ◀ and search for ▶ Databricks-Certified-Data-Engineer-Professional ◀ to download exam materials for free 🏉Databricks-Certified-Data-Engineer-Professional Instant Discount
- 100% Pass 2026 Databricks Databricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam Fantastic Official Study Guide 🧶 Easily obtain ➽ Databricks-Certified-Data-Engineer-Professional 🢪 for free download through ➤ www.dumpsmaterials.com ⮘ 🥮Certified Databricks-Certified-Data-Engineer-Professional Questions
- Exam Vce Databricks-Certified-Data-Engineer-Professional Free 🕛 Reliable Databricks-Certified-Data-Engineer-Professional Exam Pattern 👽 Pass Leader Databricks-Certified-Data-Engineer-Professional Dumps 🕶 Go to website ➽ www.pdfvce.com 🢪 open and search for ⇛ Databricks-Certified-Data-Engineer-Professional ⇚ to download for free 🤪New Databricks-Certified-Data-Engineer-Professional Dumps Sheet
- Databricks Databricks-Certified-Data-Engineer-Professional Exam Dumps - Pass Exam in One Go 🔗 Search for ✔ Databricks-Certified-Data-Engineer-Professional ️✔️ and download exam materials for free through 《 www.exam4labs.com 》 🔍Test Databricks-Certified-Data-Engineer-Professional Questions Answers
- Updated Databricks-Certified-Data-Engineer-Professional Official Study Guide | Amazing Pass Rate For Databricks-Certified-Data-Engineer-Professional Exam | Marvelous Databricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam 📗 Easily obtain ▶ Databricks-Certified-Data-Engineer-Professional ◀ for free download through [ www.pdfvce.com ] 🕥Databricks-Certified-Data-Engineer-Professional Certification Cost
- www.troytecdumps.com Databricks Databricks-Certified-Data-Engineer-Professional PDF Dumps and Practice Test Software 📸 Search for ➥ Databricks-Certified-Data-Engineer-Professional 🡄 and easily obtain a free download on “ www.troytecdumps.com ” 😟Valid Databricks-Certified-Data-Engineer-Professional Exam Pattern
- Exam Vce Databricks-Certified-Data-Engineer-Professional Free ⭐ Practice Databricks-Certified-Data-Engineer-Professional Mock 🥅 Valid Databricks-Certified-Data-Engineer-Professional Exam Pattern 🪀 Search on { www.pdfvce.com } for ➡ Databricks-Certified-Data-Engineer-Professional ️⬅️ to obtain exam materials for free download 🥅New Databricks-Certified-Data-Engineer-Professional Dumps Sheet
- Pass Leader Databricks-Certified-Data-Engineer-Professional Dumps 👩 Databricks-Certified-Data-Engineer-Professional Practice Braindumps 👤 Certified Databricks-Certified-Data-Engineer-Professional Questions ➰ Enter 「 www.dumpsmaterials.com 」 and search for ⇛ Databricks-Certified-Data-Engineer-Professional ⇚ to download for free ✌Databricks-Certified-Data-Engineer-Professional Exam Dumps Free
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.intensedebate.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes