More about CCAR-P Exams Dumps: If you want to know more about our test preparations materials, you should explore the related CCAR-P exam Page. You may go over our CCAR-P brain dumps product formats and choose the one that suits you best. You can also avail of the free demo so that you will have an idea how convenient and effective our CCAR-P exam dumps are for CCAR-P Certification. Rather we offer a wide selection of braindumps for all other exams under the CCAR-P certification. This ensures that you will cover more topics thus increasing your chances of success. With the multiple learning modes in CCAR-P practice exam software, you will surely find your pace and find your way to success.
| Section | Objectives |
|---|---|
| Topic 1: Solution Design | - Model, architecture, context, and deployment strategy selection - Claude platform and solution architecture |
| Topic 2: Stakeholder Engagement and Solution Lifecycle | - Stakeholder discovery and architectural trade-off communication - Solution lifecycle, handoff, adoption, and operational enablement |
| Topic 3: Enterprise Integration and Production | - Enterprise integration architecture and production readiness - Cost, latency, reliability, and operational design |
| Topic 4: Governance, Safety, and Risk | - Safety controls and fail-closed system design - Security, compliance, risk management, and governance |
| Topic 5: Evaluation and Optimization | - Model and architecture optimization - Evaluation design and acceptance criteria |
>> Reliable CCAR-P Test Preparation <<
The CCAR-P web-based practice exam requires no installation so you can start your preparation instantly right after you purchase. With thousands of satisfied customers around the globe, questions of the Claude Certified Architect - Professional (CCAR-P) exam dumps are real so you can pass the Anthropic CCAR-P certification on the very first attempt. Hence, it reduces your chances of failure and you can save money and time as well.
NEW QUESTION # 46
You are a solution architect evaluating candidate use cases for a Claude-based program.
For each scenario, select Yes if Claude is appropriate as the primary solution at the architectural level.
Otherwise, select No.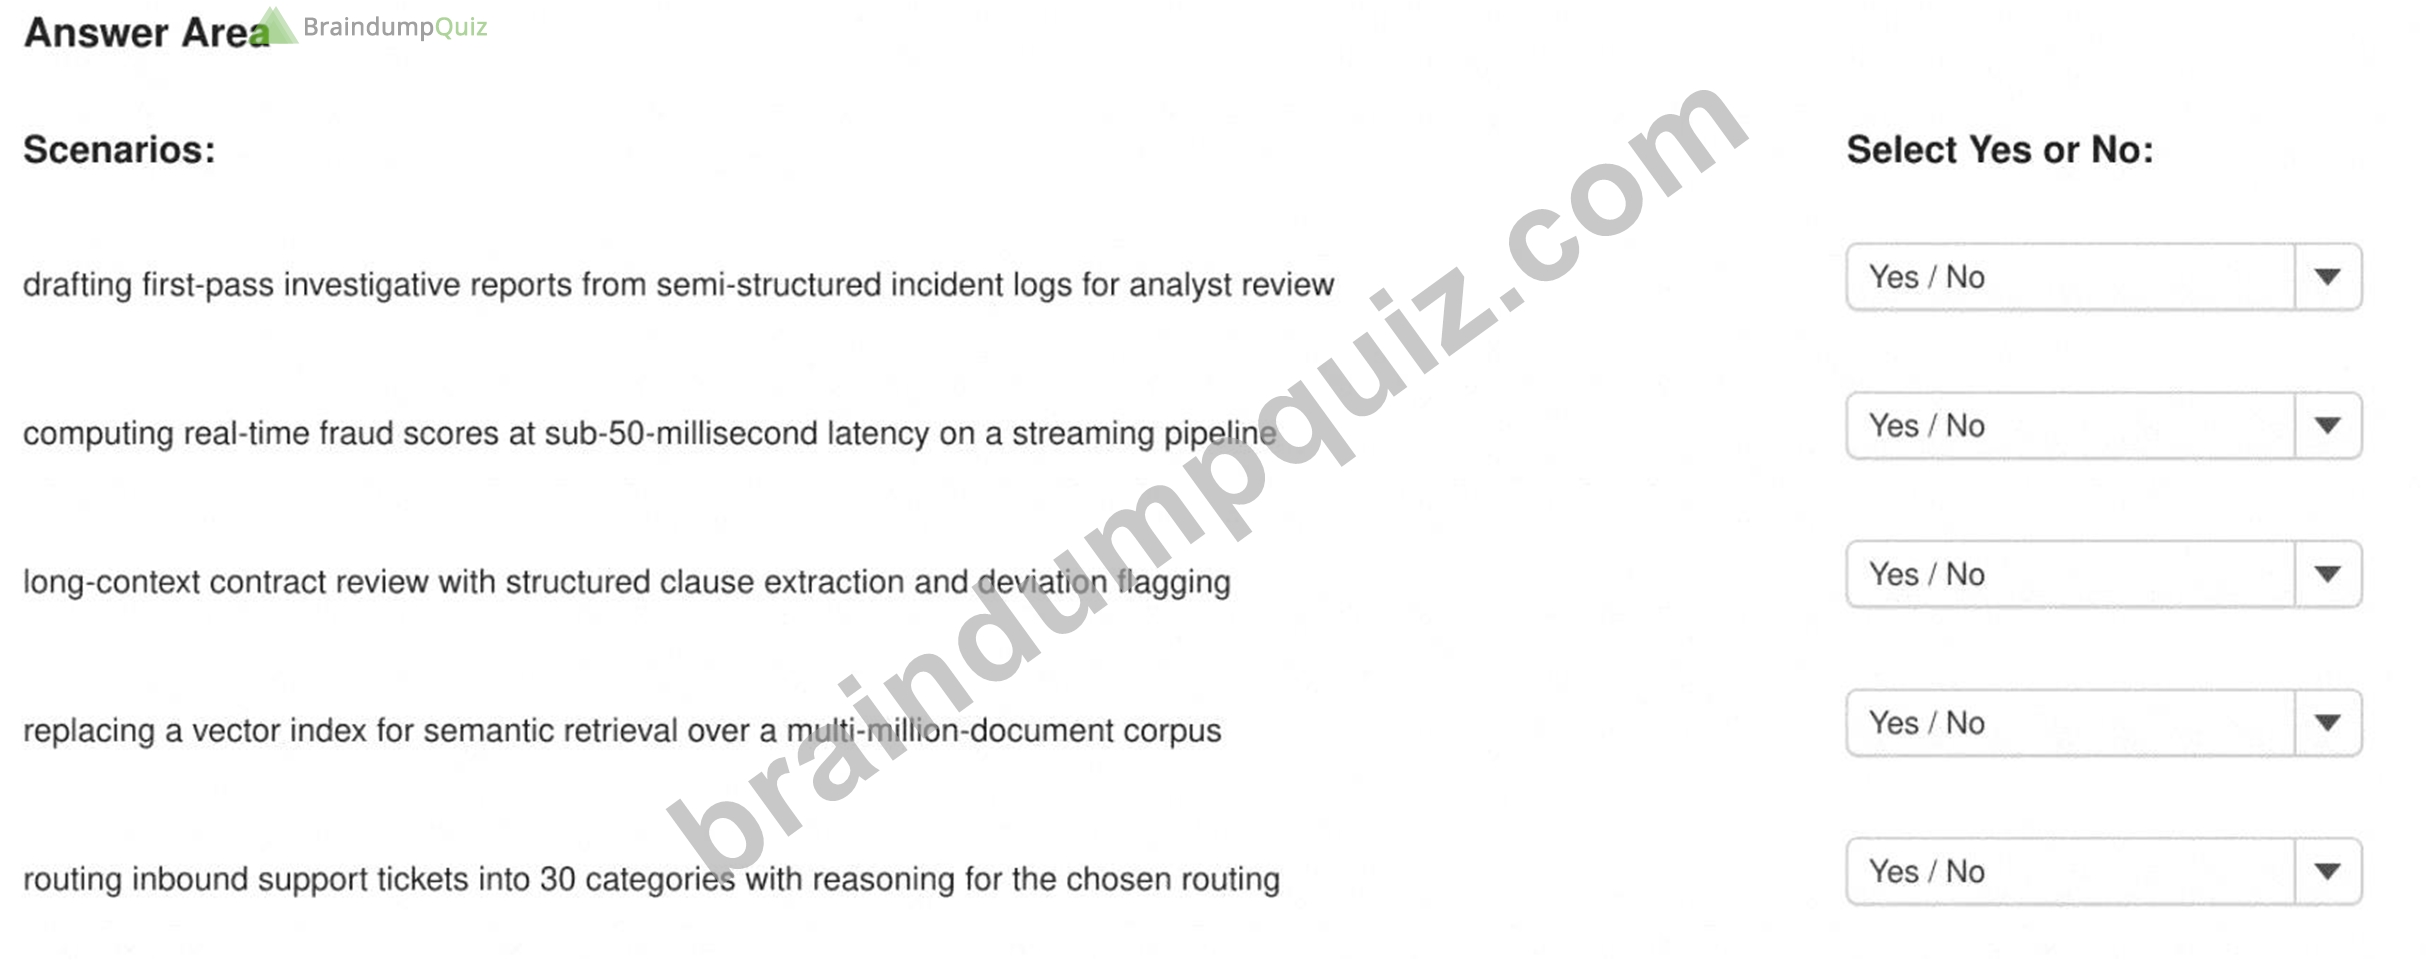
Answer:
Explanation: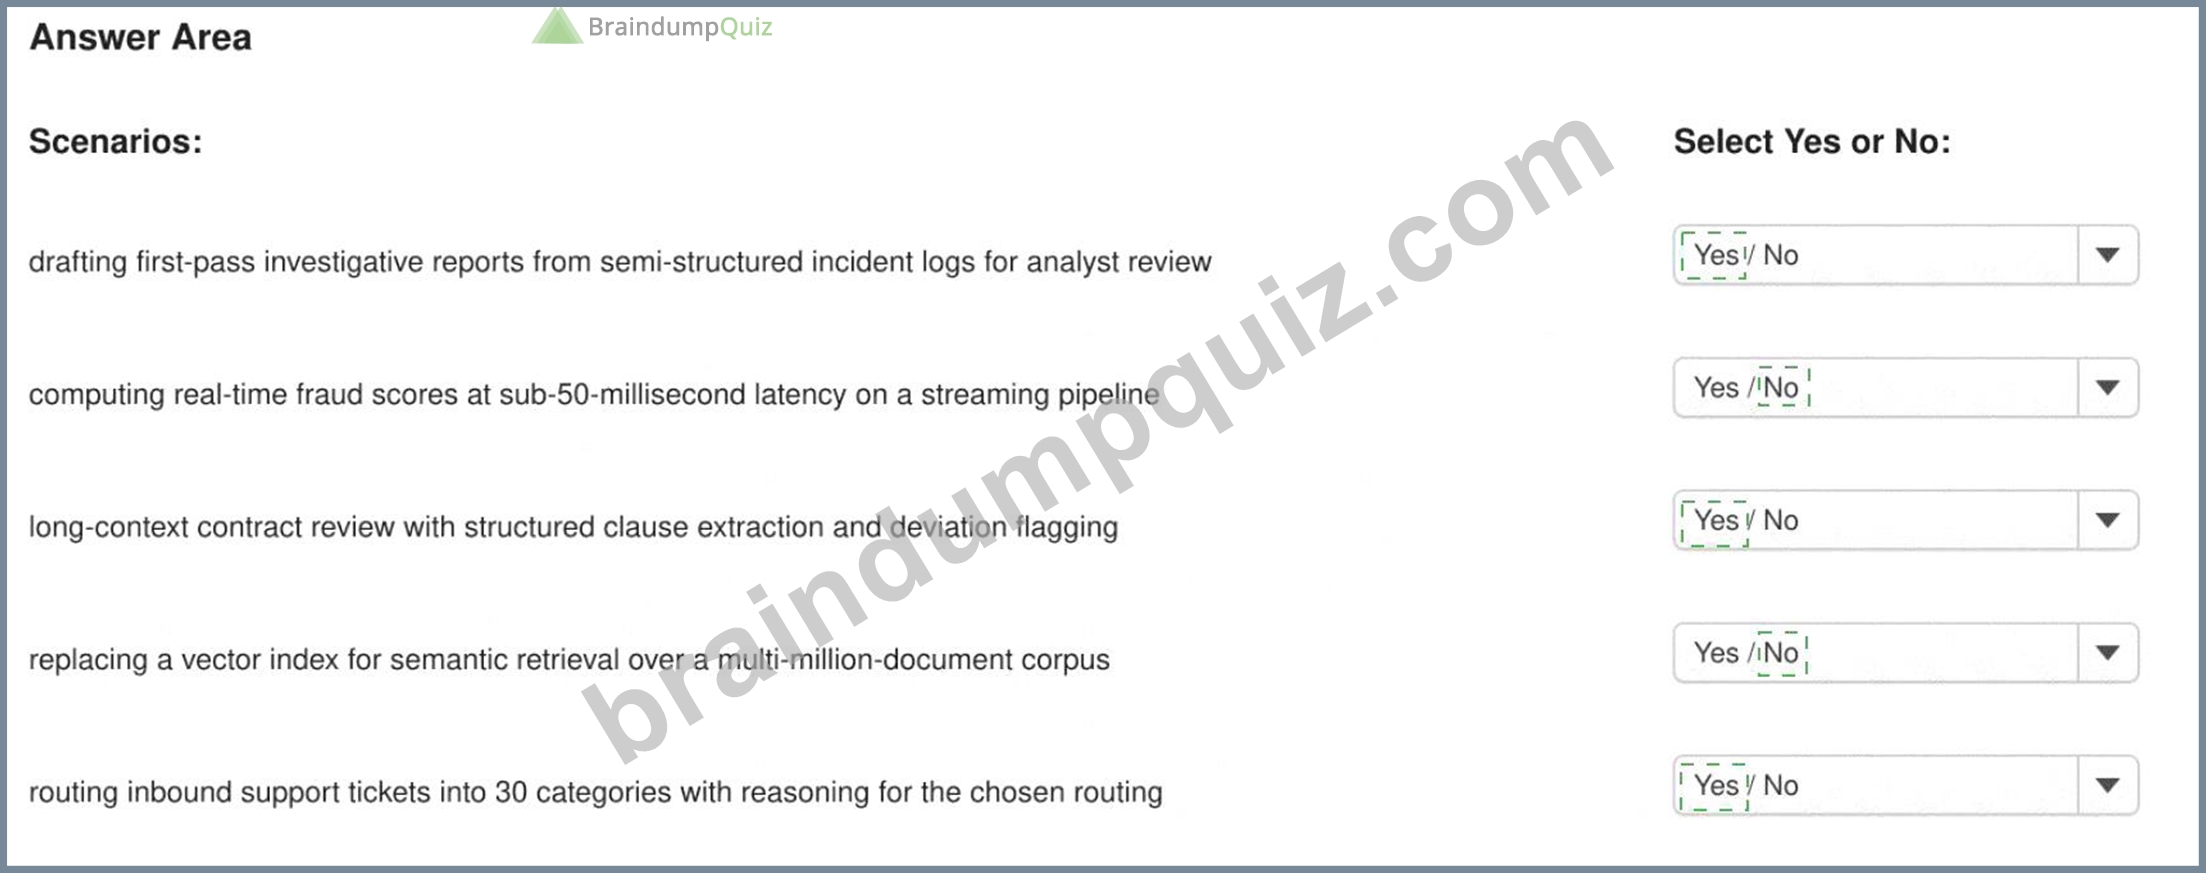
Explanation:
Drafting first-pass investigative reports from semi-structured incident logs for analyst review - Yes Computing real-time fraud scores at sub-50-millisecond latency on a streaming pipeline - No Long-context contract review with structured clause extraction and deviation flagging - Yes Replacing a vector index for semantic retrieval over a multi-million-document corpus - No Routing inbound support tickets into 30 categories with reasoning for the selected route - Yes Claude is well suited to language-intensive analysis, summarization, extraction, classification, and drafting.
Investigative-report drafting, contract analysis, and support-ticket routing all require interpretation of unstructured or semi-structured language and can incorporate human review. A sub-50-millisecond fraud- scoring path requires deterministic, specialized real-time processing and should not place LLM inference on the critical path. Claude also does not replace the retrieval index used to search millions of documents; it consumes the results produced by that infrastructure. The correct architectural decision separates tasks requiring semantic language reasoning from deterministic computation and information-retrieval infrastructure. Model selection and evaluation must then confirm that the chosen Claude model satisfies quality, latency, and cost requirements.
NEW QUESTION # 47
A Claude architect is configuring a shared Claude Code environment for a twelve-person development team.
Which two configuration decisions most directly establish a consistent, secure team environment? (Select two.)
Answer: A,D
NEW QUESTION # 48
You are evaluating an evaluation set used to score a Claude-based hiring-support tool. The set is drawn from one geographic region and one tenure band.
Which response is most appropriate?
Answer: A
Explanation:
An evaluation set must represent the populations, operating conditions, and use cases that the deployed system will encounter. A dataset drawn from only one geographic region and one tenure band cannot reliably demonstrate that the hiring-support tool performs consistently across its intended users. Expanding the evaluation set enables architects to identify regional performance differences, tenure-related errors, unsupported generalizations, and potentially discriminatory outcomes before broader deployment. The system should then be rescored using the expanded dataset, with results examined across relevant population slices rather than relying only on an aggregate score. Options A and B preserve or worsen the representation gap.
Option D is also inappropriate because qualitative feedback can supplement structured evaluation but cannot replace measurable, repeatable testing of accuracy, fairness, and reliability across the intended deployment population.
NEW QUESTION # 49
You are listing characteristics of robust guardrail design for an enterprise deployment.
Which two characteristics belong on the list? (Select two.)
Each correct answer presents a complete solution.
Answer: D,E
Explanation:
Robust guardrails require both preventive enforcement and continuous empirical validation. Per-role tool allow-lists satisfy the preventive requirement by restricting each authenticated role to explicitly authorized tools. Enforcement must occur in the orchestration or permission layer before execution; relying on the model to decide whether a tool call is authorized is not an adequate security boundary. Anthropic recommends allow- list-based validation and provides permission rules and pre-tool-use controls capable of denying calls before they execute.
Adversarial evaluation with regression tracking supplies the validation component. The evaluation set should include prompt injections, indirect injections, encoded instructions, multi-turn escalation, role-confusion attempts, and requests designed to trigger unauthorized tool use. Guardrail performance must then be measured across releases so that changes to prompts, models, tools, or orchestration logic do not silently reduce protection.
Centralized logging and user feedback are useful detective and lifecycle controls, but neither prevents an unsafe action nor proves guardrail effectiveness. Periodically refreshing refusal wording is also insufficient unless the revised behavior is evaluated against defined safety criteria. The strongest design therefore combines deterministic authorization with adversarial regression testing.
Study Guide references/topics: Claude Code permissions and pre-tool enforcement ; tool allow-list guidance ; adversarial evaluations; regression testing; least-privilege orchestration.
NEW QUESTION # 50
You are integrating AI-assisted tooling into the team's documentation workflow. The team wants generated documentation that stays grounded in the actual code.
Which integration approach best fits this requirement?
Answer: C
Explanation:
Documentation remains grounded only when the generating agent can inspect the authoritative implementation. A purpose-built subagent should receive scoped filesystem and code-search capabilities, identify the relevant modules, interfaces, configuration files, tests, and call sites, and generate documentation from that evidence. This approach minimizes reliance on training-data recall, which cannot represent the repository's current private code or recent changes.
Subagents are useful because repository exploration occurs in their own context, allowing them to return focused findings or proposed edits without filling the main conversation with every file read. Their tool access should follow least privilege: read access to required paths, narrowly controlled write access, and explicit exclusions for secrets or unrelated repositories.
Generated documentation should enter the team's established change-control process as a patch, branch, or pull request. Normal review, automated checks, link validation, example execution, and human approval provide accountability and prevent unverified material from being published. Direct publication bypasses these safeguards, while disabling repository tools makes factual grounding impossible.
Study Guide references/topics: [Claude Code custom subagents](https://docs.anthropic.com/en/docs/claude- code/sub-agents); [codebase exploration workflows] (https://docs.anthropic.com/en/docs/claude-code
/common-workflows); source-grounded generation; least-privilege tools; human review and lifecycle controls.
NEW QUESTION # 51
......
As we all know, practice makes perfect. It’s also applied into preparing for the exam. CCAR-P training materials of us contain both quality and quantity, and you will get enough practice if you choose us. In addition, CCAR-P exam cram cover most of the knowledge points for the exam, and you can master the major knowledge points for the exam as well as improve your professional ability in the process of learning. We are pass guarantee and money back guarantee if you fail to pass your exam by using CCAR-P Exam Dumps of us. Online and offline service are available by us, if you have any questions, you can consult us.
CCAR-P Exam Simulator: https://www.braindumpquiz.com/CCAR-P-exam-material.html