P.S. JpexamがGoogle Driveで共有している無料かつ新しいDatabricks-Generative-AI-Engineer-Associateダンプ:https://drive.google.com/open?id=12oOlY8_UJWEdr_ZyJmKAlFxf7QAGz6pU
私たちDatabricksは1日24時間顧客にオンライン顧客サービスを提供し、長距離オンラインでクライアントを支援する専門スタッフを提供します。 販売前または販売後に提供するDatabricks Certified Generative AI Engineer Associateガイドトレントについて質問や疑問がある場合は、お問い合わせください。Databricks-Generative-AI-Engineer-Associate試験教材の使用に関する問題の解決を支援するために、カスタマーサービスと専門スタッフをお送りします。 。 クライアントは、メールを送信するか、オンラインで問い合わせることができます。 私たちはできるだけ早くあなたの問題を解決し、最高のサービスを提供します。 Jpexamアフターサービスは、問題を迅速に解決し、お金を無駄にしないため、素晴らしいものです。 Databricks-Generative-AI-Engineer-Associate試験トレントに満足できない場合は、製品を返品して全額払い戻すことができます。
| Section | Objectives |
|---|---|
| Topic 1: Responsible AI and Governance | - AI safety and ethics
|
| Topic 2: Databricks Mosaic AI Platform | - Model development and serving
|
| Topic 3: Prompt Engineering | - Prompt evaluation
|
| Topic 4: Retrieval-Augmented Generation (RAG) | - RAG architecture
|
| Topic 5: Foundations of Generative AI | - Large Language Models (LLMs)
|
>> Databricks-Generative-AI-Engineer-Associate日本語版トレーリング <<
Databricks事実が語るよりも説得力があることは明らかです。したがって、当社がコンパイルしたDatabricks-Generative-AI-Engineer-Associateテストトレントを味わうために、このWebサイトで無料デモを用意しました。 弊社JpexamがまとめたDatabricks-Generative-AI-Engineer-Associate試験トレントは、試験に備えるための最高のDatabricks-Generative-AI-Engineer-Associate試験トレントであると私たちが確信している理由を理解するでしょう。 無料のデモはいつでも好きなときにダウンロードできます。いつでも試してみてください。Databricks-Generative-AI-Engineer-AssociateのDatabricks Certified Generative AI Engineer Associate試験の資料は決してあなたを失望させません。
質問 # 23
A Generative Al Engineer is responsible for developing a chatbot to enable their company's internal HelpDesk Call Center team to more quickly find related tickets and provide resolution. While creating the GenAI application work breakdown tasks for this project, they realize they need to start planning which data sources (either Unity Catalog volume or Delta table) they could choose for this application. They have collected several candidate data sources for consideration:
call_rep_history: a Delta table with primary keys representative_id, call_id. This table is maintained to calculate representatives' call resolution from fields call_duration and call start_time.
transcript Volume: a Unity Catalog Volume of all recordings as a *.wav files, but also a text transcript as *.txt files.
call_cust_history: a Delta table with primary keys customer_id, cal1_id. This table is maintained to calculate how much internal customers use the HelpDesk to make sure that the charge back model is consistent with actual service use.
call_detail: a Delta table that includes a snapshot of all call details updated hourly. It includes root_cause and resolution fields, but those fields may be empty for calls that are still active.
maintenance_schedule - a Delta table that includes a listing of both HelpDesk application outages as well as planned upcoming maintenance downtimes.
They need sources that could add context to best identify ticket root cause and resolution.
Which TWO sources do that? (Choose two.)
正解:A、D
解説:
In the context of developing a chatbot for a company's internal HelpDesk Call Center, the key is to select data sources that provide the most contextual and detailed information about the issues being addressed. This includes identifying the root cause and suggesting resolutions. The two most appropriate sources from the list are:
* Call Detail (Option D):
* Contents: This Delta table includes a snapshot of all call details updated hourly, featuring essential fields like root_cause and resolution.
* Relevance: The inclusion of root_cause and resolution fields makes this source particularly valuable, as it directly contains the information necessary to understand and resolve the issues discussed in the calls. Even if some records are incomplete, the data provided is crucial for a chatbot aimed at speeding up resolution identification.
* Transcript Volume (Option E):
* Contents: This Unity Catalog Volume contains recordings in .wav format and text transcripts in .txt files.
* Relevance: The text transcripts of call recordings can provide in-depth context that the chatbot can analyze to understand the nuances of each issue. The chatbot can use natural language processing techniques to extract themes, identify problems, and suggest resolutions based on previous similar interactions documented in the transcripts.
Why Other Options Are Less Suitable:
* A (Call Cust History): While it provides insights into customer interactions with the HelpDesk, it focuses more on the usage metrics rather than the content of the calls or the issues discussed.
* B (Maintenance Schedule): This data is useful for understanding when services may not be available but does not contribute directly to resolving user issues or identifying root causes.
* C (Call Rep History): Though it offers data on call durations and start times, which could help in assessing performance, it lacks direct information on the issues being resolved.
Therefore, Call Detail and Transcript Volume are the most relevant data sources for a chatbot designed to assist with identifying and resolving issues in a HelpDesk Call Center setting, as they provide direct and contextual information related to customer issues.
質問 # 24
A Generative Al Engineer would like an LLM to generate formatted JSON from emails. This will require parsing and extracting the following information: order ID, date, and sender email. Here's a sample email: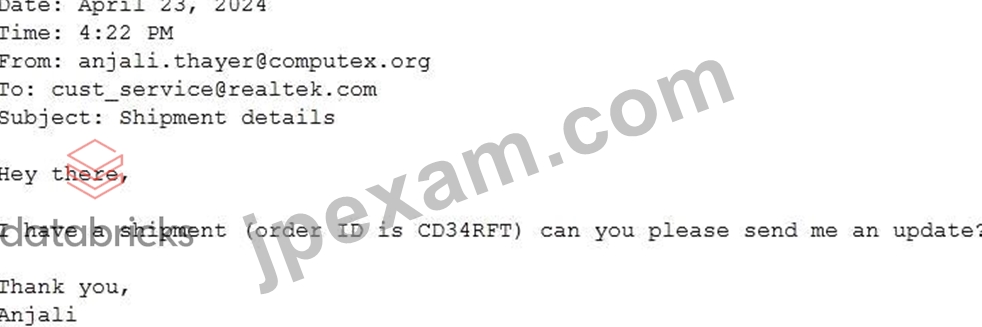
They will need to write a prompt that will extract the relevant information in JSON format with the highest level of output accuracy.
Which prompt will do that?
正解:C
解説:
Problem Context: The goal is to parse emails to extract certain pieces of information and output this in a structured JSON format. Clarity and specificity in the prompt design will ensure higher accuracy in the LLM' s responses.
Explanation of Options:
* Option A: Provides a general guideline but lacks an example, which helps an LLM understand the exact format expected.
* Option B: Includes a clear instruction and a specific example of the output format. Providing an example is crucial as it helps set the pattern and format in which the information should be structured, leading to more accurate results.
* Option C: Does not specify that the output should be in JSON format, thus not meeting the requirement.
* Option D: While it correctly asks for JSON format, it lacks an example that would guide the LLM on how to structure the JSON correctly.
Therefore,Option Bis optimal as it not only specifies the required format but also illustrates it with an example, enhancing the likelihood of accurate extraction and formatting by the LLM.
質問 # 25
A Generative AI Engineer is designing an LLM-powered live sports commentary platform. The platform provides real-time updates and LLM-generated analyses for any users who would like to have live summaries, rather than reading a series of potentially outdated news articles.
Which tool below will give the platform access to real-time data for generating game analyses based on the latest game scores?
正解:C
解説:
* Problem Context: The engineer is developing an LLM-powered live sports commentary platform that needs to provide real-time updates and analyses based on the latest game scores. The critical requirement here is the capability to access and integrate real-time data efficiently with the platform for immediate analysis and reporting.
* Explanation of Options:
* Option A: DatabricksIQ: While DatabricksIQ offers integration and data processing capabilities, it is more aligned with data analytics rather than real-time feature serving, which is crucial for immediate updates necessary in a live sports commentary context.
* Option B: Foundation Model APIs: These APIs facilitate interactions with pre-trained models and could be part of the solution, but on their own, they do not provide mechanisms to access real- time game scores.
* Option C: Feature Serving: This is the correct answer as feature serving specifically refers to the real-time provision of data (features) to models for prediction. This would be essential for an LLM that generates analyses based on live game data, ensuring that the commentary is current and based on the latest events in the sport.
* Option D: AutoML: This tool automates the process of applying machine learning models to real-world problems, but it does not directly provide real-time data access, which is a critical requirement for the platform.
Thus,Option C(Feature Serving) is the most suitable tool for the platform as it directly supports the real-time data needs of an LLM-powered sports commentary system, ensuring that the analyses and updates are based on the latest available information.
質問 # 26
A Generative AI Engineer is managing prompt templates using MLflow v3.x for a document summarization pipeline. A regulatory audit requires the team to demonstrate exactly which prompt version was used to generate outputs on a specific date three months ago, including the exact prompt text and any variables used at that time.
Which combination of MLflow v3.x capabilities allows the engineer to satisfy this audit requirement?
正解:D
解説:
The Prompt Registry preserves identifiable prompt versions, allowing the team to recover the exact template associated with a historical execution. Linking inference activity to the prompt's name and version establishes which registered template the application actually used. MLflow also supports lineage between prompt versions, application versions, and execution traces. However, satisfying the entire audit requires retaining the actual runtime variable values or the fully rendered prompt in the relevant execution records. Registry history alone preserves the template, not every value substituted into it. Therefore, D is the best option, provided the logging captures those inputs. Model webhooks, experiment tags, or table history alone do not provide the same explicit prompt-version lineage and complete historical reconstruction. Databricks documentation
質問 # 27
A Generative AI Engineer is tasked with deploying an application that takes advantage of a custom MLflow Pyfunc model to return some interim results.
How should they configure the endpoint to pass the secrets and credentials?
正解:B
解説:
Context: Deploying an application that uses an MLflow Pyfunc model involves managing sensitive information such as secrets and credentials securely.
Explanation of Options:
* Option A: Use spark.conf.set(): While this method can pass configurations within Spark jobs, using it for secrets is not recommended because it may expose them in logs or Spark UI.
* Option B: Pass variables using the Databricks Feature Store API: The Feature Store API is designed for managing features for machine learning, not for handling secrets or credentials.
* Option C: Add credentials using environment variables: This is a common practice for managing credentials in a secure manner, as environment variables can be accessed securely by applications without exposing them in the codebase.
* Option D: Pass the secrets in plain text: This is highly insecure and not recommended, as it exposes sensitive information directly in the code.
Therefore,Option Cis the best method for securely passing secrets and credentials to an application, protecting them from exposure.
質問 # 28
......
Jpexamは全面的な国際IT認証試験問題集を提供して、99%の合格率を作れるというものです。弊社のDatabricks-Generative-AI-Engineer-Associate問題集への勉強を通して、あなたは試験に関する専門知識を習得できるばかりでなく、仕事での能力を高めることができます。弊社のDatabricksのDatabricks-Generative-AI-Engineer-Associate問題集を利用して力の限りまで勉強して、合格しやすいです。万が一失敗したら、弊社は全額返金を承諾いたします。
Databricks-Generative-AI-Engineer-Associate教育資料: https://www.jpexam.com/Databricks-Generative-AI-Engineer-Associate_exam.html
P.S. JpexamがGoogle Driveで共有している無料かつ新しいDatabricks-Generative-AI-Engineer-Associateダンプ:https://drive.google.com/open?id=12oOlY8_UJWEdr_ZyJmKAlFxf7QAGz6pU