P.S. Free 2026 Microsoft DP-800 dumps are available on Google Drive shared by BraindumpsVCE: https://drive.google.com/open?id=1_GF7UTYrYAKh1RT6HfgNDxvkTnN7z-TE
With DP-800 study engine, you will get rid of the dilemma that you work hard but cannot improve. With our DP-800 learning materials, you can spend less time but learn more knowledge than others. DP-800 exam questions will help you reach the peak of your career. Just think of that after you get the Developing AI-Enabled Database Solutions DP-800 Certification, you will have a lot of opportunities of going to biger and better company and getting higher incomes!
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Design and develop database solutions (35–40%) | 35-40% | - Implement data management
|
| Topic 2: Secure, optimize, and deploy database solutions (35–40%) | 35-40% | - Optimize database performance
|
| Topic 3: Implement AI capabilities in database solutions (25–30%) | 25-30% | - Integrate Azure AI services
|
>> Microsoft DP-800 Latest Exam Price <<
In recent years, our DP-800 Test Torrent has been well received and have reached 99% pass rate with all our dedication. As a powerful tool for a lot of workers to walk forward a higher self-improvement, our DP-800 certification training continue to pursue our passion for advanced performance and human-centric technology. As a matter of fact, our company takes account of every client’s difficulties with fitting solutions. As long as you need help, we will offer instant support to deal with any of your problems about our Developing AI-Enabled Database Solutions guide torrent. Any time is available; our responsible staff will be pleased to answer your questions.
NEW QUESTION # 43
Case Study 1 - Contoso
Existing Environment
Azure Environment
Contoso has an Azure subscription in North Europe that contains the corporate infrastructure.
The current infrastructure contains a Microsoft SQL Server 2017 database. The database contains the following tables.
The FeedbackJsoncolumn has a full-text index and stores JSON documents in the following format.
The support staff at Contoso never has the UNMASKpermission.
Problem Statements
Contoso is deploying a new Azure SQL database that will become the authoritative data store for the following:
* AI workloads
* Vector search
* Modernized API access
* Retrieval Augmented Generation (RAG) pipelines
Sometimes the ingestion pipeline fails due to malformed JSON and duplicate payloads.
The engineers at Contoso report that the following dashboard query runs slowly.
You review the execution plan and discover that the plan shows a clustered index scan.
VehicleIncidentReportsoften contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
Requirements
Planned Changes
Contoso wants to modernize Fleet Intelligence Platform to support AI-powered semantic search over incident reports.
Security Requirements
Contoso identifies the following security requirements:
* Restrict the support staff from viewing Personally Identifiable Information (PII) data, which is full email addresses and phone numbers.
* Enforce row-level filtering so that analysts see only incidents for the fleets to which they are assigned. The analysts can be assigned to multiple fleets.
Database Performance and Requirements
Contoso identifies the following telemetry requirements:
* Telemetry data must be stored in a partitioned table.
* Telemetry data must provide predictable performance for ingestion and retention operations.
* latitude, longitude, and accuracyJSON properties must be filtered by using an index seek.
Contoso identifies the following maintenance data requirements:
* Ensure that any changes to a row in the MaintenanceEventstable updates the corresponding value in the LastModifiedUtccolumn to the time of the change.
* Avoid recursive updates.
AI Search, Embeddings, and Vector Indexing
Contoso plans to implement semantic search over incident data to meet the following requirements:
* Embeddings must be stored in dedicated Azure SQL Database tables.
* Embeddings must be generated from rich natural language fields.
* Chunking must preserve semantic coherence.
* Hybrid search must combine the following:
- Vector similarity
- Keyword filtering or boosting
Development Requirements
The development team at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases.
Contoso identifies the following requirements for querying data in the FeedbackJsoncolumn of the CustomerFeedbacktable:
* Extract the customer feedback text from the JSON document.
* Filter rows where the JSON text contains a keyword.
* Calculate a fuzzy similarity score between the feedback text and a known issue description.
* Order the results by similarity score, with the highest score first.
Hotspot Question
You are creating a table that will store customer profiles.
You have the following Transact-SQL code.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
NEW QUESTION # 44
You need to design a generative Al solution that uses a Microsoft SOL Server 2025 database named DB1 as a data source. The solution must generate responses that meet the following requirements:
* Ait ' grounded In the latest transactional and reference data stored in D61
* Do NOT require retraining or fine-tuning the language model when the data changes
* Can include citations or references to the source data used in the response Which scenario is the best use case for implementing a Retrieval Augmented Generation (RAG) pattern?
More than one answer choice may achieve the goal. Select the BEST answer
Answer: C
Explanation:
The best use case for RAG is answering user questions based on company-specific knowledge . Microsoft defines RAG as a pattern that augments a language model with a retrieval system that provides grounding data at inference time, which is exactly what you need when responses must be based on the latest transactional and reference data , must avoid retraining/fine-tuning , and should be able to include citations or references to source data.
The other options do not fit as well:
* summarizing free-form user input does not inherently require retrieval from DB1,
* training a custom model contradicts the requirement to avoid retraining/fine-tuning,
* generating marketing slogans is a creative generation task, not a grounding-and-citation scenario. RAG is specifically strong when answers must come from your organization's own changing knowledge.
NEW QUESTION # 45
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a SQL database in Microsoft Fabric that contains a table named dbo.Orders.
dbo.Orders has a clustered index, contains three years of data, and is partitioned by a column named OrderDate by month.
You need to remove all the rows for the oldest month. The solution must minimize the impact on other queries that access the data in dbo.Orders.
Solution: Identify the partition number for the oldest month, and then run the following Transact- SQL statement.
TRUNCATE TABLE dbo.Orders
WITH (PARTITIONS (partition number));
Does this meet the goal?
Answer: A
Explanation:
Correct:
* Identify the partition number for the oldest month, and then run the following Transact-SQL statement.
TRUNCATE TABLE dbo.Orders
WITH (PARTITIONS (partition number));
The best Transact-SQL statement to remove all rows for the oldest month while minimizing the impact on other queries is TRUNCATE TABLE with a WITH (PARTITIONS (...)) clause.
Why TRUNCATE TABLE ... WITH (PARTITIONS (...)) is Best
Efficiency: TRUNCATE TABLE is a Data Definition Language (DDL) operation that removes data by deallocating the data pages, which is a metadata operation and is very fast, regardless of the amount of data in the partition.
Minimal Logging: It uses less transaction log space compared to a DELETE statement, which logs each row deletion individually.
Low Impact on Concurrency: It performs a quick, partition-specific operation. A row-by-row DELETE would be a long-running transaction and could cause locking and blocking issues for other queries accessing the table.
Data Integrity: Because the table has a clustered index and is partitioned by the same column (aligned indexes), the TRUNCATE PARTITION operation is a fast, partition-level maintenance operation that targets only that specific data subset.
Incorrect:
* : Identify the partition scheme for the oldest month, and then run the following Transact-SQL statement.
ALTER TABLE dbo.Orders
DROP PARTITION SCHEME (partition_scheme_name);
The DROP PARTITION SCHEME statement removes the partition scheme object from the database but does not remove the data itself or free up the space, and it requires all tables to be moved off the scheme first, which is a complex operation. This does not meet the goal of removing the data efficiently.
* Run the following Transact-SQL statement.
DELETE FROM dbo.Orders
WHERE OrderDate < DATEADD(month, -36, SYSUTCDATETIME());
A standard DELETE statement, even with a WHERE clause that uses the partition column, can be a time-consuming, logged operation that causes locking and blocking on the main table, negatively impacting performance.
Reference:
https://stackoverflow.com/questions/63632963/truncate-partition-vs-drop-partition-performace- wise-which-one-is-efficient-an
NEW QUESTION # 46
You have a GitHub Enterprise subscription.
Your team is developing an Azure SQL dataset solution from a locally cloned GitHub repository by using Microsoft Visual Studio Code and GitHub Copilot Chat.
A mix of GitHub Copilot instructions is configured at different levels, including organization-wide, repository- wide, agent-specific, and personal.
Based on the GitHub Copilot instruction precedence rules, which instructions will take precedence over the others?
Answer: D
NEW QUESTION # 47
You have an Azure SQL database that contains a table named knowledgebase, knowledgebase stores human resources (HR) policy documents and contains columns named title, content, category, and embedding.
You have an application named App1. App1 queries two relational tables named employee_pnofiles and benefits_enrollnent that contain HR data. App1 hosts a chatbot that calls a large language model (LLM) directly.
Users report that the chatbot answers general HR questions correctly but provides outdated or incorrect answers when policies change. The chatbot also fails to answer questions that reference internal policy documents by title or category.
You need to recommend a Retrieval Augmented Generation (RAG) solution to resolve the chatbot issues.
What should you recommend? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation: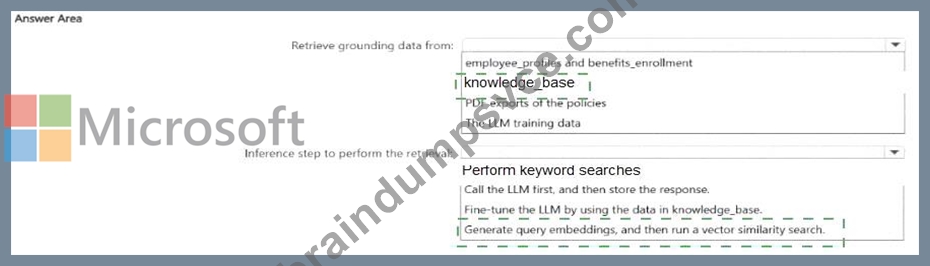
Explanation:
The correct recommendation is to retrieve grounding data from knowledge_base and, at inference time, generate query embeddings and run a vector similarity search.
The chatbot currently answers some general HR questions but fails when policies change and when users ask about internal policy documents by title or category. That is exactly the kind of problem RAG is meant to solve: ground the LLM in the organization's proprietary content instead of relying on the model's training data or unrelated transactional tables. Microsoft's RAG guidance states that RAG extends LLMs by grounding responses in your own content and that, for agentic retrieval, knowledge bases unify knowledge sources for retrieval.
So the grounding data should come from knowledge_base, because that table stores the HR policy documents and already includes fields like title, content, category, and embedding. Those are the fields directly tied to the missing and outdated policy answers. By contrast:
employee_profiles and benefits_enrollment are operational HR tables, not the authoritative store for policy- document grounding.
PDF exports of the policies would be inferior to querying the indexed/structured knowledge base already prepared for retrieval.
The LLM training data is specifically the wrong source when the issue is outdated internal content.
For the retrieval step, Microsoft's guidance says to use embeddings for vector queries and notes that vector similarity search matches concepts, not exact terms. This is especially important because users ask about policy documents by title or category and also phrase questions in ways that might not exactly match document wording. Generating a query embedding and then running a vector similarity search is the appropriate retrieval step in a RAG pipeline.
NEW QUESTION # 48
......
The BraindumpsVCE aids students in passing the test on their first try by giving them the real questions in three formats, 24/7 support team assistance, free demo, up to 1 year of free updates, and the satisfaction guarantee. As a result of its persistent efforts in providing candidates with actual DP-800 Exam Questions, BraindumpsVCE has become one of the best platforms to prepare for the Microsoft DP-800 exam successfully. One must prepare with BraindumpsVCE exam questions if one wishes to pass the DP-800 exam on their first attempt.
DP-800 Latest Exam Fee: https://www.braindumpsvce.com/DP-800_exam-dumps-torrent.html
P.S. Free & New DP-800 dumps are available on Google Drive shared by BraindumpsVCE: https://drive.google.com/open?id=1_GF7UTYrYAKh1RT6HfgNDxvkTnN7z-TE