P.S.Pass4TestがGoogle Driveで共有している無料の2026 Workday Workday-Pro-Integrationsダンプ:https://drive.google.com/open?id=1OWW1RSekCLn6Si0d3KKK5_8wEZDH0eEx
あなたの人生に残念と後悔を残しないように、私たちはできるだけ人生を変えるあらゆるチャンスをつかむ必要があります。あなたはそれをやったことができましたか。Pass4TestのWorkdayのWorkday-Pro-Integrations試験トレーニング資料は成功したいIT職員のために作成されたのです。あなたがWorkdayのWorkday-Pro-Integrations認定試験に合格することを助けます。成功と擦れ違うことを避けるように速く行動しましょう。
| Section | Objectives |
|---|---|
| Data Transformation | - XSLT and mapping concepts
|
| Core Integration Tools | - Workday Studio concepts
|
| Enterprise Interface Builder (EIB) | - Inbound integrations
|
| Integration Fundamentals | - Security and access control
|
| Operations and Maintenance | - Monitoring integrations
|
>> Workday-Pro-Integrations日本語参考 <<
ここ数年、Workday-Pro-Integrations復習教材は、無数の受験者がWorkday-Pro-Integrations試験に合格するのに役立ちました。Workday-Pro-Integrations認定資格証明書を取得した後、仕事機会が増え、偉大な企業家になり、専門家になった人もいました。Workday-Pro-Integrations復習教材は多くのいい評価をもらいました。良い評判で、Workday-Pro-Integrations復習教材を選択する人がますます増えています。
質問 # 25
What is the task used to upload a new XSLT file for a pre-existing document transformation integration system?
正解:D
質問 # 26
Refer to the following scenario to answer the question below.
An external system needs a file containing data for recent worker job changes. They would like to receive a file routinely at 5 PM eastern standard time, every 48 hours. The file should show job changes since the last integration run.
What is the run frequency of the integration schedule?
正解:A
解説:
The schedule requirement is every 48 hours, which is handled as a daily recurrence pattern with an interval of two days. Workday scheduling separates the general run frequency from the more specific recurrence interval.
The run frequency is therefore Daily Recurrence, while the recurrence detail would define the integration to recur every two days. Hourly Recurrence would be used when the integration runs at hourly intervals, not every two calendar days. Minute Recurrence is far too granular for this requirement. Custom Recurrence is unnecessary because the stated pattern can be handled by the standard daily recurrence configuration. Since the file must include changes since the last run, this schedule supports incremental processing while keeping the cadence predictable.
質問 # 27
A vendor needs an EIB that uses a custom report to output data for payroll results. You have been asked to create a calculated field that will be used to output the highest deduction from a worker's payroll results.
Which calculated field functions do you use to accomplish this?
正解:A
解説:
Payroll results usually contain multiple related rows, so the report must identify the correct payroll result instance before outputting a single value. A True/False Condition is used to define which deduction rows qualify for evaluation, such as identifying valid deduction results. Extract Single Instance is then used to return one instance from that qualified set, typically based on a sort or selection rule that identifies the highest deduction. Evaluate Expression is unnecessary because the requirement is not an if/then output selection; it is selecting one related instance from a multi-instance group. Text Constant is also irrelevant because no fixed text value is being added to the output. This is a data transformation problem inside a report-driven EIB.
質問 # 28
An external system needs a file containing data for recent compensation changes. They would like to receive a file routinely at 5 PM eastern standard time, excluding weekends. The file should show compensation changes since the last integration run.
What is the recurrence type of the integration schedule?
正解:C
解説:
Understanding the Requirement
The question involves scheduling an integration in Workday to deliver a file containing recent compensation changes to an external system. The key requirements are:
* The file must be delivered routinely at 5 PM Eastern Standard Time (EST).
* The recurrence should exclude weekends (i.e., run only on weekdays: Monday through Friday).
* The file should include compensation changes since the last integration run, implying an incremental data pull, though this does not directly affect the recurrence type.
The task is to identify the correctrecurrence typefor the integration schedule from the given options:A.
Recurs every 12 hoursB. Recurs every weekdayC. Dependent recurrenceD. Recurs every 1 day(s) Analysis of the Workflow and Recurrence Options In Workday, integrations are scheduled using theIntegration Schedulefunctionality, typically within tools like Enterprise Interface Builder (EIB) or Workday Studio, though this scenario aligns closely with EIB for routine file-based integrations. The recurrence type determines how frequently and under what conditions the integration runs. Let's evaluate each option against the requirements:
Step-by-Step Breakdown
* Time Specification (5 PM EST):
* Workday allows scheduling integrations at a specific time of day (e.g., 5 PM EST). This is set in the schedule configuration and is independent of the recurrence type but confirms the need for a daily-based recurrence with a specific time slot.
* Exclusion of Weekends:
* The requirement explicitly states the integration should not run on weekends (Saturday and Sunday), meaning it should only execute on weekdays (Monday through Friday). This is a critical filter for choosing the recurrence type.
* Incremental Data (Since Last Run):
* The file must include compensation changes since the last integration run. In Workday, this is typically handled by configuring the integration (e.g., via a data source filter or "changed since" parameter in EIB), not the recurrence type. Thus, this requirement does not directly influence the recurrence type but confirms the integration runs periodically.
質問 # 29
Refer to the following XML to answer the question below.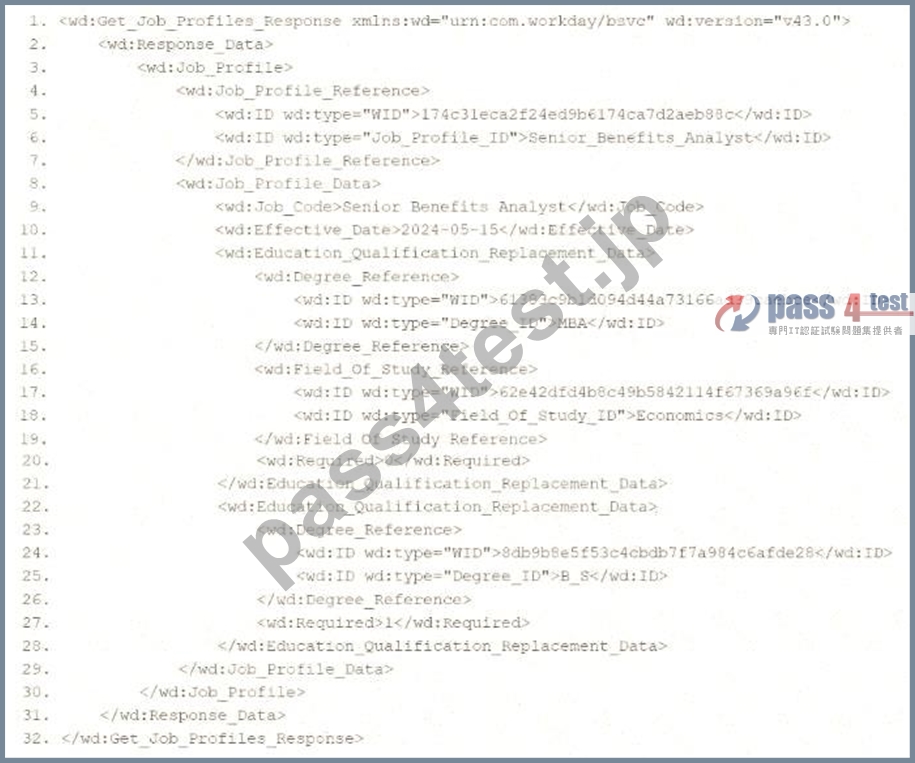
You are an integration developer and need to write XSLT to transform the output of an EIB which is making a request to the Get Job Profiles web service operation. The root template of your XSLT matches on the < wd:
Get_Job_Profiles_Response > element. This root template then applies a template against < wd:Job_Profile > .
What XPath syntax would be used to select the value of the wd:Job_Code element when the < xsl:value-of > element is placed within the template which matches on < wd:Job_Profile > ?
正解:D
解説:
As an integration developer working with Workday, you are tasked with transforming the output of an Enterprise Interface Builder (EIB) that calls the Get_Job_Profiles web service operation. The provided XML shows the response from this operation, and you need to write XSLT to select the value of the < wd:Job_Code
> element. The root template of your XSLT matches on < wd:Get_Job_Profiles_Response > and applies a template to < wd:Job_Profile > . Within this template, you use the < xsl:value-of > element to extract the < wd:Job_Code > value. Let's analyze the XML structure, the requirement, and each option to determine the correct XPath syntax.
Understanding the XML and Requirement
The XML snippet provided is a SOAP response from the Get_Job_Profiles web service operation in Workday, using the namespace xmlns:wd= " urn:com.workday/bsvc " and version wd:version= " v43.0 " .
Key elements relevant to the question include:
* The root element is < wd:Get_Job_Profiles_Response > .
* It contains < wd:Response_Data > , which includes < wd:Job_Profile > elements.
* Within < wd:Job_Profile > , there are:
* < wd:Job_Profile_Reference > , which contains < wd:ID > elements (e.g., a Job_Profile_ID).
* < wd:Job_Profile_Data > , which contains < wd:Job_Code > with the value Senior_Benefits_Analyst.
The task is to select the value of < wd:Job_Code > (e.g., " Senior_Benefits_Analyst " ) using XPath within an XSLT template that matches < wd:Job_Profile > . The < xsl:value-of > element outputs the value of the selected node, so you need the correct XPath path from the < wd:Job_Profile > context to < wd:Job_Code > .
Analysis of Options
Let's evaluate each option based on the XML structure and XPath syntax rules:
* Option A: wd:Job_Profile/wd:Job_Profile_Data/wd:Job_Code
* This XPath starts from wd:Job_Profile and navigates to wd:Job_Profile_Data/wd:Job_Code.
However, in the XML, < wd:Job_Profile > is the parent element, and < wd:Job_Profile_Data > is a direct child containing < wd:Job_Code > . The path wd:Job_Profile/wd:Job_Profile_Data/wd:
Job_Code is technically correct in terms of structure, as it follows the hierarchy:
* < wd:Job_Profile > # < wd:Job_Profile_Data > # < wd:Job_Code > .
* However, since the template matches < wd:Job_Profile > , the context node is already < wd:
Job_Profile > . You don't need to include wd:Job_Profile/ at the beginning of the XPath unless navigating from a higher level. Starting directly with wd:Job_Profile_Data/wd:Job_Code (Option C) is more concise and appropriate for the context. This option is technically valid but redundant and less efficient, making it less preferred compared to Option C.
* Option B: wd:Job_Profile_Data[@wd:Job_Code]
* This XPath uses an attribute selector ([@wd:Job_Code]) to filter < wd:Job_Profile_Data > based on an attribute named wd:Job_Code. However, examining the XML, < wd:Job_Profile_Data > does not have a wd:Job_Code attribute-it has a child element < wd:Job_Code > with the value " Senior_Benefits_Analyst. " The [@attribute] syntax is used for attributes, not child elements, so this XPath is incorrect. It would not select the < wd:Job_Code > value and would likely return no results or an error. This option is invalid.
* Option C: wd:Job_Profile_Data/wd:Job_Code
* This XPath starts from wd:Job_Profile_Data (a direct child of < wd:Job_Profile > ) and navigates to wd:Job_Code. Since the template matches < wd:Job_Profile > , the context node is < wd:
Job_Profile > , and wd:Job_Profile_Data/wd:Job_Code correctly points to the < wd:Job_Code > element within < wd:Job_Profile_Data > . This path is:
* Concise and appropriate for the context.
* Directly selects the value " Senior_Benefits_Analyst " when used with < xsl:value-of > .
* Matches the XML structure, as < wd:Job_Profile_Data > contains < wd:Job_Code > as a child.
* This is the most straightforward and correct option for selecting the < wd:Job_Code > value within the < wd:Job_Profile > template.
* Option D: wd:Job_Profile_Reference/wd:ID[@wd:type= ' Job_Profile_ID ' ]
* This XPath navigates to < wd:Job_Profile_Reference > (a child of < wd:Job_Profile > ) and then to < wd:ID > with an attribute wd:type= " Job_Profile_ID " . In the XML, < wd:
Job_Profile_Reference > contains:
* < wd:ID wd:type= " WID " > 1740d3eca2f2ed9b6174ca7d2ae88c8c < /wd:ID >
* < wd:ID wd:type= " Job_Profile_ID " > Senior_Benefits_Analyst < /wd:ID >
* The XPath wd:Job_Profile_Reference/wd:ID[@wd:type= ' Job_Profile_ID ' ] selects the < wd:ID
> element with wd:type= " Job_Profile_ID " , which has the value " Senior_Benefits_Analyst. " However, this is not the < wd:Job_Code > value-the < wd:Job_Code > is a separate element under < wd:Job_Profile_Data > , not < wd:Job_Profile_Reference > . The question specifically asks for the < wd:Job_Code > value, so this option is incorrect, as it selects a different piece of data (the job profile ID, not the job code).
Why Option C is Correct
Option C, wd:Job_Profile_Data/wd:Job_Code, is the correct XPath syntax because:
* It starts from the context node < wd:Job_Profile > (as the template matches this element) and navigates to < wd:Job_Profile_Data/wd:Job_Code > , which directly selects the < wd:Job_Code > element's value ( " Senior_Benefits_Analyst " ).
* It is concise and aligns with standard XPath navigation in XSLT, avoiding unnecessary redundancy (unlike Option A) or incorrect attribute selectors (unlike Option B).
* It matches the XML structure, where < wd:Job_Profile_Data > is a child of < wd:Job_Profile > and contains < wd:Job_Code > as a child.
* When used with < xsl:value-of select= " wd:Job_Profile_Data/wd:Job_Code " / > in the template, it outputs the job code value, fulfilling the requirement.
Practical Example in XSLT
Here's how this might look in your XSLT:
xml
WrapCopy
< xsl:template match= " wd:Job_Profile " >
< xsl:value-of select= " wd:Job_Profile_Data/wd:Job_Code " / >
< /xsl:template >
This would output " Senior_Benefits_Analyst " for the < wd:Job_Code > element in the XML.
Verification with Workday Documentation
The Workday Pro Integrations Study Guide and SOAP API Reference (available via Workday Community) detail the structure of the Get_Job_Profiles response and how to use XPath in XSLT for transformations. The XML structure shows < wd:Job_Profile_Data > as the container for job profile details, including < wd:
Job_Code > . The guide emphasizes using relative XPath paths within templates to navigate from the matched element (e.g., < wd:Job_Profile > ) to child elements like < wd:Job_Profile_Data/wd:Job_Code > .
Workday Pro Integrations Study Guide References
* Section: XSLT Transformations in EIBs - Describes using XSLT to transform web service responses, including selecting elements with XPath.
* Section: Workday Web Services - Details the Get_Job_Profiles operation and its XML output structure, including < wd:Job_Profile_Data > and < wd:Job_Code > .
* Section: XPath Syntax - Explains how to navigate XML hierarchies in Workday XSLT, using relative paths like wd:Job_Profile_Data/wd:Job_Code from a < wd:Job_Profile > context.
* Workday Community SOAP API Reference - Provides examples of XPath navigation for Workday web service responses.
Option C is the verified answer, as it correctly selects the < wd:Job_Code > value using the appropriate XPath syntax within the < wd:Job_Profile > template context.
質問 # 30
......
Workday-Pro-Integrations認定試験はIT業界の新たなターニングポイントの一つです。試験に受かったら、あなたはIT業界のエリートになることができます。情報技術の進歩と普及につれて、WorkdayのWorkday-Pro-Integrations問題集と解答を提供するオンライン·リソースが何百現れています。その中で、Pass4Testが他のサイトをずっと先んじてとても人気があるのは、Pass4TestのWorkdayのWorkday-Pro-Integrations試験トレーニング資料が本当に人々に恩恵をもたらすことができて、速く自分の夢を実現することにヘルプを差し上げられますから。
Workday-Pro-Integrations学習関連題: https://www.pass4test.jp/Workday-Pro-Integrations.html
さらに、Pass4Test Workday-Pro-Integrationsダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1OWW1RSekCLn6Si0d3KKK5_8wEZDH0eEx