Customizable Databricks Databricks-Certified-Data-Engineer-Professional Exam Mode - Databricks-Certified-Data-Engineer-Professional New Braindumps Questions

You can easily install Databricks Databricks-Certified-Data-Engineer-Professional exam questions file on your desktop computer, laptop, tabs, and smartphone devices and start Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) exam dumps preparation without wasting further time. Whereas the other two Databricks Databricks-Certified-Data-Engineer-Professional Practice Test software is concerned, both are the mock Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) exam that will give you a real-time Databricks-Certified-Data-Engineer-Professional practice exam environment for preparation.
| Section | Weight | Objectives |
|---|
| Data Governance | 7% | - Enforce data policies and standards
- Manage data assets and metadata
- Use Unity Catalog for governance
|
| Cost & Performance Optimisation | 13% | - Optimize compute and storage resources
- Apply cost management best practices
- Improve query and pipeline performance
|
| Data Transformation, Cleansing, and Quality | 10% | - Apply data cleansing and validation rules
- Enforce data quality standards
- Implement schema evolution and management
|
| Data Sharing and Federation | 5% | - Use Delta Sharing for secure data sharing
- Manage cross-platform data access
- Implement Lakehouse Federation
|
| Monitoring and Alerting | 10% | - Monitor pipeline performance and health
- Set up alerts and notifications
- Track data lineage and metrics
|
| Data Ingestion & Acquisition | 7% | - Use Auto Loader and structured streaming
- Ingest data from diverse sources
- Handle incremental and batch data loads
|
| Developing Code for Data Processing using Python and SQL | 22% | - Implement complex data processing logic
- Write efficient and maintainable code
- Use Databricks-specific libraries and APIs
|
| Data Modelling | 6% | - Optimize table design and partitioning
- Design Medallion Architecture
- Implement dimensional and relational models
|
| Ensuring Data Security and Compliance | 10% | - Ensure data privacy and compliance
- Implement access control and permissions
- Secure data at rest and in transit
|
| Debugging and Deploying | 10% | - Implement CI/CD and DevOps practices
- Deploy using Asset Bundles, CLI, and APIs
- Troubleshoot and debug pipelines
|
>> Customizable Databricks Databricks-Certified-Data-Engineer-Professional Exam Mode <<
Pass Databricks-Certified-Data-Engineer-Professional Exam with 100% Pass Rate Customizable Databricks-Certified-Data-Engineer-Professional Exam Mode by ExamsTorrent
It is browser-based; therefore no need to install it, and you can start practicing for the Databricks Databricks-Certified-Data-Engineer-Professional exam by creating the Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) practice test. You don't need to install any separate software or plugin to use it on your system to practice for your actual Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) exam. ExamsTorrent Databricks-Certified-Data-Engineer-Professional web-based practice software is supported by all well-known browsers like Chrome, Firefox, Opera, Internet Explorer, etc.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q137-Q142):
NEW QUESTION # 137
The downstream consumers of a Delta Lake table have been complaining about data quality issues impacting performance in their applications. Specifically, they have complained that invalid latitude and longitude values in the activity_details table have been breaking their ability to use other geolocation processes.
A junior engineer has written the following code to add CHECK constraints to the Delta Lake table:
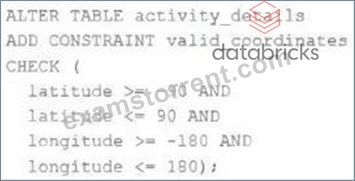
A senior engineer has confirmed the above logic is correct and the valid ranges for latitude and longitude are provided, but the code fails when executed.
Which statement explains the cause of this failure?
- A. The activity details table already contains records; CHECK constraints can only be added prior to inserting values into a table.
- B. The activity details table already exists; CHECK constraints can only be added during initial table creation.
- C. The current table schema does not contain the field valid coordinates; schema evolution will need Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from to be enabled before altering the table to add a constraint.
- D. The activity details table already contains records that violate the constraints; all existing data must pass CHECK constraints in order to add them to an existing table.
- E. Because another team uses this table to support a frequently running application, two-phase locking is preventing the operation from committing.
Answer: D
Explanation:
The failure is that the code to add CHECK constraints to the Delta Lake table fails when executed. The code uses ALTER TABLE ADD CONSTRAINT commands to add two CHECK constraints to a table named activity_details. The first constraint checks if the latitude value is between -90 and 90, and the second constraint checks if the longitude value is between -180 and
180. The cause of this failure is that the activity_details table already contains records that violate these constraints, meaning that they have invalid latitude or longitude values outside of these ranges. When adding CHECK constraints to an existing table, Delta Lake verifies that all existing data satisfies the constraints before adding them to the table. If any record violates the constraints, Delta Lake throws an exception and aborts the operation.
NEW QUESTION # 138
The data governance team is reviewing user for deleting records for compliance with GDPR. The following logic has been implemented to propagate deleted requests from the user_lookup table to the user aggregate table.
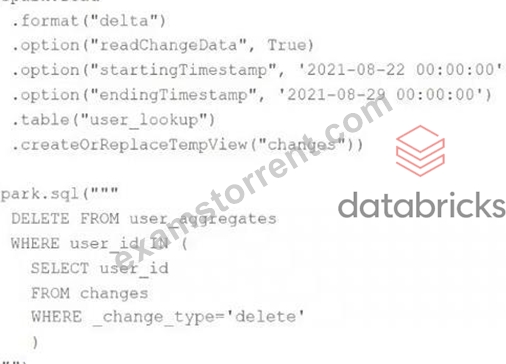
Assuming that user_id is a unique identifying key and that all users have requested deletion have been removed from the user_lookup table, which statement describes whether successfully executing the above logic guarantees that the records to be deleted from the user_aggregates table are no longer accessible and why?
- A. No; files containing deleted records may still be accessible with time travel until a BACUM command is used to remove invalidated data files.
- B. No; the change data feed only tracks inserts and updates not deleted records.
- C. Yes; Delta Lake ACID guarantees provide assurance that the DELETE command successed fully and permanently purged these records.
- D. Yes; the change data feed uses foreign keys to ensure delete consistency throughout the Lakehouse.
- E. No; the Delta Lake DELETE command only provides ACID guarantees when combined with the MERGE INTO command
Answer: A
Explanation:
The DELETE operation in Delta Lake is ACID compliant, which means that once the operation is successful, the records are logically removed from the table. However, the underlying files that contained these records may still exist and be accessible via time travel to older versions of the table. To ensure that these records are physically removed and compliance with GDPR is maintained, a VACUUM command should be used to clean up these data files after a certain retention period. The VACUUM command will remove the files from the storage layer, and after this, the records will no longer be accessible.
NEW QUESTION # 139
A data engineer has created a new cluster using shared access mode with default configurations.
The data engineer needs to allow the development team access to view the driver logs if needed.
What are the minimal cluster permissions that allow the development team to accomplish this?
- A. CAN ATTACH TO
- B. CAN RESTART
- C. CAN VIEW
- D. CAN MANAGE
Answer: C
Explanation:
The CAN VIEW permission on a cluster allows users to see cluster details, including driver and executor logs. This is the minimal permission required for the development team to access logs without granting them the ability to modify, restart, or attach notebooks to the cluster.
NEW QUESTION # 140
A data engineer inherits a Delta table with historical partitions by country that are badly skewed.
Queries often filter by high-cardinality customer_id and vary across dimensions over time. The engineer wants a strategy that avoids a disruptive full rewrite, reduces sensitivity to skewed partitions, and sustains strong query performance as access patterns evolve. Which two actions should the data engineer take? (Choose two.)
- A. Depend solely on optimized writes; Databricks will automatically replace partitioning with clustering over time.
- B. Disable data skipping statistics to avoid maintenance overhead; rely on adaptive query execution instead.
- C. Keep existing partitions and rely on bin-packing OPTIMIZE only; ZORDER and clustering are unnecessary for multi-dimensional filters.
- D. Switch from static partitioning to liquid clustering and select initial clustering keys that reflect common filters such as customer_id.
- E. Periodically run OPTIMIZE table_name.
Answer: D,E
Explanation:
Liquid Clustering replaces traditional partitioning and ZORDER optimization by automatically organizing data according to clustering keys. It supports evolving clustering strategies without requiring a full table rewrite. To maintain cluster balance and improve performance, the OPTIMIZE command should be run periodically. OPTIMIZE groups data files by clustering keys and helps reduce small file overhead.
NEW QUESTION # 141
A data engineer is working on a Databricks notebook that requires several third-party Python libraries. Some of these are available on PyPI, while others are custom-developed and stored as local.wheel (.whl) and source (.tar.gz) files in an S3 bucket. The goal is to ensure all dependencies are installed and correctly available across multiple jobs running on any automated cluster in a Unity Catalog-enabled workspace. The engineer needs to install the required dependencies in a way that ensures a consistent environment setup across interactive notebooks and jobs and complies with workspace security policies (no internet access). Which approach should the engineer use to install and manage these dependencies while also ensuring reproducibility and compliance?
- A. Use %pip install in every notebook and job to install packages directly from PyPl and custom S3 paths.
- B. Use an init script on the cluster to install all dependencies using pip, referencing the local file system.
- C. Create a Python wheel file for the entire project, upload it to the Databricks Workspace Files or Volumes, and install it using a Cluster Library or pip install in a requirements.txt declared within a Databricks Asset Bundle.
- D. Install all dependencies manually in the driver node of an interactive cluster, then export the environment and reimport on job clusters using %conda.
Answer: C
Explanation:
Packaging dependencies as wheel files and managing them through Databricks-supported artifacts ensures consistent, reproducible environments across interactive and job clusters.
Storing the wheels in Workspace Files or Unity Catalog Volumes complies with no-internet security constraints, while installing them via cluster libraries or Asset Bundles standardizes dependency management across all jobs and pipelines.
NEW QUESTION # 142
......
You must want to receive our Databricks-Certified-Data-Engineer-Professional practice materials at the first time after payment. Don't worry. As long as you finish your payment, our online workers will handle your orders of the study materials quickly. The whole payment process lasts a few seconds. Besides that, you can ask what you want to know about our Databricks-Certified-Data-Engineer-Professional Study Guide. Once you submit your questions, we will soon give you detailed explanations. Even you come across troubles during practice the Databricks-Certified-Data-Engineer-Professional study materials; we will also help you solve the problems. We are willing to deal with your problems on Databricks-Certified-Data-Engineer-Professional learning guide.
Databricks-Certified-Data-Engineer-Professional New Braindumps Questions: https://www.examstorrent.com/Databricks-Certified-Data-Engineer-Professional-exam-dumps-torrent.html
- Databricks-Certified-Data-Engineer-Professional Reliable Braindumps Sheet 🗜 Databricks-Certified-Data-Engineer-Professional Valid Cram Materials 📫 Databricks-Certified-Data-Engineer-Professional Exam Engine 🐎 Search on [ www.testkingpass.com ] for 《 Databricks-Certified-Data-Engineer-Professional 》 to obtain exam materials for free download ☃Databricks-Certified-Data-Engineer-Professional Materials
- Quiz Authoritative Databricks - Databricks-Certified-Data-Engineer-Professional - Customizable Databricks Certified Data Engineer Professional Exam Exam Mode 😜 Easily obtain free download of 《 Databricks-Certified-Data-Engineer-Professional 》 by searching on ☀ www.pdfvce.com ️☀️ 👘Exam Databricks-Certified-Data-Engineer-Professional Objectives
- Databricks Customizable Databricks-Certified-Data-Engineer-Professional Exam Mode: Databricks Certified Data Engineer Professional Exam - www.pdfdumps.com Professional Offer ⚪ Easily obtain ➥ Databricks-Certified-Data-Engineer-Professional 🡄 for free download through ⮆ www.pdfdumps.com ⮄ 🎸Latest Databricks-Certified-Data-Engineer-Professional Learning Materials
- Databricks-Certified-Data-Engineer-Professional Exam Engine 💁 Databricks-Certified-Data-Engineer-Professional Reliable Braindumps Sheet 🌷 Reliable Databricks-Certified-Data-Engineer-Professional Test Blueprint 🍲 Go to website ✔ www.pdfvce.com ️✔️ open and search for ➥ Databricks-Certified-Data-Engineer-Professional 🡄 to download for free 🐼Databricks-Certified-Data-Engineer-Professional Exam Discount
- Databricks-Certified-Data-Engineer-Professional Practice Exam 😍 Databricks-Certified-Data-Engineer-Professional Exam Questions Vce 🔟 Databricks-Certified-Data-Engineer-Professional Practice Guide 🤏 Search for ▷ Databricks-Certified-Data-Engineer-Professional ◁ and easily obtain a free download on ➤ www.dumpsquestion.com ⮘ ❤️Databricks-Certified-Data-Engineer-Professional New Exam Braindumps
- The latest Databricks certification Databricks-Certified-Data-Engineer-Professional exam practice questions and answers 🐋 Easily obtain ( Databricks-Certified-Data-Engineer-Professional ) for free download through 【 www.pdfvce.com 】 🖋Databricks-Certified-Data-Engineer-Professional Exam Discount
- Trustworthy Customizable Databricks-Certified-Data-Engineer-Professional Exam Mode | Amazing Pass Rate For Databricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam | Authorized Databricks-Certified-Data-Engineer-Professional New Braindumps Questions 🌑 The page for free download of 《 Databricks-Certified-Data-Engineer-Professional 》 on ▛ www.practicevce.com ▟ will open immediately 🏄Databricks-Certified-Data-Engineer-Professional Reliable Learning Materials
- Pass Guaranteed Databricks - Databricks-Certified-Data-Engineer-Professional - High Pass-Rate Customizable Databricks Certified Data Engineer Professional Exam Exam Mode ☝ Download ➽ Databricks-Certified-Data-Engineer-Professional 🢪 for free by simply entering ⮆ www.pdfvce.com ⮄ website 🍗Databricks-Certified-Data-Engineer-Professional Exam Discount
- Databricks-Certified-Data-Engineer-Professional Test Online 📶 Exam Databricks-Certified-Data-Engineer-Professional Objectives 🕜 Databricks-Certified-Data-Engineer-Professional Reliable Learning Materials 🕯 The page for free download of 「 Databricks-Certified-Data-Engineer-Professional 」 on “ www.examcollectionpass.com ” will open immediately 📑Dumps Databricks-Certified-Data-Engineer-Professional Free Download
- Databricks-Certified-Data-Engineer-Professional Valid Cram Materials 🥦 Databricks-Certified-Data-Engineer-Professional Reliable Braindumps Sheet ❤ Databricks-Certified-Data-Engineer-Professional Reliable Learning Materials 👤 Search on ➡ www.pdfvce.com ️⬅️ for ⇛ Databricks-Certified-Data-Engineer-Professional ⇚ to obtain exam materials for free download ✈Databricks-Certified-Data-Engineer-Professional Printable PDF
- 2026 High Hit-Rate 100% Free Databricks-Certified-Data-Engineer-Professional – 100% Free Customizable Exam Mode | Databricks Certified Data Engineer Professional Exam New Braindumps Questions 🐋 Download ☀ Databricks-Certified-Data-Engineer-Professional ️☀️ for free by simply entering ⮆ www.pdfdumps.com ⮄ website 🔢Databricks-Certified-Data-Engineer-Professional Exams Dumps
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes