Databricks-Certified-Professional-Data-Engineer Exam Cram Review | Databricks-Certified-Professional-Data-Engineer Study Materials

Believe it or not, our Databricks-Certified-Professional-Data-Engineer preparation questions will relieve you from poverty. It is important to make large amounts of money in modern society. Our Databricks-Certified-Professional-Data-Engineer practice engine has assisted many people to improve themselves. You also can become the lucky guys as long as you are willing to learn. And with our Databricks-Certified-Professional-Data-Engineer Exam Materials, you will find that to learn something is also a happy and enjoyable experience, and you can be rewarded by the certification as well.
Databricks is a cloud-based platform that provides data engineering, machine learning, and analytics services. The Databricks Certified Professional Data Engineer (DCPDE) exam is designed to test the skills and knowledge of data engineers who are responsible for building data pipelines, managing data infrastructure, and optimizing data processing workflows on the Databricks platform.
Databricks Certified Professional Data Engineer is a certification exam that tests the skills and knowledge required to design and implement data solutions using Databricks. Databricks is a cloud-based data platform that helps organizations manage and process large amounts of data. Databricks Certified Professional Data Engineer Exam certification exam is designed for data engineers who are responsible for creating and maintaining data pipelines, managing data storage, and implementing data solutions.
>> Databricks-Certified-Professional-Data-Engineer Exam Cram Review <<
Databricks-Certified-Professional-Data-Engineer Study Materials, Latest Databricks-Certified-Professional-Data-Engineer Braindumps Sheet
Do you want to pass Databricks-Certified-Professional-Data-Engineer exam and get the related certification within the minimum time and effort? If you would like to give me a positive answer, you really should keep a close eye on our website since you can find the best Databricks-Certified-Professional-Data-Engineer study material in here--our Databricks-Certified-Professional-Data-Engineer Training Materials. We have helped millions of thousands of candidates to prepare for the Databricks-Certified-Professional-Data-Engineer exam and all of them have got a fruitful outcome, we believe you will be the next winner as long as you join in us!
Databricks Certified Professional Data Engineer (Databricks-Certified-Professional-Data-Engineer) Certification Exam is a highly valued industry certification that validates the skills and expertise of data engineers in using Databricks to build and manage data pipelines. Databricks is a cloud-based data platform that offers a unified analytics engine for big data and machine learning. Databricks Certified Professional Data Engineer Exam certification exam is designed to test the candidate's knowledge of Databricks architecture, data engineering best practices, and data pipeline design and implementation.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q104-Q109):
NEW QUESTION # 104
Which of the following data workloads will utilize a Bronze table as its destination?
- A. A job that aggregates cleaned data to create standard summary statistics
- B. A job that develops a feature set for a machine learning application
- C. A job that ingests raw data from a streaming source into the Lakehouse
- D. A job that queries aggregated data to publish key insights into a dashboard
- E. A job that enriches data by parsing its timestamps into a human-readable format
Answer: C
Explanation:
Explanation
The answer is A job that ingests raw data from a streaming source into the Lakehouse.
The ingested data from the raw streaming data source like Kafka is first stored in the Bronze layer as first destination before it is further optimized and stored in Silver.
Medallion Architecture - Databricks
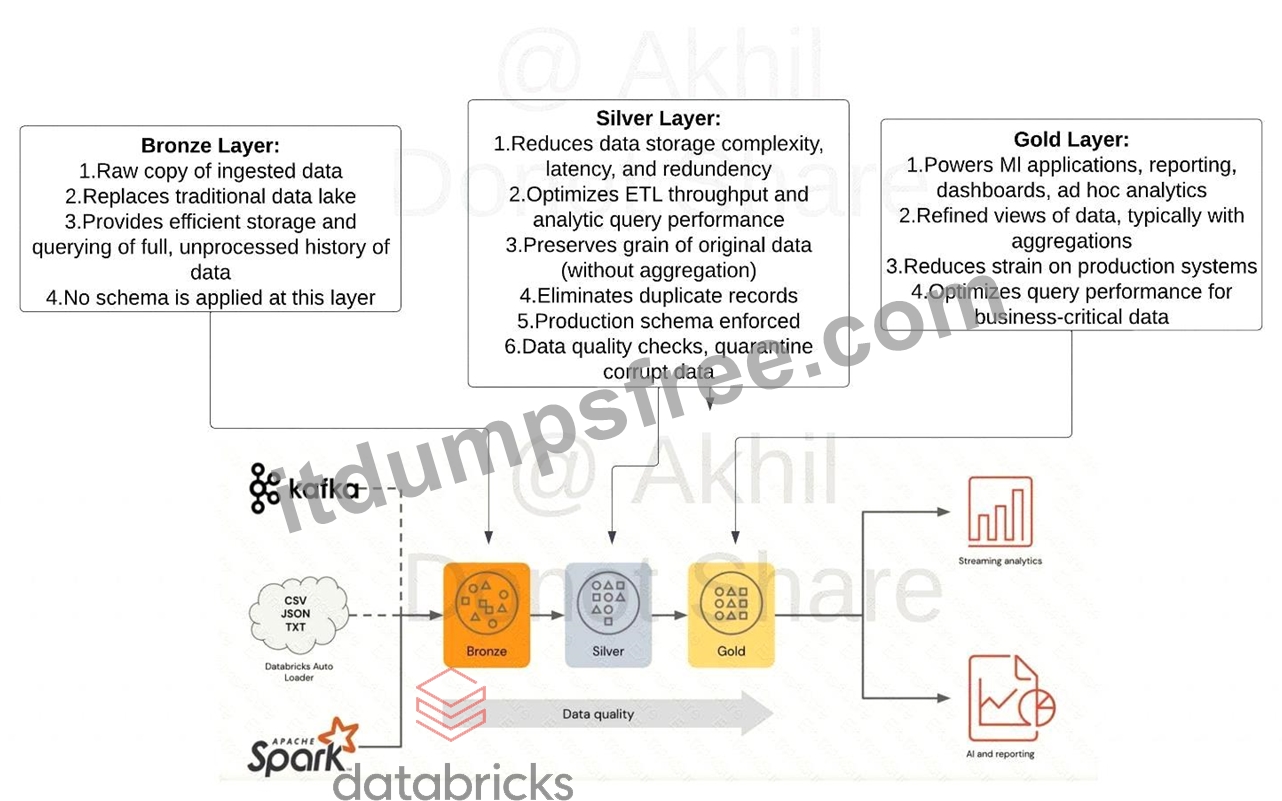
Bronze Layer:
1. Raw copy of ingested data
2. Replaces traditional data lake
3. Provides efficient storage and querying of full, unprocessed history of data
4. No schema is applied at this layer
Exam focus: Please review the below image and understand the role of each layer(bronze, silver, gold) in medallion architecture, you will see varying questions targeting each layer and its purpose.
Sorry I had to add the watermark some people in Udemy are copying my content.
Purpose of each layer in medallion architecture
NEW QUESTION # 105
A data engineer needs to capture pipeline settings from an existing in the workspace, and use them to create and version a JSON file to create a new pipeline.
Which command should the data engineer enter in a web terminal configured with the Databricks CLI?
- A. Use the alone command to create a copy of an existing pipeline; use the get JSON command to get the pipeline definition; save this to git
- B. Stop the existing pipeline; use the returned settings in a reset command
- C. Use the get command to capture the settings for the existing pipeline; remove the pipeline_id and rename the pipeline; use this in a create command
- D. Use list pipelines to get the specs for all pipelines; get the pipeline spec from the return results parse and use this to create a pipeline
Answer: C
Explanation:
The Databricks CLI provides a way to automate interactions with Databricks services. When dealing with pipelines, you can use thedatabricks pipelines get --pipeline-idcommand to capture the settings of an existing pipeline in JSON format. This JSON can then be modified by removing thepipeline_idto prevent conflicts and renaming the pipeline to create a new pipeline. The modified JSON file can then be used with the databricks pipelines createcommand to create a new pipeline with those settings.
References:
* Databricks Documentation on CLI for Pipelines: Databricks CLI - Pipelines
NEW QUESTION # 106
A junior data engineer on your team has implemented the following code block.
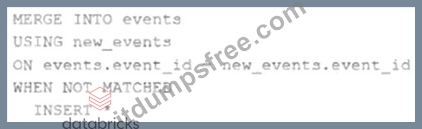
The view new_events contains a batch of records with the same schema as the events Delta table. The event_id field serves as a unique key for this table.
When this query is executed, what will happen with new records that have the same event_id as an existing record?
- A. They are updated.
- B. They are inserted.
- C. They are deleted.
- D. They are merged.
- E. They are ignored.
Answer: E
Explanation:
This is the correct answer because it describes what will happen with new records that have the same event_id as an existing record when the query is executed. The query uses the INSERT INTO command to append new records from the view new_events to the table events. However, the INSERT INTO command does not check for duplicate values in the primary key column (event_id) and does not perform any update or delete operations on existing records. Therefore, if there are new records that have the same event_id as an existing record, they will be ignored and not inserted into the table events. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Append data using INSERT INTO" section.
"If none of the WHEN MATCHED conditions evaluate to true for a source and target row pair that matches the merge_condition, then the target row is left unchanged."
https://docs.databricks.com/en/sql/language-manual/delta-merge-into.html#:~:text=If%20none%20of%20the%20
NEW QUESTION # 107
What is the output of below function when executed with input parameters 1, 3 :
1.def check_input(x,y):
2. if x < y:
3. x= x+1
4. if x>y:
5. x= x+1
6. if x <y:
7. x = x+1
8. return x
Answer: D
NEW QUESTION # 108
A data engineer is configuring a Databricks Asset Bundle to deploy a job with granular permissions. The requirements are:
* Grant the data-engineers group CAN_MANAGE access to the job.
* Ensure the auditors group can view the job but not modify or run it.
* Avoid granting unintended permissions to other users or groups.
How should the data engineer deploy the job while meeting the requirements?
- A. permissions:
- group_name: data-engineers
level: CAN_MANAGE
- group_name: auditors
level: CAN_VIEW
resources:
jobs:
my-job:
name: data-pipeline
tasks: [...]
job_clusters: [...] - B. resources:
jobs:
my-job:
name: data-pipeline
tasks: (...)
job_clusters: (...)
permissions:
- group_name: data-engineers
level: CAN_MANAGE
- group_name: auditors
level: CAN_VIEW - C. resources:
jobs:
my-job:
name: data-pipeline
tasks: (...)
job_clusters: (...)
permissions:
- group_name: data-engineers
level: CAN_MANAGE
- group_name: auditors
level: CAN_VIEW - D. resources:
jobs:
my-job:
name: data-pipeline
tasks: [...]
job_clusters: [...]
permissions:
- group_name: data-engineers
level: CAN_MANAGE
permissions:
- group_name: auditors
level: CAN_VIEW
Answer: C
Explanation:
Databricks documents that resource-specific permissions for bundle resources can be defined under the resource itself, such as resources.jobs. < job > .permissions , using group_name and level . The documented syntax supports CAN_VIEW , CAN_MANAGE , and related permission levels, which matches option B. ( Databricks Documentation ) Option C is invalid because it repeats the permissions key incorrectly. Option D applies top-level permissions more broadly across bundle resources instead of scoping them specifically to the job, which does not best satisfy the "avoid unintended permissions" requirement. Option B is therefore the correct and properly scoped configuration. ( Databricks Documentation )
======
NEW QUESTION # 109
......
Databricks-Certified-Professional-Data-Engineer Study Materials: https://www.itdumpsfree.com/Databricks-Certified-Professional-Data-Engineer-exam-passed.html
- Databricks-Certified-Professional-Data-Engineer Guide 🆔 Certification Databricks-Certified-Professional-Data-Engineer Test Questions 🏂 Databricks-Certified-Professional-Data-Engineer Braindumps Torrent 🦚 【 www.testkingpass.com 】 is best website to obtain ☀ Databricks-Certified-Professional-Data-Engineer ️☀️ for free download ⏯Databricks-Certified-Professional-Data-Engineer Latest Exam Notes
- Exam Databricks-Certified-Professional-Data-Engineer Testking 🎠 Databricks-Certified-Professional-Data-Engineer Test Price 🎵 Databricks-Certified-Professional-Data-Engineer Valid Dumps Sheet 👫 Search on ➥ www.pdfvce.com 🡄 for ⮆ Databricks-Certified-Professional-Data-Engineer ⮄ to obtain exam materials for free download 🤜Databricks-Certified-Professional-Data-Engineer Pdf Dumps
- Databricks-Certified-Professional-Data-Engineer latest exam vce - Databricks-Certified-Professional-Data-Engineer test dumps - Databricks-Certified-Professional-Data-Engineer pdf torrent 🛶 Search for ➽ Databricks-Certified-Professional-Data-Engineer 🢪 and obtain a free download on { www.validtorrent.com } 🎩Databricks-Certified-Professional-Data-Engineer Pdf Dumps
- Databricks-Certified-Professional-Data-Engineer Guide 🔪 Pass Databricks-Certified-Professional-Data-Engineer Rate 😁 Databricks-Certified-Professional-Data-Engineer Test Fee 🤿 Go to website ➠ www.pdfvce.com 🠰 open and search for ▶ Databricks-Certified-Professional-Data-Engineer ◀ to download for free 🌝Databricks-Certified-Professional-Data-Engineer Valid Dumps Sheet
- Databricks-Certified-Professional-Data-Engineer Braindumps Torrent 🐚 Pass Databricks-Certified-Professional-Data-Engineer Rate 🥖 Databricks-Certified-Professional-Data-Engineer Cost Effective Dumps 🐧 Immediately open ☀ www.troytecdumps.com ️☀️ and search for 【 Databricks-Certified-Professional-Data-Engineer 】 to obtain a free download 👲Databricks-Certified-Professional-Data-Engineer Braindumps Torrent
- Databricks-Certified-Professional-Data-Engineer latest exam vce - Databricks-Certified-Professional-Data-Engineer test dumps - Databricks-Certified-Professional-Data-Engineer pdf torrent 🥦 Open “ www.pdfvce.com ” and search for 「 Databricks-Certified-Professional-Data-Engineer 」 to download exam materials for free 🍇Databricks-Certified-Professional-Data-Engineer Certified
- Exam Databricks-Certified-Professional-Data-Engineer Testking ↪ Databricks-Certified-Professional-Data-Engineer Detail Explanation 📔 New Databricks-Certified-Professional-Data-Engineer Practice Materials 🦗 Easily obtain ➽ Databricks-Certified-Professional-Data-Engineer 🢪 for free download through ➤ www.examdiscuss.com ⮘ 🍈Databricks-Certified-Professional-Data-Engineer Guide
- Valid Databricks-Certified-Professional-Data-Engineer Study Notes ⛰ Exam Databricks-Certified-Professional-Data-Engineer Tutorials 🦳 Databricks-Certified-Professional-Data-Engineer Valid Dumps Sheet 📩 Enter ➥ www.pdfvce.com 🡄 and search for 「 Databricks-Certified-Professional-Data-Engineer 」 to download for free 🎩Databricks-Certified-Professional-Data-Engineer Valid Dumps Sheet
- Databricks-Certified-Professional-Data-Engineer Pdf Dumps 💋 Databricks-Certified-Professional-Data-Engineer Pdf Dumps 🍟 Pass Databricks-Certified-Professional-Data-Engineer Rate ➖ ✔ www.troytecdumps.com ️✔️ is best website to obtain ➤ Databricks-Certified-Professional-Data-Engineer ⮘ for free download 🥭Exam Databricks-Certified-Professional-Data-Engineer Testking
- Reliable Databricks-Certified-Professional-Data-Engineer Test Dumps 🦄 Databricks-Certified-Professional-Data-Engineer Latest Exam Notes 🌆 Certification Databricks-Certified-Professional-Data-Engineer Test Questions 🚖 Open 【 www.pdfvce.com 】 and search for [ Databricks-Certified-Professional-Data-Engineer ] to download exam materials for free 🥨Valid Databricks-Certified-Professional-Data-Engineer Study Notes
- Exam Databricks-Certified-Professional-Data-Engineer Tutorials 🦛 Reliable Databricks-Certified-Professional-Data-Engineer Test Dumps 🌈 Databricks-Certified-Professional-Data-Engineer Test Price 🛴 Open ☀ www.dumpsmaterials.com ️☀️ enter ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ and obtain a free download 🥀Databricks-Certified-Professional-Data-Engineer Test Sample Questions
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes